A vector space is any collection of objects where addition and scalar multiplication obey a consistent set of rules. The concept of a basis — a minimal set of vectors from which every other vector can be built uniquely — is the central organizing idea. Choosing a basis assigns coordinates to every vector, connects abstract spaces to concrete computation in Rⁿ, and determines the dimension that classifies the space up to isomorphism.
Vectors in Rn can be added and scaled. So can polynomials, matrices, and continuous functions. A vector space is the formal name for any collection of objects where these two operations — addition and scalar multiplication — satisfy ten algebraic axioms: closure, commutativity, associativity, the existence of a zero element, additive inverses, and the expected distributive and identity laws for scalars.
The objects in a vector space are called vectors regardless of whether they look like arrows, columns of numbers, polynomials, or functions. The power of the abstraction is that every theorem proved from the axioms alone applies to every vector space simultaneously. Linear independence, span, basis, dimension, and subspaces are all defined from the axioms, and their properties carry over to any setting where the axioms hold.
Basis: Definition
Six sets of vectors in the plane. Which of them can serve as a coordinate system for R² — reaching every vector, with nothing extra?
Checking both demands settles it: A, E and F pass; B, C and D each fail one way or another.
set
reaches every vector of the plane?
no spare vector?
basis?
A
yes
yes
yes
B
no — only the x-axis
yes
no
C
yes
no — (1, 1) = (1, 0) + (0, 1)
no
D
no — only one line
no — (2, 4) = 2·(1, 2)
no
E
yes
yes
yes
F
yes
yes
yes
B has too few vectors, C has one too many, and D's two vectors point along the same line.
B reaches only the multiples of (1,0). In C, (1,1) adds nothing that (1,0) and (0,1) cannot already make. In D, (2,4) is twice (1,2), so the pair still reaches only one line.
The rule: enough vectors to reach everything, and none that the others already produce.
The set is linearly independent: no vector in the set can be written as a linear combination of the others. Equivalently, the only combination c1v1+c2v2+⋯+cnvn=0 is the trivial one with all scalars equal to zero.
The set spansV: every vector in V can be expressed as some linear combination of v1,…,vn.
Independence means no vector in the basis is wasted. Spanning means no vector in V is out of reach.
So A, E and F are bases for R2; B, C and D are not.
A basis sits exactly on the boundary between too few vectors and too many.
THEOREM
A basis is a minimal spanning set — remove any element and the span shrinks.
It is also a maximal independent set — add any vector from V and independence breaks. These two characterizations are equivalent and place the basis at the exact boundary between "too few" and "too many."
Two independent vectors spanning R²
These two arrows do both jobs a basis has to do at once: they are independent, so neither is wasted, and they span, so nothing is missing. Adding a third vector would keep the spanning but destroy the independence; removing one would keep the independence but lose the spanning. A basis is exactly the balance point. Test that by adding and removing directions on the span and independence explorer.
Independence and spanning are therefore not two separate requirements to check but two ways the same set can fail.
A space has many bases, but every one of them has the same number of vectors.
A, E and F are three different bases of R2, each with two vectors; that common count is the dimension. What a basis gives in return is one and only one way to write each vector, as unique representation shows.
The rest of the page covers notation, unique representation, coordinates, the standard bases, finding, extending and reducing bases, change of basis, coordinates and isomorphism, and the fundamental subspaces.
Basis and Coordinate Notation
Notation
Basis and Coordinate Notation
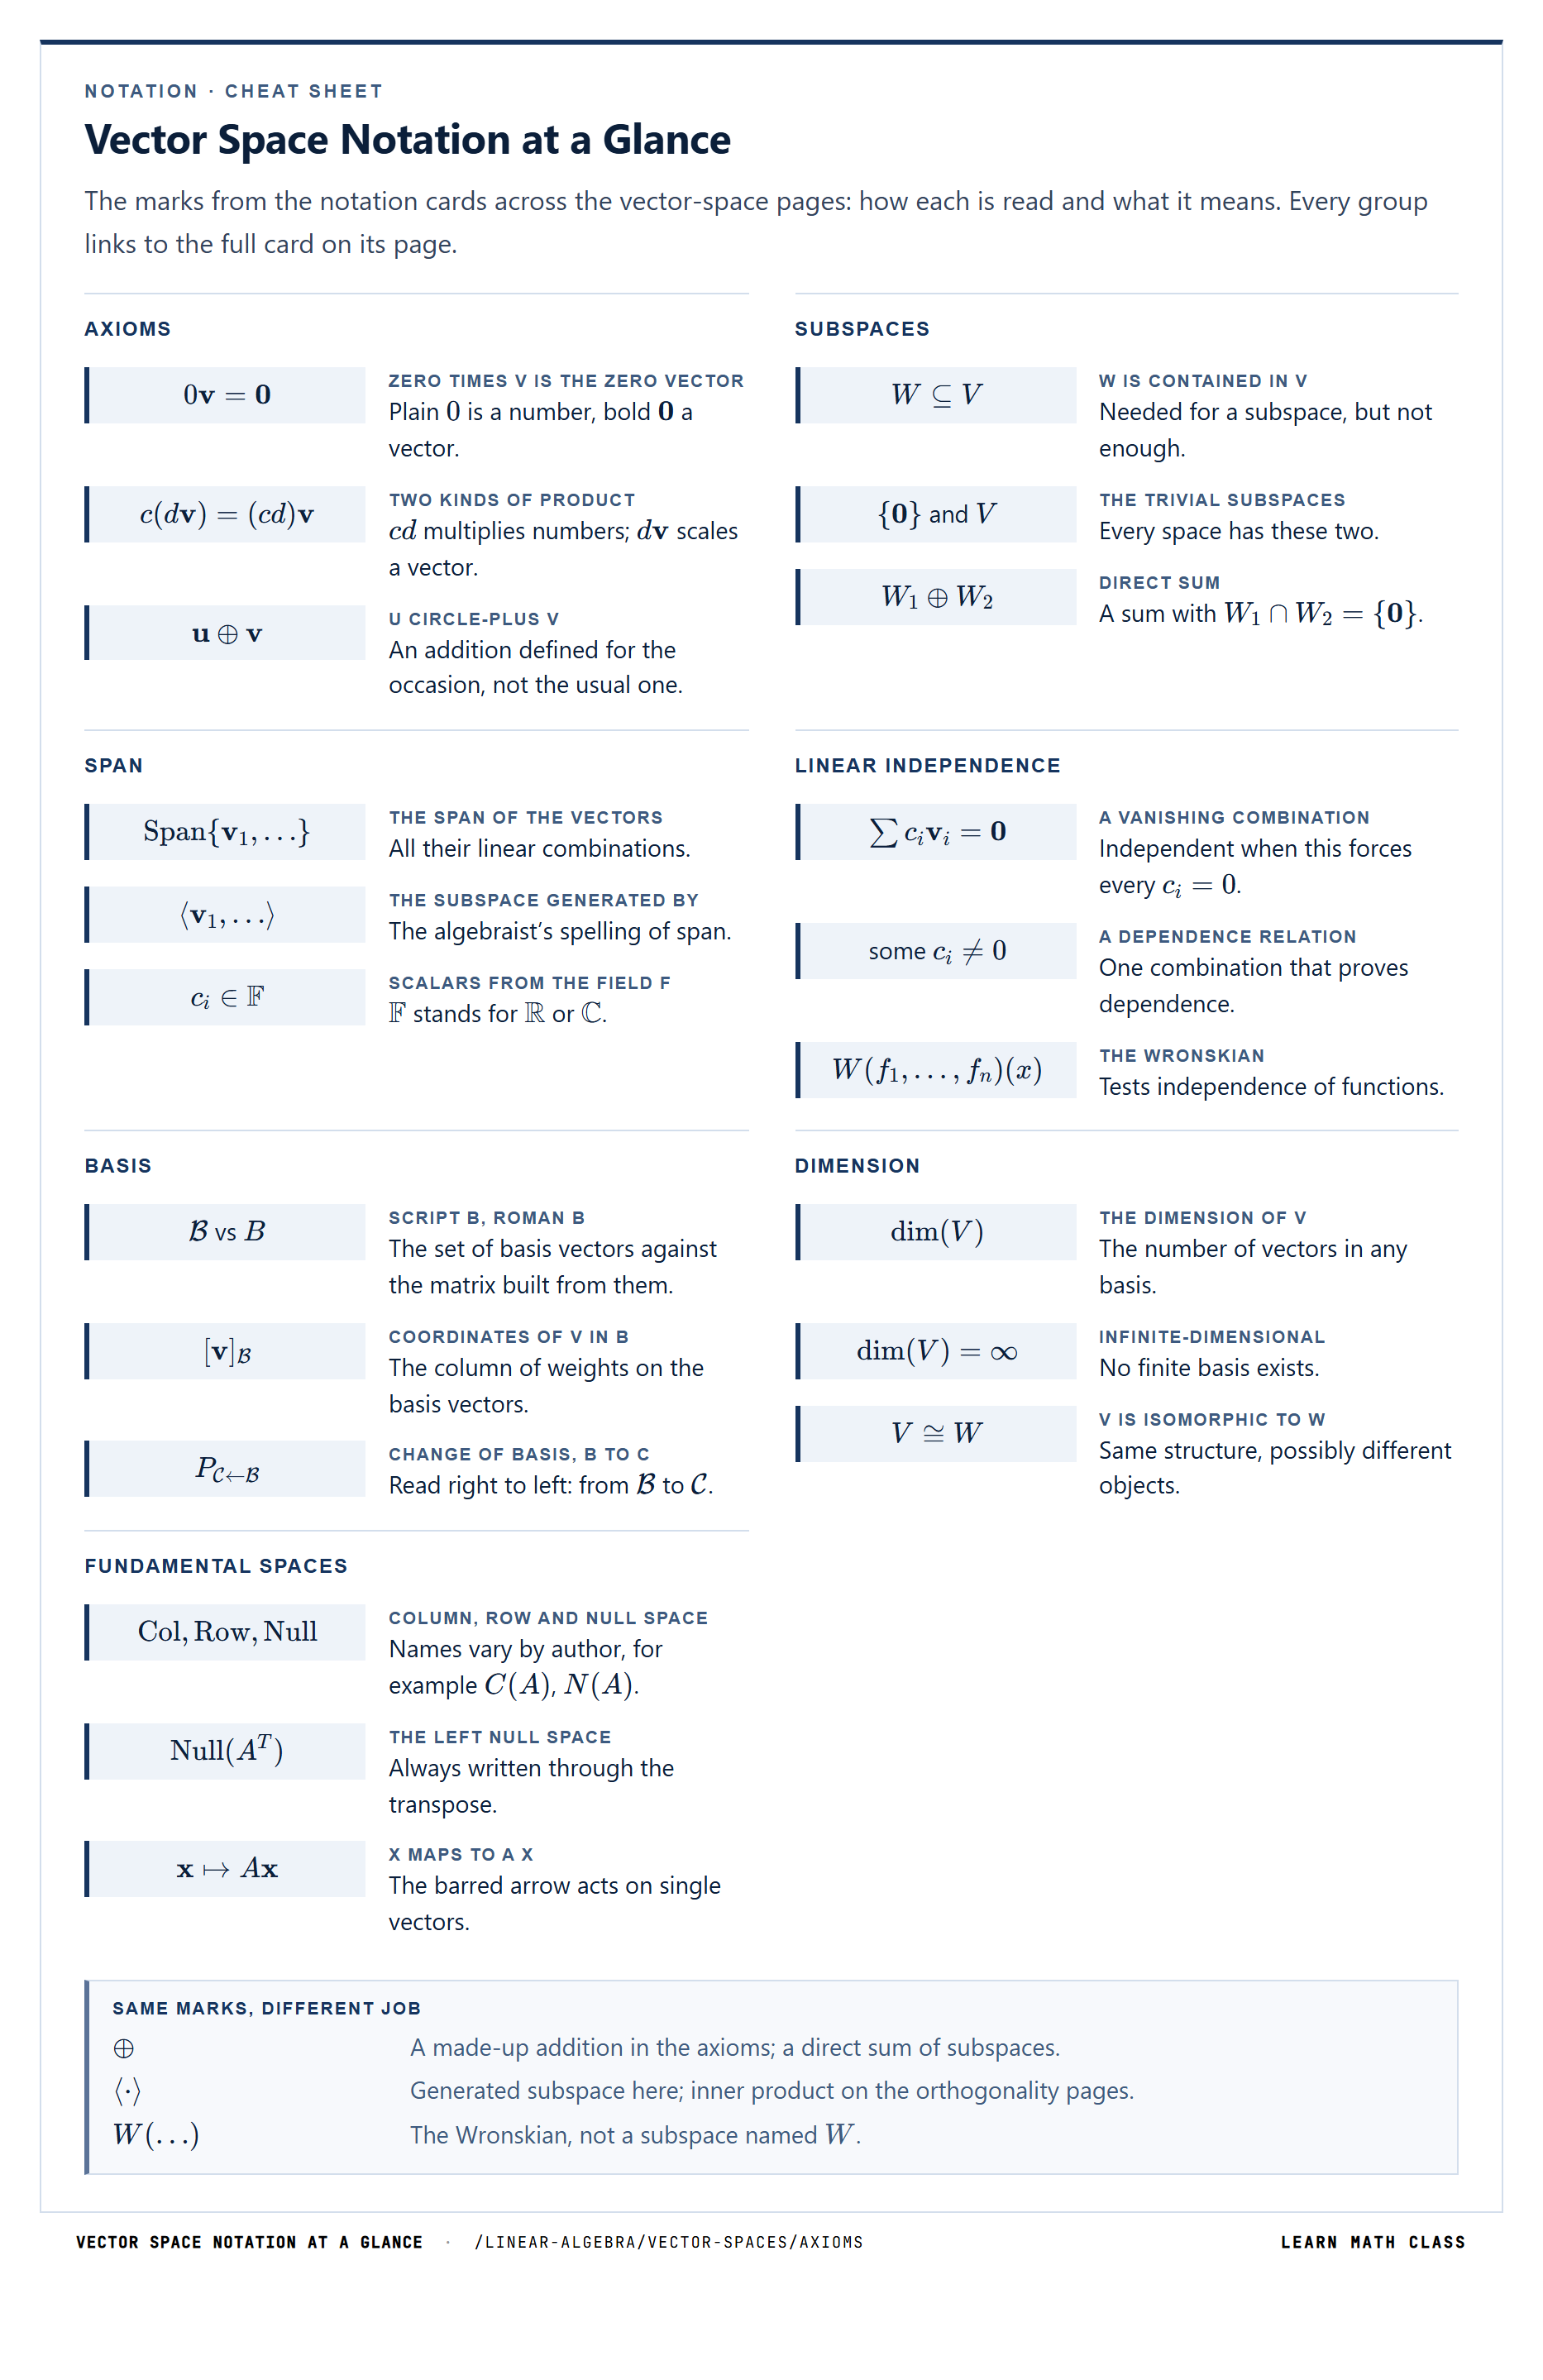
A script letter for the collection, brackets that ask “in which coordinates?”, and a subscript arrow engineered to cancel like dominoes.
Calligraphic letters name collections: B is the set of basis vectors, while roman B is the matrix whose columns they become — and the Coordinates section below legitimately uses both in one computation (c=B−1v for coordinates relative to B).
CasesThe script convention extends across the subject: Pn for the polynomial space, C for a second basis — collections and spaces get the fancy typeface, their matrix incarnations the plain one.
Also writtenPlain B={v1,…} in texts without calligraphic fonts — workable until a basis and its matrix share a page, which is exactly when the distinction earns its ink.
Do not confuseOne object. The set and the matrix carry the same data but different species — a set has members, a matrix has products; conflating them writes Bc, which multiplies nothing.
[v]B
The coordinate vector of v, relative to B
The brackets ask “in which coordinates?” and the subscript answers. Defined in Coordinates below: the column of scalars expressing v in the basis B. Same vector, different subscript, different numbers — the notation makes basis-dependence impossible to forget.
CasesIn the standard basis the machinery collapses: [v]E=v — the coordinates are the components, which is why the subscript is usually dropped there and only there.
Also written(v)B with parentheses, or vB bare in terse texts — the bracket form dominates because it survives expressions: [T(v)]B parses cleanly.
Do not confuseThe vector itself. v lives in V; [v]B lives in Rn — a description of v, not v. The gap between object and description is the entire content of coordinate isomorphism.
PC←B
The change-of-basis matrix, from B to C
The subscript reads right to left — fromB, towardC — because the notation is engineered for the equation it lives in: in [v]C=PC←B[v]B of Change of Basis below, adjacent basis letters touch and match.
CasesThe design pays off in chains: PD←CPC←B=PD←B — inner letters cancel like dominoes — and reversal is the inverse: PB←C=PC←B−1.
Also writtenPB→C with a forward arrow in some texts — same matrix, arrow flipped; check each book's convention before trusting the direction.
Do not confuseReading left to right. The arrow's tail names the input coordinates — reading it as “from C” applies the matrix backwards, and the mistake is self-concealing because the product still computes.
Existence is guaranteed by the spanning condition — every vector is reachable. Uniqueness is guaranteed by independence: if two different sets of scalars both produced v, subtracting one from the other would give a nontrivial combination equal to 0, contradicting independence.
This uniqueness is what separates a basis from an arbitrary spanning set. A spanning set that is not independent can represent some vectors in multiple ways — the representation is ambiguous. A basis eliminates all ambiguity: every vector has exactly one set of coefficients.
Coordinates
The scalars c1,c2,…,cn in the unique representation v=c1v1+⋯+cnvn are called the coordinates of v relative to the basis B. They are collected into a coordinate vector:
Coordinates depend entirely on the choice of basis. The same vector v generally has different coordinates in different bases — the vector does not change, but its numerical description does.
Pitfall: Reading components as coordinates
Taking [v]B=(3,5) for v=(3,5) and B={(1,2),(0,1)} rebuilds 3(1,2)+5(0,1)=(3,11), not v. Solving the system gives [v]B=(3,−1), since 3(1,2)−1(0,1)=(3,5).
To find the coordinates of v relative to B, solve the linear systemc1v1+⋯+cnvn=v. If the basis vectors are columns of a matrixB, this is the system Bc=v, and the coordinate vector is c=B−1v when B is invertible. For the standard basis, B=I, so the coordinates are simply the components of v itself.
The same point, read against a skewed basis
The grid has been redrawn along the two basis vectors, and the point's coordinates are read by counting steps along that grid rather than along the axes. The point never moved; only the ruler changed. This is why coordinates belong to a basis and not to a vector, and why the same arrow carries different numbers in different bases. Swap bases and watch the numbers change on the change of basis explorer.
Because the representation is unique, these coordinates are a genuine address for the vector rather than one description among many.
The Standard Basis for Rⁿ
The most familiar basis for Rn is the standard basis {e1,e2,…,en}, where ei has a 1 in position i and zeros elsewhere:
An 8×8 block of a grayscale photo is a vector in R64, and its pixel values are its standard coordinates. JPEG rewrites it in a basis of 64 cosine patterns, where most coordinates are close to zero and can be rounded away.
Independence is immediate — each vector has a 1 in a position where all others have 0, so no vector is a combination of the rest. Spanning follows from the fact that any vector (v1,…,vn)=v1e1+⋯+vnen.
The standard basis has a special property: coordinates relative to it are just the components of the vector. For any other basis, finding coordinates requires solving a system. This is why the standard basis is the default — but it is one choice among infinitely many, and other bases are often better suited to particular problems.
Other Standard Bases
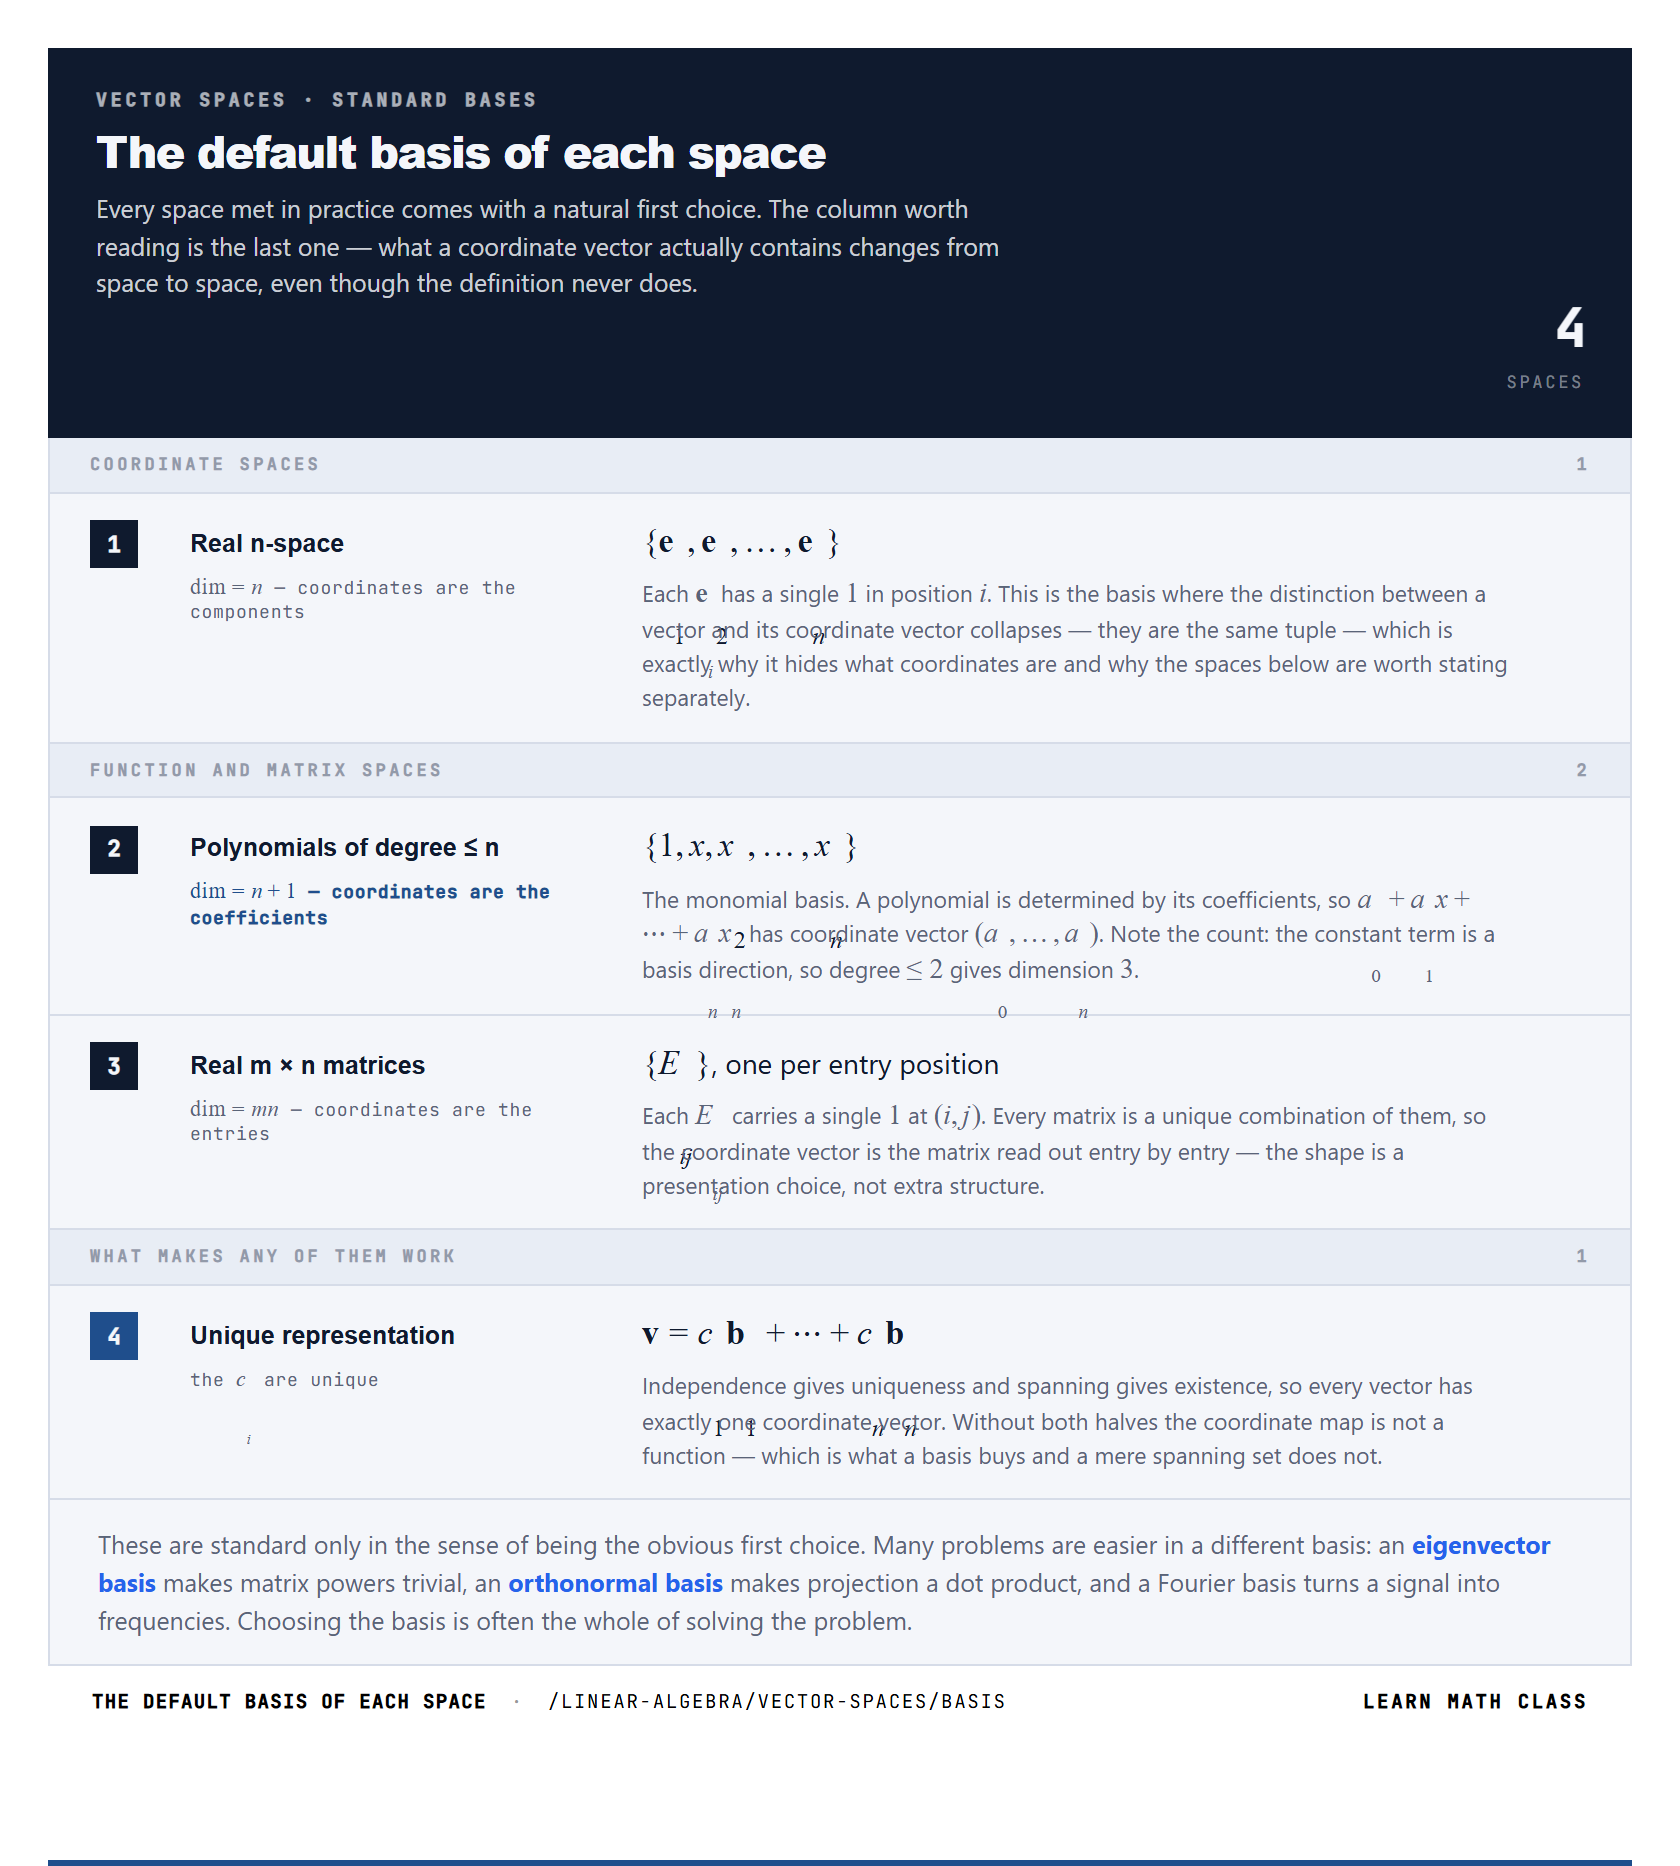
Every vector space encountered in practice comes with a natural default basis.
Fact: Fonts are drawn in another basis
A cubic Bézier curve, the shape behind many font outlines and drawing tools, is a polynomial written in the basis (1−t)3, 3t(1−t)2, 3t2(1−t), t3 of P3 instead of 1,t,t2,t3. Its coordinates in that basis are the control points a designer drags.
The polynomial space Pn of polynomials with degree at most n has the monomial basis {1,x,x2,…,xn}, consisting of n+1 elements. Every polynomial a0+a1x+⋯+anxn is a linear combination of these monomials, and the coefficients are unique (a polynomial is determined by its coefficients). The coordinates of a polynomial relative to the monomial basis are its coefficients.
The matrix space Rm×n has the matrix unit basis {Eij}, where Eij has a 1 in position (i,j) and zeros elsewhere. There are mn such matrices, and every m×n matrix is a unique linear combination of them. The coordinates of a matrix are its entries.
These are all "standard" bases in the sense that they are the most natural first choice. But many problems benefit from non-standard bases: eigenvector bases simplify matrix powers and differential equations, orthonormal bases simplify projections and least squares, and Fourier bases decompose periodic signals into frequency components. Choosing the right basis is often the key step in solving a problem.
The three spaces below are the ones worth having memorised, but the reason to compare them side by side is not the bases themselves — it is what a coordinate vector turns out to contain in each case. In Rn the coordinates are the components, so nothing seems to have happened. In the polynomial and matrix spaces the coordinates are the coefficients and the entries, and the coordinate vector is visibly a different object from the thing it describes.
Every space met in practice comes with a natural first choice. The column worth reading is the last one — what a coordinate vector actually contains changes from space to space, even though the definition never does.
Each ei has a single 1 in position i. This is the basis where the distinction between a vector and its coordinate vector collapses — they are the same tuple — which is exactly why it hides what coordinates are and why the spaces below are worth stating separately.
Function and matrix spaces2
2
Polynomials of degree ≤ n
dim=n+1 — coordinates are the coefficients
{1,x,x2,…,xn}
The monomial basis. A polynomial is determined by its coefficients, so a0+a1x+⋯+anxn has coordinate vector (a0,…,an). Note the count: the constant term is a basis direction, so degree ≤2 gives dimension 3.
3
Real m × n matrices
dim=mn — coordinates are the entries
{Eij}, one per entry position
Each Eij carries a single 1 at (i,j). Every matrix is a unique combination of them, so the coordinate vector is the matrix read out entry by entry — the shape is a presentation choice, not extra structure.
Independence gives uniqueness and spanning gives existence, so every vector has exactly one coordinate vector. Without both halves the coordinate map is not a function — which is what a basis buys and a mere spanning set does not.
These are standard only in the sense of being the obvious first choice. Many problems are easier in a different basis: an eigenvector basis makes matrix powers trivial, an orthonormal basis makes projection a dot product, and a Fourier basis turns a signal into frequencies. Choosing the basis is often the whole of solving the problem.
That difference is the whole content of coordinates. A basis does not describe a space so much as supply a dictionary between it and Rn, and the standard basis for Rn is the degenerate case where the dictionary is the identity. Working in P3 or R2×2 makes the translation visible, and both are four-dimensional — so both have the same coordinate space, despite one being polynomials and the other matrices.
Two spaces sharing a dimension share a coordinate space, and that is what isomorphism means: a polynomial of degree at most three and a 2×2 matrix carry the same information, differently arranged. Anything provable from the axioms alone holds for both, which is why the finite-dimensional theory is stated once rather than once per kind of object.
Finding a Basis for a Subspace
The three subspaces associated with a matrix each have a basis that can be extracted from row reduction.
For the column space of an m×n matrix A: row reduce A and identify the pivot columns. The corresponding columns of the original matrix A — not the echelon form — are a basis for Col(A). The echelon form reveals which columns are independent, but the original columns are the actual vectors spanning the column space.
For the null space: solve Ax=0 by reducing to RREF and expressing the general solution in terms of free variables. Each free variable contributes one basis vector.
For the row space: the nonzero rows of the echelon form are a basis. Unlike the column space, the echelon form's rows — not the original rows — are used, because row operations change individual rows but preserve their span.
Worked Example
For A=123246011134, row reduction gives 100200010110. Pivots are in columns 1 and 3. The column space basis is {(1,2,3),(0,1,1)} — the first and third columns of the original A. The row space basis is {(1,2,0,1),(0,0,1,1)}. The null space has two free variables (columns 2 and 4), and solving yields a two-dimensional null space.
One row reduction gives all three bases: original pivot columns, nonzero echelon rows, and one null-space vector per free variable.
Extending and Reducing to a Basis
Two fundamental operations guarantee that bases always exist in finite-dimensional spaces.
Extension: any linearly independent set can be grown into a basis by adding vectors one at a time. At each step, pick any vector not in the current span and adjoin it. Independence is preserved because the new vector is not a combination of the existing ones. The process stops when the span reaches all of V.
Reduction: any spanning set can be trimmed into a basis by removing redundant vectors. A vector is redundant if it lies in the span of the remaining vectors. Remove redundant vectors one at a time until what remains is independent. The span does not shrink, because each removed vector was already expressible in terms of the others.
Both processes terminate because dimension is finite — the independent set cannot grow past n vectors, and the spanning set cannot shrink below n vectors, where n=dim(V). This means every finite-dimensional vector space has a basis, and the choice of basis is highly flexible.
Change of Basis
Different bases generally assign different coordinates to the same vector. The change-of-basis matrix converts between them.
If B and C are two bases for V, the change-of-basis matrix PC←B satisfies
In R2, let B={(1,1),(1,−1)} and let C be the standard basis. The C-coordinates of (1,1) are just (1,1), and the C-coordinates of (1,−1) are (1,−1). So PC←B=(111−1). To find the B-coordinates of v=(3,1): solve Pc=(3,1), giving c=P−1(3,1)=−21(−1−1−11)(31)=(2,1). So [v]B=(2,1), meaning v=2(1,1)+1(1,−1).
Change of basis connects to similarity: if a linear transformation has matrix A in basis B, its matrix in basis C is PAP−1 with P=PC←B. Choosing a good basis — one that simplifies A into diagonal or triangular form — is the central idea behind diagonalization.
Pitfall: Applying the matrix in the wrong direction
Multiplying v=(3,1) by PC←B instead of solving gives (4,2), but 4(1,1)+2(1,−1)=(6,2), not v. The input of PC←B is B-coordinates, so [v]B=P−1v=(2,1).
In the example, the known coordinates were the standard ones, (3,1), and the unknown ones were the B-coordinates. The matrix PC←B is built directly from the B-vectors, so it is the easy matrix to write down, while the conversion that was needed ran from C back to B. Which coordinates are given and which are wanted decides whether P or its inverse is applied.
Coordinates and Isomorphism
Choosing a basis for an n-dimensional vector space V creates a one-to-one correspondence between V and Rn. Each vector v∈V maps to its coordinate vector [v]B∈Rn, and this mapping preserves addition and scalar multiplication:
Such a structure-preserving bijection is called an isomorphism. Its existence means that every n-dimensional real vector space — Rn, Pn−1, Rm×k with mk=n, solution spaces of ODEs — behaves identically to Rn in all algebraic respects. The objects differ, but the linear algebra is the same.
Dimension is the single invariant that classifies finite-dimensional vector spaces up to isomorphism.
THEOREM
Two spaces over the same field are isomorphic if and only if they have the same dimension.
This is why dimension occupies such a central place in the theory.
Independence and Span
The two concepts that a basis unifies — linear independence and span — each have their own rich theory.
Independence is tested by checking whether the homogeneous system Ac=0 has only the trivial solution, where A is the matrix whose columns are the vectors. For n vectors in Rn, this reduces to checking whether the determinant is nonzero. In Rn, at most n vectors can be independent — any set of n+1 or more is automatically dependent.
Span is tested by checking whether Ac=b is consistent for every b, or for a specific b if the question is about membership. The span of a set is always a subspace, and its dimension equals the largest number of independent vectors in the set.
THEOREM
A set of exactly n vectors in an n-dimensional space is a basis if and only if it is independent (spanning follows automatically), and if and only if it spans the space (independence follows automatically).
Pitfall: Checking one condition with the wrong count
Calling {(1,0,0),(0,1,0)} a basis of R3 because it is independent misses that every combination (a,b,0) has third entry 0, so (0,0,1) is out of reach. The shortcut needs exactly 3 vectors; this set is a basis only of the xy-plane.
At the magic count n=dim(V), the two conditions become equivalent.
In practice the theorem halves the work. For n vectors in Rn, a single determinant settles both conditions at once: a nonzero value shows that the vectors are independent, and with the count equal to the dimension they span the space as well.
Subspaces and the Fundamental Subspaces
A subspace is a subset of a vector space that is itself a vector space under the same operations. The subspace test requires only three checks: the subset contains the zero vector, and it is closed under addition and under scalar multiplication. Lines and planes through the origin, null spaces, column spaces, and row spaces are all subspaces.
Every m×n matrix A defines four fundamental subspaces: the column space in Rm (dimension r), the row space in Rn (dimension r), the null space in Rn (dimension n−r), and the left null space in Rm (dimension m−r), where r=rank(A).
These four subspaces split into two pairs of orthogonal complements: the row space and null space are perpendicular in Rn, while the column space and left null space are perpendicular in Rm. The rank governs all four dimensions and completely determines the geometry of the linear map x↦Ax.
Common Pitfalls
Four mistakes account for many wrong answers when working with bases and coordinates. Three are marked with a box where they happen in the sections above, and the fourth, taking the echelon columns as a basis for the column space, is flagged in the section on finding a basis. Here each is worked through in full, with the wrong and the right working side by side.
Reading components as coordinates
The coordinates of v relative to a basis B are written down as the components of v, as they would be in the standard basis. For any other basis, the components and the coordinates are usually different numbers.
Wrong working: for B={(1,2),(0,1)} and v=(3,5), take [v]B=(3,5).
Right working: solve c1(1,2)+c2(0,1)=(3,5). The first entries give c1=3, and the second entries give 2⋅3+c2=5, so c2=−1 and [v]B=(3,−1).
Why it happens: in Rn almost all work is done in the standard basis, where coordinates and components coincide, so the difference never shows.
How to check: rebuild the vector from its coordinates. With (3,5), 3(1,2)+5(0,1)=(3,11)=v; with (3,−1), 3(1,2)−1(0,1)=(3,5)=v.
Using echelon columns for the column space
After row reduction, the pivot columns of the echelon form are taken as the basis of Col(A), instead of the matching columns of A. Row operations change the columns, so the echelon columns usually span a different subspace.
Wrong working: for the matrix A of the worked example in the section on finding a basis, the pivot columns of the echelon form are (1,0,0) and (0,1,0), and {(1,0,0),(0,1,0)} is given as a basis of Col(A).
Right working: the pivots are in columns 1 and 3, so the basis is made of columns 1 and 3 of the original A: {(1,2,3),(0,1,1)}.
Why it happens: the echelon form is the matrix on the page at the end of the computation, and its pivot columns are the simplest vectors in sight.
How to check: every original column must be a combination of the proposed basis. Column 1 of A, (1,2,3), has third entry 3, while every combination of (1,0,0) and (0,1,0) has third entry 0. With the right basis, column 2 is 2(1,2,3) and column 4 is (1,3,4)=(1,2,3)+(0,1,1).
Applying the matrix in the wrong direction
The change-of-basis matrix PC←B takes B-coordinates as input and returns C-coordinates. When the C-coordinates are known and the B-coordinates are wanted, P is applied anyway instead of its inverse.
Wrong working: in the change-of-basis example, C is the standard basis and v=(3,1). Multiplying,
Pv=(111−1)(31)=(42)
and (4,2) is given as [v]B.
Right working: solve Pc=v, or apply the inverse:
c=P−1v=−21(−1−1−11)(31)=(21)
Why it happens: PC←B is the matrix that is easy to write, with the B-vectors as its columns, and its subscript is easily read left to right, as if it started at C. The wrong product still computes, so nothing signals the error.
How to check: rebuild v from the answer. 4(1,1)+2(1,−1)=(6,2)=(3,1), while 2(1,1)+1(1,−1)=(3,1).
Checking one condition with the wrong count
The theorem that one condition implies the other applies only to sets of exactly n=dim(V) vectors. Applied to a smaller set, independence is taken to imply spanning; applied to a larger set, spanning is taken to imply independence.
Wrong working: {(1,0,0),(0,1,0)} is independent, since neither vector is a multiple of the other, so it is declared a basis of R3.
Right working: the set has 2 vectors and dim(R3)=3, so spanning has to be checked separately. Every combination a(1,0,0)+b(0,1,0)=(a,b,0) has third entry 0, so (0,0,1) is not in the span and the set is not a basis. Adding (0,0,1) gives the standard basis.
Why it happens: the shortcut saves a whole check and is used so often for n vectors in Rn that the condition on the count is forgotten.
How to check: count first. Fewer than n vectors can never span an n-dimensional space and more than n can never be independent, so only a set of exactly n vectors can be a basis.
Basis and Coordinates FAQ
Is [v]B the same thing as v?
+
No, they live in different places. The vector v belongs to the space V, while its coordinate vector belongs to Rn and is a description of v relative to one chosen basis. The two coincide only in the standard basis, which is exactly why the subscript is usually dropped there and nowhere else.Read more →
Which way does PD←C convert?
+
It takes coordinates in C and returns coordinates in D, so the arrow's tail names the input. Reading it left to right applies the matrix backwards, and the error hides itself because the product still has compatible shapes and computes without complaint. The payoff is that chains cancel like dominoes.Read more →
Why is a basis written in script as B?
+
The typeface separates the set from the matrix built out of it. Script B is a collection with members, while a plain B is an array with columns, and the two carry the same data in different species. Conflating them produces expressions like Bc, which multiplies a set by a vector and means nothing.Read more →
Does a vector space have only one basis?
+
No. A nonzero real space has infinitely many bases: {(1,0),(0,1)}, {(1,1),(1,−1)} and {(2,1),(1,3)} are three different bases of R2. What every basis of a space shares is its size, here two vectors, and that common count is the dimension. Each basis gives a vector exactly one set of coordinates, but different bases give it different numbers.Read more →
How does JPEG use a change of basis?
+
It stores coordinates in a better basis instead of pixel values. An 8×8 block of a grayscale photo is a vector in R64, and its pixel values are its coordinates in the standard basis. JPEG rewrites the block in a basis of 64 cosine patterns, where most of the coordinates are close to zero and can be rounded away, so far fewer numbers need to be kept.Read more →
What basis is a Bézier curve written in?
+
A cubic Bézier curve is a polynomial in P3 written in the basis (1−t)3, 3t(1−t)2, 3t2(1−t), t3 instead of the monomials 1,t,t2,t3. Its coordinates in that basis are the control points a designer drags in a font or drawing tool. Both lists are bases of the same four-dimensional space, so moving between them is an ordinary change of basis.Read more →