Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Orthogonal Sets


Bases Where Coordinates Come Free

An orthogonal set consists of vectors that are pairwise perpendicular. An orthonormal set adds the requirement that each vector has unit length. These sets are automatically linearly independent, and when they form a basis, coordinates are computed by dot products alone — no system solving, no row reduction, no matrix inversion.

For step-by-step results on your own numbers, use the Gram–Schmidt and orthogonal complement calculators on CalculateMatrix.


Orthogonal Sets

Six sets of vectors. In which of them does every vector meet every other at a right angle?
Some are lined up with the axes, some are tilted, one contains a suspicious vector. From the numbers alone it is hard to tell.
setvectors
A(1, 0, 0), (0, 2, 0), (0, 0, −3)
B(1, 1, 1), (1, −2, 1), (1, 0, −1)
C(1, 1, 0), (1, −1, 0), (1, 0, 1)
D(1, 2), (2, −1)
E(1, 1), (2, 2)
F(1, 0), (0, 0)
Taking the dot product of every pair settles it: A, B and D pass; C, E and F fail.
setdot products of the pairsorthogonal set?
A0, 0, 0yes
B0, 0, 0yes
C0, 1, 1 — two pairs failno
D2 − 2 = 0yes
E2 + 2 = 4 — the vectors are parallelno
F0, but (0, 0) is the zero vectorno
C fails on two pairs, E is parallel, and F only passes the dot-product test because of the zero vector.
In C the first two vectors are perpendicular, but the third is not perpendicular to them, and one bad pair is enough to fail. B looks just as tilted as C, yet all three of its pairs give 00.
The vectors in an orthogonal set must all be nonzero — the zero vector is excluded because including it would trivialize the structure (every vector is orthogonal to 0\mathbf{0}, so 0\mathbf{0} carries no directional information).
The rule: every pair perpendicular, and no zero vector allowed.
Think of the edges meeting at the corner of a box: each one is at a right angle to every other. An orthogonal set is a collection of directions arranged like that, possibly with different lengths.
The definition
An orthogonal set is a set of nonzero vectors in which every pair of distinct vectors has dot product zero.
A set of vectors {v1,v2,…,vk}\{\mathbf{v}_1, \mathbf{v}_2, \dots, \mathbf{v}_k\} is orthogonal if every pair has dot product zero:
Orthogonal Sets
vi⋅vj=0for all i≠j\mathbf{v}_i \cdot \mathbf{v}_j = 0 \quad \text{for all } i \neq j
So sets A, B and D are orthogonal; C, E and F are not.
Being orthogonal is a property of the whole set — every pair has to pass.
For example, {(1,0,0),(0,2,0),(0,0,−3)}\{(1, 0, 0), (0, 2, 0), (0, 0, -3)\} is orthogonal in R3\mathbb{R}^3: every pair of distinct vectors has dot product zero. The vectors need not have the same length, and their lengths can be anything nonzero.
Example
A less obvious example: {(1,1,1),(1,−2,1),(1,0,−1)}\{(1, 1, 1), (1, -2, 1), (1, 0, -1)\}. Checking: (1)(1)+(1)(−2)+(1)(1)=0(1)(1) + (1)(-2) + (1)(1) = 0, (1)(1)+(1)(0)+(1)(−1)=0(1)(1) + (1)(0) + (1)(-1) = 0, (1)(1)+(−2)(0)+(1)(−1)=0(1)(1) + (-2)(0) + (1)(-1) = 0. All three pairwise products vanish — the set is orthogonal despite none of the vectors being aligned with the coordinate axes.
Fact: All-sign bases need a multiple of 4
nn mutually orthogonal vectors in Rn\mathbb{R}^n with every entry ±1\pm 1 exist for n=1n = 1 and n=2n = 2, and otherwise only when nn is a multiple of 44: any three of them sort the nn positions into four equal groups by which signs agree. Whether every multiple of 44 works is still unproved.
U3×3v1,1​v1,2​v1,3​v2,1​−c2,1​u1,1​v2,2​−c2,1​u1,2​v2,3​−c2,1​u1,3​v3,1​−c3,1​u1,1​−c3,2​u2,1​v3,2​−c3,1​u1,2​−c3,2​u2,2​v3,3​−c3,1​u1,3​−c3,2​u2,3​→E3×3u1,1​/‖u1​‖u1,2​/‖u1​‖u1,3​/‖u1​‖u2,1​/‖u2​‖u2,2​/‖u2​‖u2,3​/‖u2​‖u3,1​/‖u3​‖u3,2​/‖u3​‖u3,3​/‖u3​‖
A set with every pair at right angles

Every pair in this set has a dot product of zero. That single condition forces independence — no vector can be a combination of the others without picking up a non-zero dot product with one of them. Independence therefore comes free with orthogonality rather than needing a separate check. Build such a set from arbitrary vectors on the Gram-Schmidt visualizer.

The zero vector has to be excluded by hand, since it is orthogonal to everything and would wreck the independence it otherwise guarantees.
A rejected set can often be repaired: tilting its vectors into right angles keeps the same span.
Set C spans the same space as an orthogonal set, which the Gram-Schmidt process produces step by step. What orthogonality buys in return is shown in the next section: orthogonal sets are independent.
The rest of the page covers notation, why orthogonal sets are independent, orthonormal sets and bases, coordinates via dot products, orthogonal matrices, and matrices with orthonormal columns.

Orthogonal Set Notation

Notation

Orthogonal Set Notation

Two conditions — mutual perpendicularity and unit length — that most of this subject states in prose, compressed by one symbol into a single equation. Around it sit a hat that means a specific normalisation and a matrix letter whose name does not match its defining property. All catalogued among the linear algebra symbols.
The dot and ⊥\perp come from dot product and inner product notation; ∥v∥\|\mathbf{v}\| and the hat from norm notation; ATA^{T}, II and A−1A^{-1} from matrix operation and inverse notation; subscripted index pairs from matrix entry notation.
vi⋅vj=δij\mathbf{v}_i \cdot \mathbf{v}_j = \delta_{ij}
the dot product is one when the indices agree and zero otherwise
The Kronecker delta is a switch written as a symbol: δij=1\delta_{ij} = 1 when i=ji = j and 00 otherwise. It compresses the whole definition of an orthonormal set into one equation — perpendicularity is the i≠ji \neq j case, unit length the i=ji = j case, as Orthonormal Sets below states.
CasesThe same symbol is the identity matrix entrywise, I=[δij]I = [\delta_{ij}], which is why QTQ=IQ^{T}Q = I and "the columns are orthonormal" are the same statement written two ways — one in matrix marks, one in index marks.
Do not confuseThe Δ\Delta and δ\delta of calculus — an increment or a small quantity. Here δ\delta takes two subscripts and returns one of two values; it is a function of a pair of indices, not a magnitude, and nothing about it is small.
u^=v∥v∥\hat{\mathbf{u}} = \dfrac{\mathbf{v}}{\|\mathbf{v}\|}
u-hat — the unit vector in the direction of v
The hat is a claim about length, not about identity: it says this vector has been divided by its own norm and now measures 11. Normalising is the single step that turns an orthogonal set into an orthonormal one, so the hat marks exactly what the extra word "normal" contributes.
CasesThe standard basis carries hats for the same reason — ı^,ȷ^,k^\hat{\imath}, \hat{\jmath}, \hat{k} in physics for what this site writes e1,e2,e3\mathbf{e}_1, \mathbf{e}_2, \mathbf{e}_3 — and the hat is dropped once every vector in play is known to be a unit vector.
Same glyph elsewhereIn statistics the same hat marks an estimate rather than a length — μ^\hat{\mu} is an estimated mean, with no implication that anything equals one. The two-hats convention keeps the jobs apart.
QTQ=IQ^{T}Q = I, so Q−1=QTQ^{-1} = Q^{T}
Q is orthogonal: its transpose is its inverse
QQ is the reserved letter for a matrix with orthonormal columns, and the defining equation is the payoff — Orthogonal Matrices below — since it replaces inversion, normally expensive, with transposition, which is free.
CasesThe equation is a statement about columns, and for a square QQ it forces the same of rows, so QQT=IQQ^{T} = I holds too — one of the few places where a matrix identity is symmetric in that way.
Do not confuseThe name itself. An "orthogonal matrix" has orthonormal columns, not merely orthogonal ones — unit length is part of the definition, and a matrix whose columns are perpendicular but not normalised satisfies no such identity. The terminology is a historical accident the notation does not repeat.
DownloadPNG2×PDF
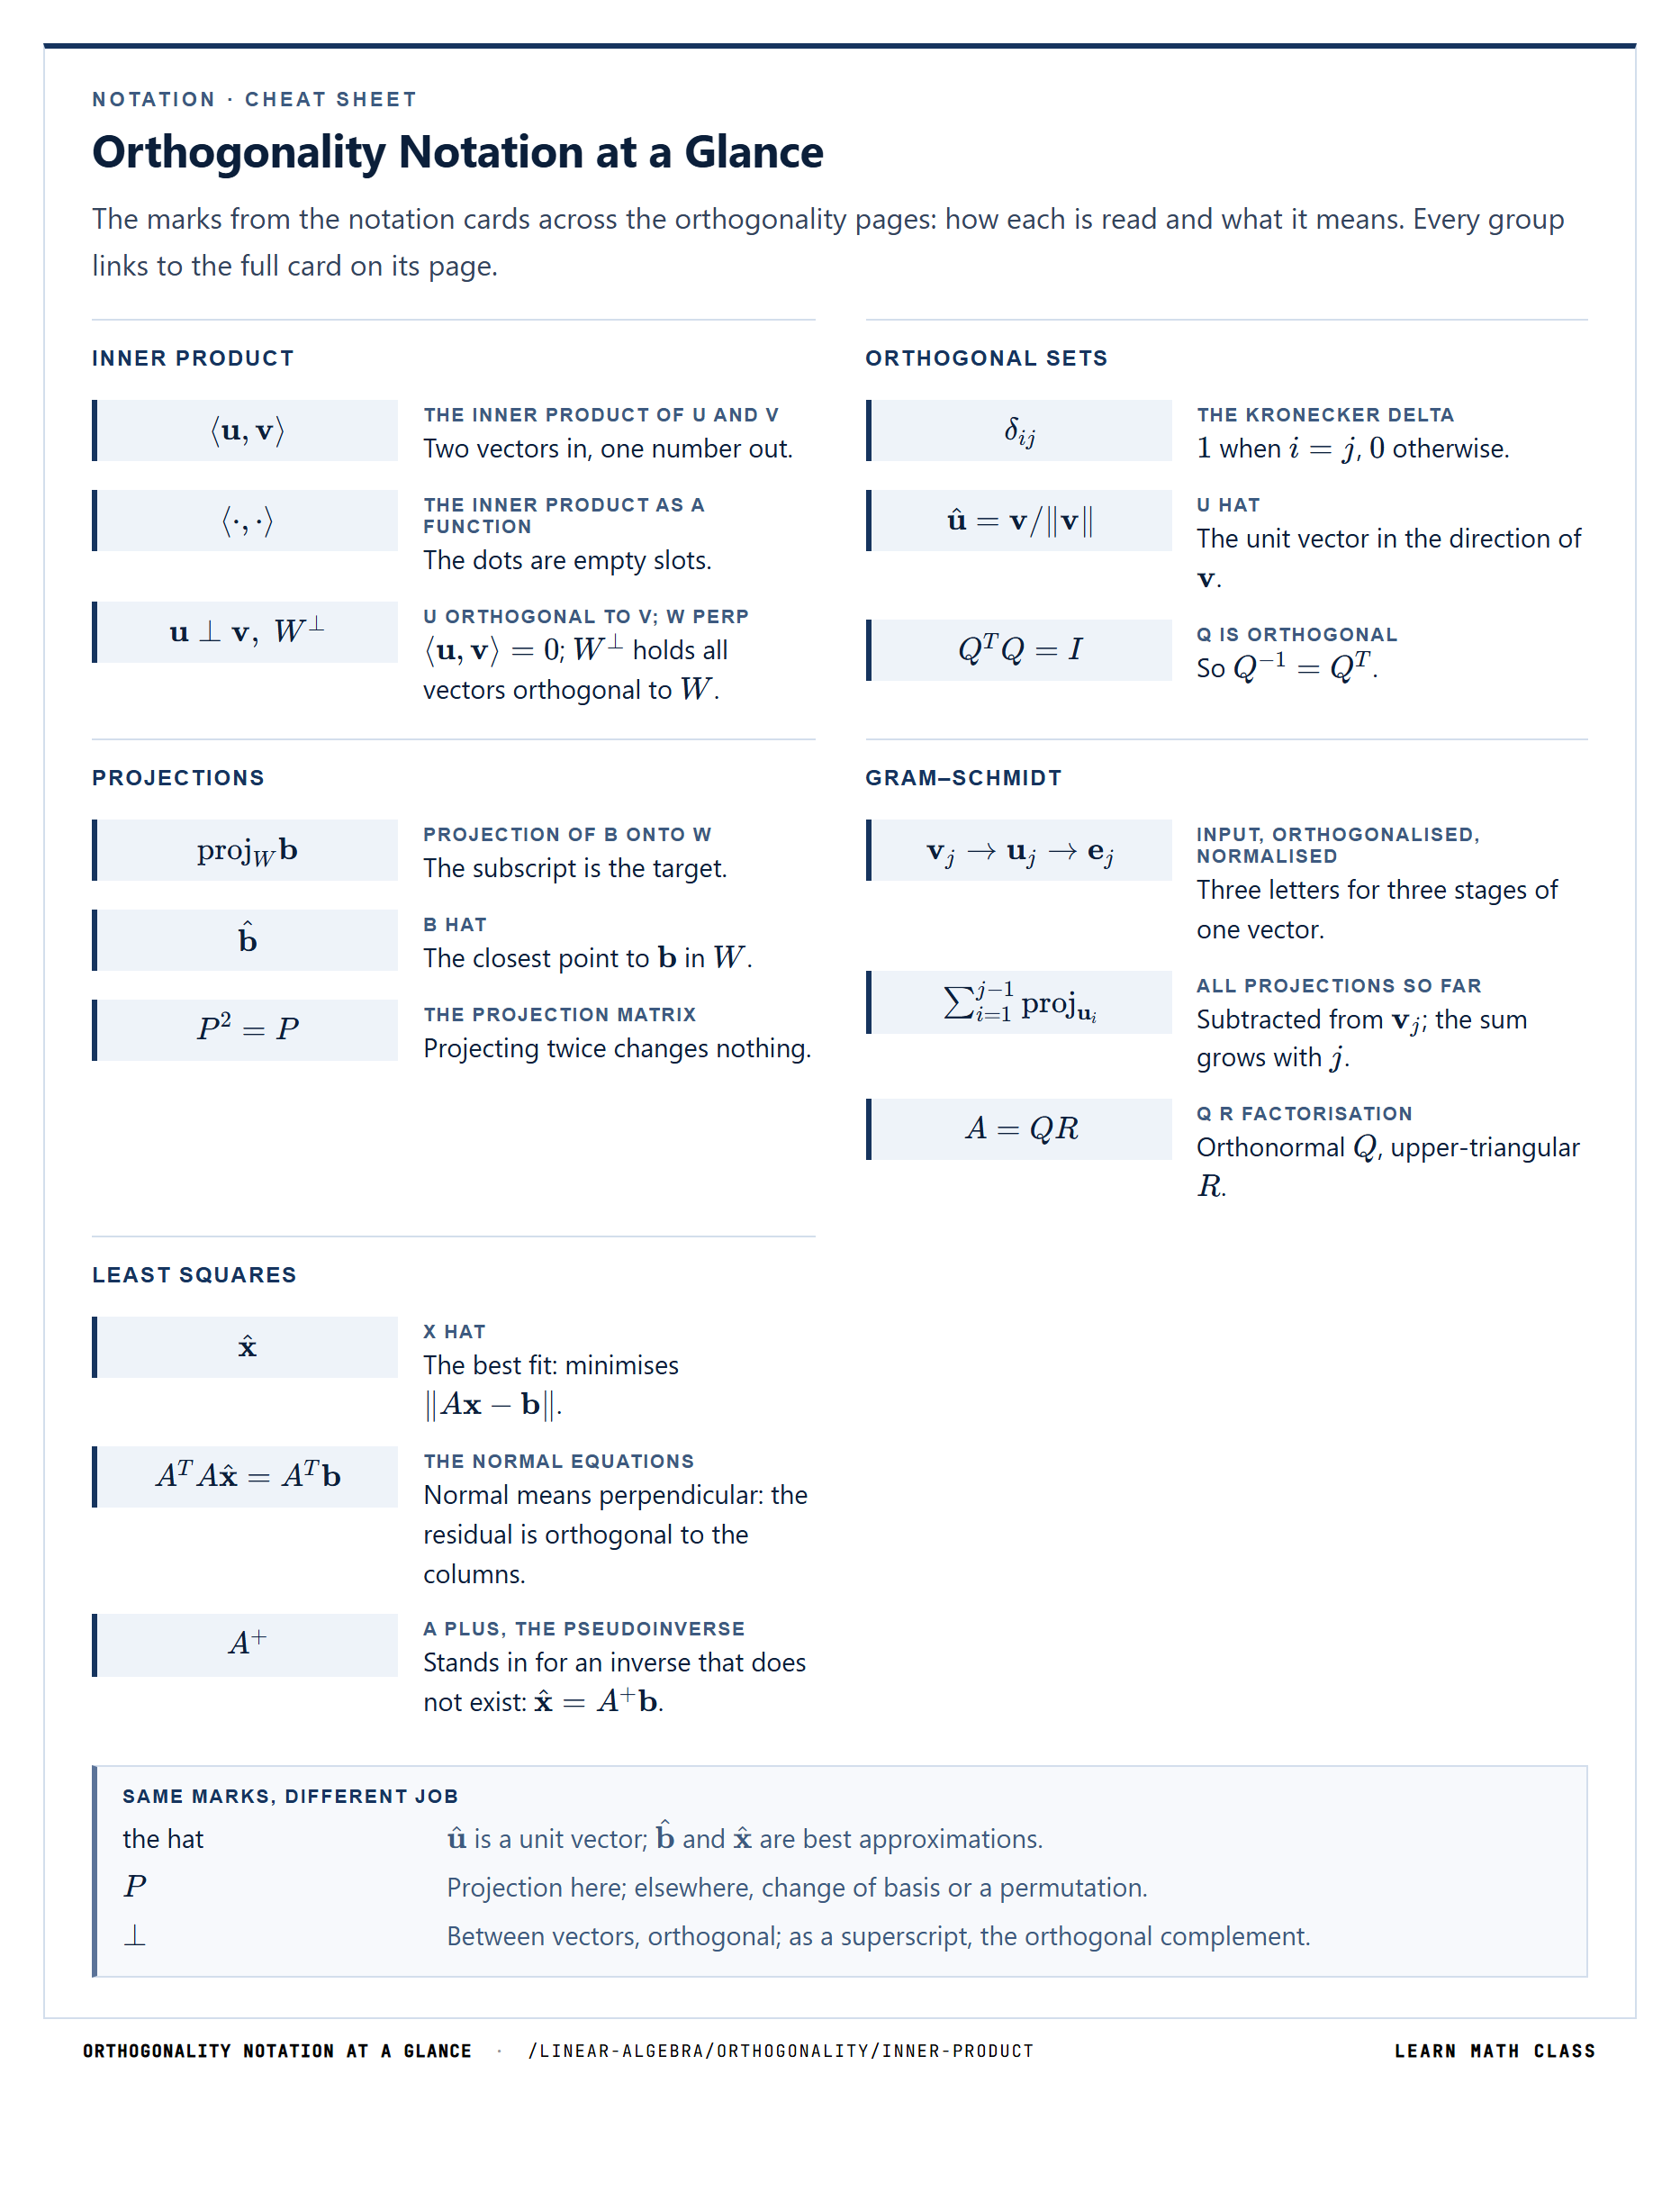
Notation · Cheat sheet
Orthogonality Notation at a Glance
The marks from the notation cards across the orthogonality pages: how each is read and what it means. Every group links to the full card on its page.
Inner product
⟨u,v⟩\langle \mathbf{u}, \mathbf{v} \rangle
the inner product of u and v
Two vectors in, one number out.
⟨⋅,⋅⟩\langle \cdot, \cdot \rangle
the inner product as a function
The dots are empty slots.
u⊥v,  W⊥\mathbf{u} \perp \mathbf{v}, \; W^{\perp}
u orthogonal to v; W perp
⟨u,v⟩=0\langle \mathbf{u}, \mathbf{v} \rangle = 0; W⊥W^{\perp} holds all vectors orthogonal to WW.
Orthogonal setsThis page
δij\delta_{ij}
the Kronecker delta
11 when i=ji = j, 00 otherwise.
u^=v/∥v∥\hat{\mathbf{u}} = \mathbf{v} / \|\mathbf{v}\|
u hat
The unit vector in the direction of v\mathbf{v}.
QTQ=IQ^{T}Q = I
Q is orthogonal
So Q−1=QTQ^{-1} = Q^{T}.
Projections
projWb\text{proj}_{W}\mathbf{b}
projection of b onto W
The subscript is the target.
b^\hat{\mathbf{b}}
b hat
The closest point to b\mathbf{b} in WW.
P2=PP^2 = P
the projection matrix
Projecting twice changes nothing.
Gram–Schmidt
vj→uj→ej\mathbf{v}_j \to \mathbf{u}_j \to \mathbf{e}_j
input, orthogonalised, normalised
Three letters for three stages of one vector.
∑i=1j−1projui\sum_{i=1}^{j-1} \text{proj}_{\mathbf{u}_i}
all projections so far
Subtracted from vj\mathbf{v}_j; the sum grows with jj.
A=QRA = QR
Q R factorisation
Orthonormal QQ, upper-triangular RR.
Least squares
x^\hat{\mathbf{x}}
x hat
The best fit: minimises ∥Ax−b∥\|A\mathbf{x} - \mathbf{b}\|.
ATAx^=ATbA^{T}A\hat{\mathbf{x}} = A^{T}\mathbf{b}
the normal equations
Normal means perpendicular: the residual is orthogonal to the columns.
A+A^{+}
A plus, the pseudoinverse
Stands in for an inverse that does not exist: x^=A+b\hat{\mathbf{x}} = A^{+}\mathbf{b}.
Same marks, different job
the hatu^\hat{\mathbf{u}} is a unit vector; b^\hat{\mathbf{b}} and x^\hat{\mathbf{x}} are best approximations.
PPProjection here; elsewhere, change of basis or a permutation.
⊥\perpBetween vectors, orthogonal; as a superscript, the orthogonal complement.
Orthogonality Notation at a Glance·/linear-algebra/orthogonality/inner-productLearn Math Class

Orthogonal Sets Are Independent

Every orthogonal set of nonzero vectors is linearly independent:

Orthogonal Set Independence
{v1,…,vk} orthogonal, all nonzero  ⟹  linearly independent\{\mathbf{v}_1, \dots, \mathbf{v}_k\} \text{ orthogonal, all nonzero} \implies \text{linearly independent}

The proof is short and reveals exactly why orthogonality is so powerful.

Suppose c1v1+c2v2+⋯+ckvk=0c_1\mathbf{v}_1 + c_2\mathbf{v}_2 + \cdots + c_k\mathbf{v}_k = \mathbf{0}. Dot both sides with vj\mathbf{v}_j:

Orthogonal Sets Are Independent
c1(v1⋅vj)+c2(v2⋅vj)+⋯+ck(vk⋅vj)=0c_1(\mathbf{v}_1 \cdot \mathbf{v}_j) + c_2(\mathbf{v}_2 \cdot \mathbf{v}_j) + \cdots + c_k(\mathbf{v}_k \cdot \mathbf{v}_j) = 0

Every term with i≠ji \neq j vanishes because vi⋅vj=0\mathbf{v}_i \cdot \mathbf{v}_j = 0. Only the jj-th term survives: cj∥vj∥2=0c_j \|\mathbf{v}_j\|^2 = 0. Since vj≠0\mathbf{v}_j \neq \mathbf{0}, ∥vj∥2>0\|\mathbf{v}_j\|^2 > 0, so cj=0c_j = 0. This works for every jj, so all coefficients are zero.

The key mechanism is that orthogonality isolates each coefficient. Dotting with vj\mathbf{v}_j kills every other term, leaving cjc_j alone. This is why orthogonal bases make coordinates computable by individual dot products — the same isolation principle that proves independence also extracts coordinates.

Orthonormal Sets

An orthonormal set is an orthogonal set where every vector additionally has unit length: ∥vi∥=1\|\mathbf{v}_i\| = 1 for all ii. The two conditions together can be written compactly using the Kronecker delta:

Orthonormal Set
vi⋅vj=δij={1if i=j0if i≠j\mathbf{v}_i \cdot \mathbf{v}_j = \delta_{ij} = \begin{cases} 1 & \text{if } i = j \\ 0 & \text{if } i \neq j \end{cases}

Any orthogonal set can be made orthonormal by normalizing each vector: v^i=vi/∥vi∥\hat{\mathbf{v}}_i = \mathbf{v}_i / \|\mathbf{v}_i\|. The directions are preserved, only the lengths change to 11.

Pitfall: Dividing by the squared length
Dividing by v⋅v=6\mathbf{v} \cdot \mathbf{v} = 6 instead of ∥v∥=6\|\mathbf{v}\| = \sqrt{6} turns (1,−2,1)(1, -2, 1) into 16(1,−2,1)\tfrac{1}{6}(1, -2, 1), whose length is 16≈0.41\tfrac{1}{\sqrt{6}} \approx 0.41. The unit vector is 16(1,−2,1)\tfrac{1}{\sqrt{6}}(1, -2, 1).

For the set (1,1,1)(1, 1, 1), (1,−2,1)(1, -2, 1), (1,0,−1)(1, 0, -1) from the first section, the three vectors have squared lengths 33, 66 and 22, so each one is rescaled by a different factor. The right angles survive the rescaling: scaling two vectors multiplies their dot product by the two scale factors, and zero stays zero.

The standard basis {e1,e2,…,en}\{\mathbf{e}_1, \mathbf{e}_2, \dots, \mathbf{e}_n\} for Rn\mathbb{R}^n is orthonormal: ei⋅ej=δij\mathbf{e}_i \cdot \mathbf{e}_j = \delta_{ij} because each basis vector has a single 11 in a different position. It is the simplest orthonormal set, but far from the only one.
Aspect Orthogonal set Orthonormal set
Pairwise dot products vi · vj = 0 for i ≠ j vi · vj = 0 for i ≠ j
Vector lengths any nonzero value each ‖vi‖ = 1
Compact condition vi · vj = 0 (i ≠ j) plus each vi ≠ 0 vi · vj = δij (the Kronecker delta)
Coordinate of x along vi ci = (vi · x) / (vi · vi) ci = qi · x
Linear independence automatic (nonzero vectors) automatic (unit vectors are nonzero)
Going between the two divide each vi by ‖vi‖ → orthonormal already orthogonal as a special case

Orthogonal and Orthonormal Bases

An orthogonal basis is an orthogonal set that spans the space. An orthonormal basis is an orthonormal set that spans the space.

COROLLARY
In Rn\mathbb{R}^n, an orthogonal set of nn nonzero vectors is automatically a basis — independence is guaranteed by orthogonality, and nn independent vectors in an nn-dimensional space automatically span.

So the only check needed is: do I have nn pairwise-orthogonal nonzero vectors? If yes, they form a basis.

Orthonormal bases exist for every finite-dimensional inner product space. The Gram-Schmidt process constructs one from any given basis. This means the computational advantages of orthonormal bases are always available — any space that has a basis at all has an orthonormal one.

Coordinates via Dot Products

The defining computational advantage of orthogonal bases is that coordinates are extracted by individual dot products.

For an orthogonal basis {v1,…,vn}\{\mathbf{v}_1, \dots, \mathbf{v}_n\}, the coordinate of x\mathbf{x} along vi\mathbf{v}_i is

Coordinates via Dot Products
ci=x⋅vivi⋅vic_i = \frac{\mathbf{x} \cdot \mathbf{v}_i}{\mathbf{v}_i \cdot \mathbf{v}_i}

For an orthonormal basis {q1,…,qn}\{\mathbf{q}_1, \dots, \mathbf{q}_n\}, the denominator is 11, and the formula simplifies to

Coordinates via Orthonormal Basis
ci=x⋅qic_i = \mathbf{x} \cdot \mathbf{q}_i

No linear system needs to be solved. No matrix needs to be inverted. Each coordinate is computed independently by a single dot product.

Worked Example
Let {q1,q2,q3}\{\mathbf{q}_1, \mathbf{q}_2, \mathbf{q}_3\} be an orthonormal basis for R3\mathbb{R}^3 with q1=12(1,1,0)\mathbf{q}_1 = \frac{1}{\sqrt{2}}(1, 1, 0), q2=16(1,−1,2)\mathbf{q}_2 = \frac{1}{\sqrt{6}}(1, -1, 2), q3=13(−1,1,1)\mathbf{q}_3 = \frac{1}{\sqrt{3}}(-1, 1, 1).
For x=(3,1,2)\mathbf{x} = (3, 1, 2): c1=x⋅q1=12(3+1+0)=42=22c_1 = \mathbf{x} \cdot \mathbf{q}_1 = \frac{1}{\sqrt{2}}(3 + 1 + 0) = \frac{4}{\sqrt{2}} = 2\sqrt{2}, c2=x⋅q2=16(3−1+4)=66=6c_2 = \mathbf{x} \cdot \mathbf{q}_2 = \frac{1}{\sqrt{6}}(3 - 1 + 4) = \frac{6}{\sqrt{6}} = \sqrt{6}, c3=x⋅q3=13(−3+1+2)=0c_3 = \mathbf{x} \cdot \mathbf{q}_3 = \frac{1}{\sqrt{3}}(-3 + 1 + 2) = 0.
So x=22 q1+6 q2+0⋅q3\mathbf{x} = 2\sqrt{2}\,\mathbf{q}_1 + \sqrt{6}\,\mathbf{q}_2 + 0 \cdot \mathbf{q}_3. The zero third coordinate means x\mathbf{x} has no component in the q3\mathbf{q}_3 direction — it is orthogonal to q3\mathbf{q}_3.

Pitfall: Dropping the denominator
Using ci=x⋅vic_i = \mathbf{x} \cdot \mathbf{v}_i for the set (1,1,1)(1, 1, 1), (1,−2,1)(1, -2, 1), (1,0,−1)(1, 0, -1) and x=(3,1,2)\mathbf{x} = (3, 1, 2) gives (6,3,1)(6, 3, 1), which rebuilds (10,0,8)(10, 0, 8), not x\mathbf{x}. Dividing by 33, 66 and 22 gives (2,12,12)(2, \tfrac{1}{2}, \tfrac{1}{2}).

The worked example uses unit vectors, which is why each coordinate came from a single dot product. Orthogonal bases met in practice are often not normalized, such as the set (1,1,1)(1, 1, 1), (1,−2,1)(1, -2, 1), (1,0,−1)(1, 0, -1) from the first section, and their coordinates are still read off one at a time, with no system to solve.

Orthogonal Matrices

An n×nn \times n matrix QQ is orthogonal if its columns form an orthonormal set. This is equivalent to QTQ=QQT=IQ^TQ = QQ^T = I, which is equivalent to Q−1=QTQ^{-1} = Q^T.

THEOREM
The rows of an orthogonal matrix also form an orthonormal set — orthogonality of columns and rows go together.

The determinant of an orthogonal matrix is ±1\pm 1, since 1=det⁡(I)=det⁡(QTQ)=det⁡(Q)21 = \det(I) = \det(Q^TQ) = \det(Q)^2. When det⁡(Q)=+1\det(Q) = +1, the matrix represents a rotation. When det⁡(Q)=−1\det(Q) = -1, it represents a rotation composed with a reflection.

Pitfall: Stopping at orthogonal columns
Taking M−1=MTM^{-1} = M^T for M=(111−1)M = \begin{pmatrix} 1 & 1 \\ 1 & -1 \end{pmatrix}, whose columns are perpendicular but of length 2\sqrt{2}, fails: MTM=2IM^TM = 2I, so M−1=12MTM^{-1} = \tfrac{1}{2}M^T, and det⁡M=−2\det M = -2. Dividing each column by 2\sqrt{2} gives an orthogonal matrix.

The defining geometric property is that orthogonal matrices preserve the dot product: (Qu)⋅(Qv)=(Qu)T(Qv)=uTQTQv=uTv=u⋅v(Q\mathbf{u}) \cdot (Q\mathbf{v}) = (Q\mathbf{u})^T(Q\mathbf{v}) = \mathbf{u}^TQ^TQ\mathbf{v} = \mathbf{u}^T\mathbf{v} = \mathbf{u} \cdot \mathbf{v}. Preserving the dot product automatically preserves lengths (∥Qx∥=∥x∥\|Q\mathbf{x}\| = \|\mathbf{x}\|), angles, and distances. An orthogonal matrix is a rigid motion of Rn\mathbb{R}^n — it rearranges vectors without distorting any geometric relationship.
Q2×20.866−0.50.50.866x21=Q x1.23211.866,Q2×20.866−0.50.50.866y10=Q y0.8660.5
Columns of length one, pairwise orthogonal

Each column has unit length and every pair is orthogonal, which is exactly the condition that makes the transpose an inverse. Nothing stronger is being asked of the matrix, and nothing weaker would do. Check the transpose-times-itself product on the orthogonal matrices visualizer.

Because the inverse is free, orthogonal matrices are the ones numerical work prefers wherever a choice exists.

Matrices with Orthonormal Columns

An m×nm \times n matrix QQ with m>nm > n can have orthonormal columns without being square. Such a matrix satisfies QTQ=InQ^TQ = I_n but QQT≠ImQQ^T \neq I_m (the product QQTQQ^T is m×mm \times m and has rank n<mn < m).

The matrix QQTQQ^T is the projection matrix onto the column space of QQ. For any b∈Rm\mathbf{b} \in \mathbb{R}^m, the vector QQTbQQ^T\mathbf{b} is the orthogonal projection of b\mathbf{b} onto the nn-dimensional subspace spanned by the columns of QQ.

These rectangular matrices with orthonormal columns are the natural output of the Gram-Schmidt process applied to the columns of a matrix. If AA is m×nm \times n with independent columns, Gram-Schmidt produces an m×nm \times n matrix QQ with orthonormal columns and an n×nn \times n upper triangular matrix RR such that A=QRA = QR. This is the thin QR decomposition.
Property Square orthogonal matrix Q (n × n) Rectangular Q with orthonormal columns (m × n, m > n)
Qᵀ Q In In
Q Qᵀ In NOT the identity; equals the projection matrix onto Col(Q)
Inverse Q⁻¹ = Qᵀ no two-sided inverse (Q is not square)
det(Q) ±1 undefined (Q is not square)
Rows also form an orthonormal set rows are not orthonormal in general
Preserves dot product? yes for all u, v ∈ ℝⁿ — full isometry of ℝⁿ yes from source to image: (Q u) · (Q v) = u · v for u, v ∈ ℝⁿ
Geometric role rotation (det +1) or rotation composed with reflection (det −1) embedding ℝⁿ into ℝᵐ as an n-dimensional subspace
Typical source stored basis change, rotation matrix, Householder/Givens factor output of Gram–Schmidt; the Q in thin QR decomposition A = Q R
A tall matrix with orthonormal columns inverts on one side only: QTQ=IQ^TQ = I, while QQTQQ^T merely projects.

Parseval's Identity and Bessel's Inequality

For an orthonormal basis {q1,…,qn}\{\mathbf{q}_1, \dots, \mathbf{q}_n\} of Rn\mathbb{R}^n and any vector x\mathbf{x}, the coordinates ci=x⋅qic_i = \mathbf{x} \cdot \mathbf{q}_i satisfy Parseval's identity:

Parseval Identity
∥x∥2=∑i=1n(x⋅qi)2\|\mathbf{x}\|^2 = \sum_{i=1}^{n} (\mathbf{x} \cdot \mathbf{q}_i)^2

The squared length of x\mathbf{x} equals the sum of the squares of its coordinates. This is the Pythagorean theorem applied to the orthonormal decomposition x=c1q1+⋯+cnqn\mathbf{x} = c_1\mathbf{q}_1 + \cdots + c_n\mathbf{q}_n.

When the orthonormal set does not span — when k<nk < n — the sum accounts for only part of the length:

Parseval's Identity and Bessel's Inequality
∑i=1k(x⋅qi)2≤∥x∥2\sum_{i=1}^{k} (\mathbf{x} \cdot \mathbf{q}_i)^2 \leq \|\mathbf{x}\|^2

This is Bessel's inequality. The left side is the squared length of the projection of x\mathbf{x} onto Span{q1,…,qk}\text{Span}\{\mathbf{q}_1, \dots, \mathbf{q}_k\}. The deficit ∥x∥2−∑(x⋅qi)2\|\mathbf{x}\|^2 - \sum(\mathbf{x} \cdot \mathbf{q}_i)^2 is the squared length of the component orthogonal to the span. Equality holds if and only if x\mathbf{x} is already in the span, leaving no perpendicular remainder.
In an orthonormal basis, squared length splits exactly among the coordinates, and whatever a partial set misses lies perpendicular to it.

Isometries: Maps That Preserve Length

An isometry is a linear map that preserves length: ∥Tx∥=∥x∥\|T\mathbf{x}\| = \|\mathbf{x}\| for every x\mathbf{x}. Because the dot product can be recovered from lengths alone through the polarization identity

Isometries: Maps That Preserve Length
x⋅y=12(∥x+y∥2−∥x∥2−∥y∥2)\mathbf{x} \cdot \mathbf{y} = \tfrac{1}{2}\left(\|\mathbf{x} + \mathbf{y}\|^2 - \|\mathbf{x}\|^2 - \|\mathbf{y}\|^2\right)

preserving every length forces TT to preserve every dot product, and with it every angle and every distance between points. Nothing is stretched, squashed or sheared.

For a matrix QQ this is exactly the orthogonality condition of the earlier sections. If QTQ=IQ^TQ = I then ∥Qx∥2=xTQTQx=∥x∥2\|Q\mathbf{x}\|^2 = \mathbf{x}^TQ^TQ\mathbf{x} = \|\mathbf{x}\|^2. Conversely, a QQ that preserves all dot products satisfies (Qei)⋅(Qej)=ei⋅ej(Q\mathbf{e}_i) \cdot (Q\mathbf{e}_j) = \mathbf{e}_i \cdot \mathbf{e}_j, so its columns are orthonormal and QTQ=IQ^TQ = I.

THEOREM
The linear isometries of Rn\mathbb{R}^n are precisely the orthogonal matrices.

They split into two families by the determinant. Those with det⁡Q=1\det Q = 1 are rotations, which preserve orientation; those with det⁡Q=−1\det Q = -1 reverse it, and in the plane these are exactly the reflections in a line through the origin. In space an isometry is a rotation about an axis, a reflection in a plane, or a rotation combined with a reflection. Translations also preserve distance but move the origin, so they are not linear and fall outside this classification.

The reflection tool shows the orientation-reversing family in the plane, and the orthogonal matrices tool shows the length-preservation check QTQ=IQ^TQ = I directly.
Length is enough: a linear map that preserves every length preserves all of the geometry, angles and distances included.

Summary: Operations in an Orthonormal Basis

An orthonormal basis converts every routine vector operation into something that uses only dot products — no system solving, no matrix inversion, no (AᵀA)⁻¹ factor. The table below collects each operation alongside its formula in an orthonormal basis and a brief note on why orthonormality makes it simple, including Parseval's identity for length and Bessel's inequality for partial projections.
Every row below is an operation that becomes simpler in an orthonormal basis, and the simplification is always the same one: a linear system turns into a dot product. Reading them together shows that these are not six separate conveniences but six consequences of a single fact about the basis vectors.
DownloadPNG2×PDF
Orthogonality · orthonormal bases

Operations in an orthonormal basis

Each row is an operation that costs a linear system in a general basis and costs a dot product here. The saving is not incremental — the system disappears entirely, because orthogonality makes the coordinates independent of each other.

6operations
Coordinates2
1
one dot product per coordinate
ci=x⋅qic_i = \mathbf{x} \cdot \mathbf{q}_i
In a general basis this means solving Bc=xB\mathbf{c} = \mathbf{x} — all coordinates at once, none available before the rest. Here each is an independent dot product, so any single coordinate can be computed without the others. This is the entry the rest depend on.
2
over a full orthonormal basis
x=∑(x⋅qi) qi\mathbf{x} = \sum (\mathbf{x} \cdot \mathbf{q}_i)\,\mathbf{q}_i
The expansion written out. Each term is the component of x\mathbf{x} along one basis direction, so the sum is a decomposition into perpendicular pieces rather than an arbitrary combination that happens to work.
Lengths and angles2
3
Parseval’s identity
∥x∥2=∑ci2\|\mathbf{x}\|^2 = \sum c_i^2
Pythagoras in nn dimensions. The length of a vector is recoverable from its coordinates alone — which fails in a general basis, where the coordinates say nothing about length without the Gram matrix to weight them.
4
coordinates in the same basis
x⋅y=∑cidi\mathbf{x} \cdot \mathbf{y} = \sum c_i d_i
The inner product of the vectors is the ordinary dot product of their coordinate vectors. Geometry is preserved exactly under the change of coordinates, which is what makes an orthonormal basis a rigid motion rather than a distortion.
Projection onto a subspace2
5
{qi}\{\mathbf{q}_i\} orthonormal basis for WW
proj⁡Wx=∑i=1k(x⋅qi) qi\operatorname{proj}_W \mathbf{x} = \sum_{i=1}^{k} (\mathbf{x} \cdot \mathbf{q}_i)\,\mathbf{q}_i
No (ATA)−1(A^{\mathsf{T}}A)^{-1} anywhere — compare the general projection formula, which needs a matrix inverse. Orthonormality makes ATA=IA^{\mathsf{T}}A = I, so the inverse is the identity and the formula collapses to a sum of independent terms.
6
equality iff x∈W\mathbf{x} \in W
∑i=1kci2≤∥x∥2\sum_{i=1}^{k} c_i^2 \leq \|\mathbf{x}\|^2
A truncated sum can only lose length. The deficit is exactly the squared distance from x\mathbf{x} to WW, so the inequality measures how much of the vector the subspace fails to capture — which is the least-squares error before any least-squares problem is posed.
One fact produces all of them: qi⋅qj\mathbf{q}_i \cdot \mathbf{q}_j is 11 when i=ji = j and 00 otherwise, so every cross term in every expansion vanishes. That is why an orthonormal basis is worth the Gram–Schmidt cost of constructing one — the expense is paid once and every operation afterwards is cheaper.
Operations in an orthonormal basis·/linear-algebra/orthogonality/orthogonal-setsLearn Math Class
What changes is that the coordinates stop depending on each other. In a general basis, finding one coordinate of x\mathbf{x} means solving for all of them at once — the system Bc=xB\mathbf{c} = \mathbf{x} couples every unknown to every other. With an orthonormal basis each coordinate is an independent dot product, so a single one can be computed alone, and adding a new basis vector does not change the coordinates already found.
The projection row is where this pays off most visibly. The general formula requires (ATA)−1(A^{\mathsf{T}}A)^{-1}, a matrix inverse computed before anything can be projected. When the columns are orthonormal, ATAA^{\mathsf{T}}A is the identity, the inverse disappears, and the projection is a sum of independent terms — which is precisely why Gram–Schmidt is worth running before a projection-heavy computation rather than after.
Common Pitfalls

Three mistakes cause many wrong answers with orthogonal sets. Each is marked with a box where it happens in the sections above. Here each is worked through in full, with the wrong and the right working side by side.

Dividing by the squared length

Normalizing a vector means dividing it by its length ∥v∥=v⋅v\|\mathbf{v}\| = \sqrt{\mathbf{v} \cdot \mathbf{v}}. The square root is left out, and the vector is divided by v⋅v\mathbf{v} \cdot \mathbf{v} instead.

Wrong working:
v=(1,−2,1),v⋅v=6,v6=(16,−13,16)\mathbf{v} = (1, -2, 1), \quad \mathbf{v} \cdot \mathbf{v} = 6, \quad \frac{\mathbf{v}}{6} = \left(\tfrac{1}{6}, -\tfrac{1}{3}, \tfrac{1}{6}\right)

Its length is 136+19+136=16≈0.41\sqrt{\tfrac{1}{36} + \tfrac{1}{9} + \tfrac{1}{36}} = \sqrt{\tfrac{1}{6}} \approx 0.41, so the result is not a unit vector.

Right working:
∥v∥=6,v^=16(1,−2,1),v^⋅v^=1+4+16=1\|\mathbf{v}\| = \sqrt{6}, \quad \hat{\mathbf{v}} = \frac{1}{\sqrt{6}}(1, -2, 1), \quad \hat{\mathbf{v}} \cdot \hat{\mathbf{v}} = \frac{1 + 4 + 1}{6} = 1


Why it happens: the squared length v⋅v\mathbf{v} \cdot \mathbf{v} is the number already at hand. It is the denominator of the coordinate formula ci=x⋅vivi⋅vic_i = \frac{\mathbf{x} \cdot \mathbf{v}_i}{\mathbf{v}_i \cdot \mathbf{v}_i} and of projection formulas, while normalizing needs the length itself.

How to check: take the dot product of the result with itself; it must be 11. After dividing by v⋅v\mathbf{v} \cdot \mathbf{v} it is 1v⋅v\frac{1}{\mathbf{v} \cdot \mathbf{v}} instead, here 16\tfrac{1}{6}.

Dropping the denominator

The coordinate formula for an orthonormal basis, ci=x⋅qic_i = \mathbf{x} \cdot \mathbf{q}_i, is applied to an orthogonal basis whose vectors are not unit vectors. The denominator vi⋅vi\mathbf{v}_i \cdot \mathbf{v}_i equals 11 only when ∥vi∥=1\|\mathbf{v}_i\| = 1.

Wrong working: with v1=(1,1,1)\mathbf{v}_1 = (1, 1, 1), v2=(1,−2,1)\mathbf{v}_2 = (1, -2, 1), v3=(1,0,−1)\mathbf{v}_3 = (1, 0, -1) and x=(3,1,2)\mathbf{x} = (3, 1, 2),
x⋅v1=6,x⋅v2=3,x⋅v3=1\mathbf{x} \cdot \mathbf{v}_1 = 6, \quad \mathbf{x} \cdot \mathbf{v}_2 = 3, \quad \mathbf{x} \cdot \mathbf{v}_3 = 1

Taking these as the coordinates gives 6v1+3v2+1v3=(10,0,8)6\mathbf{v}_1 + 3\mathbf{v}_2 + 1\mathbf{v}_3 = (10, 0, 8), not x\mathbf{x}.

Right working: divide each dot product by vi⋅vi\mathbf{v}_i \cdot \mathbf{v}_i, which is 33, 66 and 22.
c1=63=2,c2=36=12,c3=12c_1 = \frac{6}{3} = 2, \quad c_2 = \frac{3}{6} = \frac{1}{2}, \quad c_3 = \frac{1}{2}

Then 2v1+12v2+12v3=(2+12+12,  2−1+0,  2+12−12)=(3,1,2)2\mathbf{v}_1 + \tfrac{1}{2}\mathbf{v}_2 + \tfrac{1}{2}\mathbf{v}_3 = (2 + \tfrac{1}{2} + \tfrac{1}{2}, \; 2 - 1 + 0, \; 2 + \tfrac{1}{2} - \tfrac{1}{2}) = (3, 1, 2).

Why it happens: the orthonormal formula is the one that gets remembered, because it is shorter and worked examples tend to use unit vectors. Orthogonal sets with whole-number entries, such as this one, are rarely normalized.

How to check: rebuild x\mathbf{x} from the coordinates. With the denominator missing, each coordinate is too large by the factor vi⋅vi\mathbf{v}_i \cdot \mathbf{v}_i.

Stopping at orthogonal columns

A square matrix whose columns are pairwise perpendicular is treated as an orthogonal matrix, and its transpose is used as its inverse. The definition also requires every column to have length 11.

Wrong working:
M=(111−1),M−1=MT=(111−1)M = \begin{pmatrix} 1 & 1 \\ 1 & -1 \end{pmatrix}, \quad M^{-1} = M^T = \begin{pmatrix} 1 & 1 \\ 1 & -1 \end{pmatrix}

But MTM=(2002)=2IM^TM = \begin{pmatrix} 2 & 0 \\ 0 & 2 \end{pmatrix} = 2I, not II, so MTM^T is not the inverse.

Right working: the columns have length 2\sqrt{2}, so M−1=12MT=(121212−12)M^{-1} = \tfrac{1}{2}M^T = \begin{pmatrix} \tfrac{1}{2} & \tfrac{1}{2} \\ \tfrac{1}{2} & -\tfrac{1}{2} \end{pmatrix}. Dividing each column by 2\sqrt{2} gives the orthogonal matrix Q=12(111−1)Q = \frac{1}{\sqrt{2}}\begin{pmatrix} 1 & 1 \\ 1 & -1 \end{pmatrix}, with QTQ=IQ^TQ = I and Q−1=QTQ^{-1} = Q^T.

Why it happens: the name says orthogonal, and the columns are orthogonal. Unit length is part of the definition but not of the name.

How to check: compute MTMM^TM. A diagonal result with entries other than 11 means the columns are orthogonal but not unit length. The determinant is a quick test too: an orthogonal matrix has det⁡=±1\det = \pm 1, and here det⁡M=−2\det M = -2.

Orthogonal Sets FAQ

Does an "orthogonal matrix" just have orthogonal columns?

+
No, they must be orthonormal, so unit length is part of the definition despite the name. A matrix whose columns are merely perpendicular satisfies no identity of this kind. The terminology is a historical accident that the notation refuses to repeat, which is why the condition is always written QTQ=IQ^{T}Q = I rather than described in words.Read more →

What is δij\delta_{ij}?

+
The Kronecker delta, a function of two indices returning 11 when they agree and 00 otherwise. It is the identity matrix written entrywise, I=[δij]I = [\delta_{ij}]. Do not read it as the δ\delta of calculus: nothing here is small or an increment, and this symbol takes two subscripts rather than measuring a magnitude.Read more →

If QTQ=IQ^{T}Q = I, does QQT=IQQ^{T} = I as well?

+
Yes, for square QQ, and this is one of the few places where such a swap is safe. The equation is a statement about the columns being orthonormal, and it forces the rows to be orthonormal too. Most matrix identities are not symmetric in that way, so the fact is worth noting rather than assuming.Read more →

Can an orthogonal set contain the zero vector?

+
No, the definition requires every vector to be nonzero. The set {(1,0),(0,0)}\{(1, 0), (0, 0)\} passes the dot-product test only because 0\mathbf{0} is orthogonal to everything, and 0\mathbf{0} carries no direction. Allowing it would also break the guarantee that orthogonal sets are independent: 0⋅(1,0)+1⋅(0,0)=00 \cdot (1, 0) + 1 \cdot (0, 0) = \mathbf{0} is a combination with a nonzero coefficient that still gives zero.Read more →

For which nn is there an orthogonal basis of Rn\mathbb{R}^n with every entry ±1\pm 1?

+
For n=1n = 1, n=2n = 2, and otherwise only when nn is a multiple of 44. In R4\mathbb{R}^4, for example, (1,1,1,1)(1, 1, 1, 1), (1,−1,1,−1)(1, -1, 1, -1), (1,1,−1,−1)(1, 1, -1, -1) and (1,−1,−1,1)(1, -1, -1, 1) are pairwise orthogonal. For n≥3n \geq 3, any three such vectors sort the nn positions into four equal groups by which signs agree, which forces the multiple of 44. Whether every multiple of 44 actually works is still unproved.Read more →

Does adding a vector to an orthonormal set change the coefficients already found?

+
No. Each coefficient ci=x⋅qic_i = \mathbf{x} \cdot \mathbf{q}_i uses only x\mathbf{x} and qi\mathbf{q}_i, so extending the set from kk to k+1k + 1 vectors adds one new term and leaves the first kk untouched. With a set that is not orthogonal, the coefficients come from a linear system that couples every unknown to every other, so one new vector can change all of them.Read more →