Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Geometric Transformations


Rotations, Reflections, Projections, and More

In R² and R³, linear transformations have concrete geometric meanings. Each has an explicit matrix encoding its action: rotations spin, reflections mirror, projections flatten, shears skew, and scalings stretch or compress. The determinant of the matrix classifies the transformation by how it affects area, volume, and orientation.


How to Read a Transformation Matrix

The geometric effect of a matrix AA is revealed by two pieces of information: what it does to the standard basis vectors (the columns) and what its determinant is.

Column 11 is the image of e1=(1,0)\mathbf{e}_1 = (1, 0) in R2\mathbb{R}^2 or (1,0,0)(1, 0, 0) in R3\mathbb{R}^3. Column 22 is the image of e2\mathbf{e}_2. The matrix maps the standard grid to the parallelogram (or parallelepiped) spanned by these column vectors.

RULE
The absolute value ∣det⁡(A)∣|\det(A)| measures how the transformation scales areas (in R2\mathbb{R}^2) or volumes (in R3\mathbb{R}^3).

The sign of det⁡(A)\det(A) indicates orientation: positive means the transformation preserves handedness, negative means it reverses it. An orthogonal matrix (det⁡=±1\det = \pm 1) preserves all lengths and angles — it is a rigid motion.

Pitfall: Mistaking area-preserving for rigid
Treating det⁡=±1\det = \pm 1 as proof of a rigid motion fails for (1101)\begin{pmatrix} 1 & 1 \\ 0 & 1 \end{pmatrix}: its determinant is 11, yet it sends (0,1)(0, 1) to (1,1)(1, 1), of length 2\sqrt{2}. A rigid motion needs ATA=IA^T A = I; here ATA=(1112)A^T A = \begin{pmatrix} 1 & 1 \\ 1 & 2 \end{pmatrix}.

Both readings are needed. The determinant is a single number, and it records only what happens to area and to orientation. The columns carry the rest of the picture: their lengths and the angle between them show whether each square of the grid keeps its shape or comes out stretched and tilted.

Geometric Transformation Notation

Notation

Geometric Transformation Notation

Named matrices with their defining parameter hung in the subscript — an angle, an axis, a factor — so the letter says what kind of motion it is and the subscript says which one. Two sign conventions ride along, and one composition order that reads backwards. All catalogued among the linear algebra symbols.
The matrix bracket anatomy and ABAB juxtaposition come from matrix operation notation; det⁡\det and ∣det⁡∣|\det| as a scale factor from determinant and determinant geometry notation; [T][T] and its columns from matrix representation notation; θ\theta, cos⁡\cos and sin⁡\sin from trigonometric notation.
RθR_\theta, SkS_k, PWP_W
rotation by theta, scaling by k, projection onto W
A naming scheme rather than three separate symbols: the letter names the kind of motion and the subscript supplies the parameter that pins down which one. The subscript's type varies with the letter — an angle for RR, a number for SS, a whole subspace for the projection matrix — and reading it wrongly is the usual way these get confused.
CasesIn R3\mathbb{R}^3 the rotation needs an axis as well, so the subscript grows: Rz,θR_{z,\theta} or Rn(θ)R_{\mathbf{n}}(\theta) name the axis first and the angle second — the convention varies, and Rotations in R³ below fixes one.
Do not confusePP at its other jobs. The same letter is a projection here, a change-of-basis matrix elsewhere, and a permutation matrix in factorisations — three unrelated tenants distinguished only by what sits in the subscript.
Rθ=(cos⁡θ−sin⁡θsin⁡θcos⁡θ)R_\theta = \begin{pmatrix} \cos\theta & -\sin\theta \\ \sin\theta & \cos\theta \end{pmatrix}
the minus sign sits above the diagonal — counterclockwise
The placement of the single minus is the entire convention: with −sin⁡θ-\sin\theta in the upper right, positive θ\theta turns counterclockwise, the standard orientation this page uses. Transposing the matrix — equivalently negating θ\theta — reverses the direction.
CasesComputer graphics often uses the opposite sign because screen coordinates run yy downward, so the same matrix appears with the minus below the diagonal and still called "rotation by θ\theta"; the convention is a property of the coordinate system, not of the formula.
Do not confuseThe rotation's inverse as something to be computed. Rθ−1=R−θ=RθTR_\theta^{-1} = R_{-\theta} = R_\theta^{T} — the transpose already is the inverse, since a rotation is orthogonal, and inverting one by elimination is wasted effort.
BABA means "do AA first"
the rightmost factor acts first
Composing transformations writes the matrices in the reverse of the order they happen — Combining Transformations below relies on it — because each acts on the column to its right. The notation inherits its direction from function composition, not from reading order.
CasesThe consequence is that AB≠BAAB \neq BA carries geometric meaning here: rotating then reflecting is a different motion from reflecting then rotating, and the notation's order is what records which was meant.
Do not confuseLeft-to-right execution. Writing RθSkR_\theta S_k and reading it as "rotate, then scale" reverses the actual sequence — the scaling happens first, and the mistake is invisible until the two operations fail to commute.

Scaling

Uniform scaling multiplies every coordinate by the same factor: T(x)=cxT(\mathbf{x}) = c\mathbf{x}, with matrix cIcI. When c>1c > 1 the transformation enlarges, when 0<c<10 < c < 1 it shrinks, and when c<0c < 0 it reflects through the origin and scales.

Non-uniform scaling stretches each axis independently. In R2\mathbb{R}^2, T(x,y)=(c1x,c2y)T(x, y) = (c_1 x, c_2 y) has matrix diag(c1,c2)\text{diag}(c_1, c_2). The horizontal axis is scaled by c1c_1 and the vertical by c2c_2. A unit square maps to a rectangle with side lengths ∣c1∣|c_1| and ∣c2∣|c_2|.

The determinant is cnc^n for uniform scaling and c1c2c_1 c_2 (or c1c2c3c_1 c_2 c_3) for non-uniform. When any scaling factor is zero, the transformation collapses that axis entirely and the determinant is zero.

Pitfall: Forgetting the power of c
Writing det⁡(cI)=c\det(cI) = c gives det⁡(3I)=3\det(3I) = 3 in R3\mathbb{R}^3, although the unit cube becomes a cube of side 33. Each of the three axes contributes a factor 33, so det⁡(3I)=33=27\det(3I) = 3^3 = 27.

In R3\mathbb{R}^3, diag(c1,c2,c3)\text{diag}(c_1, c_2, c_3) scales each coordinate axis independently. The unit cube maps to a rectangular box with side lengths ∣c1∣|c_1|, ∣c2∣|c_2|, ∣c3∣|c_3| and volume ∣c1c2c3∣|c_1 c_2 c_3|.
Uniform scaling by 1.5 applied to the unit squareAe₁ = (1.5, 0)Ae₂ = (0, 1.5)unit squareA = 1.5 I: a square of side 1.5, area 2.25uniform scaling: every direction stretched by 1.5
Scaling the unit square by 1.5

The dashed unit square and its image. With A = 1.5I, e₁ lands at (1.5, 0) and e₂ at (0, 1.5), so the square becomes a square of side 1.5 — every direction stretched by the same factor, the area multiplied by 1.5² = 2.25, the shape unchanged.

Scaling by c multiplies every length by |c| and every area by c².

Rotations in R²

Rotation by angle θ\theta counterclockwise about the origin has matrix

Rotation Matrix 2D
Rθ=(cos⁡θ−sin⁡θsin⁡θcos⁡θ)R_\theta = \begin{pmatrix} \cos\theta & -\sin\theta \\ \sin\theta & \cos\theta \end{pmatrix}
Learn more about this formula: Rotation Matrix 2D →


The first column Rθe1=(cos⁡θ,sin⁡θ)R_\theta \mathbf{e}_1 = (\cos\theta, \sin\theta) is the image of (1,0)(1, 0) — the point on the unit circle at angle θ\theta. The second column Rθe2=(−sin⁡θ,cos⁡θ)R_\theta \mathbf{e}_2 = (-\sin\theta, \cos\theta) is the image of (0,1)(0, 1) — the point at angle θ+90°\theta + 90°.

The determinant is cos⁡2θ+sin⁡2θ=1\cos^2\theta + \sin^2\theta = 1 for every θ\theta: rotations preserve areas and orientation. The matrix is orthogonal: RθTRθ=IR_\theta^T R_\theta = I, so lengths and angles are preserved. The inverse is Rθ−1=R−θ=RθTR_\theta^{-1} = R_{-\theta} = R_\theta^T — rotating backward by the same angle.

RULE
Rotations compose by adding angles: RαRβ=Rα+βR_\alpha R_\beta = R_{\alpha + \beta}.

This follows from the trigonometric addition formulas and corresponds to the fact that rotating by β\beta then by α\alpha is the same as rotating by α+β\alpha + \beta.

Common cases: R90°=(0−110)R_{90°} = \begin{pmatrix} 0 & -1 \\ 1 & 0 \end{pmatrix}, R180°=(−100−1)R_{180°} = \begin{pmatrix} -1 & 0 \\ 0 & -1 \end{pmatrix}, R45°=12(1−111)R_{45°} = \frac{1}{\sqrt{2}}\begin{pmatrix} 1 & -1 \\ 1 & 1 \end{pmatrix}.
Rotation by 30 degrees applied to the unit squareAe₁ = (cos θ, sin θ)Ae₂ = (−sin θ, cos θ)unit squareθ = 30°: the columns of A are where e₁ and e₂ landrotation by 30°: the square turns, its size unchanged
Rotating the unit square by 30°

Under a rotation by θ, e₁ lands at (cos θ, sin θ) and e₂ at (−sin θ, cos θ) — exactly the two columns of the rotation matrix. The image is the same square turned about the origin: lengths, angles and area all survive, which is why the determinant is 1.

A rotation matrix is written down by asking one question: where do e₁ and e₂ go?

Rotations in R³

In three dimensions, a rotation is specified by an axis and an angle. The three coordinate-axis rotation matrices are:

Rotation Matrices 3D
Rx(θ)=(1000cos⁡θ−sin⁡θ0sin⁡θcos⁡θ),    Ry(θ)=(cos⁡θ0sin⁡θ010−sin⁡θ0cos⁡θ),    Rz(θ)=(cos⁡θ−sin⁡θ0sin⁡θcos⁡θ0001)R_x(\theta) = \begin{pmatrix} 1 & 0 & 0 \\ 0 & \cos\theta & -\sin\theta \\ 0 & \sin\theta & \cos\theta \end{pmatrix}, \;\; R_y(\theta) = \begin{pmatrix} \cos\theta & 0 & \sin\theta \\ 0 & 1 & 0 \\ -\sin\theta & 0 & \cos\theta \end{pmatrix}, \;\; R_z(\theta) = \begin{pmatrix} \cos\theta & -\sin\theta & 0 \\ \sin\theta & \cos\theta & 0 \\ 0 & 0 & 1 \end{pmatrix}
Learn more about this formula: Rotation Matrices 3D →


Rotation by θ\theta about the zz-axis leaves the zz-coordinate unchanged and rotates the xyxy-plane:

Rotations in R³
Rz(θ)=(cos⁡θ−sin⁡θ0sin⁡θcos⁡θ0001)R_z(\theta) = \begin{pmatrix} \cos\theta & -\sin\theta & 0 \\ \sin\theta & \cos\theta & 0 \\ 0 & 0 & 1 \end{pmatrix}

Rotations about the xx-axis and yy-axis have the same 2×22 \times 2 rotation block embedded in different positions:

Rotations in R³
Rx(θ)=(1000cos⁡θ−sin⁡θ0sin⁡θcos⁡θ),Ry(θ)=(cos⁡θ0sin⁡θ010−sin⁡θ0cos⁡θ)R_x(\theta) = \begin{pmatrix} 1 & 0 & 0 \\ 0 & \cos\theta & -\sin\theta \\ 0 & \sin\theta & \cos\theta \end{pmatrix}, \quad R_y(\theta) = \begin{pmatrix} \cos\theta & 0 & \sin\theta \\ 0 & 1 & 0 \\ -\sin\theta & 0 & \cos\theta \end{pmatrix}

RULE
Every 3×33 \times 3 rotation matrix is orthogonal with determinant +1+1.

Pitfall: Misplacing the sign for the y-axis
Copying the top-right −sin⁡θ-\sin\theta of RxR_x and RzR_z into RyR_y gives Ry(−θ)R_y(-\theta): at θ=90°\theta = 90° it sends (0,0,1)(0, 0, 1) to (−1,0,0)(-1, 0, 0). In the correct Ry(θ)R_y(\theta) the −sin⁡θ-\sin\theta sits bottom left, and Ry(90°)R_y(90°) sends (0,0,1)(0, 0, 1) to (1,0,0)(1, 0, 0).

Each of these matrices can be checked one column at a time, exactly as in the plane: column jj is the image of ej\mathbf{e}_j. The direction of turn comes from the right-hand rule. With the thumb along the positive yy-axis, the fingers curl from the positive zz-axis toward the positive xx-axis, so in the xzxz-plane the turn runs from zz to xx rather than from xx to zz.

The axis of rotation is the eigenvector with eigenvalue 11 — the direction that remains fixed. Any rotation in R3\mathbb{R}^3 can be decomposed into rotations about the coordinate axes (Euler angles), though the decomposition is not unique.

Fact: Two quarter turns, one third of a turn
The product Rz(90°) Rx(90°)R_z(90°)\,R_x(90°) is a single turn by 120°120° about the diagonal line through (1,1,1)(1, 1, 1). Every rotation of space has such an axis (Euler's rotation theorem): for a rotation det⁡(R−I)=det⁡(I−R)\det(R - I) = \det(I - R), and in odd dimension that forces the value 00.

Products of these matrices are where the templates stop helping. Turning by 90°90° about the xx-axis and then by 90°90° about the zz-axis gives Rz(90°) Rx(90°)=(001100010)R_z(90°)\,R_x(90°) = \begin{pmatrix} 0 & 0 & 1 \\ 1 & 0 & 0 \\ 0 & 1 & 0 \end{pmatrix}. None of the coordinate axes is left in place, since the columns send e1\mathbf{e}_1 to e2\mathbf{e}_2, e2\mathbf{e}_2 to e3\mathbf{e}_3 and e3\mathbf{e}_3 to e1\mathbf{e}_1. The matrix is still orthogonal with determinant +1+1, yet none of the three templates above describes the motion it performs.
Axis of rotation Matrix Fixed direction Plane that rotates
x-axis: Rₓ(θ) [1  0  0; 0  cosθ  −sinθ; 0  sinθ  cosθ] x-coordinate unchanged yz-plane
y-axis: R_y(θ) [cosθ  0  sinθ; 0  1  0; −sinθ  0  cosθ] y-coordinate unchanged xz-plane
z-axis: R_z(θ) [cosθ  −sinθ  0; sinθ  cosθ  0; 0  0  1] z-coordinate unchanged xy-plane
A rotation of space is a plane rotation around a fixed axis: the axis stays put while everything turns around it.

Reflections in R²

Reflection across the xx-axis flips the yy-coordinate: T(x,y)=(x,−y)T(x, y) = (x, -y), with matrix (100−1)\begin{pmatrix} 1 & 0 \\ 0 & -1 \end{pmatrix}.

Reflection across the yy-axis flips the xx-coordinate: matrix (−1001)\begin{pmatrix} -1 & 0 \\ 0 & 1 \end{pmatrix}.

Reflection across the line y=xy = x swaps coordinates: matrix (0110)\begin{pmatrix} 0 & 1 \\ 1 & 0 \end{pmatrix}.

Reflection across an arbitrary line through the origin at angle α\alpha has matrix

Reflection Across Line 2D
Hα=(cos⁡2αsin⁡2αsin⁡2α−cos⁡2α)H_\alpha = \begin{pmatrix} \cos 2\alpha & \sin 2\alpha \\ \sin 2\alpha & -\cos 2\alpha \end{pmatrix}
Learn more about this formula: Reflection Across Line 2D →


RULE
All reflection matrices share the same properties: the determinant is −1-1 (orientation-reversing, area-preserving), the matrix is orthogonal (lengths and angles preserved), and the matrix is involutory (H2=IH^2 = I) — reflecting twice returns every vector to its starting point.

The eigenvalues are +1+1 (vectors on the mirror line) and −1-1 (vectors perpendicular to it).
Transformations · reflections

Reflections in the plane

Four mirrors, four matrices. The first three are special cases of the fourth — substituting α=0\alpha = 0, π2\tfrac{\pi}{2} and π4\tfrac{\pi}{4} into the general form recovers them exactly.

4mirrors
Mirrors along the axes2
The x-axis§ 5α=0\alpha = 0
matrix[100−1]\begin{bmatrix} 1 & 0 \\ 0 & -1 \end{bmatrix}
effect on (x, y)(x,y)↦(x,−y)(x, y) \mapsto (x, -y)
fixed directionthe xx-axis
Diagonal, so its action is entrywise: the first coordinate survives and the second flips. The eigenvalues sit on the diagonal, +1+1 and −1-1, exactly as the general result predicts.
The y-axis§ 5α=π2\alpha = \tfrac{\pi}{2}
matrix[−1001]\begin{bmatrix} -1 & 0 \\ 0 & 1 \end{bmatrix}
effect on (x, y)(x,y)↦(−x,y)(x, y) \mapsto (-x, y)
fixed directionthe yy-axis
The same matrix with the signs exchanged, which makes it the negative of the row above. Negating both diagonal entries of II instead gives −I-I, a rotation by π\pi, which reverses both coordinates and has det⁡=+1\det = +1.
Mirror at 45 degrees1
The line y=xy = x§ 5α=π4\alpha = \tfrac{\pi}{4}
matrix[0110]\begin{bmatrix} 0 & 1 \\ 1 & 0 \end{bmatrix}
effect on (x, y)(x,y)↦(y,x)(x, y) \mapsto (y, x)
fixed directionthe line y=xy = x
Swapping coordinates is a reflection, which is worth noticing because it also describes the transpose at the level of a 2×22 \times 2 permutation. Its own inverse, as every reflection is.
The general mirror1
Line at angle α\alpha§ 5any line through the origin
matrix[cos⁡2αsin⁡2αsin⁡2α−cos⁡2α]\begin{bmatrix} \cos 2\alpha & \sin 2\alpha \\ \sin 2\alpha & -\cos 2\alpha \end{bmatrix}
effect on (x, y)reflects across that line
fixed directionthe mirror line itself
The 2α2\alpha is not a typo: rotating the mirror by α\alpha turns the image by 2α2\alpha, since the incoming and outgoing rays each make angle α\alpha with it. Symmetric and orthogonal at once, which is unusual and is why A−1=AT=AA^{-1} = A^{\mathsf{T}} = A.
Every reflection has det⁡=−1\det = -1, eigenvalues +1+1 along the mirror and −1-1 across it, and equals its own inverse. Those three facts hold whatever α\alpha is, which is what makes reflection a family rather than a list — and why the general row is the only one that has to be remembered.
Reflections in the plane·/linear-algebra/transformations/geometricLearn Math Class
The doubled angle in the general matrix is the detail worth pausing on. Rotating the mirror by α\alpha moves the image by 2α2\alpha, because the incoming ray and the outgoing ray each make angle α\alpha with the line — so the total turn is twice the tilt. It also explains why composing two reflections gives a rotation by twice the angle between their mirrors, which is the fastest route to that result.
mirrorPvRvvmirrorPvRvv
Reflection in an axis, then in a diagonal

Points on the mirror line stay exactly where they are while everything else swaps to the far side at equal distance. Changing the line changes the matrix but not the behaviour, and applying either matrix twice returns every point to its start. Rotate the mirror line and watch the entries change on the reflection explorer.

Any orthogonal matrix with determinant −1 in two dimensions is a reflection of this kind, and such a matrix is automatically its own inverse.

Reflections in R³

Reflection across a coordinate plane negates the coordinate perpendicular to that plane. Reflection across the xyxy-plane: diag(1,1,−1)\text{diag}(1, 1, -1). Across the xzxz-plane: diag(1,−1,1)\text{diag}(1, -1, 1). Across the yzyz-plane: diag(−1,1,1)\text{diag}(-1, 1, 1).

Reflection across an arbitrary plane through the origin with unit normal n\mathbf{n} is given by the Householder matrix:

Householder Reflection
H=I−2 nnTH = I - 2\,\mathbf{n}\mathbf{n}^T
Learn more about this formula: Householder Reflection →


This matrix subtracts twice the component of each vector in the direction of n\mathbf{n}, effectively mirroring across the plane perpendicular to n\mathbf{n}. Householder reflections are orthogonal, have determinant −1-1, and satisfy H2=IH^2 = I. They are the building blocks of the QR decomposition and are widely used in numerical algorithms.
A reflection keeps its mirror fixed and reverses only the one direction perpendicular to it.

Projections

Orthogonal projection onto a subspace collapses each vector onto its nearest point in the subspace, discarding the perpendicular component.

Projection onto the xx-axis in R2\mathbb{R}^2: T(x,y)=(x,0)T(x, y) = (x, 0), with matrix (1000)\begin{pmatrix} 1 & 0 \\ 0 & 0 \end{pmatrix}.

Projection onto a line through the origin in direction u\mathbf{u}:

Projection onto Line
P=uuTuTuP = \frac{\mathbf{u}\mathbf{u}^T}{\mathbf{u}^T\mathbf{u}}
Learn more about this formula: Projection onto Line →


Projection onto a plane with unit normal n\mathbf{n} in R3\mathbb{R}^3:

Projection onto Plane
P=I−nnTnTnP = I - \frac{\mathbf{n}\mathbf{n}^T}{\mathbf{n}^T\mathbf{n}}
Learn more about this formula: Projection onto Plane →


Pitfall: Dropping the denominator of P
Using uuT\mathbf{u}\mathbf{u}^T alone for u=(1,2)\mathbf{u} = (1, 2) gives (1224)\begin{pmatrix} 1 & 2 \\ 2 & 4 \end{pmatrix}, which sends (1,2)(1, 2) to (5,10)(5, 10) instead of leaving it in place. Dividing by uTu=5\mathbf{u}^T\mathbf{u} = 5 gives P=15(1224)P = \frac{1}{5}\begin{pmatrix} 1 & 2 \\ 2 & 4 \end{pmatrix}, and P(1,2)=(1,2)P(1, 2) = (1, 2).

All orthogonal projection matrices share the same algebraic signature: P2=PP^2 = P (idempotent — projecting twice is the same as projecting once), PT=PP^T = P (symmetric), eigenvalues are 00 or 11, and rank(P)=tr(P)\text{rank}(P) = \text{tr}(P). The determinant is 00 unless the projection is onto the full space — any projection onto a proper subspace collapses at least one dimension.
im Pker PPvv
The plane dropped onto a line

Unlike a reflection, this one destroys information: two different points can land on the same place and there is no way back. The determinant is zero and the matrix is idempotent, which are the algebraic signatures of exactly that loss. Compare it against the reflection above on the 2D projection explorer.

Reflections and rotations preserve information; projections and their relatives are where it starts being lost.

Shears

A shear displaces each point in proportion to its distance from a fixed line or plane. The two 2×22 \times 2 shear matrices are:

Shear Matrix
Shearx=(1k01),Sheary=(10k1)\text{Shear}_x = \begin{pmatrix} 1 & k \\ 0 & 1 \end{pmatrix}, \qquad \text{Shear}_y = \begin{pmatrix} 1 & 0 \\ k & 1 \end{pmatrix}
Learn more about this formula: Shear Matrix →


In R2\mathbb{R}^2, a horizontal shear shifts the xx-coordinate by kk times the yy-coordinate:

Shears
T(x,y)=(x+ky,  y),matrix (1k01)T(x, y) = (x + ky, \; y), \quad \text{matrix } \begin{pmatrix} 1 & k \\ 0 & 1 \end{pmatrix}

A vertical shear shifts the yy-coordinate by kk times the xx-coordinate:

Shears
T(x,y)=(x,  kx+y),matrix (10k1)T(x, y) = (x, \; kx + y), \quad \text{matrix } \begin{pmatrix} 1 & 0 \\ k & 1 \end{pmatrix}

Fact: Three shears make a rotation
For θ≠180°\theta \neq 180°, RθR_\theta equals a horizontal shear by −tan⁡θ2-\tan\frac{\theta}{2}, then a vertical shear by sin⁡θ\sin\theta, then the first shear again. Paeth's 1986 method rotates digital images this way, since each shear only slides whole rows or columns of pixels.

Both are triangular matrices with determinant 11: shears are area-preserving and orientation-preserving. They are not orthogonal — angles are distorted. A square sheared horizontally becomes a parallelogram of the same area but with tilted sides.

In R3\mathbb{R}^3, there are six possible shear directions (each coordinate shifted by a multiple of each other coordinate). Each is represented by an identity matrix with one off-diagonal entry replaced by kk.

Shears and rotations look like opposites. A rotation keeps every length and every angle, while a shear tilts the grid and changes the angle at the corners of every square. Yet both have determinant 11, and the tilt that one shear puts in can be taken out again by a shear acting in the other direction.

THEOREM
Shears are fundamental building blocks — any invertible matrix with determinant 11 can be written as a product of shears.
A horizontal shear applied to the unit squareAe₁ = e₁ = (1, 0)Ae₂ = (1, 1)unit squareA = [1 1; 0 1]: same base, same height, area still 1horizontal shear: e₁ stays, e₂ leans over
Shearing the unit square

The horizontal shear [1 1; 0 1] leaves e₁ where it is and pushes e₂ sideways to (1, 1). Every point slides parallel to the x-axis by its own height, so the square leans into a parallelogram with the same base and the same height — and therefore the same area, 1.

A shear changes shape but never area, which is why its determinant is 1.

Combining Transformations

RULE
Composing transformations corresponds to multiplying their matrices.

A rotation followed by a scaling is SASA where SS is the scaling matrix and AA is the rotation matrix. The product is applied right-to-left: AA acts first, then SS.

Order matters. Rotating then shearing produces a different result from shearing then rotating: Shear⋅Rotation≠Rotation⋅Shear\text{Shear} \cdot \text{Rotation} \neq \text{Rotation} \cdot \text{Shear} in general.

Pitfall: Reading a product left to right
Writing rotate by 90°90°, then reflect across the xx-axis, as R90°HR_{90°} H with H=diag(1,−1)H = \text{diag}(1, -1) gives (0110)\begin{pmatrix} 0 & 1 \\ 1 & 0 \end{pmatrix}, which sends (1,0)(1, 0) to (0,1)(0, 1). The rotation acts first in HR90°=(0−1−10)H R_{90°} = \begin{pmatrix} 0 & -1 \\ -1 & 0 \end{pmatrix}, which sends (1,0)(1, 0) to (0,−1)(0, -1).

Turning a description into a matrix is therefore a matter of placement. The step named first in the description stands at the far right, next to the vector it acts on, and each later step is written to the left of the steps before it. A three-step description such as scale, then rotate, then shear becomes Shear⋅Rθ⋅Sk\text{Shear} \cdot R_\theta \cdot S_k.

The singular value decomposition reveals the hidden geometric structure of any matrix: A=UΣVTA = U\Sigma V^T, where VTV^T is a rotation (or rotation-reflection), Σ\Sigma is a coordinate-axis scaling, and UU is another rotation (or rotation-reflection). Every linear transformation is a rotation or reflection, followed by a scaling along the coordinate axes, followed by another rotation or reflection. The singular values in Σ\Sigma measure the maximum stretching in each orthogonal direction.

This decomposition means no linear transformation is truly exotic — even the most complex-looking matrix is just three simple geometric operations composed together.
AvBAvv₀BvABvv
Shear after rotation, rotation after shear

A shear and a rotation applied to the same vector in both orders. The solid two-step trail is one order, ending at ABv; the dashed trail is the other order, ending somewhere else — and the unit square is carried to a different parallelogram by each. The matrices are the same two; only the order of multiplication changed. Swap the order yourself on the matrix composition visualizer.

Because matrix products do not commute, the order in which transformations are applied is part of the transformation.

Determinant as Geometric Signature

The determinant classifies every linear transformation by its effect on size and orientation.

∣det⁡(A)∣|\det(A)| is the factor by which the transformation scales areas (in R2\mathbb{R}^2) or volumes (in R3\mathbb{R}^3). A unit square maps to a parallelogram of area ∣det⁡(A)∣|\det(A)|. A unit cube maps to a parallelepiped of volume ∣det⁡(A)∣|\det(A)|.

det⁡(A)>0\det(A) > 0: the transformation preserves orientation. Counterclockwise stays counterclockwise in R2\mathbb{R}^2; right-handed stays right-handed in R3\mathbb{R}^3. Rotations and shears fall in this category.

det⁡(A)<0\det(A) < 0: the transformation reverses orientation. Counterclockwise becomes clockwise; right-handed becomes left-handed. Reflections are the canonical example.

det⁡(A)=0\det(A) = 0: the transformation collapses at least one dimension. The image is a proper subspace — a line or point in R2\mathbb{R}^2, a plane, line, or point in R3\mathbb{R}^3. Projections onto proper subspaces and singular matrices fall here.

∣det⁡(A)∣=1|\det(A)| = 1: the transformation preserves area or volume. Rotations (det⁡=+1\det = +1) and reflections (det⁡=−1\det = -1) are the area-preserving and volume-preserving transformations. Shears also have det⁡=1\det = 1, preserving area despite distorting angles.
det(A) Effect on area / volume Effect on orientation Typical transformations
|det(A)| > 1 expands by factor |det(A)| preserves if det > 0, reverses if det < 0 uniform scaling with |c| > 1
0 < |det(A)| < 1 shrinks by factor |det(A)| preserves if det > 0, reverses if det < 0 uniform scaling with 0 < |c| < 1
det(A) = +1 preserves area / volume preserves orientation rotation, shear
det(A) = −1 preserves area / volume reverses orientation (handedness flip) reflection, improper rotation
det(A) = 0 collapses at least one dimension (image is a proper subspace) undefined / degenerate projection onto a proper subspace, any singular matrix
îĵker Aim Aîĵ
Area scaled, then area destroyed

The determinant reports what the transformation does to area: above, the unit square has become a parallelogram of some definite size; below, it has been flattened to nothing. A negative value would mean the square had been turned over as well. One number, carrying both the scaling and the orientation. Change the matrix and watch it respond on the linear transformation explorer.

This is why the determinant can classify a transformation family before any of its entries are examined individually.

Summary: Algebraic Signature of Each Family

Each family of geometric transformations has been treated in its own section, with its own matrix templates and its own algebraic identities. The table below sets all five side by side across the diagnostic signatures that distinguish them — orthogonality, determinant, eigenvalues, the characteristic algebraic identity, and what each family does to length and to area. It is the recognition card to keep nearby when a matrix is in hand and the question is which geometric family it belongs to.
Read the other way round, this is a recognition problem: given a matrix and no picture, which family is it? The two columns below answer that without any geometry — an identity the matrix satisfies, and the spectrum it must have. Both are checkable by computation, which matters because in dimensions above three the picture is unavailable anyway.
Transformations · signatures

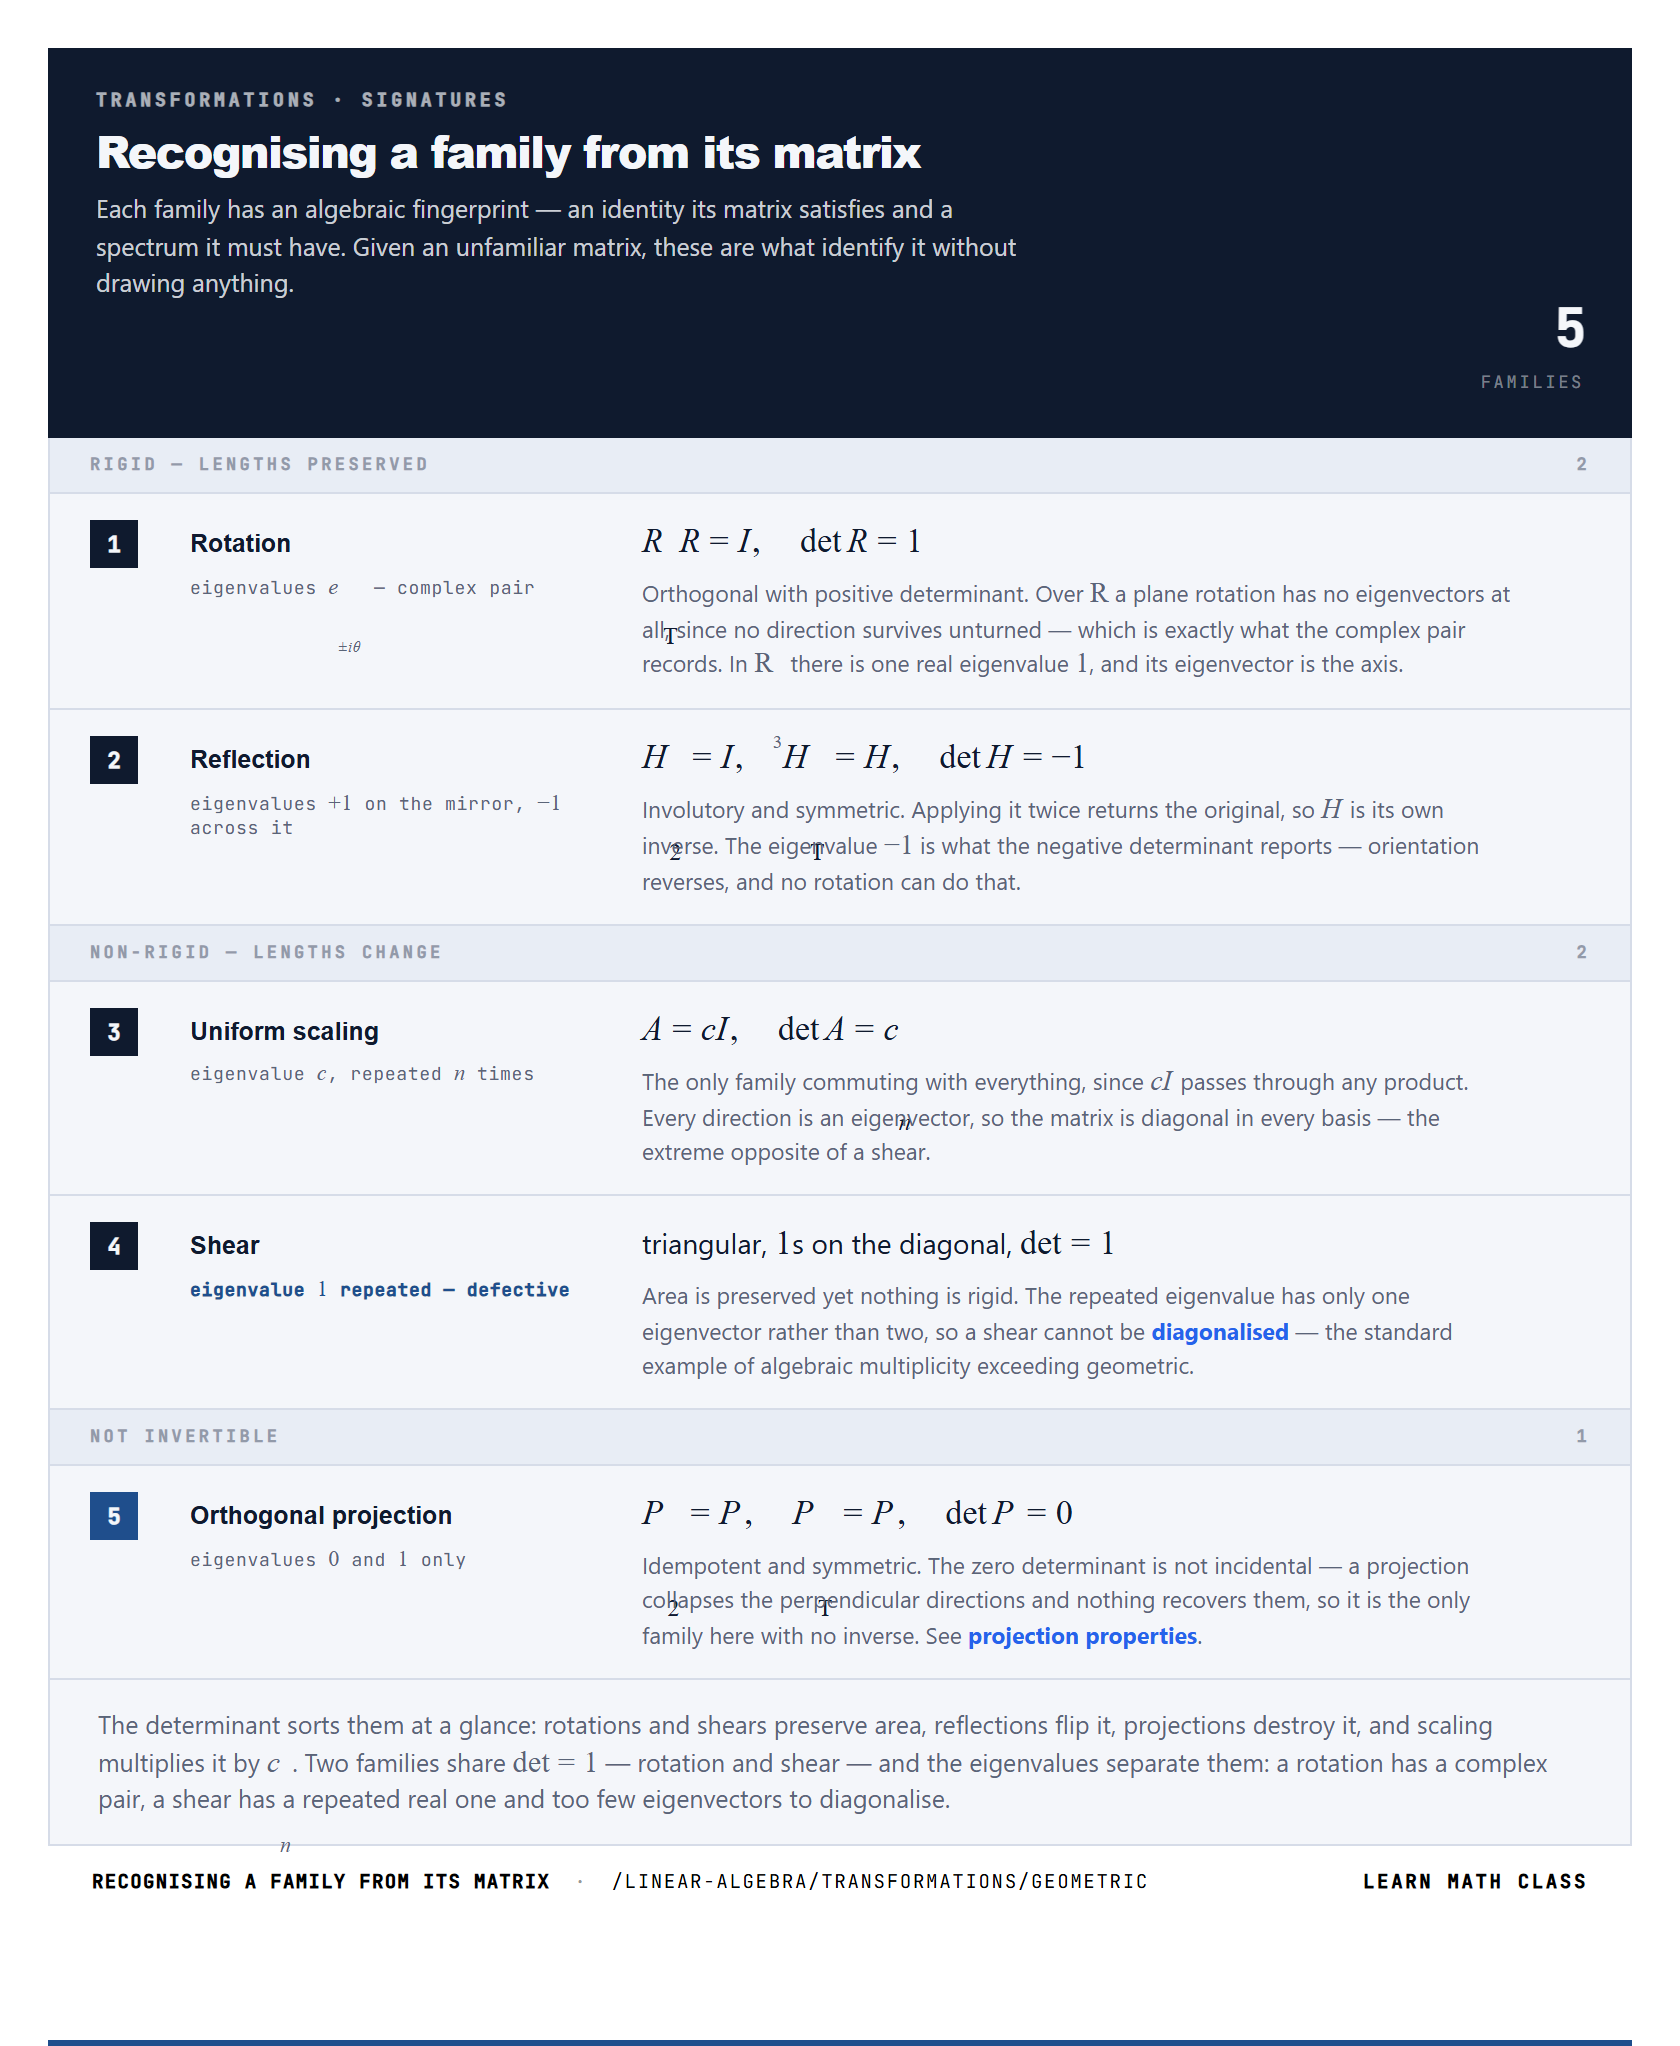
Recognising a family from its matrix

Each family has an algebraic fingerprint — an identity its matrix satisfies and a spectrum it must have. Given an unfamiliar matrix, these are what identify it without drawing anything.

5families
Rigid — lengths preserved2
1
eigenvalues e±iθe^{\pm i\theta} — complex pair
RTR=I,det⁡R=1R^{\mathsf{T}}R = I, \quad \det R = 1
Orthogonal with positive determinant. Over R\mathbb{R} a plane rotation has no eigenvectors at all, since no direction survives unturned — which is exactly what the complex pair records. In R3\mathbb{R}^3 there is one real eigenvalue 11, and its eigenvector is the axis.
2
eigenvalues +1+1 on the mirror, −1-1 across it
H2=I,HT=H,det⁡H=−1H^2 = I, \quad H^{\mathsf{T}} = H, \quad \det H = -1
Involutory and symmetric. Applying it twice returns the original, so HH is its own inverse. The eigenvalue −1-1 is what the negative determinant reports — orientation reverses, and no rotation can do that.
Non-rigid — lengths change2
3
eigenvalue cc, repeated nn times
A=cI,det⁡A=cnA = cI, \quad \det A = c^n
The only family commuting with everything, since cIcI passes through any product. Every direction is an eigenvector, so the matrix is diagonal in every basis — the extreme opposite of a shear.
4
eigenvalue 11 repeated — defective
triangular, 11s on the diagonal, det⁡=1\det = 1
Area is preserved yet nothing is rigid. The repeated eigenvalue has only one eigenvector rather than two, so a shear cannot be diagonalised — the standard example of algebraic multiplicity exceeding geometric.
Not invertible1
5
eigenvalues only 00 or 11
P2=P,PT=P,det⁡P=0P^2 = P, \quad P^{\mathsf{T}} = P, \quad \det P = 0
Idempotent and symmetric. The zero determinant is not incidental — a projection collapses the perpendicular directions and nothing recovers them, so it is the only family here with no inverse. See projection properties.
The determinant sorts them at a glance: rotations and shears preserve area, reflections flip it, projections destroy it, and scaling multiplies it by cnc^n. Two families share det⁡=1\det = 1 — rotation and shear — and the eigenvalues separate them: a rotation has a complex pair, a shear has a repeated real one and too few eigenvectors to diagonalise.
Recognising a family from its matrix·/linear-algebra/transformations/geometricLearn Math Class
Notice which pairs are hard to tell apart. Rotation and shear both have det⁡=1\det = 1, so area alone will not separate them — the eigenvalues do, a complex pair against a defective repeated root. Reflection and projection are both symmetric, and there the determinant separates them: −1-1 against 00, orientation reversed against information destroyed. No single test identifies a family; the identity and the spectrum together do.

Common Pitfalls

Five mistakes come up again and again when a transformation is read from its matrix or a matrix is written down from a description. Each is marked with a box where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.

Mistaking area-preserving for rigid

A matrix with determinant 11 or −1-1 is taken to be a rotation or a reflection, because it preserves area. The determinant measures only area and orientation; lengths and angles are never tested.

Wrong working: A=(1101)A = \begin{pmatrix} 1 & 1 \\ 0 & 1 \end{pmatrix} has det⁡A=1⋅1−1⋅0=1\det A = 1 \cdot 1 - 1 \cdot 0 = 1, so it is declared a rotation, and every length is assumed to stay the same.

Right working: test orthogonality directly.
ATA=(1011)(1101)=(1112)≠IA^T A = \begin{pmatrix} 1 & 0 \\ 1 & 1 \end{pmatrix}\begin{pmatrix} 1 & 1 \\ 0 & 1 \end{pmatrix} = \begin{pmatrix} 1 & 1 \\ 1 & 2 \end{pmatrix} \neq I

The matrix is a horizontal shear. It sends (0,1)(0, 1) to (1,1)(1, 1), of length 2\sqrt{2}, and the right angle between the two axes becomes 45°45°.

Why it happens: every rotation and every reflection has det⁡=±1\det = \pm 1, so the reverse statement feels natural. It is false: area can be kept while shape is lost.

How to check: look at the columns. A rigid motion has columns of length 11 that are perpendicular to each other. Here the second column (1,1)(1, 1) has length 2\sqrt{2}, and the dot product of the two columns is 11, not 00.

Forgetting the power of c

The determinant of the uniform scaling cIcI is taken to be cc, as if one factor of cc were enough. Each of the nn axes is stretched by cc, so the factor appears nn times.

Wrong working: in R3\mathbb{R}^3, det⁡(3I)=3\det(3I) = 3, so the unit cube would map to a solid of volume 33.

Right working: 3I=diag(3,3,3)3I = \text{diag}(3, 3, 3), so
det⁡(3I)=3⋅3⋅3=27\det(3I) = 3 \cdot 3 \cdot 3 = 27

The unit cube becomes a cube of side 33 and volume 2727. In R2\mathbb{R}^2 the same matrix has det⁡(3I)=9\det(3I) = 9.

Why it happens: cIcI reads as cc times II, and det⁡I=1\det I = 1, so taking the cc outside once seems natural. The general rule for an n×nn \times n matrix is det⁡(cA)=cndet⁡(A)\det(cA) = c^n \det(A).

How to check: compute the area or volume of the image of the unit square or cube directly. Its sides have lengths ∣c∣|c|, one per axis, and their product is ∣c∣n|c|^n.

Misplacing the sign for the y-axis

RxR_x and RzR_z both have −sin⁡θ-\sin\theta above the diagonal, and that pattern is carried over to RyR_y. In RyR_y the −sin⁡θ-\sin\theta sits below the diagonal, in the bottom-left corner.

Wrong working: the copied pattern at θ=90°\theta = 90° is
(cos⁡θ0−sin⁡θ010sin⁡θ0cos⁡θ)=(00−1010100)\begin{pmatrix} \cos\theta & 0 & -\sin\theta \\ 0 & 1 & 0 \\ \sin\theta & 0 & \cos\theta \end{pmatrix} = \begin{pmatrix} 0 & 0 & -1 \\ 0 & 1 & 0 \\ 1 & 0 & 0 \end{pmatrix}

It sends (0,0,1)(0, 0, 1) to (−1,0,0)(-1, 0, 0) and (1,0,0)(1, 0, 0) to (0,0,1)(0, 0, 1). This is Ry(−θ)R_y(-\theta), a turn the wrong way.

Right working:
Ry(90°)=(001010−100)R_y(90°) = \begin{pmatrix} 0 & 0 & 1 \\ 0 & 1 & 0 \\ -1 & 0 & 0 \end{pmatrix}

It sends (0,0,1)(0, 0, 1) to (1,0,0)(1, 0, 0) and (1,0,0)(1, 0, 0) to (0,0,−1)(0, 0, -1), as the right-hand rule about the positive yy-axis requires.

Why it happens: the plane that turns is the xzxz-plane, and the matrix lists its coordinates in the order xx, zz. The cyclic order x→y→z→xx \to y \to z \to x puts zz before xx, so reading the 2×22 \times 2 block in the matrix's own order reverses the turn.

How to check: look at column 33, the image of (0,0,1)(0, 0, 1). For a small positive angle about the yy-axis, the zz-axis tips toward the positive xx-axis, so the top entry of column 33 must be +sin⁡θ+\sin\theta.

Dropping the denominator of P

The projection onto the line through u\mathbf{u} is written as uuT\mathbf{u}\mathbf{u}^T, without the division by uTu\mathbf{u}^T\mathbf{u}. This is correct only when u\mathbf{u} is a unit vector.

Wrong working: with u=(1,2)\mathbf{u} = (1, 2),
uuT=(1224),(1224)(12)=(510)\mathbf{u}\mathbf{u}^T = \begin{pmatrix} 1 & 2 \\ 2 & 4 \end{pmatrix}, \qquad \begin{pmatrix} 1 & 2 \\ 2 & 4 \end{pmatrix}\begin{pmatrix} 1 \\ 2 \end{pmatrix} = \begin{pmatrix} 5 \\ 10 \end{pmatrix}

A vector already on the line is moved and made five times as long.

Right working: uTu=1+4=5\mathbf{u}^T\mathbf{u} = 1 + 4 = 5, so
P=15(1224),P(12)=(12),P(10)=(1/52/5)P = \frac{1}{5}\begin{pmatrix} 1 & 2 \\ 2 & 4 \end{pmatrix}, \qquad P\begin{pmatrix} 1 \\ 2 \end{pmatrix} = \begin{pmatrix} 1 \\ 2 \end{pmatrix}, \qquad P\begin{pmatrix} 1 \\ 0 \end{pmatrix} = \begin{pmatrix} 1/5 \\ 2/5 \end{pmatrix}


Why it happens: many formulas are stated for unit vectors, such as the Householder matrix I−2 nnTI - 2\,\mathbf{n}\mathbf{n}^T on this page. There the denominator equals 11 and is left out, and the shorter form is then used for vectors that are not unit vectors.

How to check: a projection satisfies P2=PP^2 = P, and its trace equals its rank. Here (uuT)2=(5101020)=5 uuT(\mathbf{u}\mathbf{u}^T)^2 = \begin{pmatrix} 5 & 10 \\ 10 & 20 \end{pmatrix} = 5\,\mathbf{u}\mathbf{u}^T, and the trace of uuT\mathbf{u}\mathbf{u}^T is 55, while a projection onto a line has rank 11.

Reading a product left to right

A sequence of transformations is written down in the order the steps happen, from left to right. The product then performs them in the reverse order, because the rightmost factor acts first.

Wrong working: rotate by 90°90°, then reflect across the xx-axis, with H=diag(1,−1)H = \text{diag}(1, -1), written as
R90°H=(0−110)(100−1)=(0110)R_{90°} H = \begin{pmatrix} 0 & -1 \\ 1 & 0 \end{pmatrix}\begin{pmatrix} 1 & 0 \\ 0 & -1 \end{pmatrix} = \begin{pmatrix} 0 & 1 \\ 1 & 0 \end{pmatrix}

This is the reflection across the line y=xy = x, and it sends (1,0)(1, 0) to (0,1)(0, 1).

Right working: the first step goes on the right.
HR90°=(100−1)(0−110)=(0−1−10)H R_{90°} = \begin{pmatrix} 1 & 0 \\ 0 & -1 \end{pmatrix}\begin{pmatrix} 0 & -1 \\ 1 & 0 \end{pmatrix} = \begin{pmatrix} 0 & -1 \\ -1 & 0 \end{pmatrix}

The rotation takes (1,0)(1, 0) to (0,1)(0, 1) and the reflection takes that to (0,−1)(0, -1). The result is the reflection across the line y=−xy = -x.

Why it happens: text is read from left to right, and the description lists the steps in that order. But each matrix acts on the vector to its right: (HR90°)x=H(R90°x)(H R_{90°})\mathbf{x} = H(R_{90°}\mathbf{x}).

How to check: follow one basis vector through the steps by hand, then compare the result with the matching column of the product. Here (1,0)(1, 0) must end at (0,−1)(0, -1), the first column of HR90°H R_{90°}.

Geometric Transformations FAQ

In RθSkR_{\theta}S_k, does the rotation or the scaling happen first?

+
The scaling, because the rightmost factor acts first. Reading the product left to right as "rotate, then scale" reverses the actual sequence, and the mistake stays invisible until the two operations fail to commute. Here AB≠BAAB \neq BA carries real geometric weight: rotating then reflecting is a different motion from reflecting then rotating.Read more →

How do you invert a rotation matrix?

+
You do not need to compute anything: Rθ−1=R−θ=RθTR_{\theta}^{-1} = R_{-\theta} = R_{\theta}^{T}. Because a rotation is orthogonal, its transpose already is its inverse, so running elimination on one is wasted effort. Negating the angle and transposing the matrix are two descriptions of the same operation.Read more →

Why does PP mean different things in different places?

+
It has three unrelated tenants in linear algebra: a projection matrix here, a change-of-basis matrix in coordinate work, and a permutation matrix in factorisations such as PA=LUPA = LU. Only the subscript and the surrounding claim distinguish them, so the letter alone never settles which object is meant.Read more →