Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Determinants


A Single Number from a Square Matrix

Every square matrix maps to a single scalar called its determinant. This value captures whether the matrix is invertible, how it scales geometric regions, and whether it preserves or reverses orientation. The determinant appears throughout linear algebra — in eigenvalue equations, system-solving formulas, and volume computations — making it one of the most information-dense quantities attached to a matrix.

For step-by-step results on your own numbers, use the determinant calculator on CalculateMatrix.


The Determinant as a Scalar Assignment

One account is an area: the parallelogram spanned by the columns.
Take A=(3125)A = \begin{pmatrix} 3 & 1 \\ 2 & 5 \end{pmatrix} and draw its two columns as arrows from the origin, (3,2)(3, 2) and (1,5)(1, 5). Together they span a parallelogram. Its area can be found with nothing but a ruler: the surrounding 4×74 \times 7 box has area 2828, and the triangles and rectangles left over around the parallelogram add up to 1515, so the parallelogram has area 1313.
The columns (3, 2) and (1, 5) span a parallelogram of area 13xy12341234567column (3, 2)column (1, 5)area 13The two columns span a parallelogram of area 13
The arrows (3,2)(3, 2) and (1,5)(1, 5) and the two copies that close the shape. The region between them has area 1313.
The other account is a short calculation on the four entries.
Multiply the two entries on the main diagonal, multiply the other two, and subtract: ad−bc=3⋅5−1⋅2=13ad - bc = 3 \cdot 5 - 1 \cdot 2 = 13. No drawing, no geometry — four numbers and one subtraction. Section 2 takes this formula as its starting point.
Both accounts give the same number every time.
Try a few pairs of columns both ways.
columnsarea of the parallelogramad − bc
(3, 2) and (1, 5)28 − 15 = 133·5 − 1·2 = 13
(2, 0) and (0, 3)a 2 × 3 rectangle: 62·3 − 0·0 = 6
(1, 2) and (2, 4)on one line: 01·4 − 2·2 = 0
The rectangle is the easy check — its area is plainly 2×32 \times 3. The last pair is the telling one: both columns lie on the same line, the parallelogram collapses to nothing, and the formula gives 00 as well.
They had to agree, because area and ad − bc react to the columns in the same way.
Change the columns and watch both quantities.
change to the columnsareaad − bc
slide one column along the other (add a multiple of it)unchangedunchanged
stretch one column by a factor ktimes ktimes k
start from the unit square, columns (1, 0) and (0, 1)11·1 − 0·0 = 1
Sliding a column along the other is a shear: the parallelogram leans but keeps its base and height, and ad−bcad - bc is unchanged by the same move. Stretching a column stretches both by the same factor, and the unit square starts both at 11. Any two quantities that behave this way under every change of columns are the same quantity — the two accounts were describing one number all along. (The formula can also come out negative; that sign records which way round the columns go, an orientation the plain area ignores.)
The definition
The determinant of a square matrix AA is the single number det⁡(A)\det(A) that both accounts describe: the signed factor by which AA scales area (volume, in higher dimensions), equal for a 2×22 \times 2 matrix to ad−bcad - bc.
For A=(3125)A = \begin{pmatrix} 3 & 1 \\ 2 & 5 \end{pmatrix}, det⁡(A)=13\det(A) = 13.
A determinant is a number, and only square matrices have one.
It is one real number (or complex number, if the entries are complex) attached to the whole matrix. It is defined only for square matrices — a rectangular matrix has no determinant. The notation ∣A∣|A| is widespread but potentially confusing, since the same vertical bars denote absolute value for real numbers and modulus for complex numbers. When there is any risk of ambiguity, det⁡(A)\det(A) is preferred.
Use the formula to compute and the area to understand.
The formula is what you calculate with, and for larger matrices it grows into the expansions of the sections below. The area is what explains the results. A zero determinant means the columns have collapsed onto a line (a plane, in 3D), so the map x↦Axx \mapsto Ax squashes space flat and cannot be undone: AA is invertible if and only if det⁡(A)≠0\det(A) \neq 0. The determinant also determines whether that map preserves or reverses orientation, and appears in explicit formulas for eigenvalues, matrix inverses, and solutions to linear systems.
The next several sections develop the determinant starting from the smallest cases — the 2×22 \times 2 formula, the 3×33 \times 3 rule — and building toward cofactor expansion, the general definition, its properties, and its geometric meaning.

The 2×2 Formula

For a 2×22 \times 2 matrix

The 2×2 Formula
A=(abcd)A = \begin{pmatrix} a & b \\ c & d \end{pmatrix}

the determinant is

The 2×2 Formula
det⁡(A)=ad−bc\det(A) = ad - bc

One way to see where this formula comes from is to solve the system Ax=vAx = \mathbf{v} for a general right-hand side. Applying elimination, the solution involves dividing by ad−bcad - bc at every step. When ad−bc=0ad - bc = 0, the system either has no solution or infinitely many, and the matrix cannot be inverted. When ad−bc≠0ad - bc \neq 0, there is a unique solution for every v\mathbf{v}, and the inverse exists.

Pitfall: Subtracting in the wrong order
Taking bc−adbc - ad for (3125)\begin{pmatrix} 3 & 1 \\ 2 & 5 \end{pmatrix} gives 1⋅2−3⋅5=−131 \cdot 2 - 3 \cdot 5 = -13, the right size with the wrong sign. The main diagonal comes first: ad−bc=15−2=13ad - bc = 15 - 2 = 13.

The expression ad−bcad - bc also carries geometric meaning. The columns of AA are the vectors (a,c)(a, c) and (b,d)(b, d) in R2\mathbb{R}^2. The signed area of the parallelogram these two vectors span equals exactly ad−bcad - bc. A positive value means the columns are arranged counterclockwise; a negative value means clockwise; zero means the columns are parallel and the parallelogram collapses to a line segment.

Worked Examples


For A=(3125)A = \begin{pmatrix} 3 & 1 \\ 2 & 5 \end{pmatrix}, the determinant is 3⋅5−1⋅2=133 \cdot 5 - 1 \cdot 2 = 13. The matrix is invertible and its column vectors span a parallelogram of area 1313.

For A=(4623)A = \begin{pmatrix} 4 & 6 \\ 2 & 3 \end{pmatrix}, the determinant is 4⋅3−6⋅2=04 \cdot 3 - 6 \cdot 2 = 0. The second column is 32\frac{3}{2} times the first, so the columns are parallel and the matrix is singular.

For A=(0−110)A = \begin{pmatrix} 0 & -1 \\ 1 & 0 \end{pmatrix}, the determinant is 0⋅0−(−1)⋅1=10 \cdot 0 - (-1) \cdot 1 = 1. This is a 90°90° rotation matrix — it preserves areas and orientation.
A2×2a1,1a1,2a2,1a2,2
ad, the first half of ad − bc

The 2 × 2 determinant is built from the two diagonals of the square. Here the main diagonal is lit: a11 and a22, whose product is the ad term. The anti-diagonal, a12 and a21, supplies bc, and the determinant is the first product minus the second. Step through both diagonals and the subtraction on the determinant visualizer.

Every larger determinant is assembled out of 2 × 2 pieces like this one.

The 3×3 Formula

For a 3×33 \times 3 matrix

The 3×3 Formula
A=(a11a12a13a21a22a23a31a32a33)A = \begin{pmatrix} a_{11} & a_{12} & a_{13} \\ a_{21} & a_{22} & a_{23} \\ a_{31} & a_{32} & a_{33} \end{pmatrix}

the determinant is computed by expanding along the first row:

Determinant 3x3
det⁡(A)=a11(a22a33−a23a32)−a12(a21a33−a23a31)+a13(a21a32−a22a31)\det(A) = a_{11}(a_{22}a_{33} - a_{23}a_{32}) - a_{12}(a_{21}a_{33} - a_{23}a_{31}) + a_{13}(a_{21}a_{32} - a_{22}a_{31})
Learn more about this formula: Determinant 3x3 →


Each first-row entry multiplies the 2×22 \times 2 determinant of the submatrix that remains after deleting that entry's row and column. The signs alternate: +,−,++, -, +.

The Sarrus Mnemonic


A shortcut for the 3×33 \times 3 case is the rule of Sarrus. Write the matrix and copy its first two columns to the right:

The 3×3 Formula
(a11a12a13a21a22a23a31a32a33)a11a12a21a22a31a32\begin{pmatrix} a_{11} & a_{12} & a_{13} \\ a_{21} & a_{22} & a_{23} \\ a_{31} & a_{32} & a_{33} \end{pmatrix} \begin{matrix} a_{11} & a_{12} \\ a_{21} & a_{22} \\ a_{31} & a_{32} \end{matrix}

Sum the three products along the downward diagonals, then subtract the three products along the upward diagonals. This gives the same result as the first-row expansion. The Sarrus rule works only for 3×33 \times 3 matrices — there is no analogous diagonal trick for 4×44 \times 4 or larger.

Worked Example


For A=(2310−14523)A = \begin{pmatrix} 2 & 3 & 1 \\ 0 & -1 & 4 \\ 5 & 2 & 3 \end{pmatrix}, expanding along the first row:

The 3×3 Formula
det⁡(A)=2[(−1)(3)−(4)(2)]−3[(0)(3)−(4)(5)]+1[(0)(2)−(−1)(5)]\det(A) = 2[(-1)(3) - (4)(2)] - 3[(0)(3) - (4)(5)] + 1[(0)(2) - (-1)(5)]

The 3×3 Formula
=2(−3−8)−3(0−20)+1(0+5)=2(−11)−3(−20)+5=−22+60+5=43= 2(-3 - 8) - 3(0 - 20) + 1(0 + 5) = 2(-11) - 3(-20) + 5 = -22 + 60 + 5 = 43

Pitfall: Adding all three terms
Adding the terms instead of alternating the signs gives 2(−11)+3(−20)+1(5)=−772(-11) + 3(-20) + 1(5) = -77. The middle term is subtracted: 2(−11)−3(−20)+1(5)=432(-11) - 3(-20) + 1(5) = 43.

The same result follows from the Sarrus rule: downward diagonals give 2(−1)(3)+3(4)(5)+1(0)(2)=−6+60+0=542(-1)(3) + 3(4)(5) + 1(0)(2) = -6 + 60 + 0 = 54; upward diagonals give 1(−1)(5)+2(4)(2)+3(0)(3)=−5+16+0=111(-1)(5) + 2(4)(2) + 3(0)(3) = -5 + 16 + 0 = 11; the determinant is 54−11=4354 - 11 = 43.
Aa1,1a1,2a1,3a1,1a1,2a2,1a2,2a2,3a2,1a2,2a3,1a3,2a3,3a3,1a3,2
The six signed products of a 3×3

Three diagonals running one way are added and three running the other are subtracted — six products in total, each using one entry from every row and every column. The pattern is a convenience for this size only: it does not extend to 4×4, where the count jumps to twenty-four. Watch the diagonals traced out on the determinant visualizer.

The general definition in the next section is what these six products are a special case of.

The General n×n Determinant

The pattern from the 3×33 \times 3 case extends to any dimension. For an n×nn \times n matrix, expand along the first row:

The General n×n Determinant
det⁡(A)=∑j=1n(−1)1+j a1j M1j\det(A) = \sum_{j=1}^{n} (-1)^{1+j} \, a_{1j} \, M_{1j}

where M1jM_{1j} is the determinant of the (n−1)×(n−1)(n-1) \times (n-1) submatrix obtained by deleting row 11 and column jj. This is a recursive definition: each n×nn \times n determinant reduces to nn determinants of size (n−1)×(n−1)(n-1) \times (n-1), each of which reduces further, until reaching the base case of 1×11 \times 1 matrices where det⁡(a)=a\det(a) = a.

A crucial fact is that the expansion need not use the first row.

THEOREM
Expanding along any row or any column gives the same result.

Fact: Drop the signs and it gets hard
Fully expanded, the determinant is a sum of n!n! signed products. Remove every minus sign and the result is the permanent: row additions now change its value, elimination fails, and the best known methods still take more than 2n2^n steps against the determinant's n3n^3.

The signed sub-determinants (−1)i+jMij(-1)^{i+j} M_{ij} are called cofactors, and the freedom to choose the expansion axis is what makes the formula practical: a row or column with many zeros dramatically reduces the number of terms.

The recursive nature of this definition means the computational cost grows factorially. An n×nn \times n determinant via cofactor expansion requires on the order of n!n! arithmetic operations. For n=5n = 5 that is 120120 operations; for n=10n = 10 it is over 3.63.6 million. This explosion is what motivates the row-reduction approach, which accomplishes the same task in O(n3)O(n^3) operations by exploiting how row operations affect the determinant.

Cofactor expansion defines the determinant in every size, but its cost grows like n!n!, so large ones are computed by row reduction.

Singular and Nonsingular Matrices

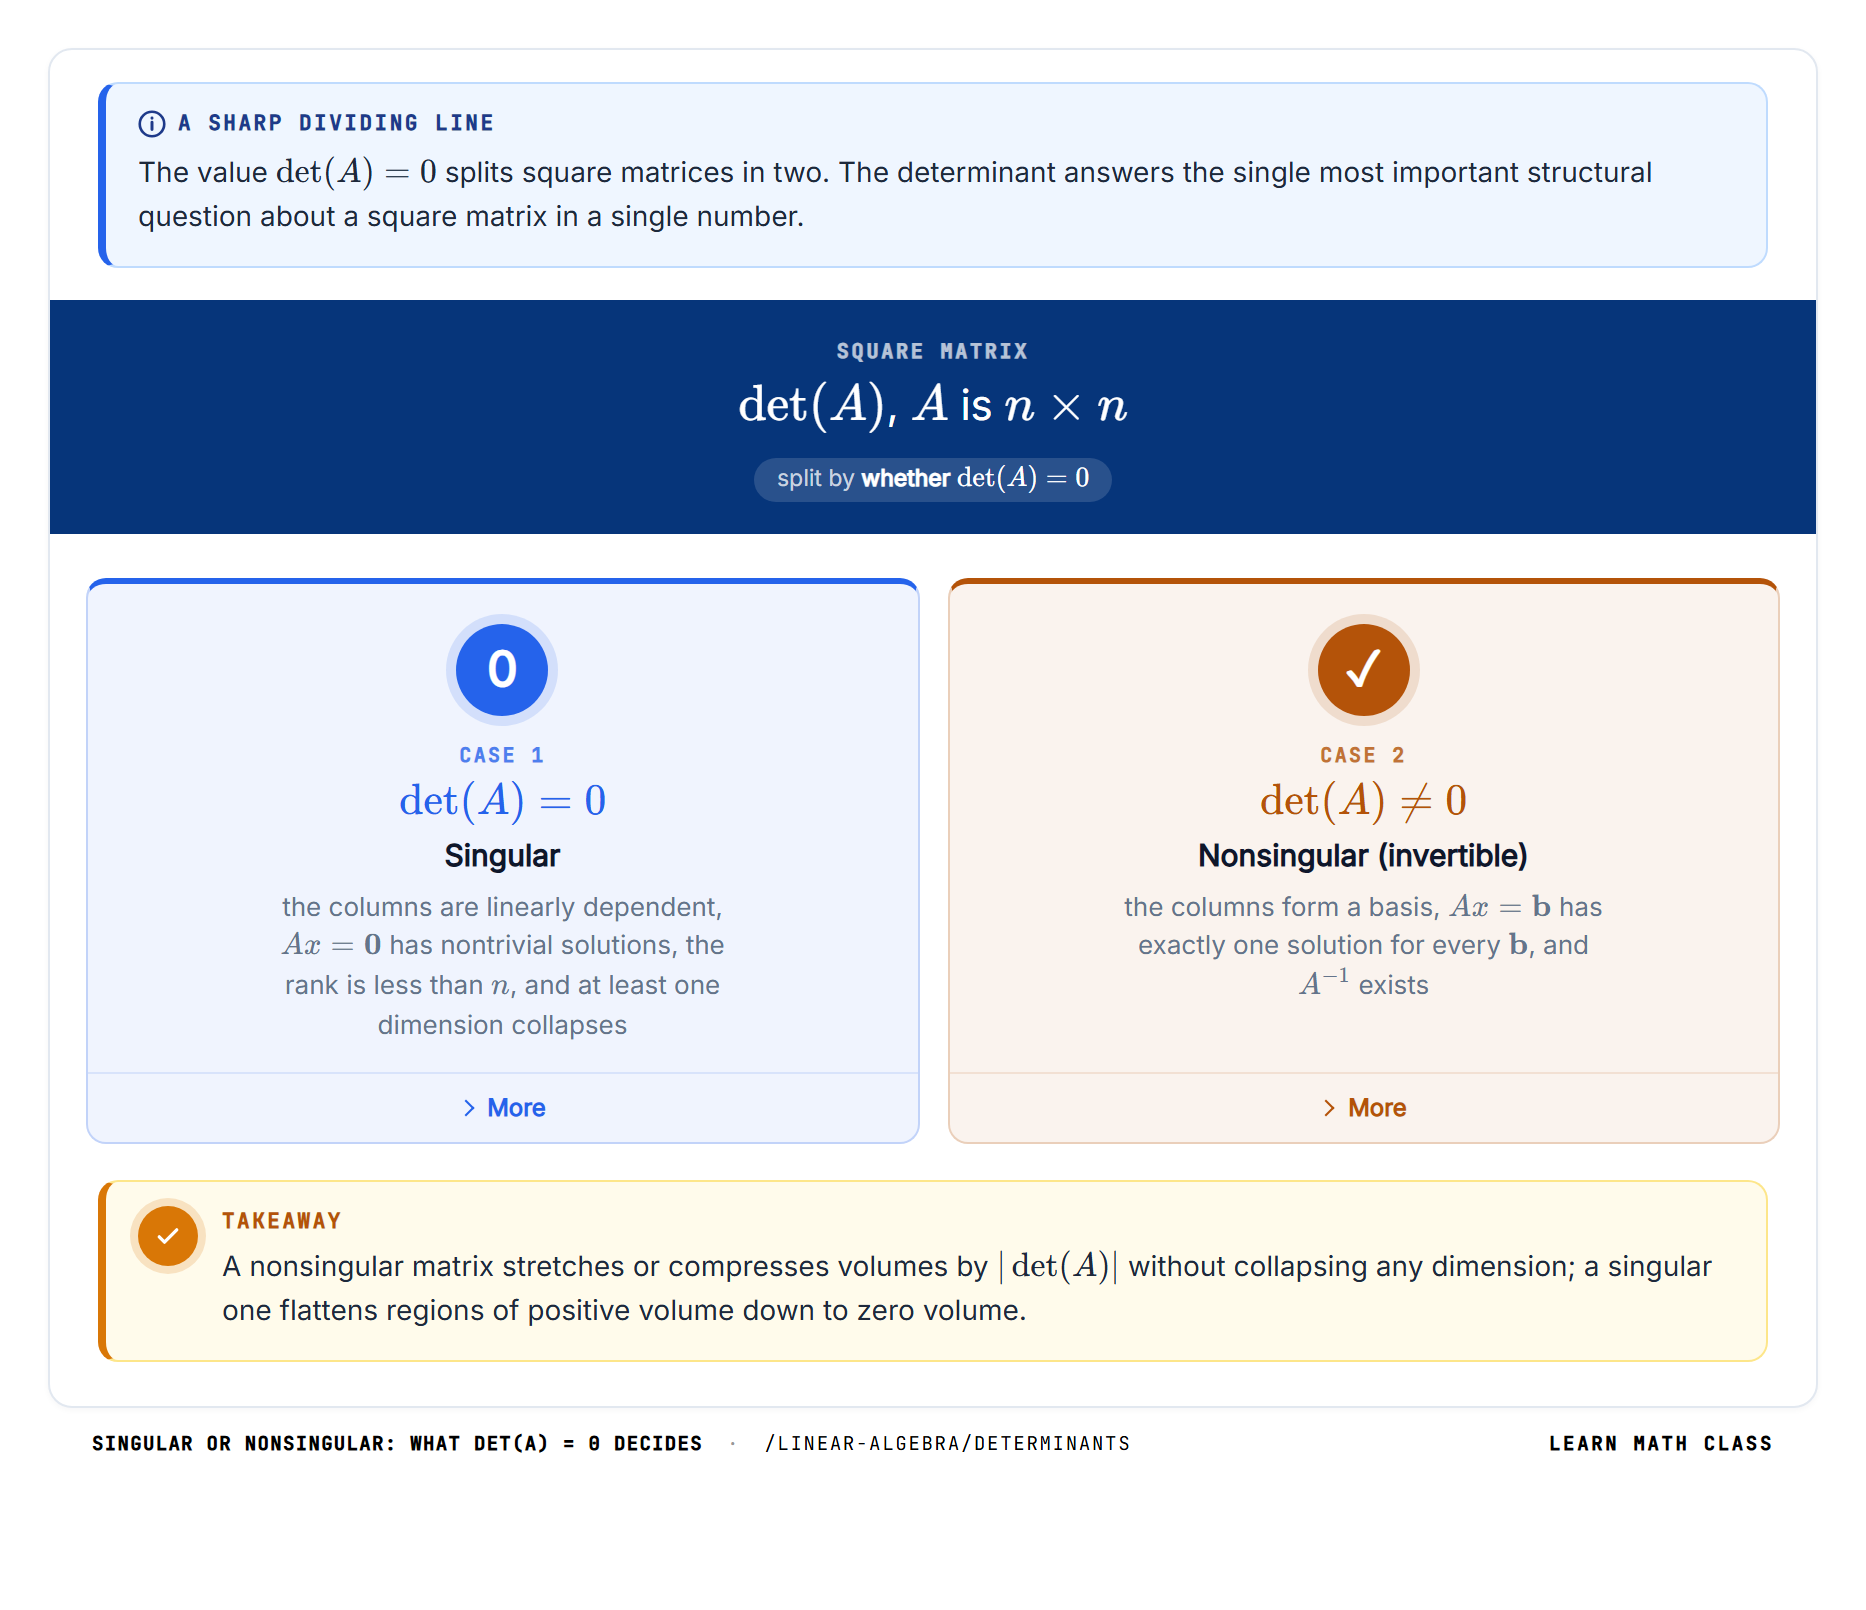
The value det⁡(A)=0\det(A) = 0 marks a sharp dividing line. A square matrix with zero determinant is called singular; a square matrix with nonzero determinant is called nonsingular or invertible.

THEOREM
When det⁡(A)=0\det(A) = 0, the columns of AA are linearly dependent — at least one column can be written as a linear combination of the others.

The homogeneous system Ax=0Ax = \mathbf{0} has nontrivial solutions, the rank of AA is strictly less than nn, and the matrix maps Rn\mathbb{R}^n onto a lower-dimensional subspace. Geometrically, the transformation collapses at least one dimension, flattening regions of positive volume down to zero volume.

When det⁡(A)≠0\det(A) \neq 0, everything works. The columns of AA form a basis for Rn\mathbb{R}^n. The system Ax=bAx = \mathbf{b} has exactly one solution for every right-hand side b\mathbf{b}. The matrix has an inverse A−1A^{-1}, and the linear map x↦Axx \mapsto Ax is a bijection from Rn\mathbb{R}^n to itself that stretches or compresses volumes by the factor ∣det⁡(A)∣|\det(A)| without collapsing any dimension.

The determinant thus answers the single most important structural question about a square matrix in a single number.
DownloadPNG2×PDF
A sharp dividing line
The value det⁡(A)=0\det(A) = 0 splits square matrices in two. The determinant answers the single most important structural question about a square matrix in a single number.
Square matrix
det⁡(A)\det(A), AA is n×nn \times n
split by whether det⁡(A)=0\det(A) = 0
0
Case 1
det⁡(A)=0\det(A) = 0
Singular
the columns are linearly dependent, Ax=0Ax = \mathbf{0} has nontrivial solutions, the rank is less than nn, and at least one dimension collapses
More
✓
Case 2
det⁡(A)≠0\det(A) \neq 0
Nonsingular (invertible)
the columns form a basis, Ax=bAx = \mathbf{b} has exactly one solution for every b\mathbf{b}, and A−1A^{-1} exists
More
The map x↦Axx \mapsto Ax is a bijection from Rn\mathbb{R}^n to itself. See basis.
Takeaway
A nonsingular matrix stretches or compresses volumes by ∣det⁡(A)∣|\det(A)| without collapsing any dimension; a singular one flattens regions of positive volume down to zero volume.
Singular or nonsingular: what det(A) = 0 decides·/linear-algebra/determinantsLearn Math Class

Computing Small Determinants

The most direct way to build intuition is to compute by hand. The 2×22 \times 2 formula ad−bcad - bc is immediate. The 3×33 \times 3 case requires either first-row expansion or the Sarrus shortcut. For 4×44 \times 4 matrices, no shortcut exists — the computation goes through cofactor expansion, but choosing a good row or column makes a significant difference.

A 4×4 Example


Computing Small Determinants
A=(102−13005214−31050)A = \begin{pmatrix} 1 & 0 & 2 & -1 \\ 3 & 0 & 0 & 5 \\ 2 & 1 & 4 & -3 \\ 1 & 0 & 5 & 0 \end{pmatrix}

Column 22 has three zeros and a single 11 in position (3,2)(3,2), making it the best expansion axis. Expanding along column 22:

Computing Small Determinants
det⁡(A)=(−1)3+2⋅1⋅M32\det(A) = (-1)^{3+2} \cdot 1 \cdot M_{32}

where M32M_{32} is the 3×33 \times 3 determinant obtained by deleting row 33 and column 22:

Computing Small Determinants
M32=det⁡(12−1305150)M_{32} = \det\begin{pmatrix} 1 & 2 & -1 \\ 3 & 0 & 5 \\ 1 & 5 & 0 \end{pmatrix}

Expanding this along its first row:

Computing Small Determinants
M32=1(0⋅0−5⋅5)−2(3⋅0−5⋅1)+(−1)(3⋅5−0⋅1)M_{32} = 1(0 \cdot 0 - 5 \cdot 5) - 2(3 \cdot 0 - 5 \cdot 1) + (-1)(3 \cdot 5 - 0 \cdot 1)

Computing Small Determinants
=1(−25)−2(−5)+(−1)(15)=−25+10−15=−30= 1(-25) - 2(-5) + (-1)(15) = -25 + 10 - 15 = -30

So det⁡(A)=(−1)5⋅1⋅(−30)=(−1)(−30)=30\det(A) = (-1)^{5} \cdot 1 \cdot (-30) = (-1)(-30) = 30.

Pitfall: Reusing the first-row signs
Applying the first-row pattern +,−,+,−+, -, +, - down column 22 gives the entry at (3,2)(3,2) the sign ++ and det⁡(A)=−30\det(A) = -30. The sign comes from the position, (−1)3+2=−1(-1)^{3+2} = -1, so det⁡(A)=30\det(A) = 30.

The choice of column 22 reduced the problem from four 3×33 \times 3 determinants down to one. This illustrates why scanning for zeros before expanding is the first step in any hand computation.

To compute the determinant of a specific matrix, use the matrix calculator.

Expanding by Minors and Cofactors

The sub-determinants appearing in cofactor expansion have their own terminology. The (i,j)(i,j) minor MijM_{ij} is the determinant of the submatrix formed by deleting row ii and column jj from AA. The (i,j)(i,j) cofactor is the signed version:

Cofactor Definition
Cij=(−1)i+jMijC_{ij} = (-1)^{i+j} M_{ij}
Learn more about this formula: Cofactor Definition →


The sign factor (−1)i+j(-1)^{i+j} follows a checkerboard pattern starting with ++ at position (1,1)(1,1):

Expanding by Minors and Cofactors
(+−+−⋯−+−+⋯+−+−⋯⋮⋱)\begin{pmatrix} + & - & + & - & \cdots \\ - & + & - & + & \cdots \\ + & - & + & - & \cdots \\ \vdots & & & & \ddots \end{pmatrix}

Using this notation, the Laplace expansion along row ii takes the compact form

Expanding by Minors and Cofactors
det⁡(A)=∑j=1naij Cij\det(A) = \sum_{j=1}^{n} a_{ij} \, C_{ij}

and the expansion along column jj is

Expanding by Minors and Cofactors
det⁡(A)=∑i=1naij Cij\det(A) = \sum_{i=1}^{n} a_{ij} \, C_{ij}

Both give the same result regardless of which row or column is chosen. Collecting all cofactors into a matrix and transposing produces the adjugate, which leads to an explicit formula for the matrix inverse. The full development of minors, cofactors, the adjugate, and the structural results they enable is on the cofactors page.
A3×3a1,1a1,2a1,3a2,1a2,2a2,3a3,1a3,2a3,3→M1,22×2a2,1a2,3a3,1a3,3
Expansion along a row, minors highlighted

For each entry of the chosen row, its own row and column are struck out and the determinant of what remains is taken, then signed and weighted. Any row or column gives the same answer, so the one with the most zeros is always the cheapest to pick. Choose a different row or column and compare on the determinant visualizer.

This is the definition that actually generalises, at the price of a cost that grows faster than almost anything else in the subject.

How Row Operations Affect the Determinant

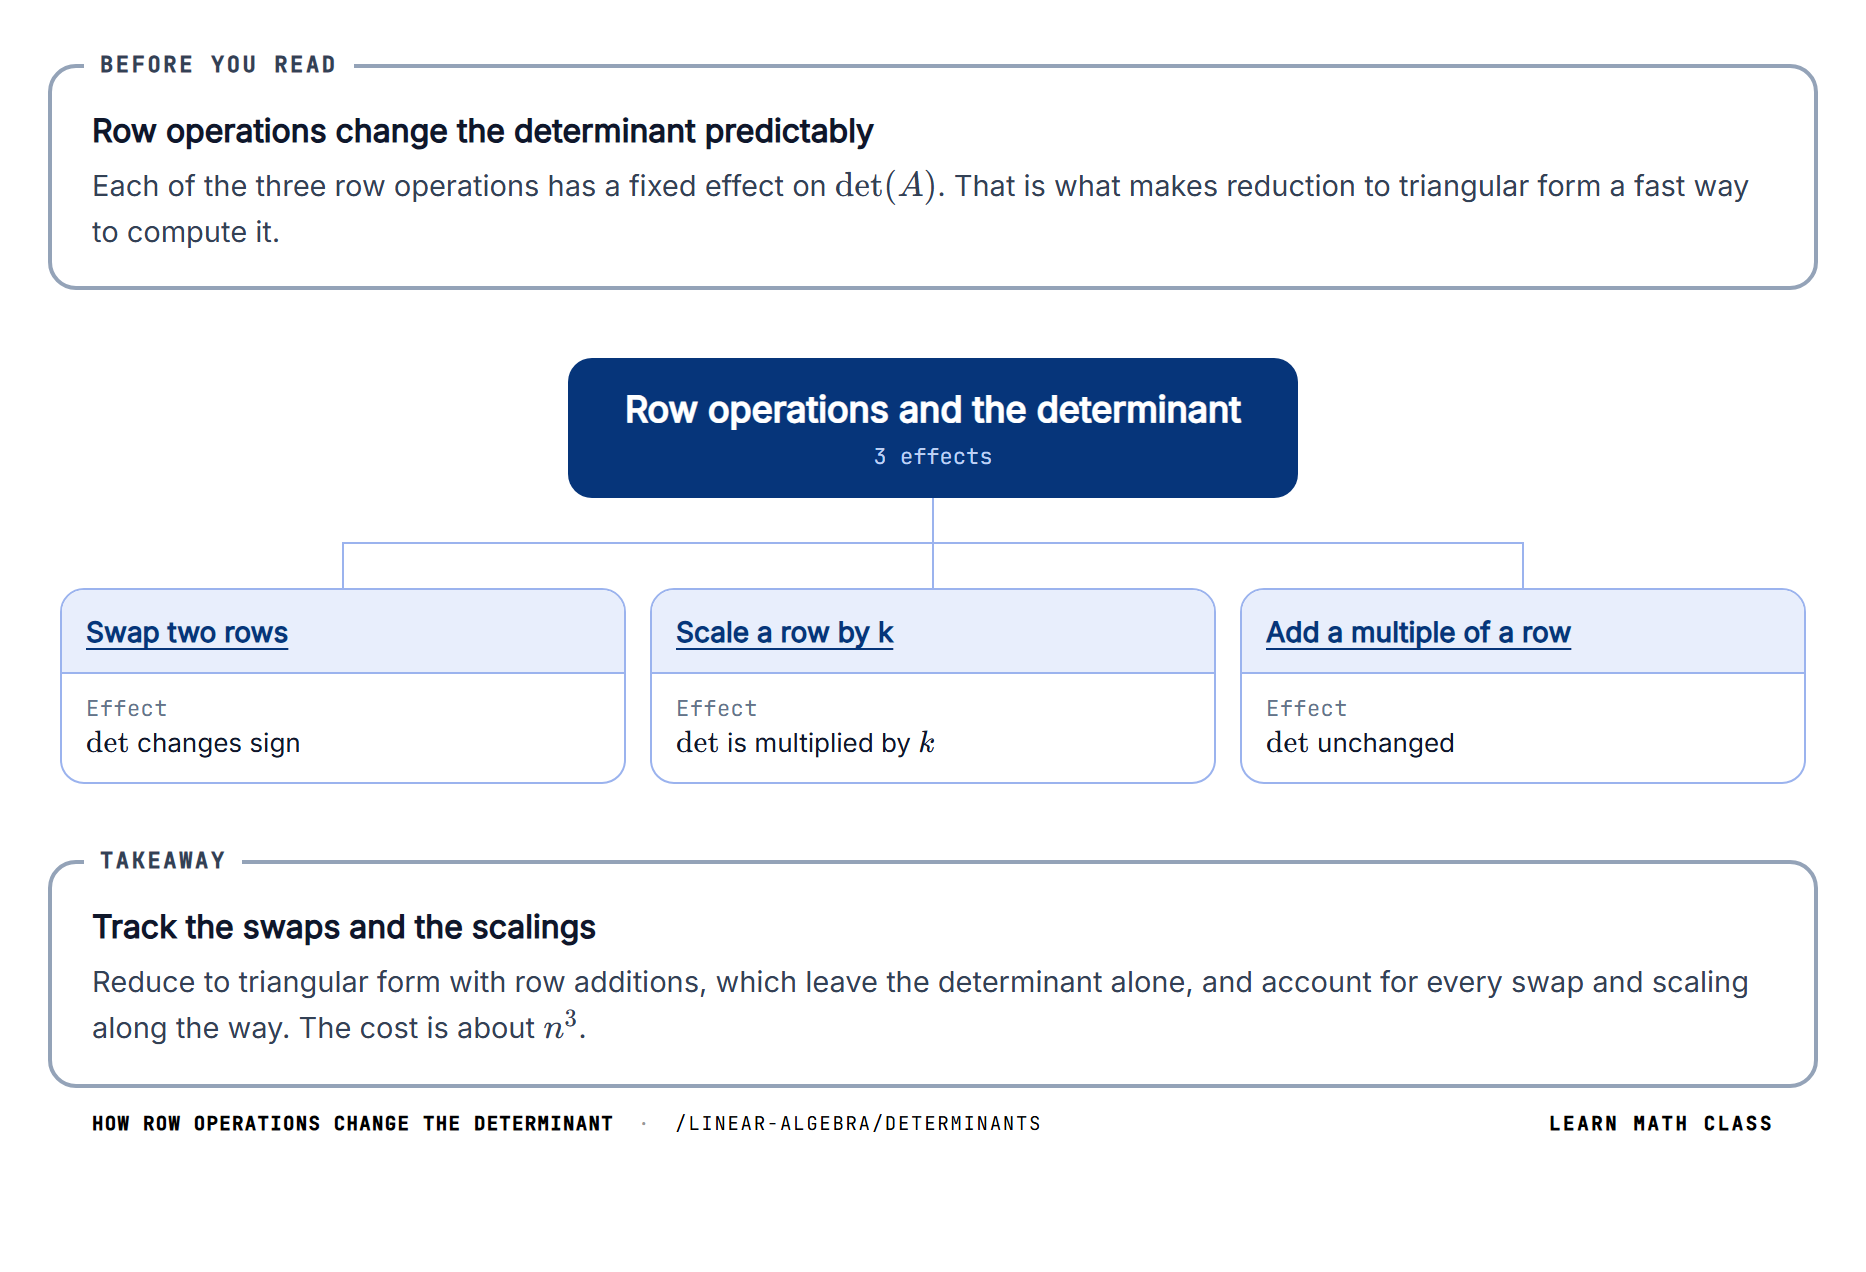
The three elementary row operations interact with the determinant in simple, predictable ways. Swapping two rows multiplies the determinant by −1-1. Multiplying a row by a nonzero scalar kk multiplies the determinant by kk. Adding a scalar multiple of one row to a different row leaves the determinant unchanged.

Pitfall: Scaling the whole matrix once
Writing det⁡(2A)=2det⁡(A)\det(2A) = 2\det(A) for A=(2437)A = \begin{pmatrix} 2 & 4 \\ 3 & 7 \end{pmatrix} gives 44. Doubling AA doubles both rows, so det⁡(2A)=22⋅2=8\det(2A) = 2^2 \cdot 2 = 8; in general det⁡(kA)=kndet⁡(A)\det(kA) = k^n \det(A).

These three rules turn Gaussian elimination into a determinant-computing algorithm. Reduce AA to upper triangular form using row operations, tracking every swap and every scaling. The determinant of the resulting triangular matrix is the product of its diagonal entries. Adjusting for the tracked sign flips and scale factors gives det⁡(A)\det(A).

This approach requires on the order of n3n^3 arithmetic operations — a dramatic improvement over the n!n! cost of cofactor expansion. For any matrix larger than 4×44 \times 4, row reduction is the practical method.

A Quick Illustration


Pitfall: Forgetting to undo a scaling
Dividing row 11 of (2437)\begin{pmatrix} 2 & 4 \\ 3 & 7 \end{pmatrix} by 22 and then clearing below the pivot gives (1201)\begin{pmatrix} 1 & 2 \\ 0 & 1 \end{pmatrix}, with diagonal product 11. That division halved the determinant, so det⁡(A)=2⋅1=2\det(A) = 2 \cdot 1 = 2.

Example
Starting from A=(2437)A =\begin{pmatrix} 2 & 4 \\ 3 & 7 \end{pmatrix}, subtract 32\frac{3}{2} times row 11 from row 22 (this does not change the determinant) to get (2401)\begin{pmatrix} 2 & 4 \\ 0 & 1 \end{pmatrix}. The product of the diagonal is 2⋅1=22 \cdot 1 = 2, which matches det⁡(A)=2⋅7−4⋅3=2\det(A) = 2 \cdot 7 - 4 \cdot 3 = 2.

The complete set of algebraic properties — including the multiplicative rule det⁡(AB)=det⁡(A)det⁡(B)\det(AB) = \det(A)\det(B), transpose invariance, and the full invertibility equivalence — is developed on the properties page. The three rules above collect into a compact reference:
Row operation Effect on det(A) Adjustment when reading off det from triangular form
Swap two rows multiplies det by −1 flip the sign once per swap
Multiply a row by k ≠ 0 multiplies det by k divide the final product by k
Add a multiple of one row to another leaves det unchanged no adjustment
DownloadPNG2×PDF
Before you read
Row operations change the determinant predictably
Each of the three row operations has a fixed effect on det⁡(A)\det(A). That is what makes reduction to triangular form a fast way to compute it.
Row operations and the determinant3 effects
Effectdet⁡\det changes sign
Effectdet⁡\det is multiplied by kk
Effectdet⁡\det unchanged
Takeaway
Track the swaps and the scalings
Reduce to triangular form with row additions, which leave the determinant alone, and account for every swap and scaling along the way. The cost is about n3n^3.
How row operations change the determinant·/linear-algebra/determinantsLearn Math Class

Area, Volume, and Orientation

The determinant has a direct geometric meaning: it measures how a matrix, viewed as a linear transformation, distorts size and orientation.

In two dimensions, ∣det⁡(A)∣|\det(A)| equals the area of the parallelogram spanned by the columns of AA. In three dimensions, ∣det⁡(A)∣|\det(A)| equals the volume of the parallelepiped spanned by the three column vectors, which also equals the scalar triple product a⋅(b×c)\mathbf{a} \cdot (\mathbf{b} \times \mathbf{c}).

THEOREM
In nn dimensions, ∣det⁡(A)∣|\det(A)| is the factor by which the map x↦Axx \mapsto Ax scales nn-dimensional volumes.

The sign carries its own meaning. A positive determinant means the transformation preserves orientation — counterclockwise stays counterclockwise in R2\mathbb{R}^2, right-handed stays right-handed in R3\mathbb{R}^3. A negative determinant means orientation is reversed. A zero determinant means the image is lower-dimensional: a 3×33 \times 3 transformation with det⁡=0\det = 0 maps all of R3\mathbb{R}^3 onto a plane, a line, or a point.

Rotation matrices always have determinant +1+1. Reflection matrices always have determinant −1-1. These are the cleanest examples of orientation-preserving and orientation-reversing maps. The full geometric treatment, including the change-of-variables formula from multivariable calculus and explicit area and volume formulas, is on the geometry page.
îĵker Aim Aîĵ
A grid stretched, then flattened

Above, the unit square has become a parallelogram and its area is exactly the determinant. Below, the matrix has flattened the plane onto a line: the parallelogram has no area left and the determinant is zero. Singularity and zero area are the same event seen from two sides. Change the entries and watch the area respond on the linear transformation explorer.

Every geometric use of the determinant — volume, orientation, change of variables — is this one fact applied in more dimensions.
Determinant-Based Formulas

The determinant is not only a diagnostic tool — it provides closed-form expressions for quantities that might otherwise require iterative procedures.

Fact: Determinants came before matrices
Seki Takakazu in Japan in 1683 and Leibniz in Europe in 1693 each found them while eliminating unknowns from systems of equations, as the expression that decides whether the equations can hold together. Matrices became objects of their own only in the 1850s, more than 150 years later.

Cramer's rule solves a linear system Ax=bAx = \mathbf{b} by expressing each component of the solution as a ratio of two determinants: xi=det⁡(Ai)/det⁡(A)x_i = \det(A_i)/\det(A), where AiA_i is AA with its ii-th column replaced by b\mathbf{b}. The adjugate formula gives the inverse of AA as A−1=1det⁡(A)adj⁡(A)A^{-1} = \frac{1}{\det(A)} \operatorname{adj}(A), writing every entry of the inverse explicitly in terms of cofactors. In the 2×22 \times 2 case, this reduces to the familiar swap-and-negate formula.

The cross product a×b\mathbf{a} \times \mathbf{b} in R3\mathbb{R}^3 can be computed as a symbolic 3×33 \times 3 determinant with the unit vectors i^,j^,k^\hat{i}, \hat{j}, \hat{k} in the first row. The characteristic polynomial det⁡(A−λI)\det(A - \lambda I) defines the eigenvalues of AA — its roots are precisely the scalars λ\lambda for which A−λIA - \lambda I is singular. The Wronskian, a determinant built from functions and their derivatives, tests linear independence in the setting of differential equations.

Each of these formulas is developed with full worked examples on the applications page. The five collect into a single reference card:
Formula Expression What it computes
Cramer's rule xi = det(Ai) / det(A) each component of the unique solution to Ax = b
Adjugate formula for A−1 A−1 = adj(A) / det(A) explicit closed form for the matrix inverse
Cross product in ℝ3 a × b = symbolic 3×3 det with î, ĵ, k̂ on top vector perpendicular to a and b with prescribed length
Characteristic polynomial det(A − λI) polynomial whose roots are the eigenvalues of A
Wronskian determinant of functions and their derivatives linear independence test for solutions of an ODE

Summary: How to Compute a Determinant

Across the methods covered above, four routes lead to det⁡(A)\det(A) — the closed-form 2×22\times 2 formula, the closed-form 3×33\times 3 expansion (or Sarrus), general cofactor expansion, and row reduction. Each is the right choice in a different regime, distinguished by matrix size, sparsity of the matrix, and whether the work needs to scale to large nn. The table below collects all four side by side on the underlying formula, the situation it suits best, and the asymptotic cost.
Method Formula / approach Best for Cost
2×2 formula ad − bc every 2×2 case — direct, no tricks needed O(1)
3×3 (first-row expansion or Sarrus) sum of three 2×2 dets with alternating signs; or downward minus upward diagonal products 3×3 only; Sarrus does not generalize O(1)
Cofactor expansion Σ (−1)i+j aij Mij along any row or column small matrices, especially when a row or column has many zeros O(n!)
Row reduction reduce to triangular form, multiply the diagonal, adjust for tracked swaps and scalings any matrix 4×4 or larger; the standard general-purpose method O(n3)

Common Pitfalls

Six mistakes account for many wrong determinants. Five are marked with a box where they happen in the sections above, and the sixth, a diagonal shortcut used on a 4×44 \times 4 matrix, is flagged in the section on the 3×33 \times 3 formula. Here each is worked through in full, with the wrong and the right working side by side.

Subtracting in the wrong order

The 2×22 \times 2 formula is applied with its two products the wrong way round: the product of the other diagonal comes first, and the main-diagonal product is subtracted from it.

Wrong working: for A=(3125)A = \begin{pmatrix} 3 & 1 \\ 2 & 5 \end{pmatrix},
bc−ad=1⋅2−3⋅5=2−15=−13bc - ad = 1 \cdot 2 - 3 \cdot 5 = 2 - 15 = -13


Right working: the main diagonal a,da, d comes first.
ad−bc=3⋅5−1⋅2=15−2=13ad - bc = 3 \cdot 5 - 1 \cdot 2 = 15 - 2 = 13


Why it happens: both products are formed correctly and only their order is swapped. The two results differ only in sign, so the wrong one looks just as plausible.

How to check: the identity matrix must give 11. With ad−bcad - bc, det⁡(I)=1⋅1−0⋅0=1\det(I) = 1 \cdot 1 - 0 \cdot 0 = 1; with the order reversed it gives −1-1.

Adding all three terms

In the first-row expansion of a 3×33 \times 3 determinant, the three terms are added as if every sign were ++. The middle term should be subtracted.

Wrong working: for the matrix of the worked example, A=(2310−14523)A = \begin{pmatrix} 2 & 3 & 1 \\ 0 & -1 & 4 \\ 5 & 2 & 3 \end{pmatrix},
2(−11)+3(−20)+1(5)=−22−60+5=−772(-11) + 3(-20) + 1(5) = -22 - 60 + 5 = -77


Right working: the signs alternate +,−,++, -, +.
2(−11)−3(−20)+1(5)=−22+60+5=432(-11) - 3(-20) + 1(5) = -22 + 60 + 5 = 43


Why it happens: the three 2×22 \times 2 determinants are computed carefully, and the sign in front of the middle one is lost when the terms are put together. A negative middle value, as here, makes the slip easier, because two minus signs have to combine into a plus.

How to check: compute the same determinant with the rule of Sarrus, which has no position signs to forget. For this matrix it gives 54−11=4354 - 11 = 43.

Using the diagonal rule on a 4×4 matrix

The rule of Sarrus is stretched to a 4×44 \times 4 matrix: the first three columns are copied to the right, and the four downward diagonal products minus the four upward ones are taken as the determinant.

Wrong working: for the 4×44 \times 4 matrix of the section on small determinants, A=(102−13005214−31050)A = \begin{pmatrix} 1 & 0 & 2 & -1 \\ 3 & 0 & 0 & 5 \\ 2 & 1 & 4 & -3 \\ 1 & 0 & 5 & 0 \end{pmatrix}, the downward diagonals give 00, 00, 00 and (−1)(3)(1)(5)=−15(-1)(3)(1)(5) = -15, and all four upward diagonals give 00. The result would be −15−0=−15-15 - 0 = -15.

Right working: expand along column 22, which has a single nonzero entry.
det⁡(A)=(−1)3+2⋅1⋅M32=(−1)(−30)=30\det(A) = (-1)^{3+2} \cdot 1 \cdot M_{32} = (-1)(-30) = 30


Why it happens: the diagonal picture is easy to remember, and nothing in it seems tied to the size 33. But a 4×44 \times 4 determinant has 4!=244! = 24 products, and the diagonals reach only 88 of them.

How to check: count the products. A determinant of size nn has n!n! of them, a diagonal rule of this kind produces 2n2n, and the two counts agree only for n=3n = 3.

Reusing the first-row signs

When a determinant is expanded along a row or column other than the first row, the signs are taken from the first-row pattern +,−,+,−+, -, +, - in the order the entries are used, instead of from their positions.

Wrong working: in the 4×44 \times 4 example, the expansion along column 22 has a single term, from the entry 11 at position (3,2)(3,2). Running +,−,+,−+, -, +, - down the column gives row 33 the sign ++:
det⁡(A)=+1⋅M32=1⋅(−30)=−30\det(A) = +1 \cdot M_{32} = 1 \cdot (-30) = -30


Right working: the sign of position (i,j)(i,j) is (−1)i+j(-1)^{i+j}. For (3,2)(3,2) it is (−1)5=−1(-1)^{5} = -1, so
det⁡(A)=(−1)⋅1⋅(−30)=30\det(A) = (-1) \cdot 1 \cdot (-30) = 30


Why it happens: most worked expansions use the first row, where the pattern does start with ++. Column 22 starts with −-, and so does row 22.

How to check: read the sign off the checkerboard pattern in the section on minors and cofactors. Position (3,2)(3,2) sits on a −- square.

Scaling the whole matrix once

The rule for scaling one row is applied to a multiple of the whole matrix: det⁡(kA)\det(kA) is taken to be kdet⁡(A)k\det(A).

Wrong working: for A=(2437)A = \begin{pmatrix} 2 & 4 \\ 3 & 7 \end{pmatrix}, with det⁡(A)=2\det(A) = 2,
det⁡(2A)=2det⁡(A)=4\det(2A) = 2\det(A) = 4


Right working: 2A2A multiplies each of the 22 rows by 22, and each row contributes its own factor.
det⁡(2A)=det⁡(48614)=4⋅14−8⋅6=56−48=8=22⋅2\det(2A) = \det\begin{pmatrix} 4 & 8 \\ 6 & 14 \end{pmatrix} = 4 \cdot 14 - 8 \cdot 6 = 56 - 48 = 8 = 2^2 \cdot 2

For an n×nn \times n matrix, det⁡(kA)=kndet⁡(A)\det(kA) = k^n \det(A).

Why it happens: multiplying a matrix by kk looks like one operation, but it scales all nn rows at once, and the row rule counts each of them.

How to check: try A=IA = I. The matrix kIkI is diagonal with nn entries equal to kk, so its determinant is knk^n, not kk.

Forgetting to undo a scaling

During row reduction a row is divided by its pivot to make the pivot 11, and the diagonal product of the final triangular matrix is reported as the determinant without accounting for that division.

Wrong working: for A=(2437)A = \begin{pmatrix} 2 & 4 \\ 3 & 7 \end{pmatrix}, divide row 11 by 22 to get (1237)\begin{pmatrix} 1 & 2 \\ 3 & 7 \end{pmatrix}, then subtract 33 times row 11 from row 22:
(1201),1⋅1=1\begin{pmatrix} 1 & 2 \\ 0 & 1 \end{pmatrix}, \quad 1 \cdot 1 = 1


Right working: dividing row 11 by 22 divided the determinant by 22, so the product is multiplied back by 22.
det⁡(A)=2⋅(1⋅1)=2\det(A) = 2 \cdot (1 \cdot 1) = 2

This matches 2⋅7−4⋅3=22 \cdot 7 - 4 \cdot 3 = 2.

Why it happens: making every pivot equal to 11 is a habit from solving linear systems, where scaling a row does not change the solution. For a determinant it does change the value.

How to check: keep a running factor beside the reduction and multiply by it at the end. Or avoid scaling altogether: row additions alone, as in the illustration of the row-operations section, leave the determinant unchanged.

Determinants FAQ

Why does ad−bcad - bc always equal the area of the parallelogram?

+
Because the two react to the columns in the same ways. Sliding one column along the other is a shear: the parallelogram leans but keeps its base and height, and ad−bcad - bc does not change either. Stretching one column stretches both by the same factor, and the unit square gives 11 for both. Quantities that agree under every such change are one quantity. For columns (3,2)(3, 2) and (1,5)(1, 5) both give 1313. The formula can also be negative; the sign records orientation, which plain area ignores.Read more →

Where does the formula ad−bcad - bc come from?

+
From solving a system. Eliminate in ax+by=v1ax + by = v_1, cx+dy=v2cx + dy = v_2 and the solution comes out as x=dv1−bv2ad−bcx = \frac{dv_1 - bv_2}{ad - bc} and y=av2−cv1ad−bcy = \frac{av_2 - cv_1}{ad - bc}, with the same number in every denominator. When ad−bc≠0ad - bc \neq 0 there is exactly one solution for every right-hand side and the matrix has an inverse. When ad−bc=0ad - bc = 0 there is no solution or there are infinitely many, and the matrix cannot be inverted.Read more →

What is the permanent of a matrix?

+
It is the determinant with every minus sign removed. Fully expanded, a determinant is a sum of n!n! signed products, one entry from each row and each column; the permanent adds the same products with all signs ++. That small change breaks the tools: adding a multiple of one row to another now changes the value, so elimination fails. The determinant takes about n3n^3 steps by row reduction, while the best known methods for the permanent still take more than 2n2^n.Read more →

Which came first, determinants or matrices?

+
Determinants, by more than 150 years. Seki Takakazu in Japan in 1683 and Leibniz in Europe in 1693 each found them while eliminating unknowns from systems of equations, as the expression that decides whether the equations can hold together. Matrices became objects of their own only in the 1850s. That order still shows in the formulas built on determinants, such as Cramer's rule, which solves a system Ax=bA\mathbf{x} = \mathbf{b} with ratios det⁡(Ai)/det⁡(A)\det(A_i)/\det(A).Read more →

Does the rule of Sarrus work for a 4×44 \times 4 matrix?

+
No. A 4×44 \times 4 determinant is a sum of 4!=244! = 24 products, and the downward and upward diagonals reach only 88 of them. A diagonal rule of this kind gives 2n2n products against the n!n! needed, and the two agree only for n=3n = 3. On the page's 4×44 \times 4 example the diagonals give −15-15, while expanding along column 22, which has a single nonzero entry, gives the true value 3030. From 4×44 \times 4 up, use cofactor expansion or row reduction.Read more →