Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Minors, Cofactors, and the Adjugate


Expanding Along Any Row or Column

The cofactor expansion generalizes the recursive pattern seen in the 3×3 case to matrices of arbitrary size. By systematically pairing each entry with a signed sub-determinant, it reduces an n×n determinant to n determinants of size (n−1)×(n−1), with complete freedom in choosing which row or column drives the expansion.

For step-by-step results on your own numbers, use the cofactor, matrix of minors and adjugate calculators on CalculateMatrix.


Minors

Given an n×nn \times n matrix AA, the (i,j)(i,j) minor MijM_{ij} is the determinant of the (n−1)×(n−1)(n-1) \times (n-1) submatrix that remains after removing row ii and column jj. The minor is itself a determinant — a number, not a matrix.

Formally:

Minor Definition
Mij=det⁡ ⁣(A(i,j))M_{ij} = \det\!\left(A^{(i,j)}\right)

where A(i,j)A^{(i,j)} denotes the submatrix of AA with row ii and column jj removed.

For a 3×33 \times 3 matrix

Minors
A=(25103−2416)A = \begin{pmatrix} 2 & 5 & 1 \\ 0 & 3 & -2 \\ 4 & 1 & 6 \end{pmatrix}

Fact: Lewis Carroll's four-minor shortcut
In 1866 Charles Dodgson, the author of Alice's Adventures in Wonderland, published a way to build a determinant from smaller minors alone. For this matrix it reads a22det⁡(A)=M11M33−M13M31a_{22} \det(A) = M_{11} M_{33} - M_{13} M_{31}: four corner minors give 20⋅6−(−12)(−13)=−3620 \cdot 6 - (-12)(-13) = -36, and dividing by the centre entry 33 gives det⁡(A)=−12\det(A) = -12.

there are nine minors, one for each entry. Deleting row 11 and column 11 leaves (3−216)\begin{pmatrix} 3 & -2 \\ 1 & 6 \end{pmatrix}, so M11=3⋅6−(−2)⋅1=20M_{11} = 3 \cdot 6 - (-2) \cdot 1 = 20. Deleting row 11 and column 22 leaves (0−246)\begin{pmatrix} 0 & -2 \\ 4 & 6 \end{pmatrix}, so M12=0⋅6−(−2)⋅4=8M_{12} = 0 \cdot 6 - (-2) \cdot 4 = 8. Deleting row 11 and column 33 leaves (0341)\begin{pmatrix} 0 & 3 \\ 4 & 1 \end{pmatrix}, so M13=0⋅1−3⋅4=−12M_{13} = 0 \cdot 1 - 3 \cdot 4 = -12.

Continuing this way produces all nine values:

Minors
M21=5⋅6−1⋅1=29,M22=2⋅6−1⋅4=8,M23=2⋅1−5⋅4=−18M_{21} = 5 \cdot 6 - 1 \cdot 1 = 29, \quad M_{22} = 2 \cdot 6 - 1 \cdot 4 = 8, \quad M_{23} = 2 \cdot 1 - 5 \cdot 4 = -18

Minors
M31=5⋅(−2)−1⋅3=−13,M32=2⋅(−2)−1⋅0=−4,M33=2⋅3−5⋅0=6M_{31} = 5 \cdot (-2) - 1 \cdot 3 = -13, \quad M_{32} = 2 \cdot (-2) - 1 \cdot 0 = -4, \quad M_{33} = 2 \cdot 3 - 5 \cdot 0 = 6

For a 4×44 \times 4 matrix, each minor is a 3×33 \times 3 determinant. For a 5×55 \times 5 matrix, each minor is 4×44 \times 4. The recursive chain continues until reaching 1×11 \times 1 sub-determinants, where the minor is simply the lone entry.

Cofactor Notation

Notation

Cofactor Notation

Capital letters that secretly name numbers, a superscript that deletes instead of multiplying, and an operator with a dangerous old name.
det⁡\det and its bars — determinant notation; (aij)(a_{ij}) and ATA^{T} — matrix notation; Σ\Sigma — sequence notation.
MijM_{ij} · CijC_{ij}
The minor and cofactor at position i, j
A convention wrinkle: capitals usually name matrices, but MijM_{ij} and CijC_{ij} are numbers — determinants of submatrices, defined in Minors and Cofactors and the Sign Pattern above and below. The double subscript locates which entry they belong to; the capital honours their determinant ancestry.
CasesThe letters regroup into genuine matrices one level up: the cofactor matrix C=(Cij)C = (C_{ij}) collects all n2n^2 cofactors — a matrix whose entries are the capital-named scalars.
Also writtenAijA_{ij} for the cofactor in many Russian and older texts — colliding head-on with the entry notation aija_{ij}, which is why CijC_{ij} won.
Do not confuseSubmatrices. MijM_{ij} is not the deleted-row-and-column matrix — it is that matrix's determinant; the matrix itself needs its own mark, next entry.
A(i,j)A^{(i,j)}
A with row i and column j removed
A parenthesized superscript that deletes: the (n−1)×(n−1)(n-1) \times (n-1) submatrix left after striking row ii and column jj. The parentheses are load-bearing — they fence the indices off from the exponent reading.
CasesThe same fencing device appears wherever a superscript must not mean a power: the nn-th derivative f(n)f^{(n)} uses identical armor. Un-parenthesized, AijA^{ij} would collide with powers and tensor conventions at once.
Also writtenAi^j^A_{\hat{i}\hat{j}} with deletion hats, or verbal “the (i,j)(i,j) submatrix” — no universal standard exists; every text declares its own mark.
Do not confuseA power or an entry. Three decorations, three meanings: aija_{ij} selects an entry, AnA^n multiplies, A(i,j)A^{(i,j)} deletes — subscript, superscript, and fenced superscript all working different jobs on one letter.
adj⁡(A)=CT\operatorname{adj}(A) = C^{T}
The adjugate of A — the transpose of the cofactor matrix
The transpose inside the definition is the notation trap: the adjugate is not the cofactor matrix but its transpose, and forgetting the flip is the classic error in the inverse formula of The Adjugate below.
CasesIts one starring role: A−1=1det⁡(A)adj⁡(A)A^{-1} = \frac{1}{\det(A)} \operatorname{adj}(A) — the closed-form inverse, where the adjugate carries all the cofactor bookkeeping.
Also writtenadj⁡A\operatorname{adj} A without parentheses; older texts say “classical adjoint” and write adj⁡\operatorname{adj} the same way.
Do not confuseThe modern adjoint. In advanced linear algebra “adjoint” means the conjugate transpose A∗A^{*} — an unrelated operation. The name migrated; the word “adjugate” exists precisely to escape the collision, and careful reading of older texts must check which one “adjoint” means.
DownloadPNG2×PDF
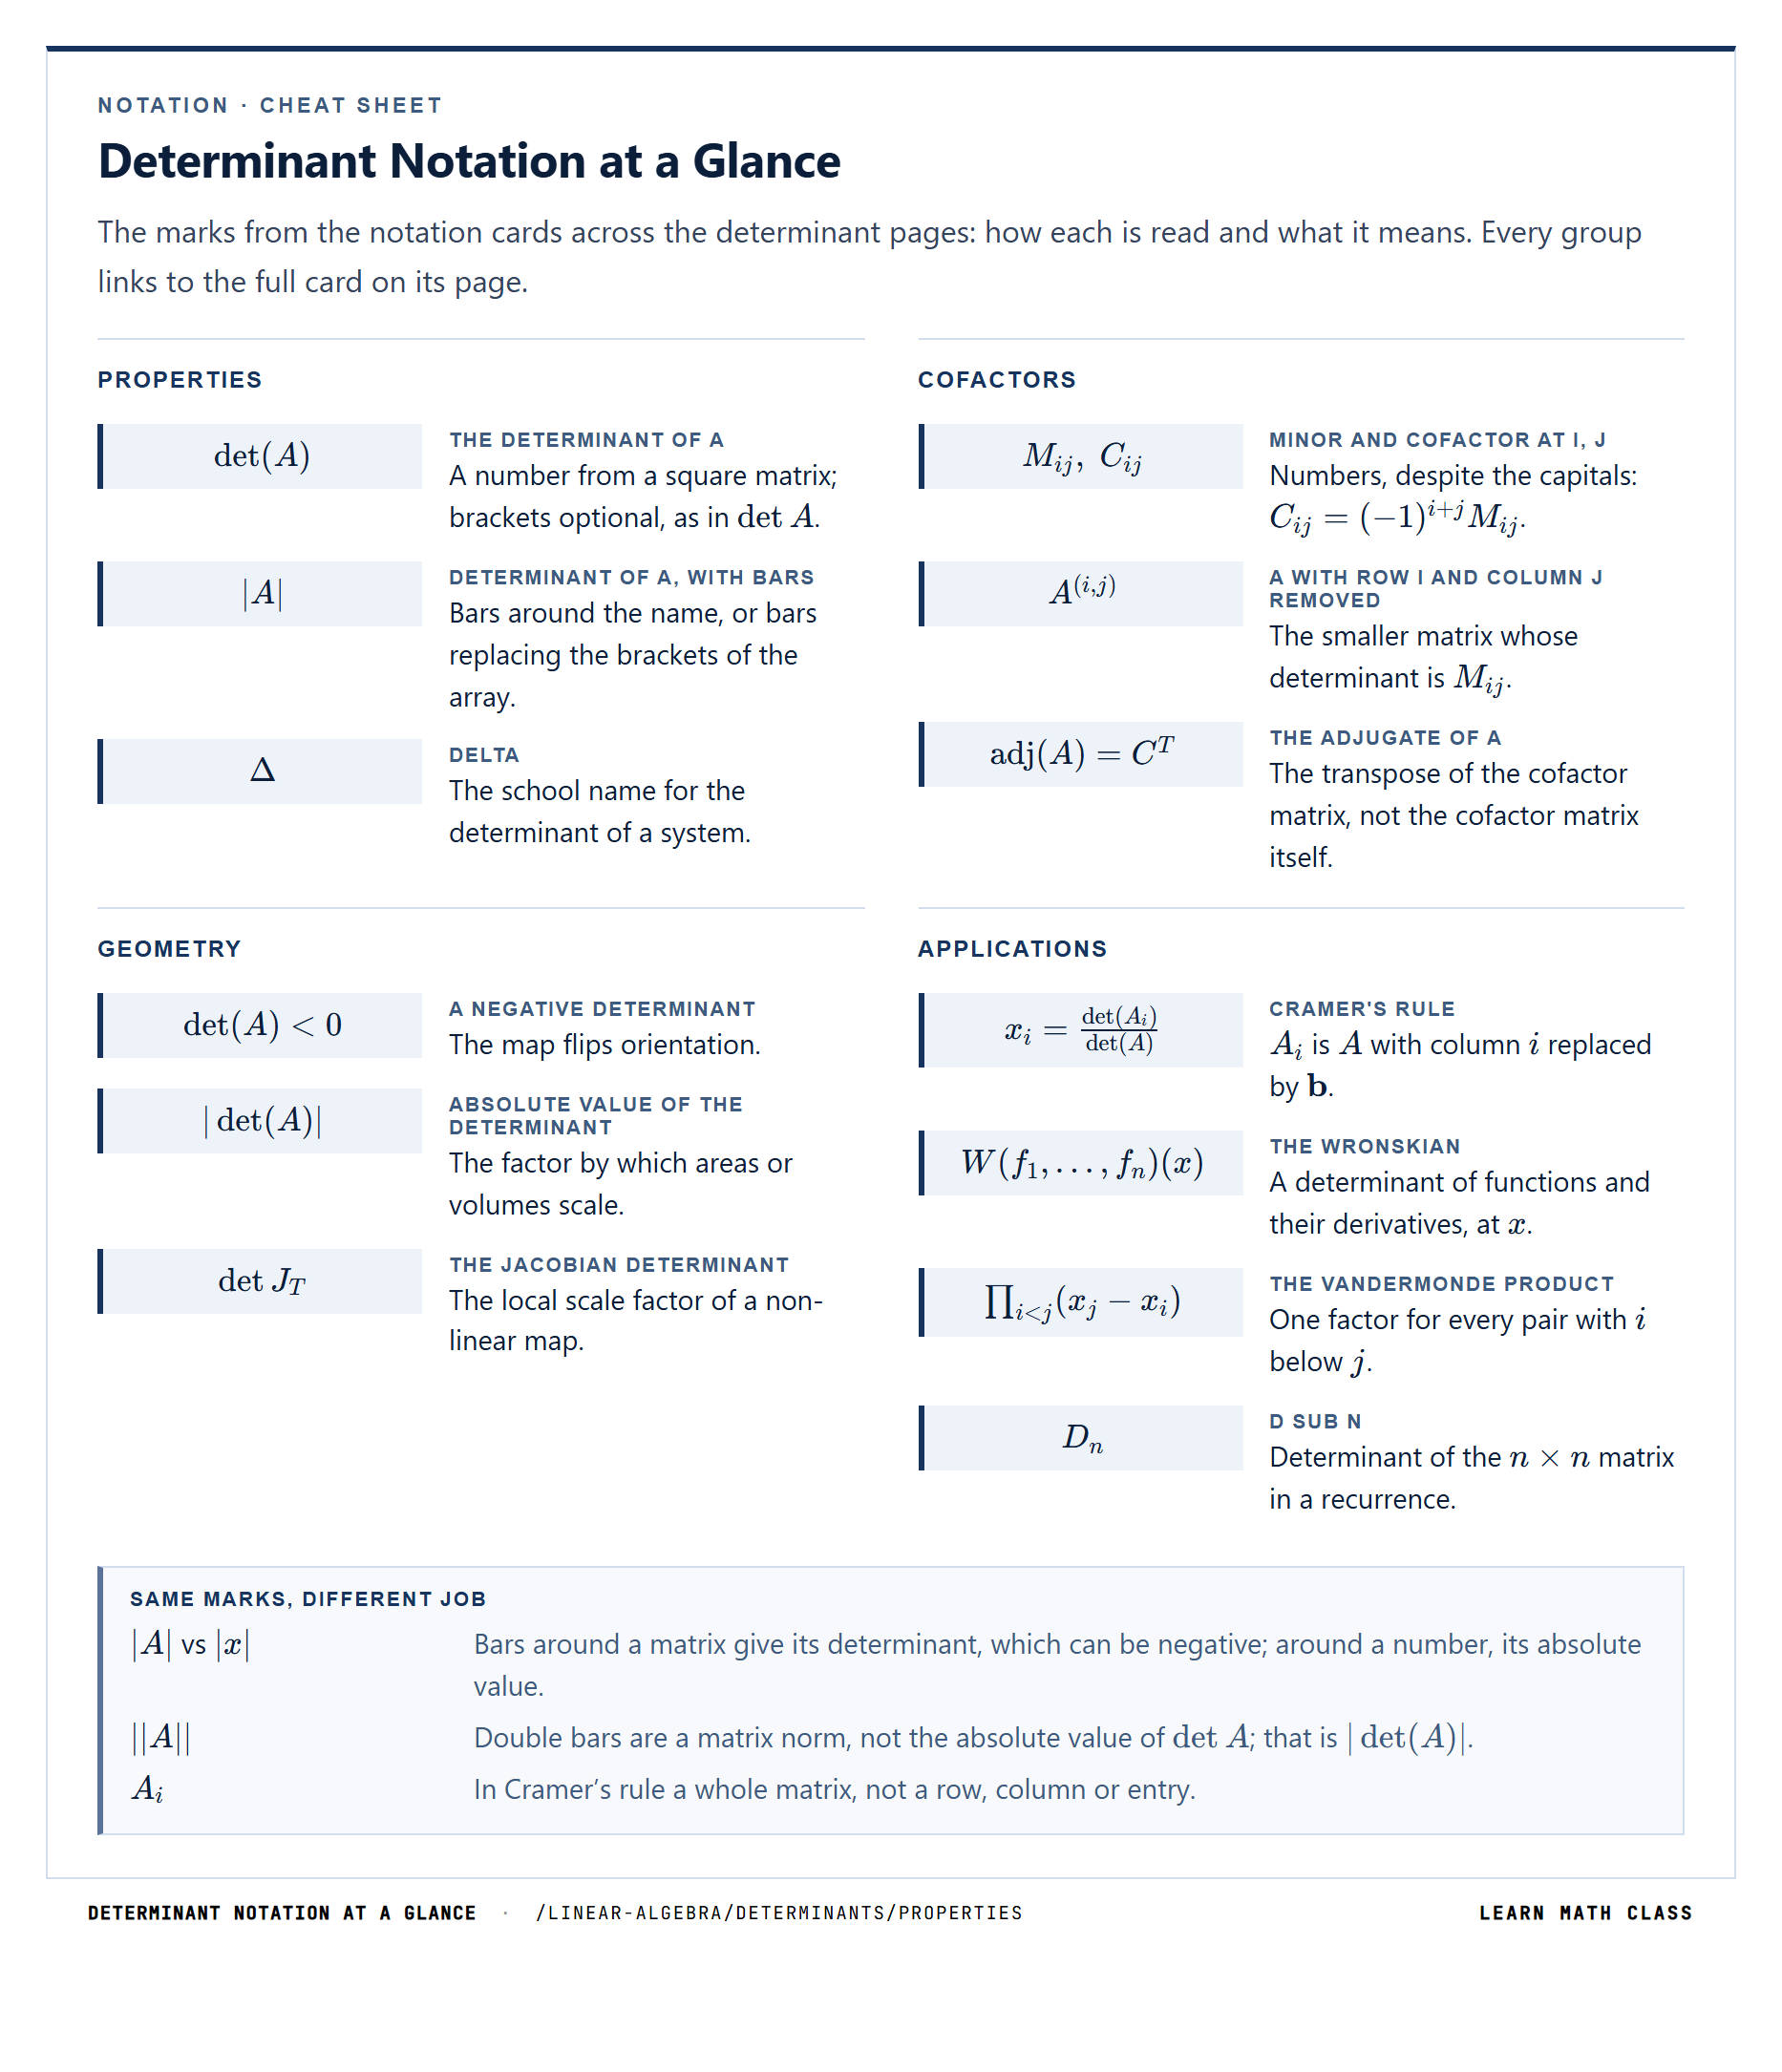
Notation · Cheat sheet
Determinant Notation at a Glance
The marks from the notation cards across the determinant pages: how each is read and what it means. Every group links to the full card on its page.
Properties
det⁡(A)\det(A)
the determinant of A
A number from a square matrix; brackets optional, as in det⁡A\det A.
∣A∣|A|
determinant of A, with bars
Bars around the name, or bars replacing the brackets of the array.
Δ\Delta
delta
The school name for the determinant of a system.
CofactorsThis page
Mij,  CijM_{ij}, \; C_{ij}
minor and cofactor at i, j
Numbers, despite the capitals: Cij=(−1)i+jMijC_{ij} = (-1)^{i+j}M_{ij}.
A(i,j)A^{(i,j)}
A with row i and column j removed
The smaller matrix whose determinant is MijM_{ij}.
adj⁡(A)=CT\operatorname{adj}(A) = C^{T}
the adjugate of A
The transpose of the cofactor matrix, not the cofactor matrix itself.
Geometry
det⁡(A)<0\det(A) < 0
a negative determinant
The map flips orientation.
∣det⁡(A)∣|\det(A)|
absolute value of the determinant
The factor by which areas or volumes scale.
det⁡JT\det J_T
the Jacobian determinant
The local scale factor of a non-linear map.
Applications
xi=det⁡(Ai)det⁡(A)x_i = \frac{\det(A_i)}{\det(A)}
Cramer's rule
AiA_i is AA with column ii replaced by b\mathbf{b}.
W(f1,…,fn)(x)W(f_1, \dots, f_n)(x)
the Wronskian
A determinant of functions and their derivatives, at xx.
∏i<j(xj−xi)\prod_{i < j} (x_j - x_i)
the Vandermonde product
One factor for every pair with ii below jj.
DnD_n
D sub n
Determinant of the n×nn \times n matrix in a recurrence.
Same marks, different job
∣A∣|A| vs ∣x∣|x|Bars around a matrix give its determinant, which can be negative; around a number, its absolute value.
∣∣A∣∣||A||Double bars are a matrix norm, not the absolute value of det⁡A\det A; that is ∣det⁡(A)∣|\det(A)|.
AiA_iIn Cramer’s rule a whole matrix, not a row, column or entry.
Determinant Notation at a Glance·/linear-algebra/determinants/propertiesLearn Math Class

Cofactors and the Sign Pattern

With the minors in hand, the natural guess is that a determinant is each entry times its minor, added up.
Across row 1 of the matrix from the previous section, that means 2⋅M11+5⋅M12+1⋅M132 \cdot M_{11} + 5 \cdot M_{12} + 1 \cdot M_{13} — every entry weighted by the determinant of what is left when its row and column are removed.
The plain sum comes out to 68, but the determinant is −12.
row-1 entryits minorentry × minorwith the checkerboard sign
a₁₁ = 2M₁₁ = 2040+40
a₁₂ = 5M₁₂ = 840−40
a₁₃ = 1M₁₃ = −12−12−12
total68 — wrong−12 — the determinant
Flipping the sign of the middle term turns 6868 into −12-12, the correct value.
The failure was predictable: even the 2 × 2 determinant ad − bc already carries a minus sign.
Expanding (abcd)\begin{pmatrix} a & b \\ c & d \end{pmatrix} along its first row gives a⋅da \cdot d and b⋅cb \cdot c, and they must be subtracted, not added. Larger determinants inherit that alternation, like the colours of a chessboard: neighbouring positions always have opposite signs.
The exponent i+ji + j determines whether the sign is positive or negative. When i+ji + j is even, the cofactor equals the minor; when i+ji + j is odd, the cofactor is the negative of the minor. This produces a checkerboard of signs across the matrix:
Cofactors and the Sign Pattern
(+−+−−+−++−+−−+−+)\begin{pmatrix} + & - & + & - \\ - & + & - & + \\ + & - & + & - \\ - & + & - & + \end{pmatrix}
The definition
The cofactor CijC_{ij} is the minor MijM_{ij} with the sign of position (i,j)(i, j) on the checkerboard attached: Cij=(−1)i+jMijC_{ij} = (-1)^{i+j} M_{ij}. Entries times their cofactors add up to the determinant.
The cofactor CijC_{ij} attaches a prescribed sign to the minor:
Cofactor Definition
Cij=(−1)i+j MijC_{ij} = (-1)^{i+j} \, M_{ij}
So C12=(−1)3⋅8=−8C_{12} = (-1)^{3} \cdot 8 = -8, and 2⋅20+5⋅(−8)+1⋅(−12)=−122 \cdot 20 + 5 \cdot (-8) + 1 \cdot (-12) = -12.
A cofactor is a signed minor: one number for each position of the matrix.
Using the 3×33 \times 3 matrix from the previous section, the cofactors are:
Cofactors and the Sign Pattern
C11=(+1)(20)=20,C12=(−1)(8)=−8,C13=(+1)(−12)=−12C_{11} = (+1)(20) = 20, \quad C_{12} = (-1)(8) = -8, \quad C_{13} = (+1)(-12) = -12
Cofactors and the Sign Pattern
C21=(−1)(29)=−29,C22=(+1)(8)=8,C23=(−1)(−18)=18C_{21} = (-1)(29) = -29, \quad C_{22} = (+1)(8) = 8, \quad C_{23} = (-1)(-18) = 18
Cofactors and the Sign Pattern
C31=(+1)(−13)=−13,C32=(−1)(−4)=4,C33=(+1)(6)=6C_{31} = (+1)(-13) = -13, \quad C_{32} = (-1)(-4) = 4, \quad C_{33} = (+1)(6) = 6
Comparing cofactors to minors, entries at even-sum positions are unchanged while entries at odd-sum positions flip sign.
Position (i, j) Minor Mij Sign (−1)i+j Cofactor Cij
(1, 1) 20 + 20
(1, 2) 8 − −8
(1, 3) −12 + −12
(2, 1) 29 − −29
(2, 2) 8 + 8
(2, 3) −18 − 18
(3, 1) −13 + −13
(3, 2) −4 − 4
(3, 3) 6 + 6
Read backwards, the sign rule is a test: a sign depends only on position, never on the entries.
The pattern always starts with ++ at position (1,1)(1,1) and alternates from there. The sign depends entirely on the position — the actual entries of the matrix play no role in determining it.
sign pattern4×4+−+−−+−++−+−−+−+
The alternating sign board

Signs alternate from the top-left corner outward, so a position's sign depends only on whether its row and column indices sum to an even or an odd number. The board is fixed, independent of the matrix's contents, and it is the only thing separating a minor from a cofactor. Generate it at other sizes on the determinant visualizer.

Because the board never changes, the sign of a cofactor can always be read off its position without any computation.
The full expansion of a determinant by cofactors is the subject of the next section, Laplace expansion along a row.
The rest of the page covers Laplace expansion along a row and along a column, the cofactor matrix, the adjugate, and the computational cost.

Laplace Expansion Along a Row

The determinant of AA can be computed by selecting any row ii and summing the products of each entry in that row with its cofactor:

Laplace Row Expansion
det⁡(A)=∑j=1naij Cijfor any fixed row i\det(A) = \sum_{j=1}^{n} a_{ij} \, C_{ij} \qquad \text{for any fixed row } i

Expanded with the explicit sign factor: det⁡(A)=∑j=1n(−1)i+j aij Mij\det(A) = \sum_{j=1}^{n} (-1)^{i+j} \, a_{ij} \, M_{ij}.

The remarkable fact is that every row produces the same number. Expanding along row 11, row 22, or row nn all yield the same determinant. This is not obvious from the formula itself — the proof relies on the algebraic properties of the determinant or on the permutation-based definition.

Worked Example: 4×4 Matrix


Laplace Expansion Along a Row
A=(1302−102104−13210−2)A = \begin{pmatrix} 1 & 3 & 0 & 2 \\ -1 & 0 & 2 & 1 \\ 0 & 4 & -1 & 3 \\ 2 & 1 & 0 & -2 \end{pmatrix}

Expanding along row 11:

Laplace Expansion Along a Row
det⁡(A)=1⋅C11+3⋅C12+0⋅C13+2⋅C14\det(A) = 1 \cdot C_{11} + 3 \cdot C_{12} + 0 \cdot C_{13} + 2 \cdot C_{14}

The zero entry at position (1,3)(1,3) eliminates one 3×33 \times 3 determinant entirely. The three remaining cofactors require expanding the sub-determinants:

Laplace Expansion Along a Row
M11=det⁡(0214−1310−2)=0(2−0)−2(−8−3)+1(0+1)=0+22+1=23M_{11} = \det\begin{pmatrix} 0 & 2 & 1 \\ 4 & -1 & 3 \\ 1 & 0 & -2 \end{pmatrix} = 0(2 - 0) - 2(-8 - 3) + 1(0 + 1) = 0 + 22 + 1 = 23

Laplace Expansion Along a Row
M12=det⁡(−1210−1320−2)=−1(2−0)−2(0−6)+1(0+2)=−2+12+2=12M_{12} = \det\begin{pmatrix} -1 & 2 & 1 \\ 0 & -1 & 3 \\ 2 & 0 & -2 \end{pmatrix} = -1(2 - 0) - 2(0 - 6) + 1(0 + 2) = -2 + 12 + 2 = 12

Laplace Expansion Along a Row
M14=det⁡(−10204−1210)=−1(0+1)−0(0+2)+2(0−8)=−1+0−16=−17M_{14} = \det\begin{pmatrix} -1 & 0 & 2 \\ 0 & 4 & -1 \\ 2 & 1 & 0 \end{pmatrix} = -1(0 + 1) - 0(0 + 2) + 2(0 - 8) = -1 + 0 - 16 = -17

Applying the signs: C11=+23C_{11} = +23, C12=−12C_{12} = -12, C14=−(−17)=+17C_{14} = -(-17) = +17. The determinant is

Laplace Expansion Along a Row
det⁡(A)=1(23)+3(−12)+0+2(17)=23−36+34=21\det(A) = 1(23) + 3(-12) + 0 + 2(17) = 23 - 36 + 34 = 21

Pitfall: Dropping the sign factor
Using the minors in place of the cofactors gives 1(23)+3(12)+0+2(−17)=251(23) + 3(12) + 0 + 2(-17) = 25. With the signs +,−,+,−+, -, +, - of row 11, the sum is 23−36+34=2123 - 36 + 34 = 21.

Every term of the expansion is built from three pieces: an entry of the chosen row, the minor left after deleting that entry's row and column, and the sign the checkerboard gives to its position. The minors are plain determinants of the smaller matrices and carry no sign of their own; the sign enters only when each minor is turned into a cofactor.

Verification via a Different Row


Expanding the same matrix along row 33 (which has a zero in the first position) would produce the same value 2121, confirming that the choice of row is purely a matter of computational convenience.
A3×3a1,1a1,2a1,3a2,1a2,2a2,3a3,1a3,2a3,3→M1,22×2a2,1a2,3a3,1a3,3
One row expanded, term by term

Each entry of the row is multiplied by the determinant of the matrix left when its own row and column are removed, and the sign board decides whether the term is added or subtracted. The recursion is visible: every minor is itself a determinant awaiting the same treatment. Expand along a column instead and check the answer matches on the determinant visualizer.

Expanding along a row with zeros in it kills those terms before their minors are ever computed, which is the only real economy available here.

Laplace Expansion Along a Column

The expansion formula works identically along columns. Fixing column jj:

Laplace Column Expansion
det⁡(A)=∑i=1naij Cijfor any fixed column j\det(A) = \sum_{i=1}^{n} a_{ij} \, C_{ij} \qquad \text{for any fixed column } j

Expanded with the explicit sign factor: det⁡(A)=∑i=1n(−1)i+j aij Mij\det(A) = \sum_{i=1}^{n} (-1)^{i+j} \, a_{ij} \, M_{ij}.

That column expansion gives the same result as row expansion follows from transpose invariance: since det⁡(AT)=det⁡(A)\det(A^T) = \det(A), expanding AA along column jj is the same as expanding ATA^T along row jj.

The practical consequence is that before starting any cofactor expansion, the first step should be to scan the matrix for the row or column containing the most zeros. Each zero entry eliminates an entire sub-determinant from the sum.

Worked Example


Laplace Expansion Along a Column
B=(3001−25407)B = \begin{pmatrix} 3 & 0 & 0 \\ 1 & -2 & 5 \\ 4 & 0 & 7 \end{pmatrix}

Column 22 has two zeros. Expanding along column 22:

Laplace Expansion Along a Column
det⁡(B)=0⋅C12+(−2)⋅C22+0⋅C32=(−2)⋅C22\det(B) = 0 \cdot C_{12} + (-2) \cdot C_{22} + 0 \cdot C_{32} = (-2) \cdot C_{22}

The minor M22M_{22} is the 2×22 \times 2 determinant from deleting row 22 and column 22:

Laplace Expansion Along a Column
M22=det⁡(3047)=21M_{22} = \det\begin{pmatrix} 3 & 0 \\ 4 & 7 \end{pmatrix} = 21

Since C22=(−1)2+2(21)=21C_{22} = (-1)^{2+2}(21) = 21, we get det⁡(B)=(−2)(21)=−42\det(B) = (-2)(21) = -42.

An expansion along row 11 or column 11 would require more terms but produce the same result. The column 22 expansion reduced the work to a single 2×22 \times 2 determinant.
A3×3a1,1a1,2a1,3a2,1a2,2a2,3a3,1a3,2a3,3→M2,12×2a1,2a1,3a3,2a3,3
Expanding down column 1

The same expansion, turned ninety degrees. The pivot is now a21, the second entry of the first column; its row and column are struck out, and what is left is the minor M21, shown alongside. Its sign comes from the same checkerboard, (−1)2+1 = −1. Summing ai1Ci1 down the column gives exactly the determinant the row expansion gave. Run both directions on the determinant visualizer.

Whichever row or column is chosen, the answer is the same, so the practical choice is always the line with the most zeros.

The Cofactor Matrix

The cofactor matrix of AA, sometimes written cof(A)\text{cof}(A), is the n×nn \times n matrix whose (i,j)(i,j) entry is the cofactor CijC_{ij}:

Cofactor Matrix Definition
cof⁡(A)=[Cij]n×n\operatorname{cof}(A) = \bigl[C_{ij}\bigr]_{n \times n}

It is not the matrix of minors — the sign factors (−1)i+j(-1)^{i+j} are already incorporated.

For the 3×33 \times 3 matrix used earlier,

The Cofactor Matrix
A=(25103−2416)A = \begin{pmatrix} 2 & 5 & 1 \\ 0 & 3 & -2 \\ 4 & 1 & 6 \end{pmatrix}

the cofactor matrix is

The Cofactor Matrix
cof(A)=(20−8−12−29818−1346)\text{cof}(A) = \begin{pmatrix} 20 & -8 & -12 \\ -29 & 8 & 18 \\ -13 & 4 & 6 \end{pmatrix}

where each entry was computed in the earlier sections. As a check, the Laplace expansion along row 11 should give det⁡(A)=2(20)+5(−8)+1(−12)=40−40−12=−12\det(A) = 2(20) + 5(-8) + 1(-12) = 40 - 40 - 12 = -12. Along row 22: 0(−29)+3(8)+(−2)(18)=0+24−36=−120(-29) + 3(8) + (-2)(18) = 0 + 24 - 36 = -12. Along row 33: 4(−13)+1(4)+6(6)=−52+4+36=−124(-13) + 1(4) + 6(6) = -52 + 4 + 36 = -12. All three rows agree.

Pitfall: Starting every row with a plus sign
Giving row 22 the signs +,−,++, -, + turns its expansion into 0(29)−3(8)+(−2)(−18)=120(29) - 3(8) + (-2)(-18) = 12. Row 22 starts with (−1)2+1=−1(-1)^{2+1} = -1, so its signs are −,+,−-, +, - and the sum is −12-12.

The cofactor matrix encodes every possible cofactor expansion simultaneously — each row of cof(A)\text{cof}(A) contains the cofactors needed for expansion along the corresponding row of AA, and each column contains those needed for column expansion.

The Adjugate

The adjugate (also called the classical adjoint) of AA is the transpose of the cofactor matrix:

Adjugate Definition
adj⁡(A)=cof⁡(A)T\operatorname{adj}(A) = \operatorname{cof}(A)^T

For the running example:

The Adjugate
adj⁡(A)=(20−29−13−884−12186)\operatorname{adj}(A) = \begin{pmatrix} 20 & -29 & -13 \\ -8 & 8 & 4 \\ -12 & 18 & 6 \end{pmatrix}

The Fundamental Identity


The adjugate satisfies

Adjugate Identity
A⋅adj⁡(A)=adj⁡(A)⋅A=det⁡(A) IA \cdot \operatorname{adj}(A) = \operatorname{adj}(A) \cdot A = \det(A) \, I

Pitfall: Forgetting to transpose the cofactors
Using cof⁡(A)\operatorname{cof}(A) itself as the adjugate pairs row 11 of AA with column 11 of cof⁡(A)\operatorname{cof}(A): 2(20)+5(−29)+1(−13)=−1182(20) + 5(-29) + 1(-13) = -118, not −12-12. After the transpose, row 11 meets its own cofactors: 2(20)+5(−8)+1(−12)=−122(20) + 5(-8) + 1(-12) = -12.

To see why, consider the (i,k)(i,k) entry of the product A⋅adj⁡(A)A \cdot \operatorname{adj}(A). This is ∑j=1naij⋅[adj⁡(A)]jk=∑j=1naij Ckj\sum_{j=1}^{n} a_{ij} \cdot [\operatorname{adj}(A)]_{jk} = \sum_{j=1}^{n} a_{ij} \, C_{kj}. When i=ki = k, this sum is exactly the Laplace expansion of det⁡(A)\det(A) along row ii, so the diagonal entries equal det⁡(A)\det(A). When i≠ki \neq k, the sum pairs the entries of row ii with the cofactors of a different row kk. This is equivalent to computing the determinant of a matrix with two identical rows (row ii appears in both its own position and row kk's), which is always zero. So the off-diagonal entries vanish.

Verification


With det⁡(A)=−12\det(A) = -12:

The Adjugate
A⋅adj⁡(A)=(25103−2416)(20−29−13−884−12186)=(−12000−12000−12)=−12 IA \cdot \operatorname{adj}(A) = \begin{pmatrix} 2 & 5 & 1 \\ 0 & 3 & -2 \\ 4 & 1 & 6 \end{pmatrix} \begin{pmatrix} 20 & -29 & -13 \\ -8 & 8 & 4 \\ -12 & 18 & 6 \end{pmatrix} = \begin{pmatrix} -12 & 0 & 0 \\ 0 & -12 & 0 \\ 0 & 0 & -12 \end{pmatrix} = -12 \, I

Fact: A singular adjugate has rank 1 or 0
When det⁡(A)=0\det(A) = 0, the identity says A⋅adj⁡(A)=OA \cdot \operatorname{adj}(A) = O, so every column of adj⁡(A)\operatorname{adj}(A) lies in the null space of AA. If that null space is a single line, adj⁡(A)\operatorname{adj}(A) has rank exactly 11; if it is larger, every cofactor is 00.

This identity is the foundation of the adjugate inverse formula: dividing both sides by det⁡(A)\det(A) gives A−1=1det⁡(A)adj⁡(A)A^{-1} = \frac{1}{\det(A)} \operatorname{adj}(A), valid whenever det⁡(A)≠0\det(A) \neq 0.
The identity itself asks nothing of det⁡(A)\det(A). The adjugate is built entry by entry from the minors, so it exists for every square matrix, singular or not. For (1224)\begin{pmatrix} 1 & 2 \\ 2 & 4 \end{pmatrix}, whose determinant is 00, the adjugate is (4−2−21)\begin{pmatrix} 4 & -2 \\ -2 & 1 \end{pmatrix}, and the product of the two matrices is the zero matrix, exactly as det⁡(A) I\det(A) \, I predicts.
A row paired with its own cofactors gives the determinant; paired with another row's cofactors, it gives zero.

Computational Cost

Cofactor expansion is a recursive algorithm. Each n×nn \times n determinant spawns nn sub-problems of size (n−1)×(n−1)(n-1) \times (n-1). Without any zero entries to prune terms, the total number of multiplications satisfies the recurrence T(n)=n⋅T(n−1)T(n) = n \cdot T(n-1), which gives T(n)=O(n!)T(n) = O(n!).

To put this in concrete terms: a 10×1010 \times 10 determinant via cofactor expansion requires roughly 10!≈3.610! \approx 3.6 million multiplications. A 20×2020 \times 20 determinant would require over 2×10182 \times 10^{18} — well beyond the reach of any computer running a naive recursive implementation. Row reduction, by contrast, computes the same determinant in roughly 23n3\frac{2}{3}n^3 operations: about 670670 for n=10n = 10 and about 53005300 for n=20n = 20.

This cost difference does not make cofactor expansion useless. For matrices up to 4×44 \times 4, the expansion is fast enough to do by hand and gives the exact symbolic result. For matrices with many zero entries, the effective cost drops dramatically because each zero eliminates an entire recursive branch. In symbolic computation — where entries are polynomials or formal expressions rather than numbers — cofactor expansion preserves structure that row reduction would obscure.

The Laplace expansion is best understood as a theoretical instrument. It defines what the determinant is, establishes its algebraic properties, and produces the adjugate and the cofactor structure. For numerical computation on anything larger than a small matrix, the row-reduction approach is the practical choice.
Matrix size n Cofactor expansion ≈ n! Row reduction ≈ (2/3)n³ Ratio
4 24 ≈ 43 cofactor faster
5 120 ≈ 83 ≈ 1.4×
10 ≈ 3.6 million ≈ 670 ≈ 5400×
20 ≈ 2.4 × 10¹⁸ ≈ 5,300 ≈ 5 × 10¹⁴×

Summary: The Cofactor Construction Chain

The objects introduced above — minor, cofactor, cofactor matrix, adjugate — form a single construction chain, each built from the previous one and culminating in the inverse formula. The table below collects each link in the chain alongside its definition, its shape (number or matrix), and the role it plays in connecting one stage to the next.
These six are a chain rather than a list, and the order is not negotiable: a cofactor needs a minor, an expansion needs cofactors, the cofactor matrix collects them, the adjugate transposes it, and the inverse formula divides by the determinant. Each definition exists because the next one requires it, which is why the terminology is worth learning in one pass rather than six.
DownloadPNG2×PDF
Determinants · cofactors

The cofactor construction chain

Six definitions in strict order, each built from the one above it. Read alone they look like six pieces of terminology; read as a chain they are one construction, and the last step is what the first five were for.

6steps
Building a number3
1
a number; unsigned
Mij=det⁡(AM_{ij} = \det(A with row ii, column jj deleted))
The raw building block, and note it is itself a determinant — the definition is recursive, which is where the cost comes from. For a 3×33 \times 3 matrix each minor is a 2×22 \times 2 determinant; for a 4×44 \times 4 each is a 3×33 \times 3, and so on down.
2
a number; signed
Cij=(−1)i+jMijC_{ij} = (-1)^{i+j} M_{ij}
The minor with a checkerboard sign attached. The sign is not decoration — it is what makes the expansion below add up to the determinant rather than to nothing in particular, and dropping it is the most common error in the whole construction.
3
any single row or column
det⁡(A)=∑jaijCij\det(A) = \sum_j a_{ij}C_{ij}
Where the cofactors do their work. Any row or column gives the same answer — a consequence of transpose invariance — so choose the one with the most zeros, since each zero entry removes an entire minor from the calculation.
Building a matrix3
4
an n×nn \times n matrix
cof⁡(A)ij=Cij\operatorname{cof}(A)_{ij} = C_{ij}
Every cofactor collected in position. On its own it does nothing; it exists to be transposed in the next step, which is the only reason to compute all n2n^2 of them rather than the single row the expansion needs.
5
A⋅adj⁡(A)=det⁡(A)⋅IA \cdot \operatorname{adj}(A) = \det(A) \cdot I
adj⁡(A)=cof⁡(A)T\operatorname{adj}(A) = \operatorname{cof}(A)^{\mathsf{T}}
The transpose, and the identity beside it is the whole point of the chain. It holds for every square matrix including singular ones — when det⁡(A)=0\det(A) = 0 it says A⋅adj⁡(A)=OA \cdot \operatorname{adj}(A) = O, which is a real statement rather than a failure.
6
det⁡(A)≠0\det(A) \neq 0
A−1=1det⁡Aadj⁡(A)A^{-1} = \dfrac{1}{\det A}\operatorname{adj}(A)
Divide the identity above by det⁡(A)\det(A) and the inverse falls out. This is the end of the chain and its justification — an explicit formula for every entry of the inverse in terms of the entries of AA.
Nothing in this chain is a good way to compute anything. A minor is a determinant, so each level multiplies the work by nn — which is why row reduction computes determinants and factorization computes inverses. The chain earns its place by giving a closed form, not a method.
The cofactor construction chain·/linear-algebra/determinants/cofactorsLearn Math Class
The identity A⋅adj⁡(A)=det⁡(A)⋅IA \cdot \operatorname{adj}(A) = \det(A) \cdot I is the destination, and it is more general than the inverse formula it produces. It holds for every square matrix, singular ones included — where it says A⋅adj⁡(A)=OA \cdot \operatorname{adj}(A) = O, which is informative rather than vacuous. Dividing by det⁡(A)\det(A) is the last step, and it is the only step that requires a hypothesis.
None of this is how anything is computed. A minor is a determinant, so every level of the recursion multiplies the work by another factor of nn — the adjugate of a 5×55 \times 5 matrix means twenty-five 4×44 \times 4 determinants, each of which means four 3×33 \times 3 determinants. Reduction computes a determinant in 23n3\tfrac{2}{3}n^3 operations and factorization inverts in 2n32n^3. What the chain provides instead is a closed form, and closed forms are what proofs and symbolic work need.
Common Pitfalls

Three slips come up again and again in cofactor work. Each is marked with a box where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.
DownloadPNG2×PDF
1Dropping the sign factor
The entries of the expansion row are multiplied by their minors MijM_{ij} instead of their cofactors CijC_{ij}. The checkerboard signs never enter, so every term at a position where i+ji + j is odd comes out with the wrong sign.
Wrong turn
Error here
For the 4×44 \times 4 matrix of the worked example, expanding along row 11 with the minors M11=23M_{11} = 23, M12=12M_{12} = 12, M14=−17M_{14} = -17,
1⋅23+3⋅12+01 \cdot 23 + 3 \cdot 12 + 0

+2⋅(−17)=23+36−34+ 2 \cdot (-17) = 23 + 36 - 34

=25= 25
Right path
The positions (1,1),(1,2),(1,3),(1,4)(1,1), (1,2), (1,3), (1,4) carry the signs +,−,+,−+, -, +, -, so C12=−12C_{12} = -12 and C14=+17C_{14} = +17.
1⋅23+3⋅(−12)+01 \cdot 23 + 3 \cdot (-12) + 0

+2⋅17=23−36+34+ 2 \cdot 17 = 23 - 36 + 34

=21= 21
Why it happensThe minors take all the effort, and once they are found the expansion looks finished. The 2×22 \times 2 minors already contain a minus sign of their own, in ad−bcad - bc, which makes it easy to believe the signs have been taken care of.
How to checkExpand along a second row. Along row 33, which is (0,4,−1,3)(0, 4, -1, 3), the minors are M32=−12M_{32} = -12, M33=−3M_{33} = -3, M34=10M_{34} = 10, and with the signs −,+,−-, +, - at those positions the sum is 4⋅12+(−1)(−3)+3⋅(−10)=48+3−30=214 \cdot 12 + (-1)(-3) + 3 \cdot (-10) = 48 + 3 - 30 = 21, matching row 11. Without signs the same row gives 4(−12)+(−1)(−3)+3(10)=−154(-12) + (-1)(-3) + 3(10) = -15, which disagrees with the 2525 from row 11.
2Starting every row with a plus sign
The signs +,−,++, -, + are written down afresh at the start of every row or column instead of being read from the checkerboard. Along an odd-numbered row or column the pattern really does start with ++, so the slip goes unnoticed there; along an even-numbered one every sign is reversed, and so is the determinant.
Start
For A=(25103−2416)A = \begin{pmatrix} 2 & 5 & 1 \\ 0 & 3 & -2 \\ 4 & 1 & 6 \end{pmatrix},
Wrong turn
Error here
Row 22 has the minors M21=29M_{21} = 29, M22=8M_{22} = 8, M23=−18M_{23} = -18. With the signs +,−,++, -, +,
0⋅29−3⋅8+(−2)(−18)0 \cdot 29 - 3 \cdot 8 + (-2)(-18)

=0−24+36=12= 0 - 24 + 36 = 12
Right path
The sign at position (2,1)(2,1) is (−1)2+1=−1(-1)^{2+1} = -1, so row 22 runs −,+,−-, +, -.
−0⋅29+3⋅8−(−2)(−18)-0 \cdot 29 + 3 \cdot 8 - (-2)(-18)

=0+24−36=−12= 0 + 24 - 36 = -12
Which matches the expansions along rows 11 and 33.
Why it happensMost first examples are expanded along row 11, where the pattern begins with ++, and the habit is carried over to the other rows.
How to checkThe first sign of row ii is (−1)i+1(-1)^{i+1}, plus for odd rows and minus for even rows. If a second expansion gives the same size but the opposite sign, this slip is the usual cause.
3Forgetting to transpose the cofactors
The cofactor matrix itself is used as the adjugate. The identity A⋅adj⁡(A)=det⁡(A) IA \cdot \operatorname{adj}(A) = \det(A) \, I then fails, and so does the inverse formula built on it. The slip is invisible only when cof⁡(A)\operatorname{cof}(A) happens to be symmetric.
Wrong turn
Error here
With the running example,
A⋅cof⁡(A)A \cdot \operatorname{cof}(A)

=(25103−2416)(20−8−12−29818−1346)= \begin{pmatrix} 2 & 5 & 1 \\ 0 & 3 & -2 \\ 4 & 1 & 6 \end{pmatrix} \begin{pmatrix} 20 & -8 & -12 \\ -29 & 8 & 18 \\ -13 & 4 & 6 \end{pmatrix}

=(−1182872−611642−2706)= \begin{pmatrix} -118 & 28 & 72 \\ -61 & 16 & 42 \\ -27 & 0 & 6 \end{pmatrix}
Which is not a multiple of II, so dividing it by det⁡(A)=−12\det(A) = -12 does not give A−1A^{-1}.
Right path
Transpose first, adj⁡(A)=cof⁡(A)T\operatorname{adj}(A) = \operatorname{cof}(A)^T. The product is then −12 I-12 \, I, as in the verification of the adjugate section.
Why it happensThe cofactor matrix is where all the work goes, and the transpose is a last step with no arithmetic in it. The cofactor CijC_{ij} belongs to position (i,j)(i,j) of AA, so it feels natural to leave it there.
How to checkEvery diagonal entry of AA times the candidate adjugate is a Laplace expansion and must equal det⁡(A)\det(A). Row 22 of AA against column 22 of the true adjugate gives 0(−29)+3(8)+(−2)(18)=−120(-29) + 3(8) + (-2)(18) = -12; against column 22 of cof⁡(A)\operatorname{cof}(A) it gives 0(−8)+3(8)+(−2)(4)=160(-8) + 3(8) + (-2)(4) = 16.
Common pitfalls with cofactors·/linear-algebra/determinants/cofactorsLearn Math Class
Each slip loses a sign or a transpose. A cofactor is (−1)i+j(-1)^{i+j} times its minor, the signs of each row are read from the checkerboard, and the adjugate is the transpose of the cofactor matrix. Expanding along a second row, or checking that A⋅adj⁡(A)=det⁡(A) IA \cdot \operatorname{adj}(A) = \det(A)\,I, catches each slip.

Cofactors and Minors FAQ

Is the minor MijM_{ij} a matrix or a number?

+
A number. Deleting row ii and column jj produces a smaller matrix, but MijM_{ij} names that matrix's determinant rather than the matrix itself. The submatrix needs its own notation if you want to refer to it. Treating MijM_{ij} as an array is a species error that surfaces as soon as you try to add or multiply with it.Read more →

Why is the superscript in A(i,j)A^{(i,j)} written inside parentheses?

+
The parentheses are armour against misreading it as a power. Unfenced, AijA^{ij} would collide with exponents and with tensor index conventions at once. The same device appears in the nn-th derivative f(n)f^{(n)}. Three decorations then do three jobs on one letter: aija_{ij} selects an entry, AnA^n multiplies, A(i,j)A^{(i,j)} deletes.Read more →

Is the adjugate the same thing as the adjoint?

+
Not in modern usage. In advanced linear algebra the adjoint means the conjugate transpose A∗A^{*}, an unrelated operation. The word adjugate exists precisely to escape that collision, since older texts did use adjoint for this cofactor construction. When reading an older source, check which meaning is intended before applying anything.Read more →

Does the adjugate exist when the determinant is zero?

+
Yes. Every entry of the adjugate is a signed minor, so it can be built for any square matrix, singular or not, and the identity A⋅adj⁡(A)=det⁡(A) IA \cdot \operatorname{adj}(A) = \det(A) \, I still holds. With det⁡(A)=0\det(A) = 0 it reads A⋅adj⁡(A)=OA \cdot \operatorname{adj}(A) = O, so every column of the adjugate lies in the null space of AA, and its rank drops to 11 or 00. Only the step to the inverse fails, since it divides by det⁡(A)\det(A).Read more →

Why does a row times another row's cofactors give zero?

+
Because the sum is secretly the determinant of a matrix with two equal rows. The cofactors of row kk never look at row kk itself, so ∑jaijCkj\sum_j a_{ij} C_{kj} is exactly the expansion along row kk of the matrix in which row kk has been overwritten by a copy of row ii. Two identical rows force that determinant to 00. This is what makes the off-diagonal entries of A⋅adj⁡(A)A \cdot \operatorname{adj}(A) vanish.Read more →

When is cofactor expansion better than row reduction?

+
When the matrix is small, sparse or symbolic. Up to about 4×44 \times 4 it is quick enough by hand and gives an exact result; each zero in the chosen row or column removes a whole branch of the recursion; and when the entries are polynomials or letters, it keeps the structure that elimination would bury in fractions. For a general numerical matrix it loses badly: about 10!≈3.610! \approx 3.6 million multiplications at n=10n = 10, against roughly 670670 operations for row reduction.Read more →