Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Eigenvalues and Eigenvectors


The Directions a Matrix Preserves

Most vectors change direction when multiplied by a matrix. The rare exceptions — vectors that emerge scaled but not rotated — are eigenvectors, and their scaling factors are eigenvalues. These special directions and values encode the deepest structural information about a linear transformation: how it stretches, compresses, and orients space. They are the key to diagonalization, stability analysis, and the spectral theory that unifies much of applied mathematics.


The Core Idea

When a matrix AA multiplies a vector x\mathbf{x}, the result AxA\mathbf{x} is usually a vector pointing in a completely different direction. But for certain special vectors, the output AxA\mathbf{x} points in the same direction as x\mathbf{x} — it is simply a scaled copy.

Fact: Eigen means own
The prefix is German for own: an eigenvector is a direction that belongs to the matrix itself. The word Eigenwert, own value, comes from Hilbert's 1904 work on integral equations; English writers long said characteristic root, or Sylvester's latent root, instead.

These are the vectors that the linear transformation x↦Ax\mathbf{x} \mapsto A\mathbf{x} stretches, compresses, or reverses without deflecting. They are the "natural axes" of the transformation, and the scaling factors measure exactly how the transformation acts along each such axis. Finding these directions and factors is the eigenvalue problem.

These directions belong to the transformation, not to the way it happens to be written down. In another basis the same transformation gets a different array of numbers, yet it stretches the same lines by the same factors. The eigenvalues are therefore the same numbers whichever basis is used to write the matrix.

Definition

For an n×nn \times n matrix AA, a nonzero vector v\mathbf{v} is an eigenvector of AA if

Eigenvalue Definition
Av=λvA\mathbf{v} = \lambda\mathbf{v}
Learn more about this formula: Eigenvalue Definition →


for some scalar λ\lambda. The scalar λ\lambda is the corresponding eigenvalue.

The requirement that v≠0\mathbf{v} \neq \mathbf{0} is essential. The zero vector trivially satisfies A0=λ0A\mathbf{0} = \lambda\mathbf{0} for every λ\lambda, so it carries no information and is excluded by convention.

The eigenvalue λ\lambda can be any real or complex number, including zero. When λ=0\lambda = 0, the equation Av=0A\mathbf{v} = \mathbf{0} says that v\mathbf{v} is in the null space of AA — the transformation annihilates that direction entirely.

RULE
Only square matrices have eigenvalues.

The equation Av=λvA\mathbf{v} = \lambda\mathbf{v} requires AvA\mathbf{v} and λv\lambda\mathbf{v} to live in the same space, which demands that AA maps Rn\mathbb{R}^n to Rn\mathbb{R}^n.

Rewriting as a Homogeneous System

The eigenvalue equation Av=λvA\mathbf{v} = \lambda\mathbf{v} rearranges to

Rewriting as a Homogeneous System
(A−λI)v=0(A - \lambda I)\mathbf{v} = \mathbf{0}

This is a homogeneous linear system with coefficient matrix A−λIA - \lambda I. Eigenvectors are its nontrivial solutions. Such solutions exist if and only if A−λIA - \lambda I is singular — that is, if and only if

Characteristic Equation
det⁡(A−λI)=0\det(A - \lambda I) = 0
Learn more about this formula: Characteristic Equation →


Pitfall: Subtracting λ from every entry
Subtracting λ\lambda from all four entries of A=(4213)A = \begin{pmatrix} 4 & 2 \\ 1 & 3 \end{pmatrix} gives (4−λ)(3−λ)−(2−λ)(1−λ)=10−4λ(4 - \lambda)(3 - \lambda) - (2 - \lambda)(1 - \lambda) = 10 - 4\lambda, with the single root λ=5/2\lambda = 5/2. Since λI\lambda I puts λ\lambda only on the diagonal, det⁡(A−λI)=λ2−7λ+10\det(A - \lambda I) = \lambda^2 - 7\lambda + 10, with roots 22 and 55.

This determinant condition is the characteristic equation. It converts the eigenvalue problem from a geometric question ("which directions survive?") into an algebraic one ("which values of λ\lambda make this determinant vanish?"). The characteristic equation is a polynomial of degree nn in λ\lambda, and its roots are the eigenvalues.
A − λI3×32 − λ0003 − λ4049 − λ
Subtracting λ from the diagonal

The eigenvalue has been taken off every diagonal entry, turning the eigenvector equation into a homogeneous system. That system needs a solution other than zero, which is possible only when the shifted matrix is singular — and that requirement is where the characteristic equation comes from. Watch the shift and the determinant condition together on the eigenvalues and eigenvectors visualizer.

Every computational route on this page begins from that singularity requirement rather than from the original equation.

Eigenspaces

For a given eigenvalue λ\lambda, the eigenspace is the set of all vectors satisfying (A−λI)v=0(A - \lambda I)\mathbf{v} = \mathbf{0}, together with the zero vector:

Eigenspace
Eλ=Null(A−λI)E_\lambda = \text{Null}(A - \lambda I)
Learn more about this formula: Eigenspace →


THEOREM
The eigenspace is a subspace of Rn\mathbb{R}^n.

It contains the zero vector and is closed under addition and scalar multiplication — any linear combination of eigenvectors for the same eigenvalue is again an eigenvector for that eigenvalue (or the zero vector).

Pitfall: Accepting the zero solution
Reporting v=0\mathbf{v} = \mathbf{0} when A−λIA - \lambda I reduces with no free variable hides an error in λ\lambda. For A=(4213)A = \begin{pmatrix} 4 & 2 \\ 1 & 3 \end{pmatrix}, a sign slip gives λ=−2\lambda = -2, and A+2I=(6215)A + 2I = \begin{pmatrix} 6 & 2 \\ 1 & 5 \end{pmatrix} has det⁡=28≠0\det = 28 \neq 0, so only 0\mathbf{0} solves it. The true eigenvalue λ=2\lambda = 2 leaves a free variable and gives v=(−1,1)T\mathbf{v} = (-1, 1)^T.

The dimension of the eigenspace is called the geometric multiplicity of λ\lambda. Finding a basis for the eigenspace is a standard null-space computation: row reduce A−λIA - \lambda I and extract the general solution in parametric form. Each free variable contributes one basis vector to the eigenspace.

An eigenvalue never comes with a single eigenvector: it owns a whole subspace of them, found as an ordinary null space.

Geometric Meaning

An eigenvector v\mathbf{v} defines a direction that the transformation x↦Ax\mathbf{x} \mapsto A\mathbf{x} maps to itself. The eigenvalue λ\lambda determines what happens along that direction.

When λ>1\lambda > 1, the direction is stretched — the transformation pushes vectors outward along v\mathbf{v}. When 0<λ<10 < \lambda < 1, the direction is compressed. When λ<0\lambda < 0, the direction is reversed and scaled by ∣λ∣|\lambda| — the vector flips through the origin. When λ=1\lambda = 1, the vector is completely fixed. When λ=0\lambda = 0, the vector is annihilated — that direction is collapsed to the origin.

Quick Examples


For the matrix (300−2)\begin{pmatrix} 3 & 0 \\ 0 & -2 \end{pmatrix}, the standard basis vectors are eigenvectors: e1\mathbf{e}_1 has eigenvalue 33 (stretched) and e2\mathbf{e}_2 has eigenvalue −2-2 (reversed and doubled). A reflection across a line has eigenvalue +1+1 for vectors on the line and −1-1 for vectors perpendicular to it. A projection has eigenvalue 11 for vectors in the target subspace and 00 for vectors in its orthogonal complement.
Eigenvalue λ Geometric action along v Example
λ > 1 stretches the direction outward by a factor of λ λ = 3: vectors along v triple in length
λ = 1 leaves the vector completely fixed vectors on the reflection axis of a 2D reflection
0 < λ < 1 compresses the direction toward the origin λ = 1/2: vectors along v are halved
λ = 0 annihilates the direction; v lies in the null space vectors perpendicular to the target subspace of a projection
λ < 0 flips the vector through the origin and scales by |λ| λ = −1: a reflection across the perpendicular hyperplane
λ=2λ=0.5Avv
Two directions the matrix leaves in place

Almost every arrow is rotated by the matrix, but the two marked directions are not: they are stretched along their own line and nothing more. The eigenvalue is the stretch factor, and a negative one would flip the arrow without leaving the line. Drag a vector around and watch it snap into alignment on the eigenvector explorer.

A matrix with no real eigenvectors is one that rotates every direction, which is exactly the complex case dealt with later in the section.

Examples

For a diagonal matrix D=diag(d1,…,dn)D = \text{diag}(d_1, \dots, d_n), the eigenvalues are the diagonal entries d1,…,dnd_1, \dots, d_n and the eigenvectors are the standard basis vectors e1,…,en\mathbf{e}_1, \dots, \mathbf{e}_n. The eigenvector-eigenvalue structure is visible by inspection.

For a triangular matrix, the eigenvalues are still the diagonal entries (since det⁡(A−λI)\det(A - \lambda I) is the product of the diagonal entries of A−λIA - \lambda I), but the eigenvectors generally require computation.

Worked Example
For A=(4213)A = \begin{pmatrix} 4 & 2 \\ 1 & 3 \end{pmatrix}, the characteristic equation is det⁡(A−λI)=(4−λ)(3−λ)−2=λ2−7λ+10=(λ−2)(λ−5)=0\det(A - \lambda I) = (4 - \lambda)(3 - \lambda) - 2 = \lambda^2 - 7\lambda + 10 = (\lambda - 2)(\lambda - 5) = 0. The eigenvalues are λ1=2\lambda_1 = 2 and λ2=5\lambda_2 = 5.
For λ1=2\lambda_1 = 2: (A−2I)v=(2211)v=0(A - 2I)\mathbf{v} = \begin{pmatrix} 2 & 2 \\ 1 & 1 \end{pmatrix}\mathbf{v} = \mathbf{0} gives v1=(−1,1)T\mathbf{v}_1 = (-1, 1)^T.
For λ2=5\lambda_2 = 5: (A−5I)v=(−121−2)v=0(A - 5I)\mathbf{v} = \begin{pmatrix} -1 & 2 \\ 1 & -2 \end{pmatrix}\mathbf{v} = \mathbf{0} gives v2=(2,1)T\mathbf{v}_2 = (2, 1)^T.

Pitfall: Reading eigenvalues off the diagonal
Taking the diagonal entries 44 and 33 of A=(4213)A = \begin{pmatrix} 4 & 2 \\ 1 & 3 \end{pmatrix} as its eigenvalues fails: det⁡(A−4I)=0⋅(−1)−2⋅1=−2≠0\det(A - 4I) = 0 \cdot (-1) - 2 \cdot 1 = -2 \neq 0. The eigenvalues are 22 and 55; the diagonal gives them only for diagonal and triangular matrices.

The matrix in the worked example is neither diagonal nor triangular: both of its off-diagonal entries are nonzero. Its determinant det⁡(A−λI)\det(A - \lambda I) is therefore not a plain product of diagonal terms, since the off-diagonal product 2⋅12 \cdot 1 is subtracted from it, and the eigenvalues come only from solving the full quadratic. The eigenvectors, too, point in directions other than e1\mathbf{e}_1 and e2\mathbf{e}_2.

Rotation by 90°90° in R2\mathbb{R}^2 has matrix (0−110)\begin{pmatrix} 0 & -1 \\ 1 & 0 \end{pmatrix} and characteristic polynomial λ2+1=0\lambda^2 + 1 = 0. No real direction survives a quarter-turn — the eigenvalues are ±i\pm i, which are complex.
Matrix structure Eigenvalues Eigenvectors
Diagonal the diagonal entries d₁, …, dₙ standard basis vectors e₁, …, eₙ (visible by inspection)
Triangular still the diagonal entries require null-space computation for each (A − λI)
90° rotation in ℝ² no real eigenvalues (±i over ℂ) no real direction is preserved by a quarter-turn

Eigenvalues and Matrix Properties

Two of the most basic matrix invariants are direct functions of the eigenvalues.

The trace equals the sum of the eigenvalues: tr(A)=λ1+λ2+⋯+λn\text{tr}(A) = \lambda_1 + \lambda_2 + \cdots + \lambda_n, counted with algebraic multiplicity. This follows from the relationship between the coefficients of the characteristic polynomial and the trace.

The determinant equals the product of the eigenvalues: det⁡(A)=λ1λ2⋯λn\det(A) = \lambda_1 \lambda_2 \cdots \lambda_n. This follows from evaluating the characteristic polynomial at λ=0\lambda = 0.

Together these two identities connect the simplest diagonal entry sum and the global scaling factor to the eigenvalue spectrum. They immediately imply that AA is invertible if and only if no eigenvalue is zero, and singular if and only if at least one eigenvalue vanishes.

The full set of properties — including eigenvalues of powers, inverses, transposes, and special matrix types — is developed on its own page.

Why Eigenvalues Matter

Diagonalization is the most immediate application. If AA has nn linearly independent eigenvectors, it can be written as A=PDP−1A = PDP^{-1} where DD is the diagonal matrix of eigenvalues. This factorization reduces matrix powers to Ak=PDkP−1A^k = PD^kP^{-1} — raising a diagonal matrix to a power means raising each diagonal entry independently.

Fact: Google's ranking is an eigenvector
PageRank, the score Google first used to rank web pages, is the eigenvector for eigenvalue 11 of a matrix with one row and one column per page. With billions of pages, it was found by multiplying by the matrix over and over, never through a characteristic polynomial.

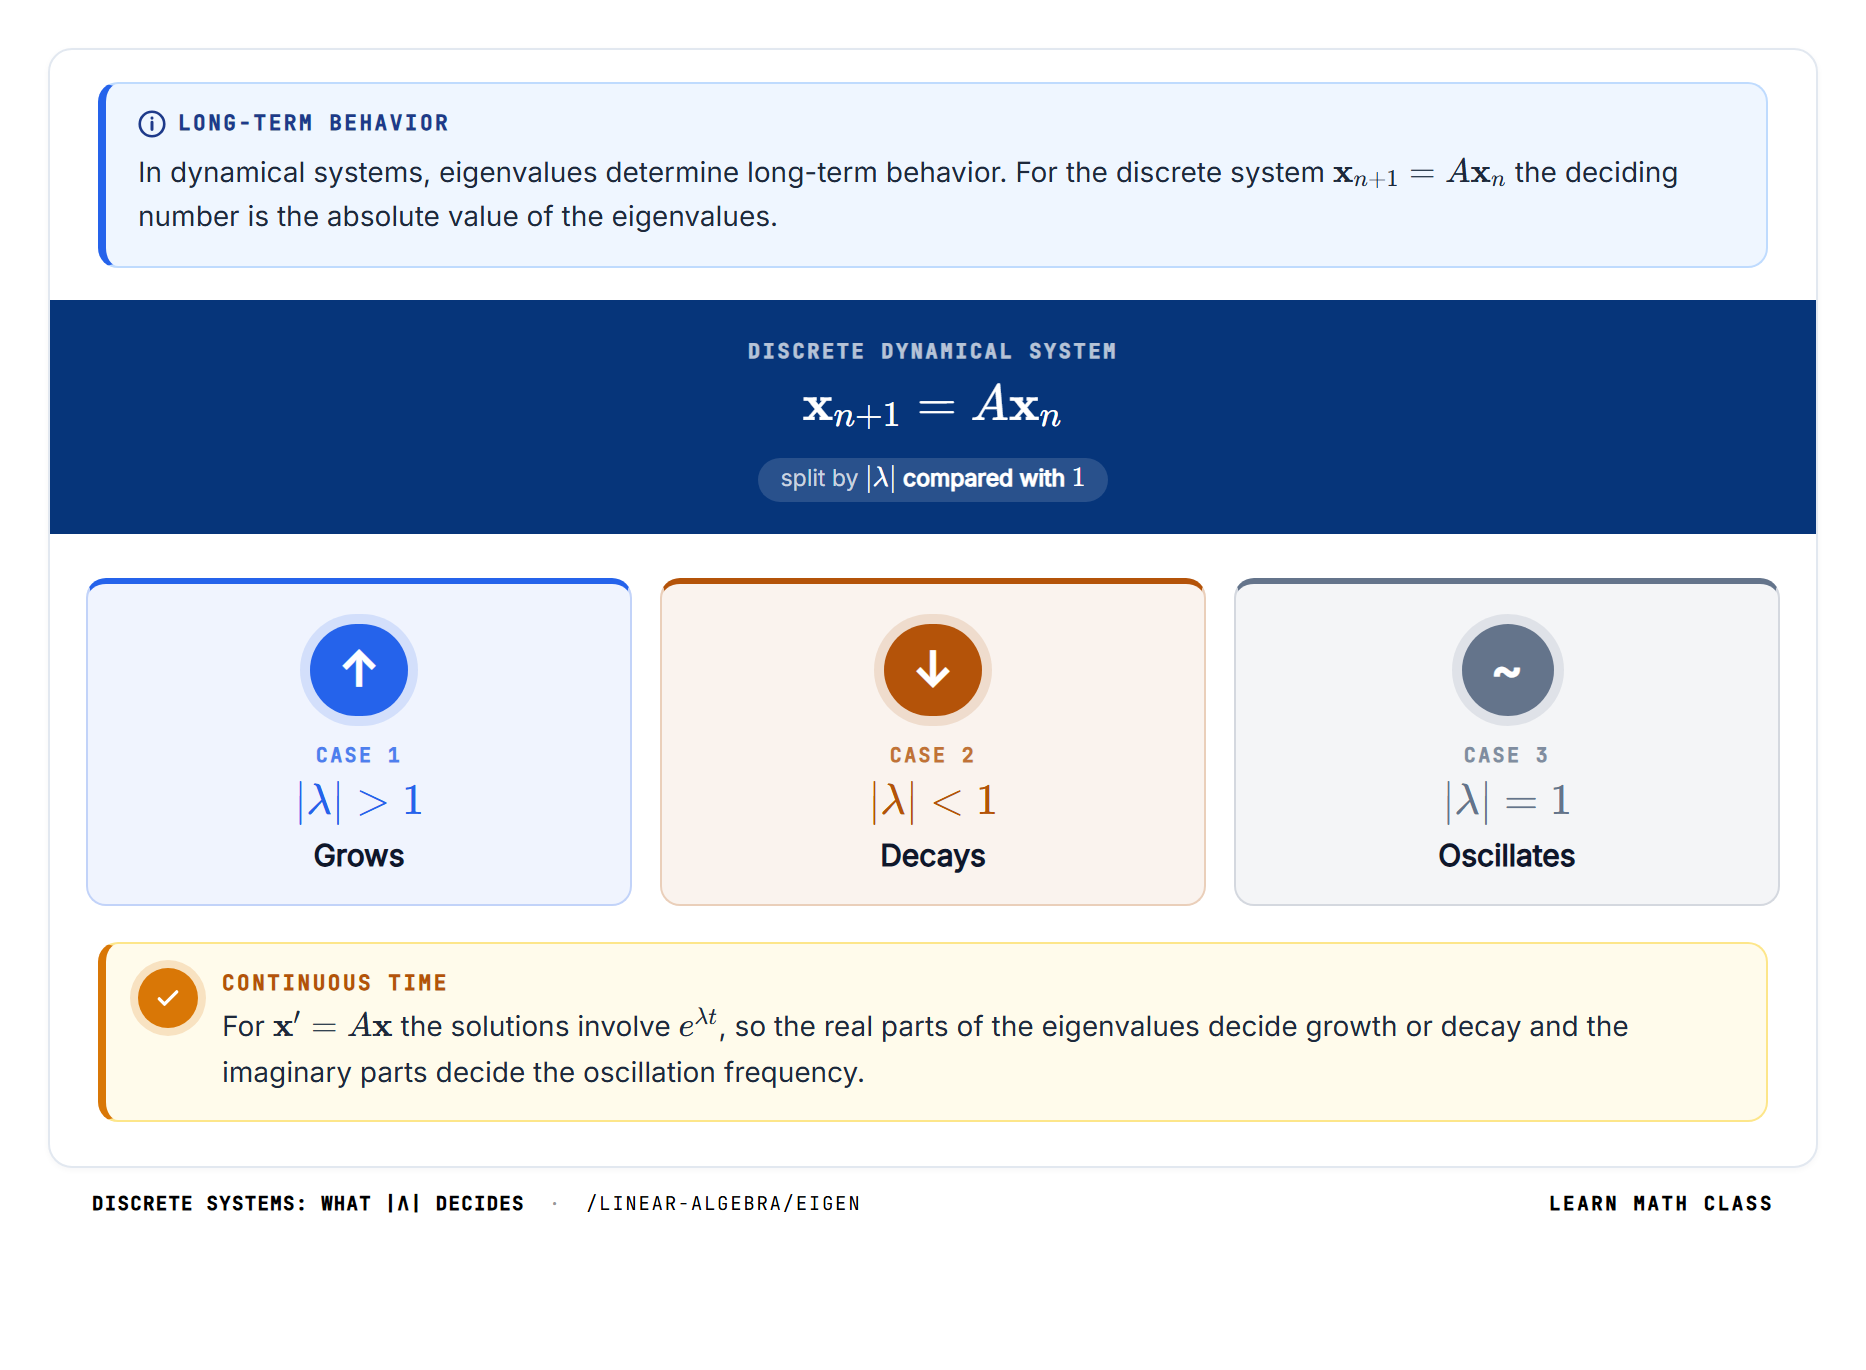
In dynamical systems, eigenvalues determine long-term behavior. The system xn+1=Axn\mathbf{x}_{n+1} = A\mathbf{x}_n grows, decays, or oscillates depending on whether the eigenvalues have absolute value greater than, less than, or equal to 11. The system x′=Ax\mathbf{x}' = A\mathbf{x} has solutions involving eλte^{\lambda t}, so the real parts of the eigenvalues determine exponential growth or decay and the imaginary parts determine oscillation frequency.

In statistics, the eigenvectors of a covariance matrix point in the directions of maximum variance — this is the foundation of principal component analysis. In physics, the eigenvectors of a Hamiltonian or stiffness matrix correspond to natural modes of vibration. In graph theory, eigenvalues of adjacency and Laplacian matrices encode connectivity and clustering structure.

The eigenvalue decomposition is arguably the single most important factorization in applied mathematics. Virtually every iterative algorithm, stability criterion, and spectral method in scientific computing traces back to it.
DownloadPNG2×PDF
Long-term behavior
In dynamical systems, eigenvalues determine long-term behavior. For the discrete system xn+1=Axn\mathbf{x}_{n+1} = A\mathbf{x}_n the deciding number is the absolute value of the eigenvalues.
Discrete dynamical system
xn+1=Axn\mathbf{x}_{n+1} = A\mathbf{x}_n
split by ∣λ∣|\lambda| compared with 11
↑
Case 1
∣λ∣>1|\lambda| > 1
Grows
↓
Case 2
∣λ∣<1|\lambda| < 1
Decays
~
Case 3
∣λ∣=1|\lambda| = 1
Oscillates
Continuous time
For x′=Ax\mathbf{x}' = A\mathbf{x} the solutions involve eλte^{\lambda t}, so the real parts of the eigenvalues decide growth or decay and the imaginary parts decide the oscillation frequency.
Discrete systems: what |λ| decides·/linear-algebra/eigenLearn Math Class
Powers, long-run behavior, principal directions and vibration modes are all read from the eigenvalues and eigenvectors.

Summary: The Eigenvalue Workflow

Finding eigenvalues and eigenvectors is a four-step procedure: a single algebraic equation produces the eigenvalues, and a separate null-space computation produces the eigenvectors for each one. The table below collects the four steps alongside what each one produces and the tool it relies on, summarizing the entire computational pipeline assembled across the sections above.
Step Action Output Tool
1 form the matrix A − λI an n × n matrix with λ subtracted along the diagonal scalar–matrix subtraction
2 set det(A − λI) = 0 a degree-n polynomial in λ — the characteristic equation determinant (cofactor expansion or row reduction)
3 solve the characteristic polynomial the n eigenvalues λ₁, …, λₙ (counted with algebraic multiplicity) polynomial root-finding (factoring, quadratic formula, …)
4 for each λ, solve (A − λI)v = 0 a basis of the eigenspace Eλ; its dimension is the geometric multiplicity row reduction and parametric null-space extraction

Common Pitfalls

Three mistakes account for many wrong answers when eigenvalues and eigenvectors are computed by hand. Each is marked with a box where it happens in the sections above. Here each is worked through in full, with the wrong and the right working side by side, using the matrix A=(4213)A = \begin{pmatrix} 4 & 2 \\ 1 & 3 \end{pmatrix} from the worked example.

Subtracting λ from every entry

The matrix A−λIA - \lambda I is formed by subtracting λ\lambda from every entry of AA, as if λI\lambda I were a matrix filled with λ\lambda. The identity matrix has ones only on the diagonal, so λI\lambda I changes only the diagonal entries.

Wrong working:
det⁡(4−λ2−λ1−λ3−λ)=(λ2−7λ+12)−(λ2−3λ+2)=10−4λ\det\begin{pmatrix} 4 - \lambda & 2 - \lambda \\ 1 - \lambda & 3 - \lambda \end{pmatrix} = (\lambda^2 - 7\lambda + 12) - (\lambda^2 - 3\lambda + 2) = 10 - 4\lambda

The λ2\lambda^2 terms cancel, and the only root is λ=5/2\lambda = 5/2.

Right working: only the diagonal changes.
det⁡(4−λ213−λ)=(4−λ)(3−λ)−2=λ2−7λ+10=(λ−2)(λ−5)\det\begin{pmatrix} 4 - \lambda & 2 \\ 1 & 3 - \lambda \end{pmatrix} = (4 - \lambda)(3 - \lambda) - 2 = \lambda^2 - 7\lambda + 10 = (\lambda - 2)(\lambda - 5)

The eigenvalues are λ1=2\lambda_1 = 2 and λ2=5\lambda_2 = 5.

Why it happens: λ\lambda is a scalar, and subtracting a scalar from a matrix seems to call for touching every entry, the way multiplying a matrix by a scalar does. Writing A−λA - \lambda without the II makes the slip even easier.

How to check: count the degree. The characteristic polynomial of an n×nn \times n matrix has degree nn, so a 2×22 \times 2 matrix must give a quadratic; 10−4λ10 - 4\lambda is linear. The trace check also fails: the eigenvalues must add up to tr(A)=7\text{tr}(A) = 7, and 5/25/2 does not.

Accepting the zero solution

An eigenvalue has been found, A−λIA - \lambda I is row reduced, and every column gets a pivot. The only solution of (A−λI)v=0(A - \lambda I)\mathbf{v} = \mathbf{0} is then v=0\mathbf{v} = \mathbf{0}, and this is written down as the eigenvector, or the eigenspace is reported as {0}\{\mathbf{0}\}.

Wrong working: the characteristic polynomial λ2−7λ+10\lambda^2 - 7\lambda + 10 is factored with the wrong signs as (λ+2)(λ+5)(\lambda + 2)(\lambda + 5), giving λ=−2\lambda = -2. Then
A+2I=(6215)⟶(1001)A + 2I = \begin{pmatrix} 6 & 2 \\ 1 & 5 \end{pmatrix} \longrightarrow \begin{pmatrix} 1 & 0 \\ 0 & 1 \end{pmatrix}

so the only solution is v=0\mathbf{v} = \mathbf{0}, which is reported as the eigenvector.

Right working: a pivot in every column means A+2IA + 2I is invertible (det⁡=30−2=28≠0\det = 30 - 2 = 28 \neq 0), so −2-2 is not an eigenvalue at all. Going back, λ2−7λ+10=(λ−2)(λ−5)\lambda^2 - 7\lambda + 10 = (\lambda - 2)(\lambda - 5). For λ=2\lambda = 2:
A−2I=(2211)⟶(1100)A - 2I = \begin{pmatrix} 2 & 2 \\ 1 & 1 \end{pmatrix} \longrightarrow \begin{pmatrix} 1 & 1 \\ 0 & 0 \end{pmatrix}

The free variable v2=tv_2 = t gives v1=−tv_1 = -t, so v1=(−1,1)T\mathbf{v}_1 = (-1, 1)^T, and indeed Av1=(−2,2)T=2v1A\mathbf{v}_1 = (-2, 2)^T = 2\mathbf{v}_1.

Why it happens: row reduction always ends in some answer, and v=0\mathbf{v} = \mathbf{0} really does satisfy the equation, so the computation looks finished. The zero vector is excluded from the definition precisely because it solves (A−λI)v=0(A - \lambda I)\mathbf{v} = \mathbf{0} for every λ\lambda.

How to check: at a true eigenvalue, det⁡(A−λI)=0\det(A - \lambda I) = 0 and the reduced matrix has at least one zero row. If the reduction leaves no free variable, the error is upstream, in the eigenvalue.

Reading eigenvalues off the diagonal

The shortcut for diagonal and triangular matrices, where the eigenvalues are the diagonal entries, is applied to a matrix that has nonzero entries both above and below the diagonal.

Wrong working: the diagonal of AA holds 44 and 33, so the eigenvalues are taken to be 44 and 33.

Right working: the characteristic polynomial is det⁡(A−λI)=(4−λ)(3−λ)−2=λ2−7λ+10=(λ−2)(λ−5)\det(A - \lambda I) = (4 - \lambda)(3 - \lambda) - 2 = \lambda^2 - 7\lambda + 10 = (\lambda - 2)(\lambda - 5), so the eigenvalues are 22 and 55. Neither diagonal entry is an eigenvalue:
det⁡(A−4I)=det⁡(021−1)=−2,det⁡(A−3I)=det⁡(1210)=−2\det(A - 4I) = \det\begin{pmatrix} 0 & 2 \\ 1 & -1 \end{pmatrix} = -2, \qquad \det(A - 3I) = \det\begin{pmatrix} 1 & 2 \\ 1 & 0 \end{pmatrix} = -2


Why it happens: diagonal and triangular matrices are the first examples met, and for them the rule is exact. The diagonal also has the right sum, 4+3=7=2+54 + 3 = 7 = 2 + 5, so a quick trace check does not catch the error.

How to check: use the product instead of the sum. The eigenvalues must multiply to det⁡(A)=12−2=10\det(A) = 12 - 2 = 10, and 2⋅5=102 \cdot 5 = 10, while 4⋅3=124 \cdot 3 = 12. Or substitute a candidate into det⁡(A−λI)\det(A - \lambda I): a true eigenvalue gives 00.