Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Systems of Linear Equations


Solving Ax = b

A linear system is a collection of linear equations in several unknowns. Writing it in matrix form as Ax = b transforms the problem into a question about matrices: is b in the column space of A, and if so, what are the weights? Row reduction answers both questions systematically, and the rank of the coefficient matrix determines whether the solution exists, whether it is unique, and what the solution set looks like.

For step-by-step results on your own numbers, use the system of equations calculator on CalculateMatrix.


What a Linear System Is

Two coffees and a muffin cost 7 dollars; one coffee and three muffins cost 11 dollars. What does each one cost?
With xx the price of a coffee and yy the price of a muffin, the two sentences say 2x+y=72x + y = 7 and x+3y=11x + 3y = 11. Each sentence alone allows many prices; only together do they pin the answer down.
Each condition on its own has many answers; only one pair of prices satisfies both.
coffee xmuffin y2x + y = 7?x + 3y = 11?
31yesno — 6
15yesno — 16
52no — 12yes
23yesyes
A coffee costs 22 and a muffin 33: 2⋅2+3=72 \cdot 2 + 3 = 7 and 2+3⋅3=112 + 3 \cdot 3 = 11.
The lines 2x + y = 7 and x + 3y = 11 cross at the single point (2, 3)xy1234512345672x + y = 7x + 3y = 11(2, 3): both holdEach equation is a line; the solution is the point on both
Each condition multiplies the unknowns by fixed numbers and adds them — and the answer has to satisfy all of them at once.
"Linear" means no products of unknowns, no powers higher than 11, and no transcendental functions of unknowns. The expression 3x1−2x2+x3=73x_1 - 2x_2 + x_3 = 7 is linear; the expression x1x2+x32=1x_1 x_2 + x_3^2 = 1 is not.
Drawn in the plane, each such equation in two unknowns is a straight line, and a solution is a point lying on every line.
The definition
A system of linear equations is a collection of linear equations in the same unknowns, all to be satisfied at the same time.
A linear system is a set of mm equations in nn unknowns where each equation is a linear combination of the unknowns equal to a constant:
What a Linear System Is
a11x1+a12x2+⋯+a1nxn=b1a_{11}x_1 + a_{12}x_2 + \cdots + a_{1n}x_n = b_1
What a Linear System Is
a21x1+a22x2+⋯+a2nxn=b2a_{21}x_1 + a_{22}x_2 + \cdots + a_{2n}x_n = b_2
What a Linear System Is
⋮\vdots
What a Linear System Is
am1x1+am2x2+⋯+amnxn=bma_{m1}x_1 + a_{m2}x_2 + \cdots + a_{mn}x_n = b_m
So 2x+y=72x + y = 7, x+3y=11x + 3y = 11 is a linear system of two equations in two unknowns, with the solution x=2x = 2, y=3y = 3.
What matters about a system is its solution set: every assignment that satisfies all the equations together.
A solution is an assignment of values to x1,…,xnx_1, \dots, x_n that satisfies every equation simultaneously. The solution set is the collection of all solutions. The central question is: what does this set look like?
A system need not have exactly one solution: it can have none, or infinitely many.
The lines 2x+y=72x + y = 7 and 2x+y=52x + y = 5 are parallel and never meet, so that system has no solution; two equations describing the same line share every point on it. These are the only possibilities, as the three possible outcomes explains.
The rest of the page covers matrix form, the augmented matrix, the three possible outcomes, the geometric picture, row operations and echelon forms, homogeneous systems, existence and uniqueness, and other solution methods.

Writing a System in Matrix Form

The entire system can be compressed into a single matrix equation:

Linear System Matrix Form
Ax=bA\mathbf{x} = \mathbf{b}
Learn more about this formula: Linear System Matrix Form →


where AA is the m×nm \times n coefficient matrix with entry aija_{ij} in row ii, column jj; x=(x1,x2,…,xn)T\mathbf{x} = (x_1, x_2, \dots, x_n)^T is the unknown vector; and b=(b1,b2,…,bm)T\mathbf{b} = (b_1, b_2, \dots, b_m)^T is the right-hand side.

Each row of AA corresponds to one equation. Each column corresponds to one unknown. The matrix-vector product AxA\mathbf{x} is a linear combination of the columns of AA weighted by the entries of x\mathbf{x}:

Matrix-Vector Product (Column Form)
Ax=x1a1+x2a2+⋯+xnanA\mathbf{x} = x_1 \mathbf{a}_1 + x_2 \mathbf{a}_2 + \cdots + x_n \mathbf{a}_n
Learn more about this formula: Matrix-Vector Product (Column Form) →


Asking whether Ax=bA\mathbf{x} = \mathbf{b} has a solution is therefore equivalent to asking whether b\mathbf{b} lies in the column space of AA — whether b\mathbf{b} can be assembled from the columns using some choice of weights.
-4-22468-22468col 1col 2-4-22468-22468row 1row 2
The same product read down the columns, then across the rows

The upper plane builds each column of the product as a combination of the columns on the left; the lower one builds each row as a combination of the rows on the right. Both walks end on the same matrix, which is why the sentence above can describe a row as an equation and a column as an unknown without contradiction — they are two readings of one product, not two products. Step through either reading on the rows and columns visualizer.

The rest of this page works in the row reading, because elimination acts on equations; the column reading returns whenever the question is about span.

The Augmented Matrix

The augmented matrix packages the coefficient matrix and the right-hand side into a single object:

Augmented Matrix Construction
[A∣b]=(a11a12⋯a1nb1a21a22⋯a2nb2⋮⋮⋱⋮⋮am1am2⋯amnbm)[A \mid \mathbf{b}] = \left(\begin{array}{cccc|c} a_{11} & a_{12} & \cdots & a_{1n} & b_1 \\ a_{21} & a_{22} & \cdots & a_{2n} & b_2 \\ \vdots & \vdots & \ddots & \vdots & \vdots \\ a_{m1} & a_{m2} & \cdots & a_{mn} & b_m \end{array}\right)
Learn more about this formula: Augmented Matrix Construction →


The vertical bar separates the coefficients from the constants but is purely notational — the augmented matrix is an m×(n+1)m \times (n+1) matrix on which row operations are performed. Every row operation on [A∣b][A \mid \mathbf{b}] corresponds to a legal algebraic manipulation of the equations: swapping two equations, multiplying an equation by a nonzero scalar, or adding a multiple of one equation to another. None of these changes the solution set.

The augmented matrix is the object that Gaussian elimination operates on, and comparing its rank to the rank of AA alone determines whether the system is consistent.
021424191138
[A | b] before any row operation

The coefficient matrix on the left of the bar, the right-hand side b on the right: one row per equation, one column per unknown, and the constants carried along as a final column. Every row operation acts on the whole row, bar included, which is why the right-hand side stays correct as the left side is reduced. Start the reduction from here on the Gaussian elimination calculator.

The bar is only bookkeeping: [A | b] is the whole system with the variable names left out.

The Three Possible Outcomes

A linear system Ax=bA\mathbf{x} = \mathbf{b} has exactly one of three outcomes.

No solution: the system is inconsistent. The equations impose contradictory constraints — there is no x\mathbf{x} that satisfies all of them. In the augmented matrix, this manifests as a row of the form [0  0  ⋯  0∣d][0 \; 0 \; \cdots \; 0 \mid d] with d≠0d \neq 0, representing the impossible equation 0=d0 = d.

Exactly one solution: the system is consistent and determined. There is a unique x\mathbf{x} satisfying all equations. This requires the coefficient matrix to have rank equal to nn (the number of unknowns), leaving no free variables.

Infinitely many solutions: the system is consistent but underdetermined. The constraints do not pin down a single point — the solution set is a line, plane, or higher-dimensional flat parametrized by free variables.

There is no fourth option.

THEOREM
A linear system never has exactly two solutions, or ten, or any finite number greater than one.

The proof is simple: if x1\mathbf{x}_1 and x2\mathbf{x}_2 are both solutions with x1≠x2\mathbf{x}_1 \neq \mathbf{x}_2, then x1+t(x2−x1)\mathbf{x}_1 + t(\mathbf{x}_2 - \mathbf{x}_1) is a solution for every t∈Rt \in \mathbb{R}, producing infinitely many.

Pitfall: Treating a zero row as a contradiction
Reading the zero row of (123000)\left(\begin{array}{cc|c} 1 & 2 & 3 \\ 0 & 0 & 0 \end{array}\right) as a sign of inconsistency gives no solution. The row says 0=00 = 0, true for every x\mathbf{x}; with yy free, x=3−2yx = 3 - 2y, and there are infinitely many solutions.

In practice the outcome is read from the augmented matrix after row reduction, working up from the bottom row. Rows whose coefficients have all been eliminated often appear there, because one equation of the system was a combination of the others or contradicted them. The table below collects what each outcome looks like in the reduced matrix.
Outcome How it appears in the reduced augmented matrix Rank condition
No solution (inconsistent) a row of the form [0 0 ⋯ 0 | d] with d ≠ 0 — the impossible equation 0 = d rank(A) < rank([A | b])
Exactly one solution every column of A has a pivot; no free variables; every xi is determined rank(A) = rank([A | b]) = n
Infinitely many solutions at least one column of A has no pivot; the corresponding variable is free rank(A) = rank([A | b]) < n
A | b3×410050103001−2→x3×153−2A | b3×31120−2−2001A | b2×412040011→p3×1401+t₁v₁3×1−210
Unique, none, infinitely many

Three finished eliminations, three different endings: a pivot in every column and one answer; a contradiction row and no answer; a free column and a whole family of answers. There is no fourth ending available to a linear system, and which one you get is settled by the pivots rather than by the arithmetic. Build systems that land in each case on the linear system solutions visualizer.

Everything else on this page is machinery for finding out which of these three you are in.

Geometric Interpretation

Each equation in a linear system defines a hyperplane in Rn\mathbb{R}^n. The solution set is the intersection of all mm hyperplanes.

Fact: A ten-thousandth moves the answer to (1,1)(1, 1)
The lines x+y=2x + y = 2 and x+1.0001y=2x + 1.0001y = 2 meet at (2,0)(2, 0). Change the second right-hand side to 2.00012.0001 and they meet at (1,1)(1, 1): the lines differ in direction by less than 0.003∘0.003^\circ, so a tiny shift of one slides the crossing point far along the other.

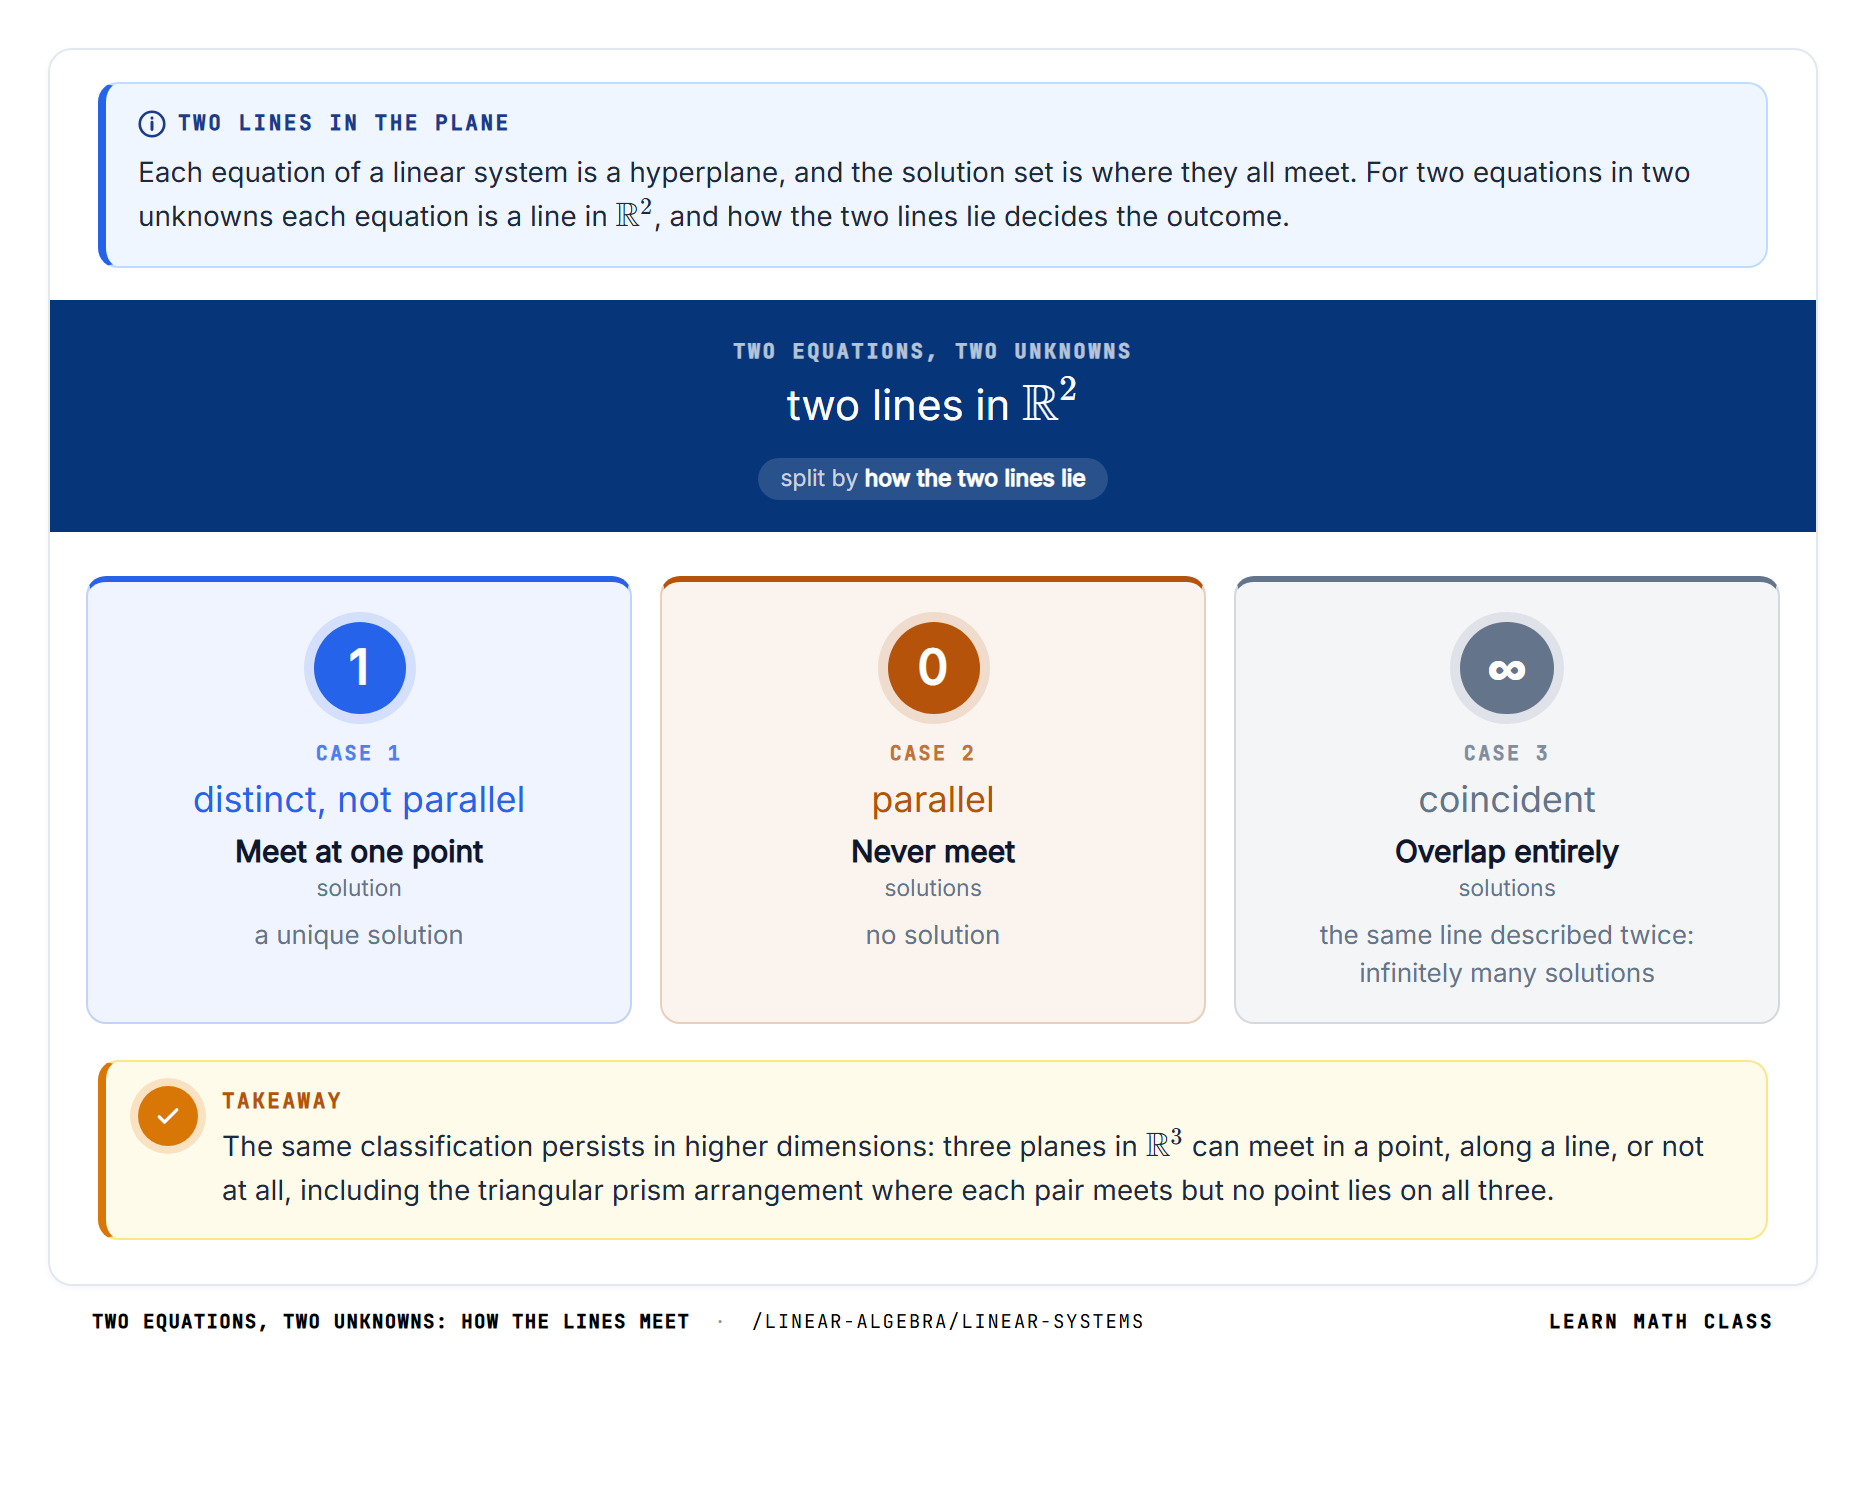
For two equations in two unknowns, each equation is a line in R2\mathbb{R}^2. Two distinct non-parallel lines meet at exactly one point — a unique solution. Parallel lines never meet — no solution. Coincident lines (the same line described twice) overlap entirely — infinitely many solutions.

For three equations in three unknowns, each equation is a plane in R3\mathbb{R}^3. Three planes can intersect in a point, along a line, or not at all. They can also coincide or be arranged so that each pair intersects but no point lies on all three — a triangular prism configuration that yields no solution.

In higher dimensions the geometry is harder to visualize but the classification persists. The rank of the coefficient matrix counts how many hyperplanes cut independently — each independent equation reduces the dimension of the intersection by one.

THEOREM
If the rank is rr and the system is consistent, the solution set has dimension n−rn - r.
DownloadPNG2×PDF
Two lines in the plane
Each equation of a linear system is a hyperplane, and the solution set is where they all meet. For two equations in two unknowns each equation is a line in R2\mathbb{R}^2, and how the two lines lie decides the outcome.
Two equations, two unknowns
two lines in R2\mathbb{R}^2
split by how the two lines lie
1
Case 1
distinct, not parallel
Meet at one point
solution
a unique solution
0
Case 2
parallel
Never meet
solutions
no solution
∞
Case 3
coincident
Overlap entirely
solutions
the same line described twice: infinitely many solutions
Takeaway
The same classification persists in higher dimensions: three planes in R3\mathbb{R}^3 can meet in a point, along a line, or not at all, including the triangular prism arrangement where each pair meets but no point lies on all three.
Two equations, two unknowns: how the lines meet·/linear-algebra/linear-systemsLearn Math Class

Elementary Row Operations

The three elementary row operations are the legal moves that transform one augmented matrix into another without altering the solution set.

Swapping two rows (Ri↔RjR_i \leftrightarrow R_j) reorders the equations. Multiplying a row by a nonzero scalar (kRi→RikR_i \to R_i) rescales an equation. Adding a multiple of one row to another (Ri+cRj→RiR_i + cR_j \to R_i) replaces one equation with a combination of two equations.

THEOREM
Each operation is reversible: a swap undoes itself, scaling by kk is reversed by scaling by 1/k1/k, and adding cc times row jj to row ii is reversed by subtracting cc times row jj from row ii. Reversibility guarantees that the solution set is unchanged — no solutions are created or destroyed.

Pitfall: Leaving the right-hand side unchanged
Applying R2−2R1→R2R_2 - 2R_1 \to R_2 to the coefficients only turns (113214)\left(\begin{array}{cc|c} 1 & 1 & 3 \\ 2 & 1 & 4 \end{array}\right) into a second row (0,−1∣4)(0, -1 \mid 4), giving y=−4y = -4, x=7x = 7. On the full row it is (0,−1∣−2)(0, -1 \mid -2), so y=2y = 2 and x=1x = 1.

Each row operation corresponds to left-multiplication by an elementary matrix. This algebraic interpretation connects the row-reduction algorithm to the theory of matrix factorization and invertibility. The full systematic application of row operations is Gaussian elimination.

Row Echelon Form and Reduced Row Echelon Form

Row operations aim to reduce the augmented matrix to a standard shape from which the solution can be read.

Row echelon form (REF) has a staircase pattern: the leading entry of each row is to the right of the leading entry of the row above, and all entries below each leading entry are zero. In REF, the solution is obtained by back substitution — solving from the bottom row upward.

Reduced row echelon form (RREF) goes further: each leading entry is 11 and is the only nonzero entry in its column. In RREF, the solution is visible by inspection — each pivot variable is already isolated.

THEOREM
The RREF of any matrix is unique. Different sequences of row operations always arrive at the same RREF.

This uniqueness makes the pivot positions intrinsic to the matrix: the rank, the free variables, and the solvability verdict all follow from the pivot structure. The full treatment of both forms, including how to read solutions from each, is on the echelon form page.
120.504.50010.5020011.831001.420101.080011.83
Row echelon form, then reduced

The upper form has zeros below every pivot and is enough to back-substitute from. The lower one goes further, clearing above the pivots and scaling them to one, so the solution can simply be read off. The extra work buys legibility, not correctness. Run both passes on a system of your own on the Gaussian elimination visualizer.

Reduced form is unique to the matrix, while the echelon form reached along the way depends on the route taken.

Homogeneous Systems

The special case Ax=0A\mathbf{x} = \mathbf{0} — where every right-hand side entry is zero — is called a homogeneous system. It is always consistent, since x=0\mathbf{x} = \mathbf{0} satisfies every equation. The question is whether nontrivial solutions exist.

Nontrivial solutions exist if and only if the rank of AA is less than nn. If the system has more unknowns than equations (n>mn > m), nontrivial solutions are guaranteed — the rank cannot exceed mm, which is less than nn.

THEOREM
The solution set of a homogeneous system is the null space of AA: a subspace of Rn\mathbb{R}^n with dimension n−rank(A)n - \text{rank}(A).

The superposition principle holds — any linear combination of solutions is again a solution — which is why the solution set has the clean structure of a vector space rather than an arbitrary collection of points.

Pitfall: Adding solutions of a non-homogeneous system
Adding two solutions of x+y=2x + y = 2, such as (2,0)(2, 0) and (0,2)(0, 2), gives (2,2)(2, 2), where x+y=4x + y = 4; in general A(x1+x2)=2bA(\mathbf{x}_1 + \mathbf{x}_2) = 2\mathbf{b}. Superposition holds only when b=0\mathbf{b} = \mathbf{0}; here the difference (2,−2)(2, -2) solves x+y=0x + y = 0.

A system with a nonzero right-hand side, Ax=bA\mathbf{x} = \mathbf{b}, is tied to the homogeneous system Ax=0A\mathbf{x} = \mathbf{0} with the same coefficient matrix. When it is consistent, its solution set is one particular solution plus every solution of the homogeneous system: the null space moved away from the origin. It is a point, line, plane or higher flat that does not pass through the origin, so it is not a subspace.

When Does a Solution Exist? When Is It Unique?

The rank of AA determines both existence and uniqueness of solutions to Ax=bA\mathbf{x} = \mathbf{b}.

Existence: a solution exists if and only if rank(A)=rank([A∣b])\text{rank}(A) = \text{rank}([A \mid \mathbf{b}]). This means b\mathbf{b} lies in the column space of AA — appending it as an extra column does not introduce a new independent direction.

Uniqueness: if a solution exists, it is unique if and only if rank(A)=n\text{rank}(A) = n. Full column rank means no free variables and a trivial null space, so the particular solution stands alone with no homogeneous component to add freedom.

When AA is square (m=nm = n) and det⁡(A)≠0\det(A) \neq 0, both conditions hold for every b\mathbf{b}: the system always has a unique solution, given by x=A−1b\mathbf{x} = A^{-1}\mathbf{b}. When AA is rectangular or singular, the analysis requires comparing ranks and identifying free variables. The full treatment, including overdetermined and underdetermined systems, is on the solvability page.

Pitfall: Reading a zero determinant as no solution
Concluding no solution from det⁡(A)=0\det(A) = 0 fails for x+y=2x + y = 2, 2x+2y=42x + 2y = 4. The determinant is 1⋅2−1⋅2=01 \cdot 2 - 1 \cdot 2 = 0, yet the second equation is twice the first, so every point (t,2−t)(t, 2 - t) is a solution.

For a singular square matrix the outcome depends on b\mathbf{b} as well as on AA. The same coefficient matrix can give a consistent system for one right-hand side and an inconsistent one for another, and the existence condition above, the comparison of rank(A)\text{rank}(A) with rank([A∣b])\text{rank}([A \mid \mathbf{b}]), is what separates the two.
Whether a solution exists depends on b\mathbf{b} and the column space; whether it is unique depends on AA alone.

Solution Methods Beyond Row Reduction

Gaussian elimination is the most general and widely used method, but several alternatives exist for special cases.

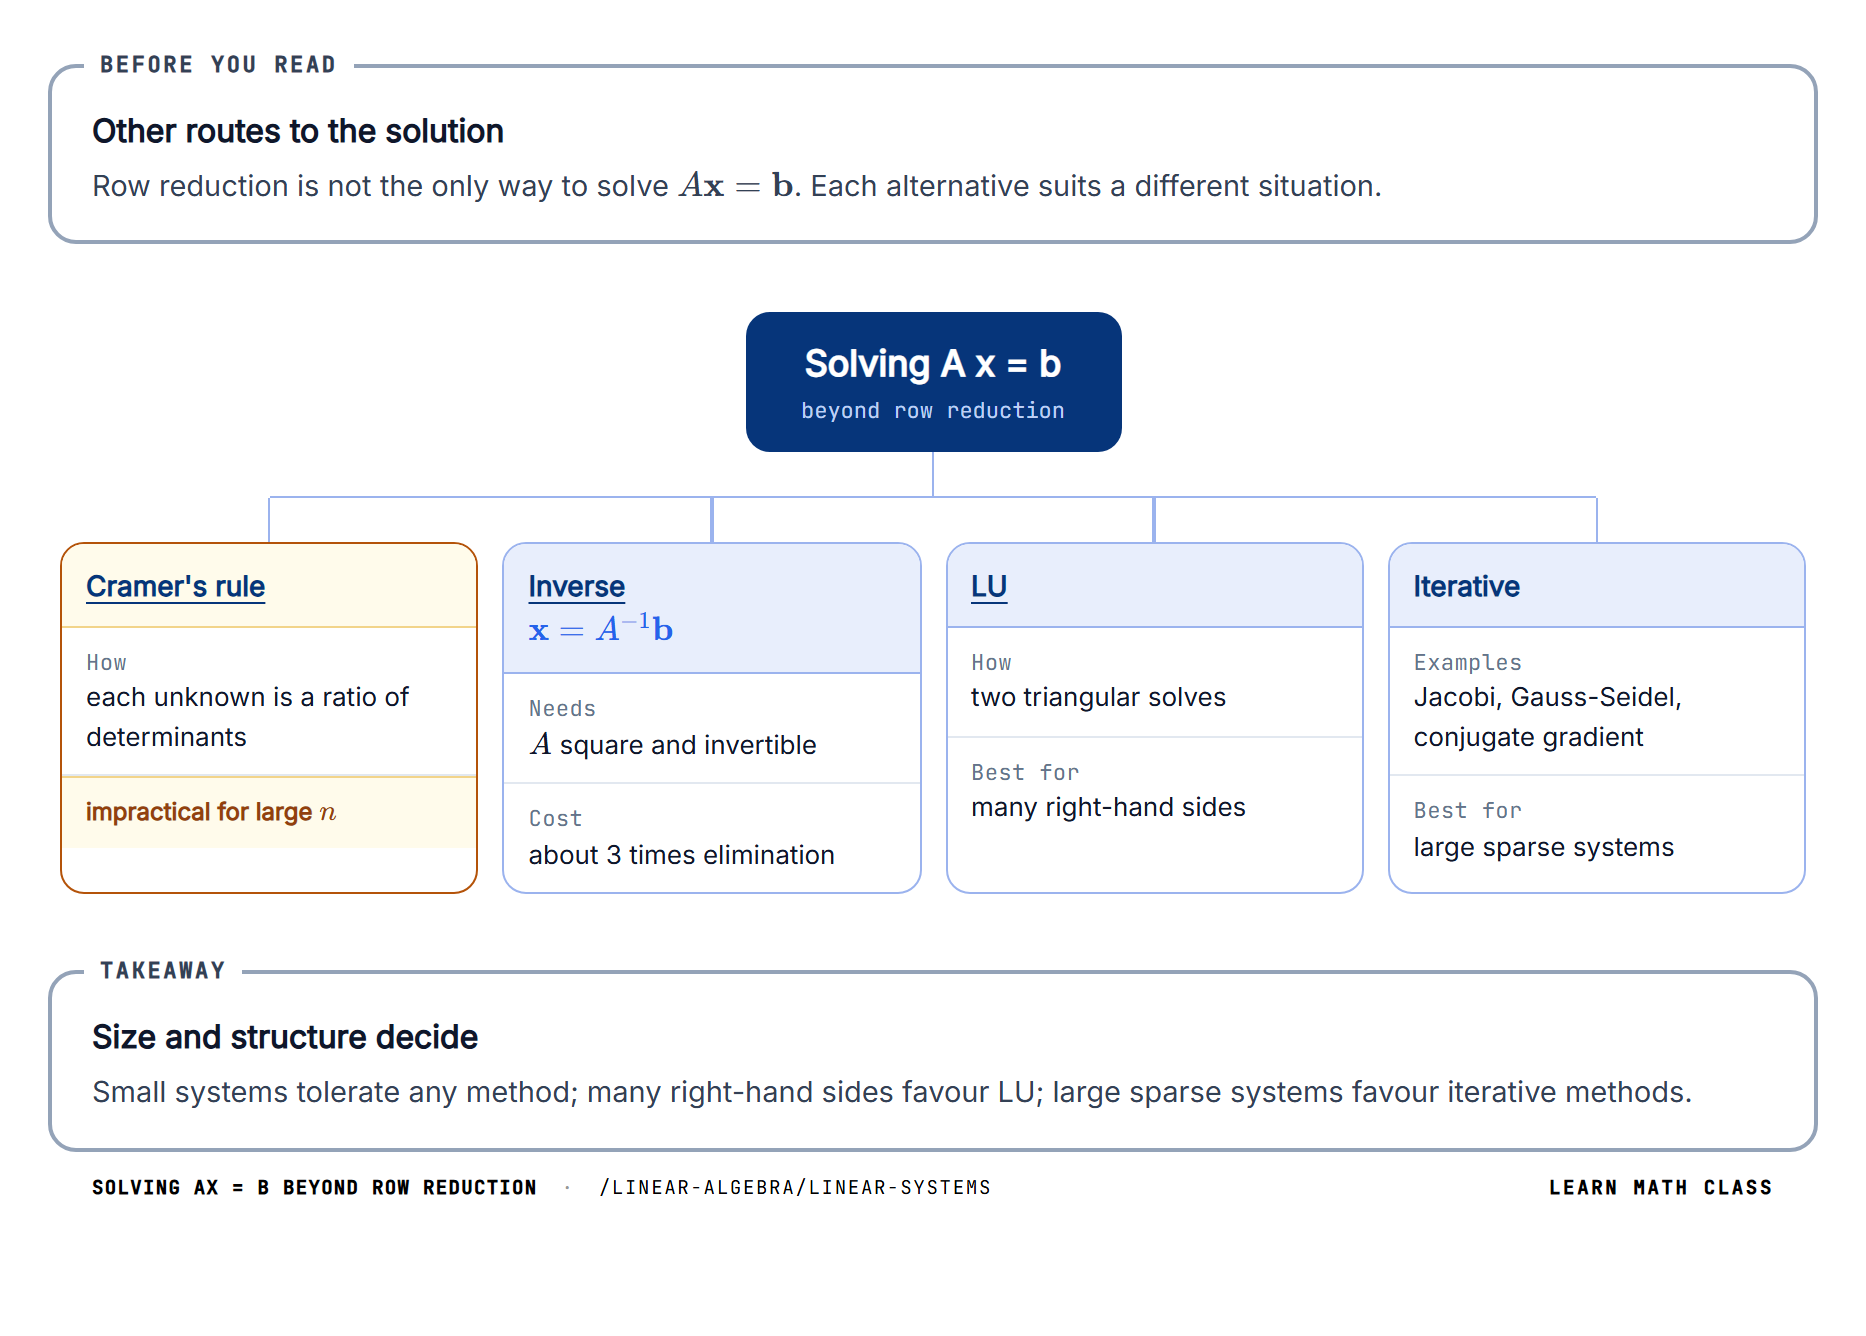
Cramer's rule solves an n×nn \times n system by expressing each unknown as a ratio of determinants. It gives a closed-form solution but is computationally impractical for large nn.

The inverse formula x=A−1b\mathbf{x} = A^{-1}\mathbf{b} applies when AA is square and invertible. It is elegant but rarely the most efficient approach — computing A−1A^{-1} costs roughly three times as much as solving by elimination.

LU decomposition factors AA into a lower triangular matrix LL and an upper triangular matrix UU. Once the factorization is computed, solving Ax=bA\mathbf{x} = \mathbf{b} reduces to two cheap triangular solves. This is the method of choice when multiple systems share the same coefficient matrix AA but have different right-hand sides.

Iterative methods — Jacobi, Gauss-Seidel, conjugate gradient — generate a sequence of approximations converging to the solution. They are preferred for very large sparse systems where direct methods would require too much memory or time. These methods lie at the boundary between linear algebra and numerical analysis.

To solve a specific system with Gaussian elimination, Gauss-Jordan or Cramer's rule and see each step, use the linear systems calculator.
Method When it applies Cost / notes
Gaussian elimination any system; the most general method ≈ (2/3)n³ operations; the default workhorse
Cramer's rule square n × n with det(A) ≠ 0; small n or symbolic work n + 1 determinant evaluations; impractical for large n
Inverse formula x = A−1b square A with det(A) ≠ 0 computing A−1 costs roughly 3× elimination; rarely the most efficient choice
LU decomposition multiple right-hand sides b sharing the same coefficient matrix A one factorization (cost of elimination) plus cheap triangular solves for each b
Iterative methods (Jacobi, Gauss-Seidel, CG) very large sparse systems where direct methods are too costly produces a sequence of approximations; convergence depends on the matrix structure
DownloadPNG2×PDF
Before you read
Other routes to the solution
Row reduction is not the only way to solve Ax=bA\mathbf{x} = \mathbf{b}. Each alternative suits a different situation.
Solving A x = bbeyond row reduction
Howeach unknown is a ratio of determinants

impractical for large nn

Inversex=A−1b\mathbf{x} = A^{-1}\mathbf{b}
NeedsAA square and invertible
Costabout 3 times elimination
Howtwo triangular solves
Best formany right-hand sides
Iterative
ExamplesJacobi, Gauss-Seidel, conjugate gradient
Best forlarge sparse systems
Takeaway
Size and structure decide
Small systems tolerate any method; many right-hand sides favour LU; large sparse systems favour iterative methods.
Solving Ax = b beyond row reduction·/linear-algebra/linear-systemsLearn Math Class

Summary: Rank Conditions and Solution Sets

The rank of A and its relationship to the rank of the augmented matrix [A | b] settles every question about A·x = b — whether a solution exists, whether it is unique, and what shape the solution set takes. The table below collects each rank pattern alongside the resulting outcome, the structure of the solution set, and the geometric picture, providing a single reference card for the hub.
Rank pattern Outcome Solution set structure Geometric picture
rank(A) < rank([A | b]) inconsistent empty hyperplanes with no common point (e.g., parallel lines in ℝ²)
rank(A) = rank([A | b]) = n consistent and determined a single point in ℝⁿ n independent hyperplanes meet at one point
rank(A) = rank([A | b]) = r < n consistent and underdetermined affine flat: particular solution + null space of A; dimension n − r hyperplanes intersect along a line, plane, or higher flat
rank(A) < n with b = 0 (homogeneous) nontrivial solutions exist null space of A; subspace of dimension n − rank(A) a subspace through the origin

Common Pitfalls

Four mistakes account for many wrong verdicts about linear systems. Each is marked with a box where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.

Treating a zero row as a contradiction

After row reduction, a row whose coefficients are all zero is taken as a sign that the system has no solution, without looking at its last entry. Only a row [0  ⋯  0∣d][0 \; \cdots \; 0 \mid d] with d≠0d \neq 0 is a contradiction; a row [0  ⋯  0∣0][0 \; \cdots \; 0 \mid 0] is the equation 0=00 = 0.

Wrong working: for x+2y=3x + 2y = 3, 2x+4y=62x + 4y = 6, the operation R2−2R1→R2R_2 - 2R_1 \to R_2 gives
(123000)\left(\begin{array}{cc|c} 1 & 2 & 3 \\ 0 & 0 & 0 \end{array}\right)

and the zero row is read as "inconsistent, no solution".

Right working: the second row says 0x+0y=00x + 0y = 0, which every x\mathbf{x} satisfies. Only x+2y=3x + 2y = 3 remains, yy is free, and
(x,y)=(3−2t,  t),t∈R(x, y) = (3 - 2t, \; t), \quad t \in \mathbb{R}

gives infinitely many solutions. Had the second equation been 2x+4y=72x + 4y = 7, the same operation would give the row [0  0∣1][0 \; 0 \mid 1], the impossible 0=10 = 1, and then there would be no solution.

Why it happens: a row of zero coefficients appears both when an equation is redundant and when it contradicts the others, and only the last entry tells the two apart.

How to check: look at the entry to the right of the bar. Or substitute one candidate: t=0t = 0 gives (3,0)(3, 0), and 3+0=33 + 0 = 3, 6+0=66 + 0 = 6 both hold.

Leaving the right-hand side unchanged

A row operation is carried out on the coefficient part of the augmented matrix, and the entry to the right of the bar is copied down unchanged. The new row then stands for an equation the system never implied.

Wrong working: for x+y=3x + y = 3, 2x+y=42x + y = 4, apply R2−2R1→R2R_2 - 2R_1 \to R_2 to the coefficients only:
(113214)→(1130−14)\left(\begin{array}{cc|c} 1 & 1 & 3 \\ 2 & 1 & 4 \end{array}\right) \to \left(\begin{array}{cc|c} 1 & 1 & 3 \\ 0 & -1 & 4 \end{array}\right)

so y=−4y = -4 and x=3−(−4)=7x = 3 - (-4) = 7.

Right working: the operation acts on the whole row, so the last entry becomes 4−2⋅3=−24 - 2 \cdot 3 = -2:
(1130−1−2)\left(\begin{array}{cc|c} 1 & 1 & 3 \\ 0 & -1 & -2 \end{array}\right)

so y=2y = 2 and x=3−2=1x = 3 - 2 = 1.

Why it happens: the bar makes the last column look like a separate object, and much of the work on a system, such as finding the rank of AA, looks at the coefficients alone.

How to check: substitute into the original equations. (1,2)(1, 2) gives 1+2=31 + 2 = 3 and 2+2=42 + 2 = 4. The wrong answer (7,−4)(7, -4) satisfies the first equation but gives 14−4=10≠414 - 4 = 10 \neq 4 in the second.

Adding solutions of a non-homogeneous system

The superposition principle of homogeneous systems is applied to Ax=bA\mathbf{x} = \mathbf{b} with b≠0\mathbf{b} \neq \mathbf{0}: the sum or a multiple of two solutions is taken to be another solution.

Wrong working: (2,0)(2, 0) and (0,2)(0, 2) both solve x+y=2x + y = 2, so their sum (2,2)(2, 2) is taken as a solution. But 2+2=4≠22 + 2 = 4 \neq 2.

Right working: in general
A(x1+x2)=Ax1+Ax2=b+b=2bA(\mathbf{x}_1 + \mathbf{x}_2) = A\mathbf{x}_1 + A\mathbf{x}_2 = \mathbf{b} + \mathbf{b} = 2\mathbf{b}

What does hold is A(x1−x2)=0A(\mathbf{x}_1 - \mathbf{x}_2) = \mathbf{0}: the difference (2,−2)(2, -2) solves x+y=0x + y = 0. The solutions of x+y=2x + y = 2 are one particular solution plus the homogeneous ones:
(x,y)=(2,0)+t(−1,1)=(2−t,  t)(x, y) = (2, 0) + t(-1, 1) = (2 - t, \; t)


Why it happens: superposition is learned for homogeneous systems, and the right-hand side is not checked when it is reused.

How to check: if the solutions of Ax=bA\mathbf{x} = \mathbf{b} could be added and scaled freely, 0⋅x1=00 \cdot \mathbf{x}_1 = \mathbf{0} would be one of them. But A0=0≠bA\mathbf{0} = \mathbf{0} \neq \mathbf{b}.

Reading a zero determinant as no solution

For a square system, det⁡(A)=0\det(A) = 0 is taken to mean that there is no solution. It only means that the solution is not unique for every b\mathbf{b}: depending on b\mathbf{b}, there are no solutions or infinitely many.

Wrong working: for x+y=2x + y = 2, 2x+2y=42x + 2y = 4,
det⁡(1122)=1⋅2−1⋅2=0\det\begin{pmatrix} 1 & 1 \\ 2 & 2 \end{pmatrix} = 1 \cdot 2 - 1 \cdot 2 = 0

so the system is declared to have no solution.

Right working: reduce the augmented matrix.
(112224)→(112000)\left(\begin{array}{cc|c} 1 & 1 & 2 \\ 2 & 2 & 4 \end{array}\right) \to \left(\begin{array}{cc|c} 1 & 1 & 2 \\ 0 & 0 & 0 \end{array}\right)

Here rank(A)=rank([A∣b])=1<2\text{rank}(A) = \text{rank}([A \mid \mathbf{b}]) = 1 < 2, so there are infinitely many solutions, (t,  2−t)(t, \; 2 - t). With the right-hand side (2,5)(2, 5) instead, the last row becomes [0  0∣1][0 \; 0 \mid 1], the ranks are 11 and 22, and then there is no solution.

Why it happens: det⁡(A)≠0\det(A) \neq 0 means exactly one solution for every b\mathbf{b}, and its negation is misread as no solution at all.

How to check: compare rank(A)\text{rank}(A) with rank([A∣b])\text{rank}([A \mid \mathbf{b}]), or simply try to find one solution: (2,0)(2, 0) satisfies both x+y=2x + y = 2 and 2x+2y=42x + 2y = 4.

Systems of Linear Equations FAQ

What makes an equation linear?

+
Each unknown appears only to the first power, multiplied by a fixed number, and the terms are added: no products of unknowns, no powers higher than 11, and no functions such as sin⁡\sin or exe^{x} applied to an unknown. So 3x1−2x2+x3=73x_1 - 2x_2 + x_3 = 7 is linear, while x1x2+x32=1x_1 x_2 + x_3^2 = 1 is not. In two unknowns a linear equation draws a straight line, and a solution of a system is a point lying on every line.Read more →

How is solving Ax=bA\mathbf{x} = \mathbf{b} a question about the columns of AA?

+
Because Ax=x1a1+⋯+xnanA\mathbf{x} = x_1\mathbf{a}_1 + \cdots + x_n\mathbf{a}_n is a combination of the columns, weighted by the unknowns. Solving asks whether b\mathbf{b} can be assembled from the columns, and with which weights. For 2x+y=72x + y = 7, x+3y=11x + 3y = 11, the weights 22 and 33 work: 2(2,1)+3(1,3)=(7,11)2(2, 1) + 3(1, 3) = (7, 11). A solution exists exactly when b\mathbf{b} lies in the column space of AA, which is the condition rank(A)=rank([A∣b])\text{rank}(A) = \text{rank}([A \mid \mathbf{b}]).Read more →

Why can a tiny change to one equation move the solution far away?

+
Because the lines are nearly parallel. x+y=2x + y = 2 and x+1.0001y=2x + 1.0001y = 2 meet at (2,0)(2, 0), but changing the second right-hand side to 2.00012.0001 moves the crossing to (1,1)(1, 1). The two lines differ in direction by less than 0.003∘0.003^\circ, so a tiny shift of one slides the meeting point far along the other. A system like this is close to having no solution or infinitely many, and small errors in its numbers can change the answer completely.Read more →

How are very large linear systems solved?

+
Often by iterative methods such as Jacobi, Gauss-Seidel and conjugate gradient. Instead of eliminating unknowns, they build a sequence of approximations that converges to the solution. They are preferred for very large sparse systems, where most entries are zero and direct methods such as Gaussian elimination, at about 23n3\frac{2}{3}n^3 operations, would need too much memory or time. Whether and how fast they converge depends on the structure of the matrix.Read more →