Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Orthogonality


Perpendicularity and Its Consequences

Orthogonality — the condition that two vectors are perpendicular — is the geometric idea that makes linear algebra computationally clean. Orthogonal bases turn coordinate-finding into dot products. Projections onto subspaces become explicit formulas. Least-squares approximation reduces to a single matrix equation. Every simplification traces back to the same root: when vectors are perpendicular, their interactions vanish and problems decouple.


What Orthogonality Means

Two vectors u\mathbf{u} and v\mathbf{v} in Rn\mathbb{R}^n are orthogonal if their dot product is zero:

What Orthogonality Means
u⋅v=u1v1+u2v2+⋯+unvn=0\mathbf{u} \cdot \mathbf{v} = u_1 v_1 + u_2 v_2 + \cdots + u_n v_n = 0

Geometrically, this means the angle between the two vectors is 90°90°. The vectors are perpendicular — pointing in completely independent directions with no component of one lying along the other.

The zero vector is orthogonal to every vector, since 0⋅v=0\mathbf{0} \cdot \mathbf{v} = 0 for all v\mathbf{v}. This is a convention that keeps the theory clean, not a geometric statement — the zero vector has no direction. Orthogonality is defined relative to an inner product, and on this site the standard dot product is used unless stated otherwise.

Orthogonality in R² and R³

In R2\mathbb{R}^2, the vectors (a,b)(a, b) and (c,d)(c, d) are orthogonal if and only if ac+bd=0ac + bd = 0. The pair (1,2)(1, 2) and (−2,1)(-2, 1) satisfies 1(−2)+2(1)=01(-2) + 2(1) = 0, so these vectors are perpendicular.

RULE
Rotating any vector by 90°90° produces an orthogonal partner: (a,b)(a, b) is orthogonal to (−b,a)(-b, a).

In R3\mathbb{R}^3, the standard basis vectors e1=(1,0,0)\mathbf{e}_1 = (1, 0, 0), e2=(0,1,0)\mathbf{e}_2 = (0, 1, 0), e3=(0,0,1)\mathbf{e}_3 = (0, 0, 1) are mutually orthogonal — every pair has dot product zero. The cross product a×b\mathbf{a} \times \mathbf{b} produces a vector orthogonal to both a\mathbf{a} and b\mathbf{b}, constructing perpendicularity from any two non-parallel inputs.

Fact: No two cube diagonals are perpendicular
The long diagonals of a cube point along (±1,±1,±1)(\pm 1, \pm 1, \pm 1), and the dot product of two such vectors is a sum of three terms ±1\pm 1: an odd number, never 00. A four-dimensional cube does have four mutually perpendicular diagonals, along (1,1,1,1)(1, 1, 1, 1), (1,1,−1,−1)(1, 1, -1, -1), (1,−1,1,−1)(1, -1, 1, -1) and (1,−1,−1,1)(1, -1, -1, 1).

Integer examples are easy to find in R3\mathbb{R}^3 as well. Besides the standard basis, the vectors (1,2,2)(1, 2, 2), (2,1,−2)(2, 1, -2) and (2,−2,1)(2, -2, 1) are mutually orthogonal: the three pairs have dot products 2+2−4=02 + 2 - 4 = 0, 2−4+2=02 - 4 + 2 = 0 and 4−2−2=04 - 2 - 2 = 0, and all three vectors have the same length 33.

Orthogonality is the foundation of coordinate systems. Axes that are perpendicular allow each coordinate to be read independently — changing one coordinate does not affect any other. This independence is what makes orthogonal bases so powerful.

Orthogonal Complements

For a subspace WW of Rn\mathbb{R}^n, the orthogonal complement W⊥W^\perp is the set of all vectors perpendicular to everything in WW:

Orthogonal Complement Definition
W⊥={v∈Rn:v⋅w=0 for all w∈W}W^\perp = \{\mathbf{v} \in \mathbb{R}^n : \mathbf{v} \cdot \mathbf{w} = 0 \text{ for all } \mathbf{w} \in W\}
Learn more about this formula: Orthogonal Complement Definition →


THEOREM
The orthogonal complement is itself a subspace.

Pitfall: Calling any perpendicular subspace the complement
Taking a subspace perpendicular to WW as W⊥W^\perp: in R3\mathbb{R}^3 the yy-axis is perpendicular to the xx-axis WW, but the dimensions give 1+1=2≠31 + 1 = 2 \neq 3. The complement W⊥W^\perp is the whole yzyz-plane, all vectors (0,b,c)(0, b, c).

Its dimension satisfies dim⁡(W)+dim⁡(W⊥)=n\dim(W) + \dim(W^\perp) = n, and taking the complement twice returns to the original: (W⊥)⊥=W(W^\perp)^\perp = W.

The most important structural consequence is the orthogonal decomposition. Every vector v∈Rn\mathbf{v} \in \mathbb{R}^n can be written uniquely as

Orthogonal Complements
v=w+w⊥\mathbf{v} = \mathbf{w} + \mathbf{w}^\perp

Fact: The double complement can outgrow WW
In the space of sequences (x1,x2,…)(x_1, x_2, \ldots) with x12+x22+⋯x_1^2 + x_2^2 + \cdots finite, let WW hold the sequences with only finitely many nonzero entries. Every (0,…,0,1,0,…)(0, \ldots, 0, 1, 0, \ldots) lies in WW, so only 0\mathbf{0} is perpendicular to all of WW: W⊥={0}W^\perp = \{\mathbf{0}\}, and (W⊥)⊥(W^\perp)^\perp is the whole space, which also holds (1,12,13,…)(1, \frac{1}{2}, \frac{1}{3}, \ldots).

where w∈W\mathbf{w} \in W and w⊥∈W⊥\mathbf{w}^\perp \in W^\perp. The two components are perpendicular to each other: w⋅w⊥=0\mathbf{w} \cdot \mathbf{w}^\perp = 0. This decomposition is the geometric heart of projection: w\mathbf{w} is the projection of v\mathbf{v} onto WW, and w⊥\mathbf{w}^\perp is the residual.

Both dimension statements above are proved for Rn\mathbb{R}^n, where every subspace has a finite dimension. Orthogonal complements are defined in exactly the same way in spaces of infinite sequences, with the dot product replaced by the infinite sum x1y1+x2y2+⋯x_1 y_1 + x_2 y_2 + \cdots, and in spaces of functions, where it becomes an integral. There a subspace can have infinitely many independent directions, and the count dim⁡(W)+dim⁡(W⊥)=n\dim(W) + \dim(W^\perp) = n has no number nn to reach.

The Four Fundamental Subspaces Revisited

The orthogonal complement structure appears naturally in the four fundamental subspaces of any m×nm \times n matrix AA.

In Rn\mathbb{R}^n, the row space and the null space are orthogonal complements:

The Four Fundamental Subspaces Revisited
Row(A)⊥=Null(A)\text{Row}(A)^\perp = \text{Null}(A)

Every vector in the null space is perpendicular to every row of AA, because Ax=0A\mathbf{x} = \mathbf{0} means the dot product of x\mathbf{x} with each row is zero.

In Rm\mathbb{R}^m, the column space and the left null space are orthogonal complements:

The Four Fundamental Subspaces Revisited
Col(A)⊥=Null(AT)\text{Col}(A)^\perp = \text{Null}(A^T)

These two pairs of complements are the structural backbone of projection and least squares. Projecting a vector b\mathbf{b} onto the column space means decomposing b\mathbf{b} into a column-space component (the best approximation Ax^A\hat{\mathbf{x}}) and a left-null-space component (the residual b−Ax^\mathbf{b} - A\hat{\mathbf{x}}).
Ambient space Subspace Its orthogonal complement Dimension sum
ℝⁿ (the domain) Row(A) — row space of A Null(A) — null space of A rank(A) + nullity(A) = n
ℝᵐ (the codomain) Col(A) — column space of A Null(Aᵀ) — left null space of A rank(A) + (m − rank(A)) = m
rows of R2×3120001N(A)3×12−10=02×100andC(A)ᵀ2×3123134N(Aᵀ)3×111−1=02×100
Two orthogonal pairings of whole subspaces

Row space against null space, column space against left null space. Every vector in one is orthogonal to every vector in its partner, and each pair fills the space between them, so any vector splits uniquely across the pair. Orthogonality has stopped being a relation between two arrows and become the architecture of the space. Check both pairings on the four fundamental subspaces visualizer.

Projections, Gram-Schmidt and least squares in the sections below are all built on this decomposition.

Why Orthogonality Matters

Orthogonality is the single property that converts hard linear algebra problems into easy ones.

Orthogonal bases make coordinate computation trivial: the coefficient of each basis vector is a single dot product, not the solution of a system. For a general basis, finding coordinates requires solving nn equations; for an orthonormal basis, it requires nn dot products.

Projections onto subspaces have explicit formulas when the basis is orthogonal. The projection of b\mathbf{b} onto a subspace splits into independent projections onto each basis vector, with no cross-talk between components.

Least-squares approximation — the best approximate solution when Ax=bA\mathbf{x} = \mathbf{b} has no exact solution — reduces to projecting b\mathbf{b} onto the column space. The normal equations ATAx^=ATbA^TA\hat{\mathbf{x}} = A^T\mathbf{b} are a direct consequence of the orthogonality condition on the residual.

Orthogonal matrices preserve lengths and angles, making them numerically stable in computation. The Gram-Schmidt process converts any basis into an orthogonal one, ensuring these benefits are always available.

Perpendicular directions do not interfere, so each piece of a problem is solved on its own, with one dot product.

Inner Products

The dot product is the standard way to measure angles and lengths in Rn\mathbb{R}^n, but it is not the only one. An inner product is any function ⟨⋅,⋅⟩\langle \cdot, \cdot \rangle that satisfies symmetry, linearity, and positive definiteness. Different inner products define different notions of perpendicularity and distance.

A weighted inner product ⟨u,v⟩=uTWv\langle \mathbf{u}, \mathbf{v} \rangle = \mathbf{u}^T W \mathbf{v} (with WW symmetric positive definite) distorts the geometry — circles become ellipses, and "perpendicular" means something different than in the standard dot product. On function spaces, the integral ⟨f,g⟩=∫abf(x)g(x) dx\langle f, g \rangle = \int_a^b f(x)g(x)\,dx defines orthogonality for functions, leading to Fourier series and orthogonal polynomials.

THEOREM
Every inner product induces a norm (∥v∥=⟨v,v⟩\|\mathbf{v}\| = \sqrt{\langle \mathbf{v}, \mathbf{v} \rangle}), a distance (d(u,v)=∥u−v∥d(\mathbf{u}, \mathbf{v}) = \|\mathbf{u} - \mathbf{v}\|), and the Cauchy-Schwarz inequality (∣⟨u,v⟩∣≤∥u∥∥v∥|\langle \mathbf{u}, \mathbf{v} \rangle| \leq \|\mathbf{u}\|\|\mathbf{v}\|).

The entire orthogonality framework — projections, Gram-Schmidt, least squares — works in any inner product space.
Inner product Definition Setting What it enables
Standard dot product u · v = Σ ui vi ℝⁿ with Euclidean geometry standard lengths, angles, and perpendicularity
Weighted inner product ⟨u, v⟩ = uᵀ W v (W symmetric positive definite) ℝⁿ with distorted metric ellipsoidal geometry; statistics (e.g. Mahalanobis distance)
Function-space integral ⟨f, g⟩ = ∫ab f(x) g(x) dx spaces of square-integrable functions Fourier series, orthogonal polynomials, signal decomposition

Orthogonal and Orthonormal Sets

An orthogonal set is a collection of vectors that are pairwise perpendicular: vi⋅vj=0\mathbf{v}_i \cdot \mathbf{v}_j = 0 whenever i≠ji \neq j. An orthonormal set adds the requirement that each vector has unit length: ∥vi∥=1\|\mathbf{v}_i\| = 1.

THEOREM
Orthogonal sets of nonzero vectors are automatically linearly independent — no independence check is needed.

The proof is one line: if ∑civi=0\sum c_i \mathbf{v}_i = \mathbf{0}, dotting both sides with vj\mathbf{v}_j gives cj∥vj∥2=0c_j \|\mathbf{v}_j\|^2 = 0, forcing cj=0c_j = 0.

The computational advantage of an orthonormal basis {q1,…,qn}\{\mathbf{q}_1, \dots, \mathbf{q}_n\} is that coordinates are free: ci=qi⋅vc_i = \mathbf{q}_i \cdot \mathbf{v}. No system of equations, no row reduction, no matrix inversion — just nn dot products.

Pitfall: Treating an orthogonal basis as orthonormal
Using ci=vi⋅vc_i = \mathbf{v}_i \cdot \mathbf{v} with a basis that is orthogonal but not unit length: for (1,1)(1, 1), (1,−1)(1, -1) and v=(3,1)\mathbf{v} = (3, 1) it gives c1=4c_1 = 4, c2=2c_2 = 2, and 4(1,1)+2(1,−1)=(6,2)≠v4(1, 1) + 2(1, -1) = (6, 2) \neq \mathbf{v}. Dividing by vi⋅vi=2\mathbf{v}_i \cdot \mathbf{v}_i = 2 gives c1=2c_1 = 2, c2=1c_2 = 1.

The formula relies on both halves of orthonormality. When v=∑cjqj\mathbf{v} = \sum c_j \mathbf{q}_j is dotted with qi\mathbf{q}_i, pairwise perpendicularity removes every term except ci qi⋅qic_i\,\mathbf{q}_i \cdot \mathbf{q}_i, and unit length makes that term cic_i itself. Bases met in practice are often orthogonal without being normalized, such as (1,1)(1, 1) and (1,−1)(1, -1) in R2\mathbb{R}^2.
DownloadPNG2×PDF
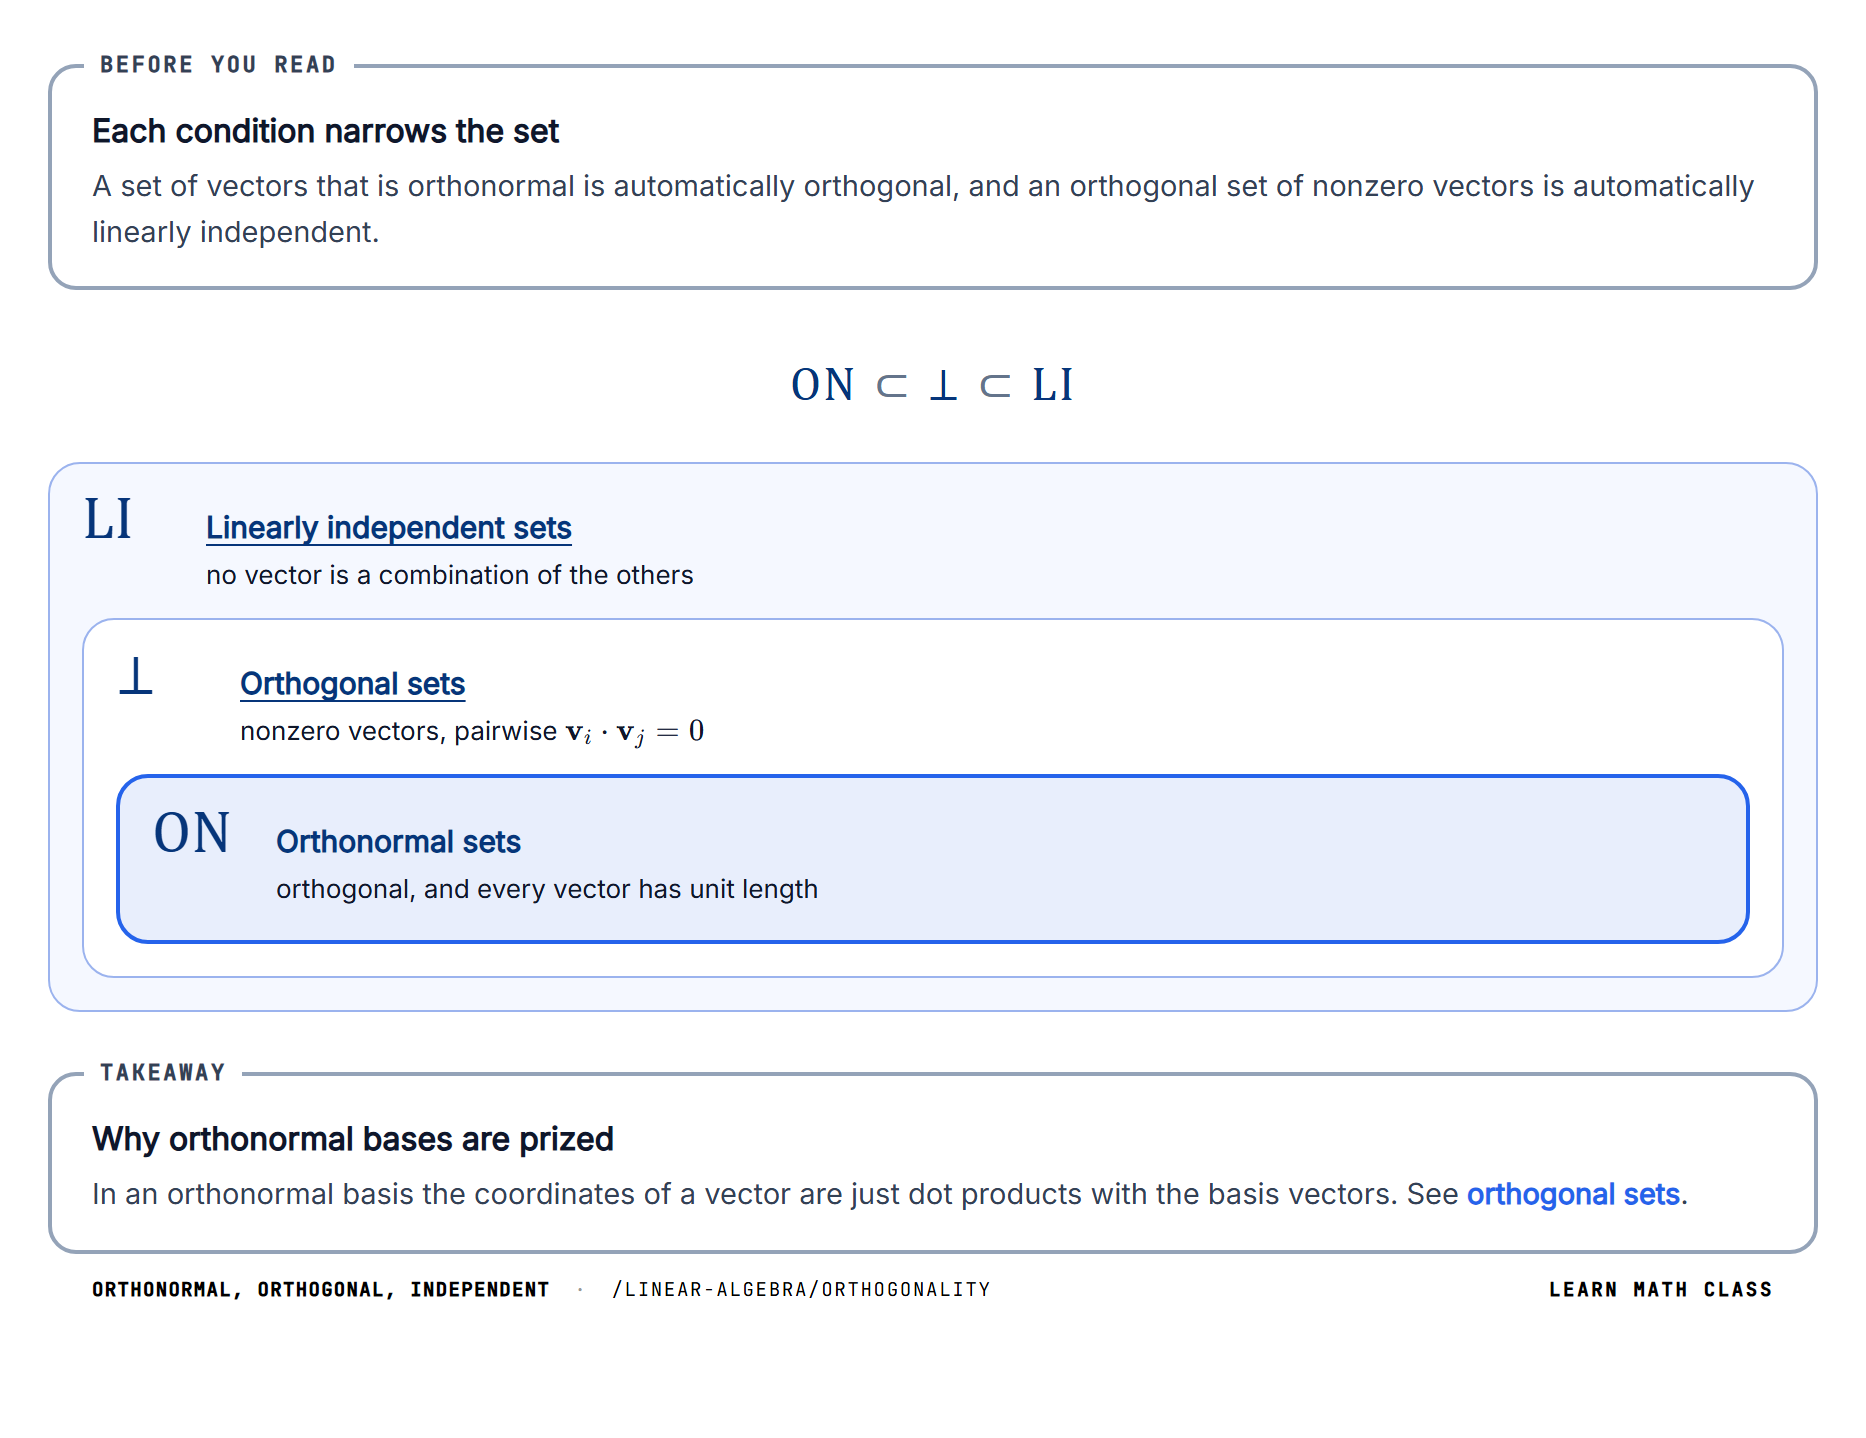
Before you read
Each condition narrows the set
A set of vectors that is orthonormal is automatically orthogonal, and an orthogonal set of nonzero vectors is automatically linearly independent.

ON⊂⊥⊂LI

LI
no vector is a combination of the others
⊥
nonzero vectors, pairwise vi⋅vj=0\mathbf{v}_i \cdot \mathbf{v}_j = 0
ON
Orthonormal sets
orthogonal, and every vector has unit length
Takeaway
Why orthonormal bases are prized
In an orthonormal basis the coordinates of a vector are just dot products with the basis vectors. See orthogonal sets.
Orthonormal, orthogonal, independent·/linear-algebra/orthogonalityLearn Math Class

Projections

The orthogonal projection of a vector b\mathbf{b} onto a subspace WW is the closest point in WW to b\mathbf{b}. It is the component of b\mathbf{b} that lies in WW, with the perpendicular remainder discarded.

For projection onto a single vector a\mathbf{a}: projab=a⋅ba⋅aa\text{proj}_{\mathbf{a}}\mathbf{b} = \frac{\mathbf{a} \cdot \mathbf{b}}{\mathbf{a} \cdot \mathbf{a}}\mathbf{a}. For projection onto a subspace with basis matrix AA: b^=A(ATA)−1ATb\hat{\mathbf{b}} = A(A^TA)^{-1}A^T\mathbf{b}.

RULE
The projection matrix P=A(ATA)−1ATP = A(A^TA)^{-1}A^T is symmetric and idempotent: PT=PP^T = P and P2=PP^2 = P.

The residual b−Pb\mathbf{b} - P\mathbf{b} is orthogonal to WW — this is the defining geometric property. And I−PI - P projects onto the orthogonal complement W⊥W^\perp.

Pitfall: Splitting the inverse in P
Splitting (ATA)−1(A^TA)^{-1} into A−1(AT)−1A^{-1}(A^T)^{-1} collapses PP to AA−1(AT)−1AT=IAA^{-1}(A^T)^{-1}A^T = I. For A=(11)A = \begin{pmatrix} 1 \\ 1 \end{pmatrix}, A−1A^{-1} does not exist, and P=12(1111)P = \frac{1}{2}\begin{pmatrix} 1 & 1 \\ 1 & 1 \end{pmatrix} sends (1,0)(1, 0) to (12,12)(\frac{1}{2}, \frac{1}{2}), not to itself.

The formula is built for a basis matrix AA of size m×nm \times n with independent columns, usually with m>nm > n, so AA is tall rather than square. The only matrix inverted is the n×nn \times n product ATAA^TA. For a single column a\mathbf{a} that product is the number a⋅a\mathbf{a} \cdot \mathbf{a}, and P=aaTa⋅aP = \frac{\mathbf{a}\mathbf{a}^T}{\mathbf{a} \cdot \mathbf{a}} reproduces the single-vector formula above.

Gram-Schmidt and Least Squares

The Gram-Schmidt process converts any linearly independent set into an orthogonal (or orthonormal) set spanning the same subspace. It does this by sequentially subtracting projections: each new vector has its components along all previously computed directions removed, leaving only the perpendicular remainder.

Pitfall: Projecting onto the original vectors
Subtracting projections onto the original v1,v2\mathbf{v}_1, \mathbf{v}_2: for (1,1,0)(1, 1, 0), (1,0,1)(1, 0, 1), (0,1,1)(0, 1, 1) it gives u3=(−1,12,12)\mathbf{u}_3 = (-1, \frac{1}{2}, \frac{1}{2}), and u3⋅u1=−12\mathbf{u}_3 \cdot \mathbf{u}_1 = -\frac{1}{2}. Projecting onto u1=(1,1,0)\mathbf{u}_1 = (1, 1, 0) and u2=(12,−12,1)\mathbf{u}_2 = (\frac{1}{2}, -\frac{1}{2}, 1) gives u3=(−23,23,23)\mathbf{u}_3 = (-\frac{2}{3}, \frac{2}{3}, \frac{2}{3}).

Gram-Schmidt applied to the columns of a matrix AA produces the QR decomposition A=QRA = QR, where QQ has orthonormal columns and RR is upper triangular. This decomposition is numerically superior to forming ATAA^TA directly and is the standard method for least-squares computation.

Least squares addresses the case where Ax=bA\mathbf{x} = \mathbf{b} has no exact solution. The best approximation x^\hat{\mathbf{x}} minimizes ∥Ax−b∥2\|A\mathbf{x} - \mathbf{b}\|^2 and satisfies the normal equations ATAx^=ATbA^TA\hat{\mathbf{x}} = A^T\mathbf{b}. Geometrically, Ax^A\hat{\mathbf{x}} is the projection of b\mathbf{b} onto the column space of AA — the closest reachable point to the unreachable target.

Common Pitfalls

Four mistakes are common when the ideas of this page are first put to work. Each is marked with a box where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.

Calling any perpendicular subspace the complement

A subspace that is perpendicular to WW is taken to be W⊥W^\perp. But W⊥W^\perp contains every vector perpendicular to WW, and a perpendicular subspace may hold only some of them.

Wrong working: in R3\mathbb{R}^3 let WW be the xx-axis, spanned by (1,0,0)(1, 0, 0). The yy-axis, spanned by (0,1,0)(0, 1, 0), is perpendicular to it, since (1,0,0)⋅(0,1,0)=0(1, 0, 0) \cdot (0, 1, 0) = 0, so it is declared to be W⊥=Span{(0,1,0)}W^\perp = \text{Span}\{(0, 1, 0)\}.

Right working: a vector v=(a,b,c)\mathbf{v} = (a, b, c) lies in W⊥W^\perp exactly when v⋅(1,0,0)=a=0\mathbf{v} \cdot (1, 0, 0) = a = 0. So
W⊥={(0,b,c):b,c∈R}W^\perp = \{(0, b, c) : b, c \in \mathbb{R}\}

the whole yzyz-plane, which contains the yy-axis, the zz-axis and every line between them.

Why it happens: in R2\mathbb{R}^2 a line perpendicular to a line really is its complement, and that picture is carried over to higher dimensions. The phrases "orthogonal subspaces" and "orthogonal complement" also sound alike.

How to check: count dimensions. dim⁡W+dim⁡W⊥\dim W + \dim W^\perp must equal nn. The xx-axis and the yy-axis give 1+1=21 + 1 = 2, not 33; the xx-axis and the yzyz-plane give 1+2=31 + 2 = 3.

Treating an orthogonal basis as orthonormal

The shortcut ci=qi⋅vc_i = \mathbf{q}_i \cdot \mathbf{v} is applied to a basis that is orthogonal but not unit length. Each coordinate then comes out multiplied by the squared length of its basis vector.

Wrong working: basis v1=(1,1)\mathbf{v}_1 = (1, 1), v2=(1,−1)\mathbf{v}_2 = (1, -1), vector v=(3,1)\mathbf{v} = (3, 1).
c1=v1⋅v=4,c2=v2⋅v=2,4(1,1)+2(1,−1)=(6,2)c_1 = \mathbf{v}_1 \cdot \mathbf{v} = 4, \quad c_2 = \mathbf{v}_2 \cdot \mathbf{v} = 2, \quad 4(1, 1) + 2(1, -1) = (6, 2)


Right working: divide each dot product by vi⋅vi\mathbf{v}_i \cdot \mathbf{v}_i.
c1=v1⋅vv1⋅v1=42=2,c2=v2⋅vv2⋅v2=22=1,2(1,1)+1(1,−1)=(3,1)c_1 = \frac{\mathbf{v}_1 \cdot \mathbf{v}}{\mathbf{v}_1 \cdot \mathbf{v}_1} = \frac{4}{2} = 2, \quad c_2 = \frac{\mathbf{v}_2 \cdot \mathbf{v}}{\mathbf{v}_2 \cdot \mathbf{v}_2} = \frac{2}{2} = 1, \quad 2(1, 1) + 1(1, -1) = (3, 1)


Why it happens: "orthogonal" and "orthonormal" differ by a few letters, and the dot-product formula is usually quoted for the orthonormal case only. Dotting with vi\mathbf{v}_i removes the other terms in both cases, but only unit length removes the factor ∥vi∥2\|\mathbf{v}_i\|^2.

How to check: rebuild the vector from its coordinates. The wrong coordinates give (6,2)=2v(6, 2) = 2\mathbf{v}, too long by exactly ∥vi∥2=2\|\mathbf{v}_i\|^2 = 2.

Splitting the inverse in P

The rule for inverting a product is applied to (ATA)−1(A^TA)^{-1}, giving A−1(AT)−1A^{-1}(A^T)^{-1}. Everything then cancels, and every projection matrix comes out as the identity.

Wrong working:
P=A(ATA)−1AT=AA−1(AT)−1AT=IP = A(A^TA)^{-1}A^T = AA^{-1}(A^T)^{-1}A^T = I


Right working: for A=(11)A = \begin{pmatrix} 1 \\ 1 \end{pmatrix}, whose column spans the line through (1,1)(1, 1),
ATA=2,P=12(11)(11)=12(1111),P(10)=(1/21/2)A^TA = 2, \quad P = \frac{1}{2}\begin{pmatrix} 1 \\ 1 \end{pmatrix}\begin{pmatrix} 1 & 1 \end{pmatrix} = \frac{1}{2}\begin{pmatrix} 1 & 1 \\ 1 & 1 \end{pmatrix}, \quad P\begin{pmatrix} 1 \\ 0 \end{pmatrix} = \begin{pmatrix} 1/2 \\ 1/2 \end{pmatrix}


Why it happens: the rule (BC)−1=C−1B−1(BC)^{-1} = C^{-1}B^{-1} is correct, but only when each factor is square and invertible. Here AA is 2×12 \times 1 and has no inverse; only the product ATAA^TA does.

How to check: a projection onto a subspace smaller than the whole space cannot be the identity, since vectors outside WW must move. Its rank must equal dim⁡W\dim W: here PP has rank 11, while II has rank 22. The split is valid only when AA is square and invertible, and then WW is the whole space and P=IP = I is correct.

Projecting onto the original vectors

In Gram-Schmidt, the third vector has its projections onto the original v1\mathbf{v}_1 and v2\mathbf{v}_2 removed, instead of its projections onto the new u1\mathbf{u}_1 and u2\mathbf{u}_2. Since v1\mathbf{v}_1 and v2\mathbf{v}_2 are not perpendicular to each other, the two subtractions interfere and the result is not orthogonal to them.

Wrong working: v1=(1,1,0)\mathbf{v}_1 = (1, 1, 0), v2=(1,0,1)\mathbf{v}_2 = (1, 0, 1), v3=(0,1,1)\mathbf{v}_3 = (0, 1, 1).
u3=v3−v3⋅v1v1⋅v1v1−v3⋅v2v2⋅v2v2=(0,1,1)−12(1,1,0)−12(1,0,1)=(−1,12,12)\mathbf{u}_3 = \mathbf{v}_3 - \frac{\mathbf{v}_3 \cdot \mathbf{v}_1}{\mathbf{v}_1 \cdot \mathbf{v}_1}\mathbf{v}_1 - \frac{\mathbf{v}_3 \cdot \mathbf{v}_2}{\mathbf{v}_2 \cdot \mathbf{v}_2}\mathbf{v}_2 = (0, 1, 1) - \tfrac{1}{2}(1, 1, 0) - \tfrac{1}{2}(1, 0, 1) = (-1, \tfrac{1}{2}, \tfrac{1}{2})


Right working: first u1=v1=(1,1,0)\mathbf{u}_1 = \mathbf{v}_1 = (1, 1, 0) and u2=v2−12u1=(12,−12,1)\mathbf{u}_2 = \mathbf{v}_2 - \frac{1}{2}\mathbf{u}_1 = (\frac{1}{2}, -\frac{1}{2}, 1), with v3⋅u2=12\mathbf{v}_3 \cdot \mathbf{u}_2 = \frac{1}{2} and u2⋅u2=32\mathbf{u}_2 \cdot \mathbf{u}_2 = \frac{3}{2}. Then
u3=v3−12u1−13u2=(0,1,1)−(12,12,0)−(16,−16,13)=(−23,23,23)\mathbf{u}_3 = \mathbf{v}_3 - \tfrac{1}{2}\mathbf{u}_1 - \tfrac{1}{3}\mathbf{u}_2 = (0, 1, 1) - (\tfrac{1}{2}, \tfrac{1}{2}, 0) - (\tfrac{1}{6}, -\tfrac{1}{6}, \tfrac{1}{3}) = (-\tfrac{2}{3}, \tfrac{2}{3}, \tfrac{2}{3})


Why it happens: the original vectors are the ones written down in the problem, and "subtract the projections" does not say onto which vectors. For the second vector there is no difference, because u1=v1\mathbf{u}_1 = \mathbf{v}_1, so the slip only shows from the third vector on.

How to check: dot the result with every earlier uj\mathbf{u}_j. The wrong vector gives (−1,12,12)⋅(1,1,0)=−12(-1, \frac{1}{2}, \frac{1}{2}) \cdot (1, 1, 0) = -\frac{1}{2}. The right one gives (−23,23,23)⋅(1,1,0)=0(-\frac{2}{3}, \frac{2}{3}, \frac{2}{3}) \cdot (1, 1, 0) = 0 and (−23,23,23)⋅(12,−12,1)=0(-\frac{2}{3}, \frac{2}{3}, \frac{2}{3}) \cdot (\frac{1}{2}, -\frac{1}{2}, 1) = 0.

Summary: Orthogonality at a Glance

The orthogonality subtree branches into several specialized topics — inner products, orthogonal and orthonormal sets, projections, Gram–Schmidt, and least squares — each developed in its own page. The table below collects each topic alongside its key statement and the main formula or result, providing a roadmap from this hub into the deeper material and a single reference for the central facts.
Topic Key statement Main formula or result
Orthogonal vectors u · v = 0 means u and v are perpendicular the dot-product-zero test
Orthogonal complement W⊥ vectors perpendicular to every vector in W form a subspace dim W + dim W⊥ = n; every v = w + w⊥ uniquely
Inner product generalizes the dot product to arbitrary vector spaces symmetry, linearity, positive definiteness; induces norm, distance, Cauchy–Schwarz
Orthogonal & orthonormal sets pairwise-perpendicular vectors are automatically independent in an orthonormal basis, coordinates are free: ci = qi · v
Projection onto a subspace the closest point in W to a given b projection matrix P = A(AᵀA)⁻¹Aᵀ; idempotent and symmetric
Gram–Schmidt process converts any basis into an orthonormal one sequential projection subtraction; produces A = QR (QR decomposition)
Least squares best approximate solution when A x = b has none normal equations AᵀA x̂ = Aᵀb; A x̂ is the projection of b onto Col(A)