Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Least Squares


The Best Approximate Solution

When a linear system has no solution, the least-squares method finds the vector that comes closest — the one minimizing the squared distance between Ax and b. The answer is a projection: the least-squares solution produces the point in the column space nearest to b, and the normal equations encode the orthogonality condition that defines "nearest."


The Problem

Fact: A lost asteroid found again
Ceres, discovered on 1 January 1801, was followed for about six weeks before it vanished in the Sun's glare. The 24-year-old Gauss fitted an orbit to those few observations, Ceres was found again on 31 December 1801 close to his prediction, and least squares was part of the method he published in 1809.

The system Ax=bA\mathbf{x} = \mathbf{b} may have no solution — b\mathbf{b} may not lie in the column space of AA. This is typical when the system is overdetermined: more equations than unknowns, with the equations imposing contradictory constraints.

Overdetermined systems are the normal situation whenever something is measured. An orbit around the Sun is fixed by six numbers, but astronomers record far more than six positions, and each one carries a small measurement error. The equations then disagree slightly with one another, and no single orbit satisfies all of them exactly.

When no exact solution exists, the goal shifts from solving Ax=bA\mathbf{x} = \mathbf{b} to minimizing the error:

The Problem
x^=arg⁡min⁡x∥Ax−b∥2\hat{\mathbf{x}} = \arg\min_{\mathbf{x}} \|A\mathbf{x} - \mathbf{b}\|^2

The quantity ∥Ax−b∥2=∑i(Ax−b)i2\|A\mathbf{x} - \mathbf{b}\|^2 = \sum_i (A\mathbf{x} - \mathbf{b})_i^2 is the sum of squared residuals. The vector x^\hat{\mathbf{x}} that minimizes this sum is the least-squares solution.
[A | b]3×3106110120→rref3×3100010001
The system has no solution

Three data points and a line with two parameters give three equations in two unknowns. Reducing [A | b] leaves a pivot in the last column — a row that reads 0 = nonzero — so b is not in the column space of A and no x makes Ax equal b. Least squares starts exactly here: if no x is exact, find the x whose Ax comes closest. Follow the whole method on the least squares visualizer.

An inconsistent system is not the end of the problem; it is the reason least squares exists.

Least Squares Notation

Notation

Least Squares Notation

A hat that marks a best guess rather than a solution, a named equation whose name means "perpendicular" and not "usual", and a superscript plus that stands in for an inverse the matrix does not have. All catalogued among the linear algebra symbols.
The estimate hat x^\hat{\mathbf{x}}, proj⁡W\operatorname{proj}_W and the projection matrix PP come from projection notation; ∥⋅∥\|\cdot\| from norm notation; ATA^{T} and A−1A^{-1} from matrix operation and inverse notation; A=QRA = QR from Gram-Schmidt notation; Col⁡\operatorname{Col} from fundamental-space notation.
x^=arg⁡min⁡x∥Ax−b∥\hat{\mathbf{x}} = \arg\min_{\mathbf{x}} \|A\mathbf{x} - \mathbf{b}\|
x-hat is the x that minimises the residual length
The hat announces that this is a best available answer, not a solution: when Ax=bA\mathbf{x} = \mathbf{b} has no solution, x^\hat{\mathbf{x}} is what replaces it. The arg min is doing the same job it does elsewhere — returning the input that minimises, not the minimum itself.
CasesSquaring is a notational convenience, not a change of problem: ∥Ax−b∥2\|A\mathbf{x} - \mathbf{b}\|^2 has the same minimiser as ∥Ax−b∥\|A\mathbf{x} - \mathbf{b}\| because squaring is increasing on non-negative numbers — and the square is what makes the derivative tractable, which is where the method's name comes from.
Do not confuseAn exact solution. Ax^=bA\hat{\mathbf{x}} = \mathbf{b} is generally false — that is the entire premise — so writing x^\hat{\mathbf{x}} without the hat quietly asserts something the setup denies.
ATAx^=ATbA^{T}A\hat{\mathbf{x}} = A^{T}\mathbf{b}
the normal equations
A named system, and the name is geometric: "normal" here means perpendicular, recording that the residual is orthogonal to the column space — the condition The Normal Equations below derives. Multiplying through by ATA^{T} is what converts an unsolvable system into a solvable one.
CasesWhen ATAA^{T}A is invertible the equations close into x^=(ATA)−1ATb\hat{\mathbf{x}} = (A^{T}A)^{-1}A^{T}\mathbf{b}; that inverse exists exactly when AA has independent columns, so the formula silently assumes full column rank and should not be written otherwise.
Do not confuse"Normal" as ordinary, or as the normal distribution. Neither is meant — the word points at the right angle in the geometry, and the collision with the statistical sense is pure accident of vocabulary, not a shared idea.
A+A^{+}
A-plus — the pseudoinverse of A
The plus superscript joins the corner census as a stand-in for an inverse that does not exist: x^=A+b\hat{\mathbf{x}} = A^{+}\mathbf{b} mirrors x=A−1b\mathbf{x} = A^{-1}\mathbf{b} in shape, and the changed symbol is the only warning that AA may be non-square or singular. Its construction belongs to SVD notation.
Also writtenA†A^{\dagger} — the dagger — is equally standard and dominant in physics and numerical texts; both spellings mean the Moore–Penrose pseudoinverse, and the choice is house style rather than a difference in object.
Do not confuseThe superscript ++ of set theory and elsewhere. Here it neither adds nor denotes a positive part; the corner is a label, the same grammar as ATA^{T} and A−1A^{-1}, and only its position identifies the job.

The Geometric Interpretation

The set of all vectors AxA\mathbf{x} as x\mathbf{x} ranges over Rn\mathbb{R}^n is the column space of AA. Minimizing ∥Ax−b∥\|A\mathbf{x} - \mathbf{b}\| means finding the point in the column space closest to b\mathbf{b}. That closest point is the orthogonal projection b^=projCol(A)b\hat{\mathbf{b}} = \text{proj}_{\text{Col}(A)}\mathbf{b}.

The least-squares solution x^\hat{\mathbf{x}} satisfies Ax^=b^A\hat{\mathbf{x}} = \hat{\mathbf{b}} — it produces the projection, not the original b\mathbf{b}. The residual r=b−Ax^=b−b^\mathbf{r} = \mathbf{b} - A\hat{\mathbf{x}} = \mathbf{b} - \hat{\mathbf{b}} is the component of b\mathbf{b} orthogonal to the column space. It lies in Col(A)⊥=Null(AT)\text{Col}(A)^\perp = \text{Null}(A^T).

The orthogonality condition ATr=0A^T\mathbf{r} = \mathbf{0} — the residual is perpendicular to every column of AA — is the geometric content of the least-squares solution. It is this condition that leads to the normal equations.
b600−p52−1=e1−21,Aᵀ2×3111012e1−21=Aᵀe00
The residual, perpendicular to the column space

The target lies off the column space, so no exact solution exists. The best available answer is its projection, and what is left over is the residual — which comes out perpendicular to the column space rather than merely small. Minimising the error and making it perpendicular are the same requirement. See it for an inconsistent system on the least squares visualizer.

Everything algebraic that follows is a way of computing this projection without having to draw it.

The Normal Equations

The orthogonality condition AT(b−Ax^)=0A^T(\mathbf{b} - A\hat{\mathbf{x}}) = \mathbf{0} rearranges to

Normal Equations
ATAx^=ATbA^TA\hat{\mathbf{x}} = A^T\mathbf{b}

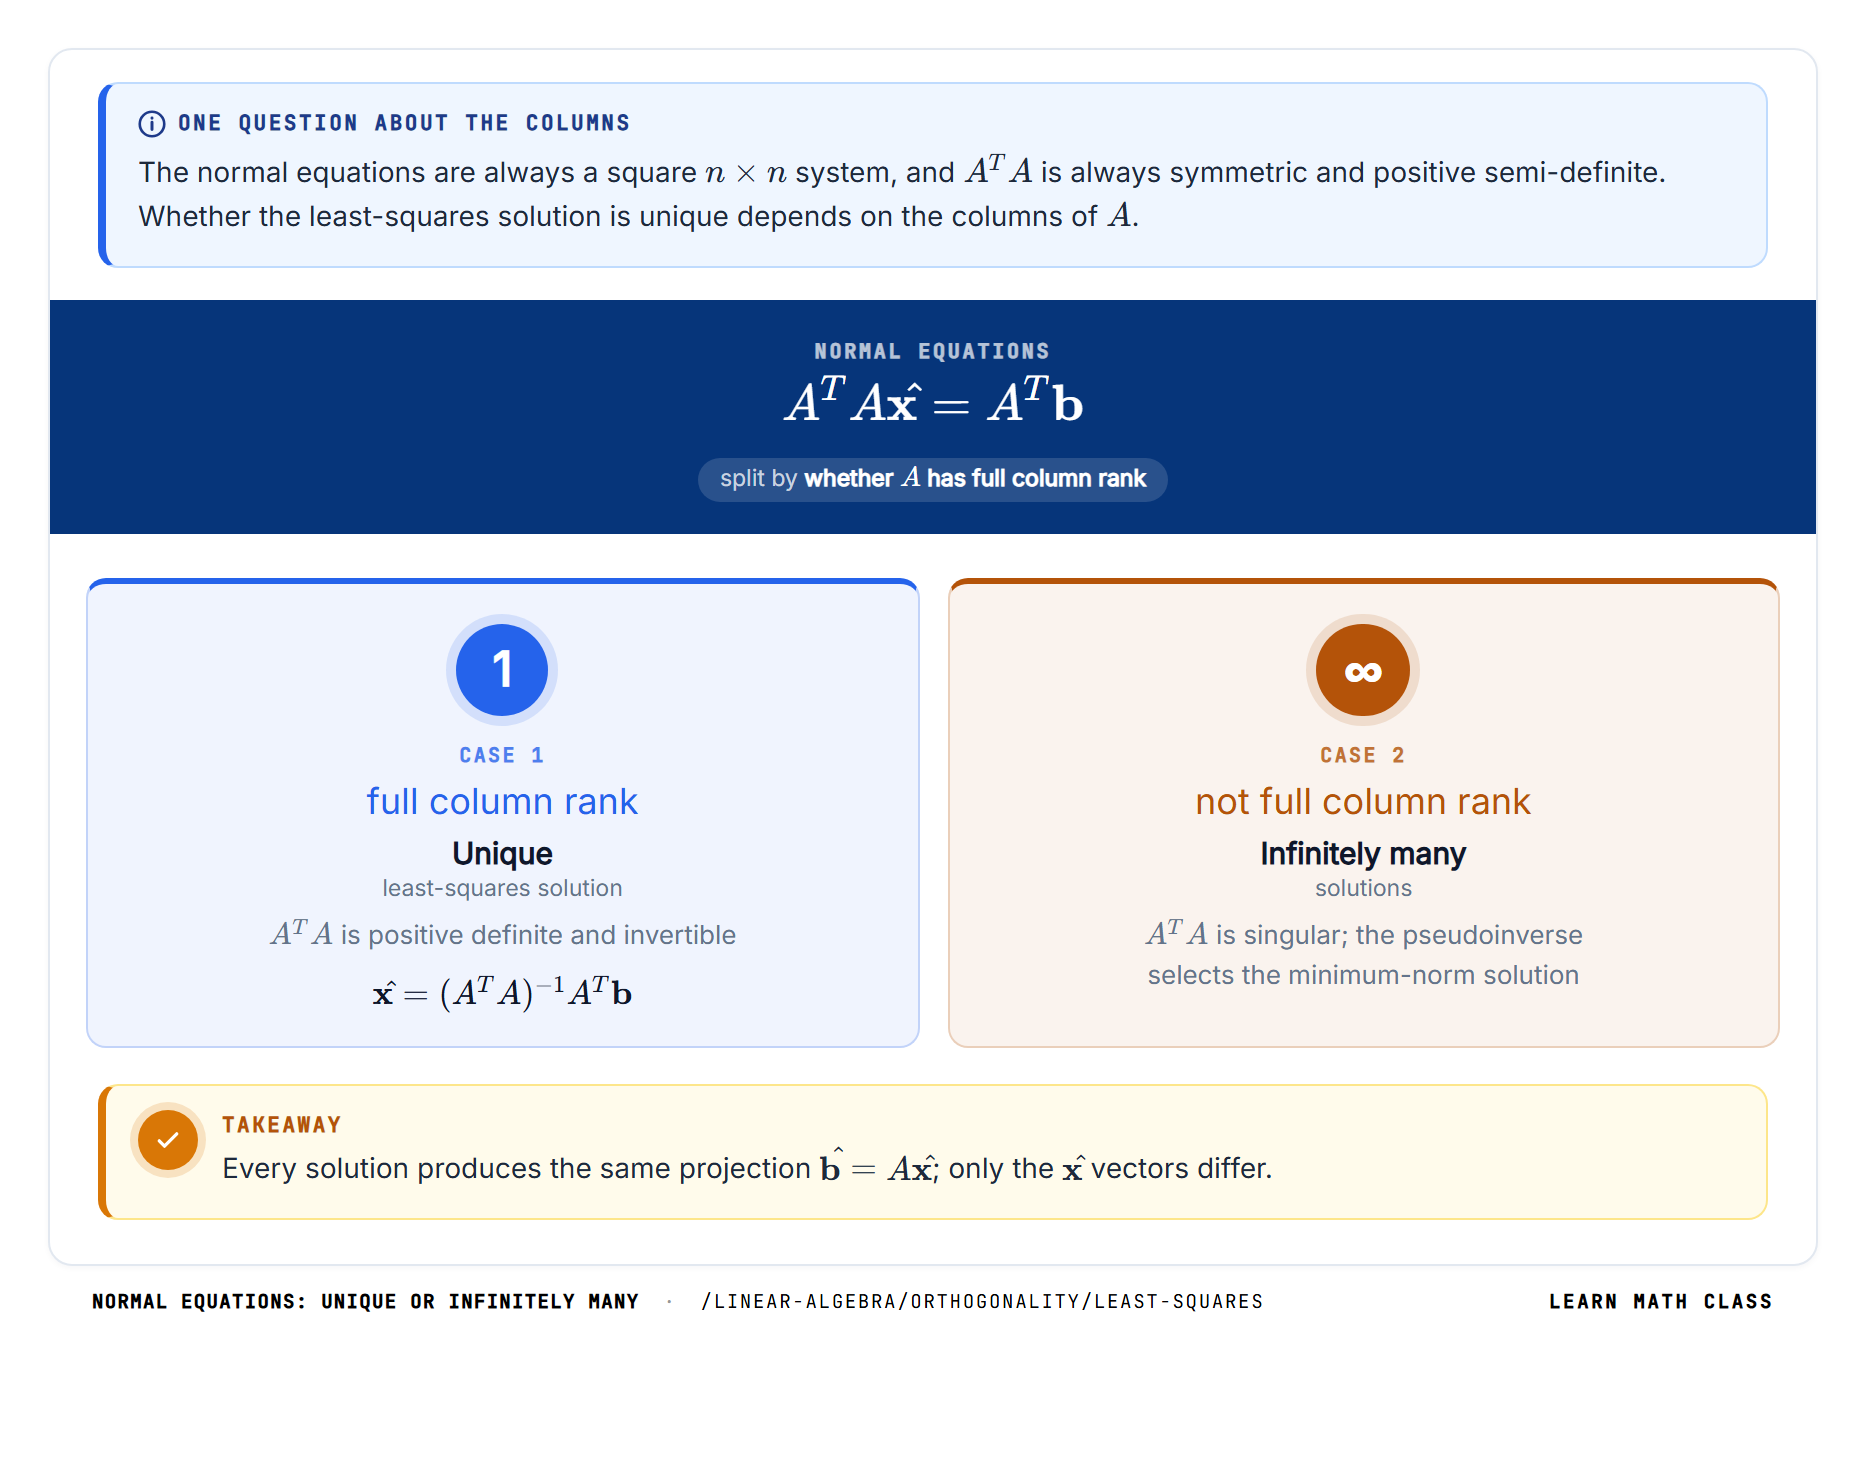
These are the normal equations. They form a square n×nn \times n system regardless of the shape of AA.

RULE
The matrix ATAA^TA is always symmetric and positive semi-definite.

When AA has full column rank (the columns are linearly independent), ATAA^TA is positive definite and invertible, giving a unique least-squares solution:

Least Squares Solution
x^=(ATA)−1ATb\hat{\mathbf{x}} = (A^TA)^{-1}A^T\mathbf{b}

Pitfall: Splitting the inverse into two factors
Writing (ATA)−1=A−1(AT)−1(A^TA)^{-1} = A^{-1}(A^T)^{-1} collapses the formula to x^=A−1b\hat{\mathbf{x}} = A^{-1}\mathbf{b}, but the 4×24 \times 2 matrix AA of the line fit below has no inverse. Only the square matrix ATAA^TA, there (4101030)\begin{pmatrix} 4 & 10 \\ 10 & 30 \end{pmatrix}, is inverted, as one matrix.

The formula is read from right to left. The vector ATbA^T\mathbf{b} collects the dot products of b\mathbf{b} with the columns of AA, the matrix ATAA^TA collects the dot products of the columns with each other, and the inverse of ATAA^TA turns the first into the coefficients. For the line fit below, AA is 4×24 \times 2, so both pieces are small: a 2×22 \times 2 matrix and a vector of length 22.

When AA does not have full column rank, ATAA^TA is singular and the normal equations have infinitely many solutions. All produce the same projection b^=Ax^\hat{\mathbf{b}} = A\hat{\mathbf{x}}, but the x^\hat{\mathbf{x}} vectors differ. The minimum-norm solution — the one with smallest ∥x^∥\|\hat{\mathbf{x}}\| — is selected by the pseudoinverse.
DownloadPNG2×PDF
One question about the columns
The normal equations are always a square n×nn \times n system, and ATAA^TA is always symmetric and positive semi-definite. Whether the least-squares solution is unique depends on the columns of AA.
Normal equations
ATAx^=ATbA^TA\hat{\mathbf{x}} = A^T\mathbf{b}
split by whether AA has full column rank
1
Case 1
full column rank
Unique
least-squares solution
ATAA^TA is positive definite and invertible
x^=(ATA)−1ATb\hat{\mathbf{x}} = (A^TA)^{-1}A^T\mathbf{b}
∞
Case 2
not full column rank
Infinitely many
solutions
ATAA^TA is singular; the pseudoinverse selects the minimum-norm solution
Takeaway
Every solution produces the same projection b^=Ax^\hat{\mathbf{b}} = A\hat{\mathbf{x}}; only the x^\hat{\mathbf{x}} vectors differ.
Normal equations: unique or infinitely many·/linear-algebra/orthogonality/least-squaresLearn Math Class
Aᵀ2×3111012A3×2101112=AᵀA2×23335,Aᵀ2×3111012b600=Aᵀb60
The normal equations assembled

Multiplying through by the transpose turns an unsolvable system into a solvable one, and the reason is the perpendicularity above: demanding that the residual be orthogonal to every column is exactly what these equations say. Form them for your own data on the least squares visualizer.

These equations are the classical route and the least numerically stable one, which is why QR is preferred in practice.

Worked Example: Fitting a Line

Fit a line y=c0+c1xy = c_0 + c_1 x to the data points (1,2)(1, 2), (2,3)(2, 3), (3,6)(3, 6), (4,7)(4, 7).

The model yi=c0+c1xiy_i = c_0 + c_1 x_i for each data point gives the system Ac=yA\mathbf{c} = \mathbf{y} with

Worked Example: Fitting a Line
A=(11121314),y=(2367)A = \begin{pmatrix} 1 & 1 \\ 1 & 2 \\ 1 & 3 \\ 1 & 4 \end{pmatrix}, \quad \mathbf{y} = \begin{pmatrix} 2 \\ 3 \\ 6 \\ 7 \end{pmatrix}

Four equations in two unknowns — overdetermined. The normal equations:

Worked Example: Fitting a Line
ATA=(4101030),ATy=(1854)A^TA = \begin{pmatrix} 4 & 10 \\ 10 & 30 \end{pmatrix}, \quad A^T\mathbf{y} = \begin{pmatrix} 18 \\ 54 \end{pmatrix}

Solving: det⁡(ATA)=120−100=20\det(A^TA) = 120 - 100 = 20. (ATA)−1=120(30−10−104)(A^TA)^{-1} = \frac{1}{20}\begin{pmatrix} 30 & -10 \\ -10 & 4 \end{pmatrix}.

Worked Example: Fitting a Line
c^=120(30−10−104)(1854)=120(540−540−180+216)=120(036)=(01.8)\hat{\mathbf{c}} = \frac{1}{20}\begin{pmatrix} 30 & -10 \\ -10 & 4 \end{pmatrix}\begin{pmatrix} 18 \\ 54 \end{pmatrix} = \frac{1}{20}\begin{pmatrix} 540 - 540 \\ -180 + 216 \end{pmatrix} = \frac{1}{20}\begin{pmatrix} 0 \\ 36 \end{pmatrix} = \begin{pmatrix} 0 \\ 1.8 \end{pmatrix}

The best-fit line is y=1.8xy = 1.8x (the intercept comes out 00). The residuals are 2−1.8=0.22 - 1.8 = 0.2, 3−3.6=−0.63 - 3.6 = -0.6, 6−5.4=0.66 - 5.4 = 0.6, 7−7.2=−0.27 - 7.2 = -0.2. Their sum of squares 0.04+0.36+0.36+0.04=0.80.04 + 0.36 + 0.36 + 0.04 = 0.8 is the minimum achievable error for any line through these data.
[AᵀA | Aᵀb]1×2915→rref1×215/3→x̂5/3
A best-fit line through scattered points

The points do not lie on any line, so the system was never going to be consistent. What the fit returns is the line whose vertical errors have the smallest total square — and fitting a line is nothing more than least squares with two unknowns. Move the points and watch the fit respond on the least squares visualizer.

Fitting a parabola in the next section changes only the columns, never the method.

Worked Example: Fitting a Parabola

Fit a parabola y=c0+c1x+c2x2y = c_0 + c_1 x + c_2 x^2 to the same data (1,2)(1, 2), (2,3)(2, 3), (3,6)(3, 6), (4,7)(4, 7).

The design matrix gains a third column:

Worked Example: Fitting a Parabola
A=(1111241391416)A = \begin{pmatrix} 1 & 1 & 1 \\ 1 & 2 & 4 \\ 1 & 3 & 9 \\ 1 & 4 & 16 \end{pmatrix}

Fact: The best parabola is a straight line
For these four points the least-squares parabola is y=1.8xy = 1.8x again, with c2=0c_2 = 0. The line's residuals (0.2,−0.6,0.6,−0.2)(0.2, -0.6, 0.6, -0.2) are already perpendicular to the new column (1,4,9,16)(1, 4, 9, 16), so the extra freedom has nothing to fix.

The normal equations ATAc^=ATyA^TA\hat{\mathbf{c}} = A^T\mathbf{y} now form a 3×33 \times 3 system. The machinery is identical — only the model matrix changes. A higher-degree model provides a fit at least as close (the residual sum of squares cannot increase when the model gains flexibility), but it also risks fitting noise rather than signal.

The framework generalizes to any linear model: y=c0f0(x)+c1f1(x)+⋯+ckfk(x)y = c_0 f_0(x) + c_1 f_1(x) + \cdots + c_k f_k(x) where the functions fif_i are chosen in advance. Each choice produces a different design matrix AA, and the normal equations produce the best coefficients in the least-squares sense.
Model Number of parameters Row of the design matrix A Typical use
Line: y = c0 + c1 x 2 [ 1, xi ] linear trends in one variable
Parabola: y = c0 + c1 x + c2 x² 3 [ 1, xi, xi² ] smooth one-variable curves with curvature
Polynomial of degree k k + 1 [ 1, xi, xi², …, xik ] higher-order curve fitting; flexible but prone to overfit
Generic linear model: y = Σj cj fj(x) k + 1 [ f0(xi), f1(xi), …, fk(xi) ] arbitrary basis functions (sinusoids, exponentials, splines)
Multiple linear regression: y = β0 + Σj βj xj k + 1 [ 1, x1,i, x2,i, …, xk,i ] several predictors per observation

The Projection Matrix

The projection of b\mathbf{b} onto the column space is b^=Pb\hat{\mathbf{b}} = P\mathbf{b} where

The Projection Matrix
P=A(ATA)−1ATP = A(A^TA)^{-1}A^T

When the columns of AA are orthonormal (A=QA = Q with QTQ=IQ^TQ = I), this simplifies to P=QQTP = QQ^T.

Pitfall: Swapping the order of the two factors
Writing P=QTQP = Q^TQ gives InI_n, which is n×nn \times n and for m>nm > n cannot even multiply b∈Rm\mathbf{b} \in \mathbb{R}^m. For Q=12(11)Q = \frac{1}{\sqrt{2}}\begin{pmatrix} 1 \\ 1 \end{pmatrix}, QTQ=1Q^TQ = 1, while the projection is P=QQT=12(1111)P = QQ^T = \frac{1}{2}\begin{pmatrix} 1 & 1 \\ 1 & 1 \end{pmatrix}.

With orthonormal columns the middle factor ATA=QTQA^TA = Q^TQ drops out of the formula, and no inverse is left to compute. The projection becomes Pb=Q(QTb)P\mathbf{b} = Q(Q^T\mathbf{b}): the entries of QTbQ^T\mathbf{b} are the dot products of b\mathbf{b} with the columns of QQ, and QQ uses them as weights on those same columns.

RULE
The projection matrix is symmetric (PT=PP^T = P) and idempotent (P2=PP^2 = P).

The complementary matrix I−PI - P projects onto the orthogonal complement Col(A)⊥\text{Col}(A)^\perp and extracts the residual: r=(I−P)b\mathbf{r} = (I - P)\mathbf{b}.

The minimum squared error is

The Projection Matrix
∥r∥2=∥(I−P)b∥2=∥b∥2−∥Pb∥2\|\mathbf{r}\|^2 = \|(I - P)\mathbf{b}\|^2 = \|\mathbf{b}\|^2 - \|P\mathbf{b}\|^2

by the Pythagorean theorem, since PbP\mathbf{b} and (I−P)b(I - P)\mathbf{b} are orthogonal.
P3×35/61/3−1/61/31/31/3−1/61/35/6b600=P b52−1
P b = p

The projection matrix P = A(ATA)−1AT built from the same A, applied to b. The output p is the point of the column space nearest to b — the vector Ax̂ that the least-squares solution produces. P depends only on A, so one matrix projects every right-hand side at once. See the same projection from the normal equations on the least squares visualizer.

Whichever way it is computed, the least-squares fit is the projection of b onto the column space.

The Pseudoinverse

The matrix A+=(ATA)−1ATA^+ = (A^TA)^{-1}A^T (when AA has full column rank) is called the left pseudoinverse of AA. The least-squares solution is x^=A+b\hat{\mathbf{x}} = A^+\mathbf{b}.

The pseudoinverse satisfies A+A=InA^+A = I_n (it is a left inverse of AA), but AA+≠ImAA^+ \neq I_m in general — the product AA+AA^+ equals the projection matrix PP.

When AA does not have full column rank, the Moore-Penrose pseudoinverse A+A^+ is defined through the singular value decomposition: if A=UΣVTA = U\Sigma V^T, then A+=VΣ+UTA^+ = V\Sigma^+ U^T, where Σ+\Sigma^+ inverts the nonzero singular values and transposes the shape.

THEOREM
The Moore-Penrose pseudoinverse gives the minimum-norm least-squares solution — the x^\hat{\mathbf{x}} of smallest length among all minimizers of ∥Ax−b∥\|A\mathbf{x} - \mathbf{b}\|.

Least Squares via QR

The QR decomposition A=QRA = QR provides a numerically superior method for solving the normal equations.

Substituting A=QRA = QR into ATAx^=ATbA^TA\hat{\mathbf{x}} = A^T\mathbf{b} gives RTQTQRx^=RTQTbR^TQ^TQR\hat{\mathbf{x}} = R^TQ^T\mathbf{b}. Since QTQ=IQ^TQ = I, this simplifies to RTRx^=RTQTbR^TR\hat{\mathbf{x}} = R^TQ^T\mathbf{b}. Multiplying both sides by (RT)−1(R^T)^{-1}:

Least Squares via QR
Rx^=QTbR\hat{\mathbf{x}} = Q^T\mathbf{b}

The right-hand side QTbQ^T\mathbf{b} is a vector of nn dot products. The left-hand side is an upper triangular system, solved by back substitution.

The critical advantage is numerical. Forming ATAA^TA explicitly squares the condition number of AA, amplifying rounding errors. The QR approach works with QQ and RR directly, preserving the original conditioning. This is why QR-based least squares is the standard algorithm in numerical software, from MATLAB to Python's NumPy.

Regression as Least Squares

The entire framework of linear regression is a least-squares problem in matrix form.

Simple linear regression fits y=β0+β1x+ϵy = \beta_0 + \beta_1 x + \epsilon to data (xi,yi)(x_i, y_i). The design matrix has a column of ones and a column of xix_i values. The normal equations produce the slope β^1\hat{\beta}_1 and intercept β^0\hat{\beta}_0 that minimize ∑(yi−β0−β1xi)2\sum(y_i - \beta_0 - \beta_1 x_i)^2.

Pitfall: Leaving out the column of ones
Without the column of ones the model is y=c1xy = c_1x, a line forced through the origin. For (0,1)(0, 1), (1,3)(1, 3), (2,5)(2, 5) the single column (0,1,2)(0, 1, 2) gives 5c1=135c_1 = 13 and y=2.6xy = 2.6x, although the line y=1+2xy = 1 + 2x passes through all three points.

Multiple linear regression fits y=Xβ+ϵ\mathbf{y} = X\boldsymbol{\beta} + \boldsymbol{\epsilon} where XX is the design matrix with rows for observations and columns for predictors. The normal equations XTXβ^=XTyX^TX\hat{\boldsymbol{\beta}} = X^T\mathbf{y} give the coefficient estimates.

The projection matrix P=X(XTX)−1XTP = X(X^TX)^{-1}X^T is called the hat matrix in statistics because it puts the "hat" on y\mathbf{y}: y^=Py\hat{\mathbf{y}} = P\mathbf{y}. The residual vector e=y−y^=(I−P)y\mathbf{e} = \mathbf{y} - \hat{\mathbf{y}} = (I - P)\mathbf{y} is the component of y\mathbf{y} orthogonal to the column space of XX, and ∥e∥2\|\mathbf{e}\|^2 is the residual sum of squares.
Linear-algebra object Statistics / regression name Symbol and role
Coefficient matrix design matrix / predictor matrix X — rows = observations, columns = features (with an intercept column of 1s)
Vector of unknowns coefficient (parameter) vector β — parameters to be estimated
Right-hand side response vector y — observed outcomes
Least-squares solution estimated coefficients β̂ = (XᵀX)⁻¹ Xᵀ y
Projection matrix P hat matrix P = X(XᵀX)⁻¹Xᵀ — puts the "hat" on y
Projection of b onto Col(A) fitted values ŷ = P y = X β̂
Residual vector residual (errors) e = y − ŷ = (I − P) y
Squared residual length residual sum of squares (RSS) ‖e‖² = Σᵢ (yi − ŷi)²
Fraction of length captured by projection (centered) coefficient of determination R² — fraction of variation in y explained by the model
Linear regression is least squares under another name: the fitted values are the projection of the data onto the column space.

The Minimum Error

THEOREM
The least-squares error ∥r∥=∥b−Ax^∥\|\mathbf{r}\| = \|\mathbf{b} - A\hat{\mathbf{x}}\| is the distance from b\mathbf{b} to the column space of AA.

It is the length of the orthogonal component of b\mathbf{b} with respect to Col(A)\text{Col}(A).

By the Pythagorean theorem, since b^=Ax^\hat{\mathbf{b}} = A\hat{\mathbf{x}} and r=b−b^\mathbf{r} = \mathbf{b} - \hat{\mathbf{b}} are perpendicular:

The Minimum Error
∥b∥2=∥b^∥2+∥r∥2\|\mathbf{b}\|^2 = \|\hat{\mathbf{b}}\|^2 + \|\mathbf{r}\|^2

The error is what remains after the projection accounts for as much of b\mathbf{b} as possible. The ratio ∥b^∥2/∥b∥2\|\hat{\mathbf{b}}\|^2 / \|\mathbf{b}\|^2 (computed with centered data in regression) is the coefficient of determination R2R^2 — the fraction of the total variation explained by the model. An R2R^2 close to 11 means the column space captures nearly all of b\mathbf{b}; close to 00 means the model explains little.

The error is zero if and only if b∈Col(A)\mathbf{b} \in \text{Col}(A) — if and only if the original system Ax=bA\mathbf{x} = \mathbf{b} has an exact solution. In that case, the least-squares solution is the exact solution, and the two problems coincide.

Summary: Methods for Computing the Least-Squares Solution

The least-squares solution x̂ can be computed by several distinct routes, each with its own cost and numerical-stability profile. The table below collects the main methods alongside their formulas, operation counts, and stability characteristics, providing a single reference for choosing among them.
The four methods below all return the same x^\hat{\mathbf{x}} in exact arithmetic, so the choice between them is not about correctness. It is about a single decision: whether the method forms ATAA^{\mathsf{T}}A or arranges never to see it. The grouping is that decision, and it is also the ranking.
Orthogonality · least squares

Four ways to compute the same solution

All four minimise ∥Ax−b∥2\|A\mathbf{x} - \mathbf{b}\|^2 and return the same x^\hat{\mathbf{x}} in exact arithmetic. In floating point they do not, and the difference is entirely about whether the method forms ATAA^{\mathsf{T}}A or avoids it.

4methods
Forms ATAA^{\mathsf{T}}A — correct, fragile1
1
∼mn2+n3/3\sim mn^2 + n^3/3; needs full column rank
ATAx^=ATbA^{\mathsf{T}}A\hat{\mathbf{x}} = A^{\mathsf{T}}\mathbf{b}
The derivation everyone learns and the computation nobody should run. Setting the gradient to zero gives these equations directly, and ATAA^{\mathsf{T}}A is symmetric positive definite so Cholesky solves it — but the squared condition number means the answer can lose half its digits before Cholesky begins.
Avoids it — the practical routes3
2
∼2mn2\sim 2mn^2 via Householder
Rx^=QTbR\hat{\mathbf{x}} = Q^{\mathsf{T}}\mathbf{b}
Factor A=QRA = QR, multiply through by QTQ^{\mathsf{T}}, and back-substitute on the triangular system. QQ is orthogonal so it preserves lengths and therefore the condition number — the workhorse in every numerical library, and the reason QR is taught alongside least squares.
3
no rank condition at all
x^=VΣ+UTb\hat{\mathbf{x}} = V\Sigma^{+}U^{\mathsf{T}}\mathbf{b}
The only method that works when AA is rank-deficient, where the others have no unique solution to find. Among the infinitely many minimisers it returns the one of smallest norm — a choice made deliberately rather than by accident of the algorithm. Costs more than QR and is worth it when the rank is in doubt.
4
one matrix–vector product per step
Krylov iteration on ATAx^=ATbA^{\mathsf{T}}A\hat{\mathbf{x}} = A^{\mathsf{T}}\mathbf{b}
Never forms ATAA^{\mathsf{T}}A explicitly — only its action on a vector, which costs two multiplications by AA. The right choice when AA is large and sparse and a factorization would destroy the sparsity. Convergence depends on conditioning, so preconditioning is part of the method rather than an optimisation.
Forming ATAA^{\mathsf{T}}A squares the condition number — a matrix with κ=104\kappa = 10^4 becomes 10810^8, and roughly half the available digits are lost before the solve begins. Every method below except the first is a way of not doing that, which is why the textbook derivation and the library implementation take different routes to the same answer.
Four ways to compute the same solution·/linear-algebra/orthogonality/least-squaresLearn Math Class
Why forming ATAA^{\mathsf{T}}A hurts is worth stating in numbers. The condition number of ATAA^{\mathsf{T}}A is the square of the condition number of AA, so a matrix with κ(A)=104\kappa(A) = 10^4 — unremarkable in a fitting problem — produces a system with κ=108\kappa = 10^8. In double precision that consumes roughly half the available digits before the solve has started, and no amount of care in the solver recovers them.
QR avoids this because QQ is orthogonal: multiplying by it preserves lengths, so it cannot amplify error, and the triangular system inherits AA's conditioning rather than its square. The SVD goes further and drops the rank requirement entirely, which is the case where the other three have no unique answer to compute — among infinitely many minimisers it returns the one of least norm. That is a deliberate choice, not a default, and it is why the pseudoinverse is the right tool when the rank is uncertain.
Common Pitfalls

Three mistakes come up again and again when the least-squares formulas are applied by hand. Each is marked with a box where it happens in the sections above. Here each is worked through in full, with the wrong and the right working side by side.

Splitting the inverse into two factors

The formula x^=(ATA)−1ATb\hat{\mathbf{x}} = (A^TA)^{-1}A^T\mathbf{b} is simplified with the rule for the inverse of a product, (XY)−1=Y−1X−1(XY)^{-1} = Y^{-1}X^{-1}, taking X=ATX = A^T and Y=AY = A. The factors cancel, and the least-squares problem seems to disappear.

Wrong working:
x^=(ATA)−1ATb=A−1(AT)−1ATb=A−1b\hat{\mathbf{x}} = (A^TA)^{-1}A^T\mathbf{b} = A^{-1}(A^T)^{-1}A^T\mathbf{b} = A^{-1}\mathbf{b}

For the line fit, A=(11121314)A = \begin{pmatrix} 1 & 1 \\ 1 & 2 \\ 1 & 3 \\ 1 & 4 \end{pmatrix} is 4×24 \times 2, so A−1A^{-1} does not exist and the last expression means nothing.

Right working: form the 2×22 \times 2 matrix first and invert it as a whole,
ATA=(4101030),(ATA)−1=120(30−10−104)A^TA = \begin{pmatrix} 4 & 10 \\ 10 & 30 \end{pmatrix}, \quad (A^TA)^{-1} = \frac{1}{20}\begin{pmatrix} 30 & -10 \\ -10 & 4 \end{pmatrix}

and then multiply by the vector ATyA^T\mathbf{y}.

Why it happens: the rule (XY)−1=Y−1X−1(XY)^{-1} = Y^{-1}X^{-1} is learned for square invertible matrices and looks as if it applies to any product. Here neither AA nor ATA^T is square; only their product is.

How to check: check the sizes before writing an inverse, since only square matrices have one. If a simplification ends in A−1bA^{-1}\mathbf{b}, then AA would have to be square and invertible, and in that case Ax=bA\mathbf{x} = \mathbf{b} has an exact solution and there was nothing to approximate.

Swapping the order of the two factors

With orthonormal columns, A=QA = Q and the projection matrix becomes QQTQQ^T. The two factors are written in the other order, QTQQ^TQ, which is the product that appears in the condition QTQ=IQ^TQ = I.

Wrong working: for Q=12(11)Q = \frac{1}{\sqrt{2}}\begin{pmatrix} 1 \\ 1 \end{pmatrix} and b=(20)\mathbf{b} = \begin{pmatrix} 2 \\ 0 \end{pmatrix},
QTQ=12(1⋅1+1⋅1)=1Q^TQ = \tfrac{1}{2}(1 \cdot 1 + 1 \cdot 1) = 1

a 1×11 \times 1 matrix. Read as the identity, it says b\mathbf{b} is its own projection, (2,0)(2, 0), although (2,0)(2, 0) does not lie on the line spanned by (1,1)(1, 1).

Right working:
P=QQT=12(1111),Pb=(11)P = QQ^T = \frac{1}{2}\begin{pmatrix} 1 & 1 \\ 1 & 1 \end{pmatrix}, \quad P\mathbf{b} = \begin{pmatrix} 1 \\ 1 \end{pmatrix}

The projection (1,1)(1, 1) lies on the line, and the residual (2,0)−(1,1)=(1,−1)(2, 0) - (1, 1) = (1, -1) is perpendicular to it.

Why it happens: QTQ=IQ^TQ = I is the identity that defines orthonormal columns, so QTQQ^TQ is the product written most often. For a square QQ both orders give II; for the tall matrices of least squares only QTQQ^TQ does.

How to check: compare sizes. PP must be m×mm \times m to multiply b∈Rm\mathbf{b} \in \mathbb{R}^m; QTQQ^TQ is n×nn \times n and QQTQQ^T is m×mm \times m. The result PbP\mathbf{b} must also lie in the column space of QQ.

Leaving out the column of ones

The model y=c0+c1xy = c_0 + c_1x is turned into a design matrix, but only the column of xix_i values is written down. The intercept c0c_0 gets no column, so the model actually fitted is y=c1xy = c_1x, a line through the origin.

Wrong working: for the points (0,1)(0, 1), (1,3)(1, 3), (2,5)(2, 5), with A=(012)A = \begin{pmatrix} 0 \\ 1 \\ 2 \end{pmatrix} and y=(135)\mathbf{y} = \begin{pmatrix} 1 \\ 3 \\ 5 \end{pmatrix},
ATA=0+1+4=5,ATy=0+3+10=13,c1=135=2.6A^TA = 0 + 1 + 4 = 5, \quad A^T\mathbf{y} = 0 + 3 + 10 = 13, \quad c_1 = \frac{13}{5} = 2.6

The fitted line y=2.6xy = 2.6x leaves the residuals 11, 0.40.4 and −0.2-0.2.

Right working: one column per coefficient, the first one all ones.
A=(101112),ATA=(3335),ATy=(913)A = \begin{pmatrix} 1 & 0 \\ 1 & 1 \\ 1 & 2 \end{pmatrix}, \quad A^TA = \begin{pmatrix} 3 & 3 \\ 3 & 5 \end{pmatrix}, \quad A^T\mathbf{y} = \begin{pmatrix} 9 \\ 13 \end{pmatrix}

Solving gives c0=1c_0 = 1 and c1=2c_1 = 2. The line y=1+2xy = 1 + 2x passes through all three points, and every residual is 00.

Why it happens: the intercept multiplies the constant 11, which does not appear anywhere in the data. Every coefficient of the model needs its own column, including the one that multiplies no variable.

How to check: count the columns, one per unknown coefficient. With a column of ones the residuals always add up to 00, because that column is orthogonal to the residual; here 1+0.4−0.2=1.21 + 0.4 - 0.2 = 1.2, so the column is missing.

Least Squares FAQ

Does x^\hat{\mathbf{x}} satisfy Ax^=bA\hat{\mathbf{x}} = \mathbf{b}?

+
Generally no, and that failure is the whole premise. Least squares exists precisely because the system has no exact solution, so x^\hat{\mathbf{x}} is the vector making the residual as small as possible rather than zero. Dropping the hat and writing Ax=bA\mathbf{x} = \mathbf{b} quietly asserts the very thing the setup denies.Read more →

Why minimise the squared norm instead of the norm itself?

+
Convenience, not a change of problem. Squaring is increasing on non-negative numbers, so ∥Ax−b∥2\|A\mathbf{x} - \mathbf{b}\|^2 and ∥Ax−b∥\|A\mathbf{x} - \mathbf{b}\| are minimised by the same x^\hat{\mathbf{x}}. What the square buys is a tractable derivative, since the square root would otherwise sit in the way. It also supplies the method's name.Read more →

Why are they called the "normal" equations?

+
Because normal here means perpendicular, pointing at the right angle in the geometry: the residual is orthogonal to the column space at the minimiser. It has nothing to do with ordinary in the everyday sense, and nothing to do with the normal distribution. That second collision is pure accident of vocabulary.Read more →