The Gram-Schmidt process takes a set of linearly independent vectors and produces an orthogonal (or orthonormal) set spanning the same subspace. It works by sequentially stripping each vector of its components along previously computed directions, leaving only the perpendicular remainder. The result is a constructive proof that orthonormal bases always exist — and the matrix version of this process is the QR decomposition.
The Goal
The input is a set of linearly independent vectors {v1,v2,…,vk} in an inner product space. The output is an orthogonal set {u1,u2,…,uk} satisfying two conditions: the vectors are pairwise perpendicular (ui⋅uj=0 for i=j), and they span the same subspace (Span{u1,…,uj}=Span{v1,…,vj} at every step j).
Optionally, each ui is normalized to unit length, producing an orthonormal set {q1,…,qk}.
The process is the constructive proof that every finite-dimensional inner product space has an orthonormal basis.
THEOREM
Given any basis, Gram-Schmidt produces an orthonormal one for the same space.
The coefficient in front of u1 is a ratio of two dot products. The numerator u1⋅v2 measures how far v2 reaches along u1, and the denominator u1⋅u1=∥u1∥2 accounts for the length of u1 itself, so rescaling u1 leaves the subtracted vector unchanged. When u1 is a unit vector the denominator equals 1, which is why the formula becomes shorter once the vectors are normalized.
The overlap removed from the second vector
The projection of this vector onto the direction already fixed is being subtracted away. What survives is orthogonal to that direction by construction, not by luck — the subtraction removes precisely the component that would have made the dot product non-zero. Watch the next vector go through the same treatment on the Gram-Schmidt visualizer.
The general case below repeats this step once per vector already fixed, which is the only way the algorithm grows.
Projecting v3=(0,1,1) onto v1=(1,1,0) and v2=(1,0,1) instead of onto u1,u2 gives (−1,21,21), whose dot product with u1 is −21. Projecting onto the ui gives u3=(−32,32,32).
At each step, vj has its projections onto all previously computed orthogonal vectors subtracted. What remains is the component of vj perpendicular to Span{u1,…,uj−1}.
Because vj is independent of {v1,…,vj−1} — and therefore not in Span{u1,…,uj−1} — this perpendicular component is nonzero. So each uj=0, and the process never breaks down.
At every stage, Span{u1,…,uj}=Span{v1,…,vj}. The span is preserved because each uj is a linear combination of vj and the earlier ui's (which are themselves combinations of v1,…,vj−1).
Gram-Schmidt Notation
Notation
Gram-Schmidt Notation
An algorithm's notation has to record not just what the objects are but the order they were built in — so this page runs three letters for three stages of the same vector, and a sum whose upper limit moves with the step it appears in. All catalogued among the linear algebra symbols.
Three letters for three stages of the same vector: vj is what you started with, uj what survives after the projections are removed, and ej the unit version — Normalization below performs that last step. The subscript stays fixed across all three; only the letter records how far the vector has been processed.
CasesSources that skip the orthogonal stage write qj directly for the normalised output, matching the Q of the decomposition below; others reuse vj throughout and overwrite in place, which is how the algorithm is actually implemented but loses the ability to refer to an earlier stage.
Do not confuseej as a standard basis vector. Here it is the j-th vector this process produced, not the j-th axis — the letter is borrowed for "unit vector", and only the surrounding construction says which unit vector is meant.
uj=vj−∑i=1j−1projui(vj)
subtract the projections onto everything built so far
The upper limit is the notational content: j−1 means everything already constructed, so the sum's length grows as the algorithm proceeds and the formula refers to its own earlier outputs. This is a recursive definition written as a formula, not a closed expression.
CasesThe first step is the empty case — at j=1 the sum has no terms, which is why u1=v1 needs no separate rule; and the projections are onto the ui, never the vi, which is the one substitution that silently breaks the algorithm.
Do not confuseA fixed sum over all k vectors. Reading the limit as k rather than j−1 asks the formula to use vectors that do not exist yet — the range is the whole reason the construction terminates.
A=QR
A factors into an orthonormal Q and an upper-triangular R
Letters as a contract, in the family pattern decomposition notation describes: Q carries the orthonormal columns this process produces, R collects the coefficients it discarded along the way — The QR Decomposition below reads them off directly.
CasesR comes out upper triangular for a reason the notation encodes: vj is built only from u1,…,uj, so every entry below the diagonal is a coefficient that was never used.
Do not confuseR as the real numbers. Blackboard R is the field; italic R here is one specific triangular matrix, and the two sit close together in exactly the equations where both appear.
After computing the orthogonal set {u1,…,uk}, normalization produces an orthonormal set:
Normalization
qi=∥ui∥ui
Each vector is divided by its length, making ∥qi∥=1 while preserving direction. The resulting set satisfies qi⋅qj=δij.
Pitfall: Normalizing the inputs first
Scaling v1,v2 to 21(1,1,0) and 21(1,0,1) before orthogonalizing gives 21(21,−21,1), of length 23, not 1. Normalizing after the subtraction gives q2=61(1,−1,2).
Normalization can be done at each step (normalize uj immediately before moving to vj+1) or all at the end. The result is the same in exact arithmetic. In practice, normalizing at each step is slightly preferable for numerical stability, as it keeps the vectors well-scaled throughout the computation.
Scaling the survivor to unit length
Orthogonality was settled by the subtraction; this step only fixes the length. Splitting the two concerns is why the algorithm can be stated for an orthogonal basis and then upgraded to an orthonormal one without changing its structure. Toggle normalisation on and off on the Gram-Schmidt visualizer.
Dividing by a very small length is where the classical algorithm loses accuracy, which is the subject of the stability section later.
Check: u1⋅u3=−21+0+21=0 and u2⋅u3=−61+0+61=0.
Normalizing: ∥u1∥=3, ∥u2∥=6/3, ∥u3∥=1/2. The orthonormal basis is {u1/3,3u2/6,2u3}.
To run Gram-Schmidt on your own set of vectors, use the vector calculator.
Why It Works
At each step, uj is constructed as vj minus everything in vj that lies in the subspace Wj−1=Span{u1,…,uj−1}. Since {u1,…,uj−1} is orthogonal, the projection formula decomposes cleanly into independent terms — one projection per basis vector.
What remains after subtraction is the component of vjorthogonal to Wj−1. This component is nonzero because vj∈/Wj−1 — guaranteed by the independence of the original set.
The span is preserved at each step. Each uj is a linear combination of vj and u1,…,uj−1, and each earlier ui is a combination of v1,…,vi. So uj∈Span{v1,…,vj}, and the reverse inclusion follows because vj can be recovered from uj and the earlier ui's.
Independence guarantees that something survives each subtraction, and the subtraction guarantees that what survives is perpendicular.
The QR Decomposition
Applying Gram-Schmidt to the columns a1,…,an of an m×nmatrixA (with independent columns) produces the QR decomposition:
Q is m×n with orthonormal columns (the normalized qi's). R is n×n upper triangular with positive diagonal entries.
The entries of R are the dot products computed during Gram-Schmidt: Rij=qi⋅aj for i≤j, and Rij=0 for i>j (because aj lies in the span of q1,…,qj, so it is perpendicular to qi when i>j).
The factorization captures two complementary pieces of information. Q stores the orthonormal directions. R stores the coefficients that express the original columns in terms of those directions: aj=R1jq1+R2jq2+⋯+Rjjqj.
Running Gram–Schmidt on the columns of A produces both factors at once. Q is the output and R is the bookkeeping — the coefficients that were subtracted along the way, kept rather than discarded.
the coefficients discarded during orthogonalization
This is why QR is not a separate algorithm from Gram–Schmidt so much as its record. Every projection coefficient computed during orthogonalization is an entry of R, and R is triangular precisely because vj is only ever projected onto vectors that came before it.
The triangularity of R is worth seeing as a consequence rather than a condition. At step j the algorithm projects vj onto q1,…,qj−1 and no others, so every coefficient with i>j is zero because that projection was never computed. Nothing was imposed on the shape — it fell out of processing the columns in order.
The same run, recorded as two factors
The orthonormal vectors produced have become the columns of Q, and the coefficients subtracted along the way have become the entries of R. The triangularity of R is not imposed: it reflects the fact that each vector was only ever corrected against the ones before it. Compare the two views on the QR decomposition visualizer.
Gram-Schmidt and QR are therefore one computation with two names, depending on whether the vectors or the factors are what you are after.
QR and Least Squares
The QR decomposition provides a numerically superior method for solving least-squares problems.
The normal equations ATAx^=ATb can be rewritten using A=QR. Since ATA=RTQTQR=RTR and ATb=RTQTb, the normal equations become RTRx^=RTQTb. Canceling RT (which is invertible since R has positive diagonal):
QR and Least Squares
Rx^=QTb
This is an upper triangular system, solved by back substitution. The computation QTb is just n dot products (one per column of Q).
The QR approach avoids forming ATA explicitly. This matters because the condition number of ATA is the square of the condition number of A — squaring amplifies rounding errors. Working with Q and R directly preserves the original conditioning and is the standard method for least squares in numerical software.
Numerical Stability
Fact: Perpendicular on paper, 60∘ on a computer
Run classical Gram-Schmidt in double precision on (1,ε,0,0), (1,0,ε,0), (1,0,0,ε) with ε=10−8: since 1+ε2 rounds to 1, the last two outputs come out with q2⋅q3=21, an angle of 60∘. The modified version, on the same input, gives q2⋅q3≈10−16.
Classical Gram-Schmidt (as presented above) can lose orthogonality in floating-point arithmetic. When the input vectors are nearly dependent, the computed uj's may fail to be perpendicular to machine precision, and the errors accumulate with each step.
Modified Gram-Schmidt addresses this by reorganizing the computation. Instead of computing all projections using the original vj, modified Gram-Schmidt updates vj in place after each projection is subtracted. At step j, first subtract the projection onto u1 from vj, then subtract the projection onto u2 from the updated vj, and so on. The mathematical result is identical in exact arithmetic, but the modified version is significantly more stable numerically.
Householder reflections provide an even more robust alternative for computing the QR factorization. Householder-based QR achieves backward stability — the gold standard in numerical linear algebra — and is the default algorithm in most software libraries.
Method
How it computes the orthogonal set / QR
Numerical stability
Typical use
Classical Gram–Schmidt
at step j, all projections of the original vj onto u1, …, uj−1 are computed and subtracted at once
poor — orthogonality can be lost when input vectors are nearly dependent; errors accumulate
textbook / illustrative use; abstract inner product spaces where exact arithmetic is available
Modified Gram–Schmidt
vj is updated in place after each individual projection is subtracted
significantly better than classical; identical result in exact arithmetic
educational software, moderate-precision floating-point work
Householder reflections
a sequence of orthogonal reflections is applied to A to zero out below-diagonal entries column by column
backward stable — the gold standard in numerical linear algebra
default QR routine in LAPACK, NumPy, MATLAB, and most numerical libraries
Givens rotations
a sequence of 2 × 2 plane rotations zeros out individual entries one at a time
backward stable; lets the algorithm target nonzero entries only
sparse matrices with structured zeros; updating an existing QR factorization
Formulas that agree in exact arithmetic can behave very differently on a computer: the order of the subtractions matters.
Gram-Schmidt on Abstract Inner Product Spaces
The algorithm works in any inner product space — the dot product is replaced by the general inner product ⟨⋅,⋅⟩, and the formulas are otherwise identical:
Gram-Schmidt on Abstract Inner Product Spaces
uj=vj−i=1∑j−1⟨ui,ui⟩⟨ui,vj⟩ui
Pitfall: Using the dot product of coefficients
Treating 1 and x2 as coefficient lists (1,0,0) and (0,0,1) gives dot product 0, so x2 is kept unchanged, although ∫−111⋅x2dx=32=0. With the integral inner product the third vector is x2−31.
Orthogonalizing {1,x,x2} in the polynomial space P2 with the inner product ⟨p,q⟩=∫−11p(x)q(x)dx produces the Legendre polynomials (up to normalization): P0(x)=1, P1(x)=x, P2(x)=21(3x2−1). The polynomial x is already orthogonal to 1 under this inner product (the integral of an odd function over a symmetric interval is zero), so the first subtraction has no effect.
On the function space C[0,2π] with ⟨f,g⟩=∫02πf(x)g(x)dx, orthogonalizing appropriate function sets produces Fourier bases. The algorithm is identical in structure to the Rn version — only the inner product changes.
Summary: Gram-Schmidt Across Settings
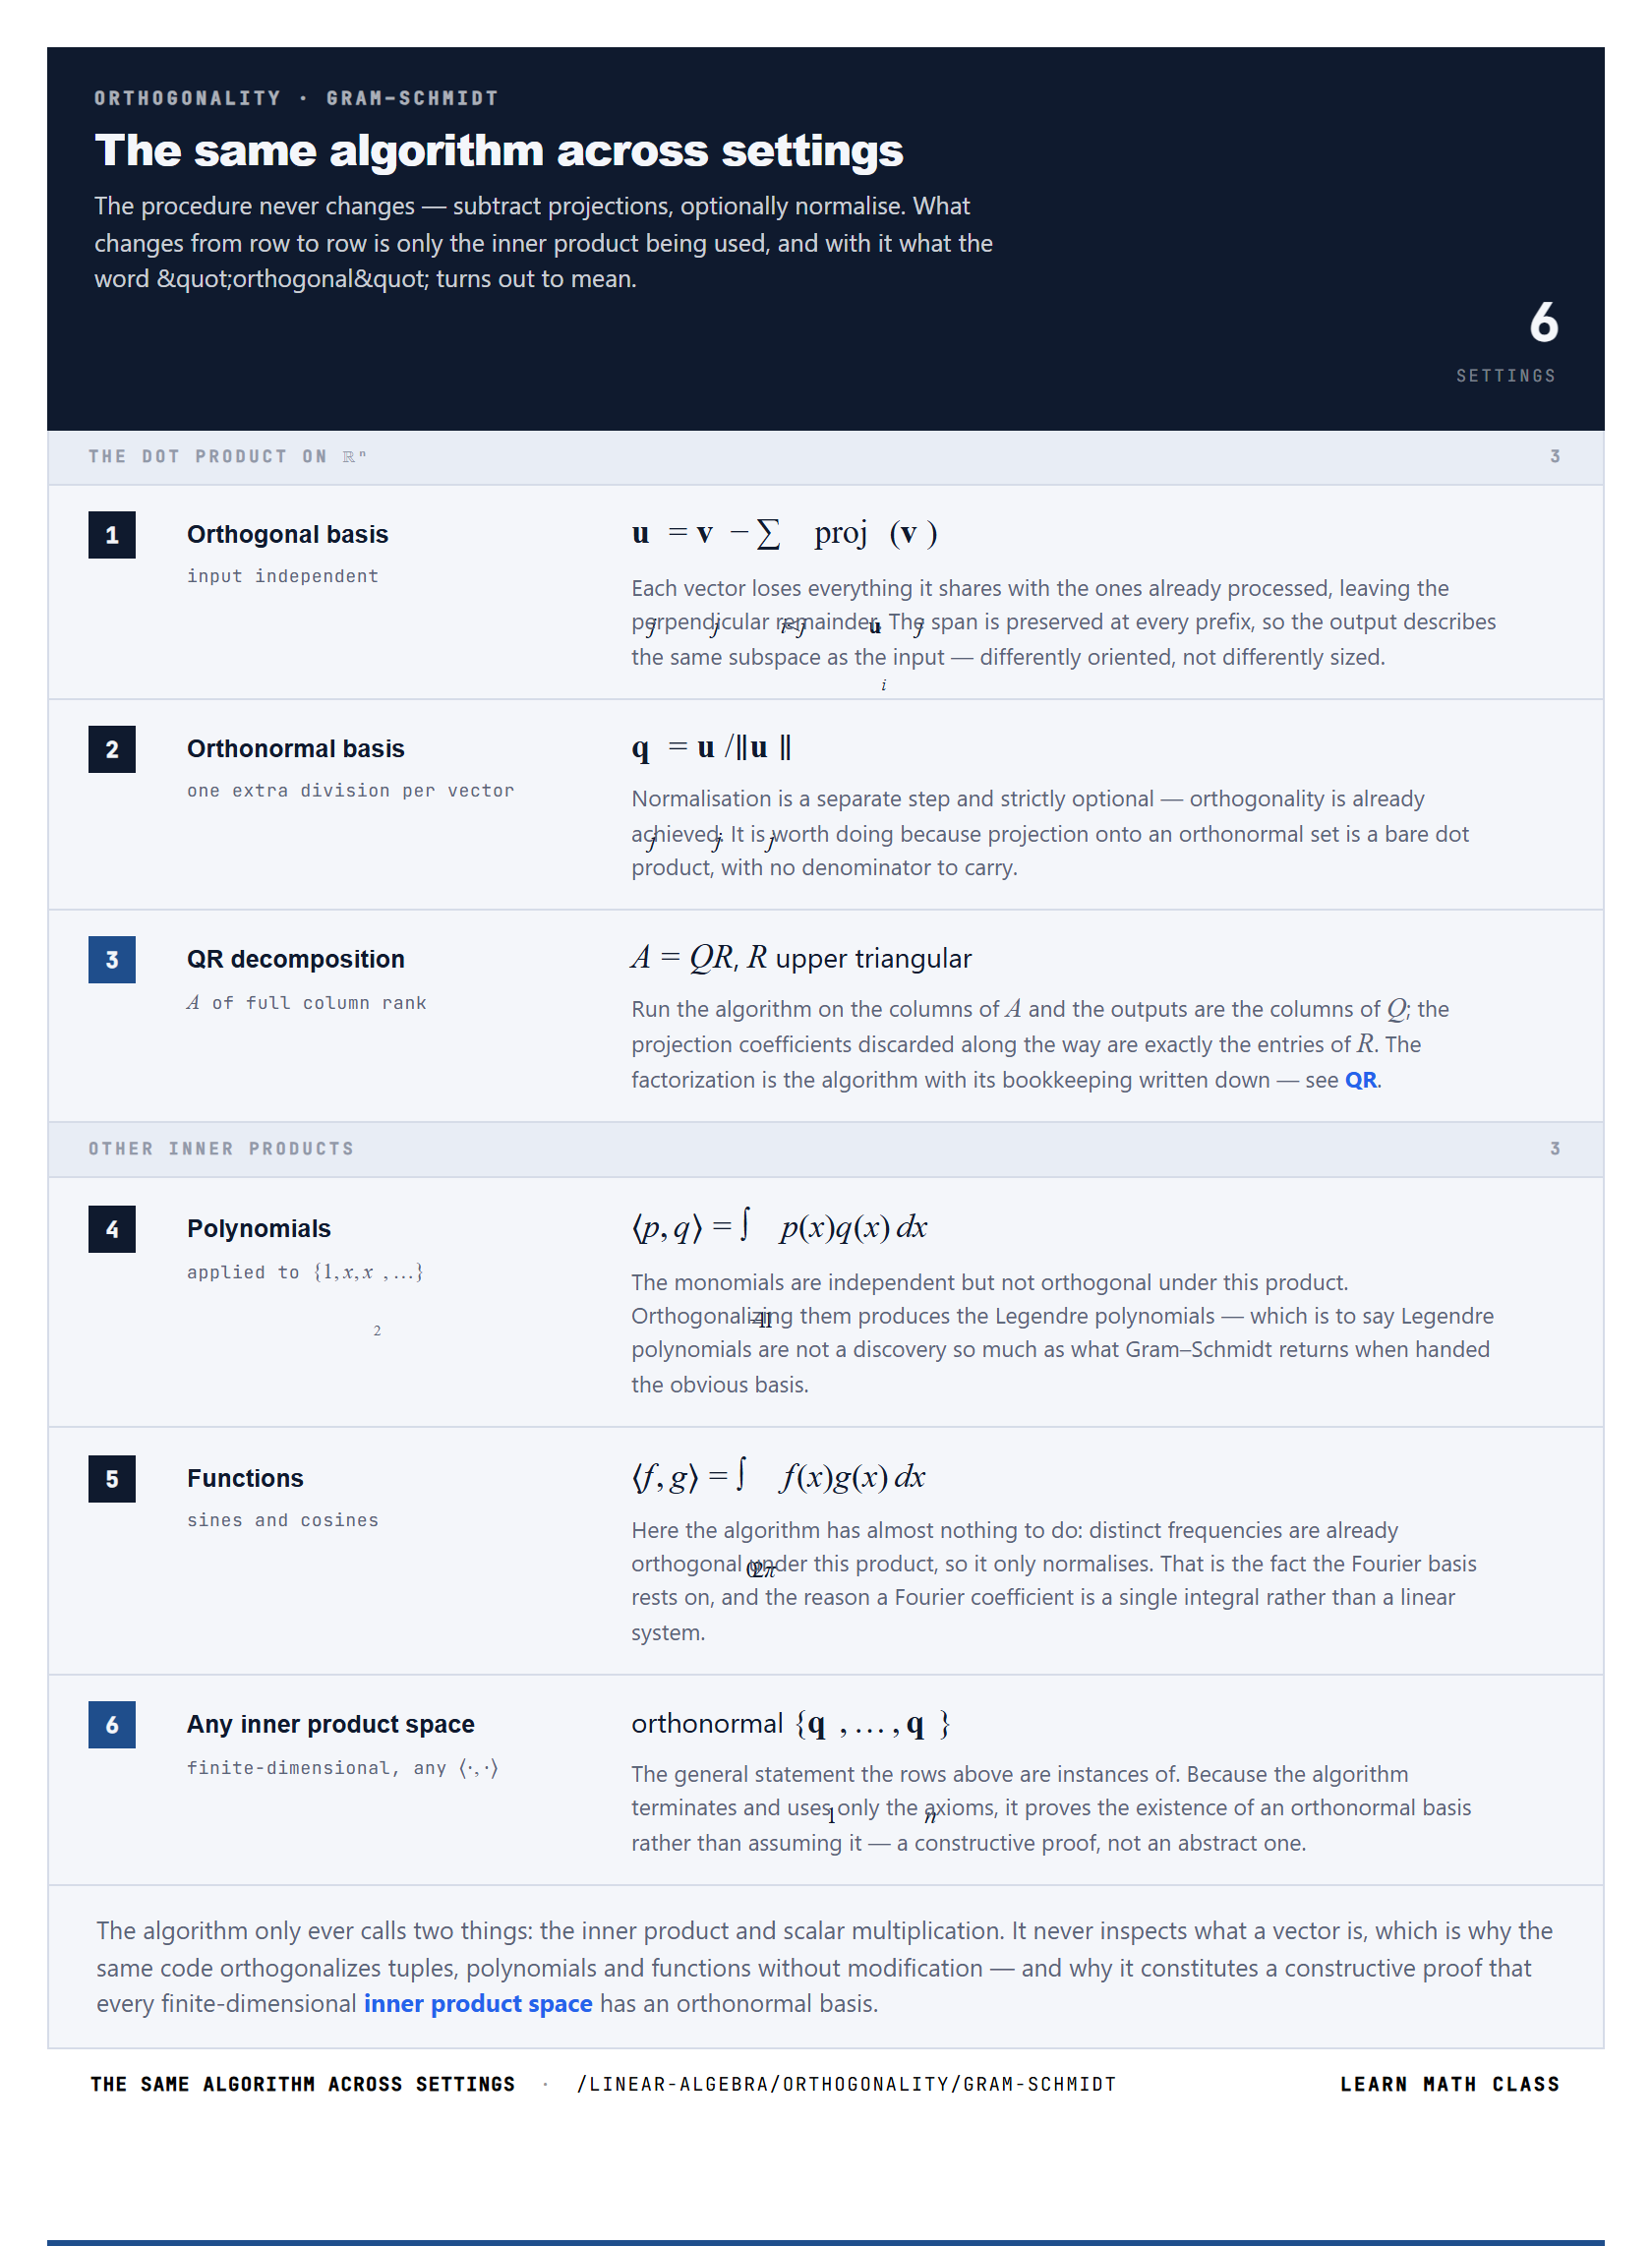
Gram-Schmidt operates uniformly across many settings — ℝⁿ with the standard dot product, polynomial spaces with integral inner products, function spaces in Fourier analysis, and abstract inner product spaces in general. The table below collects the main contexts in which the process is applied, alongside the input, the inner product used, and what the algorithm produces in each case.
What follows is one algorithm listed six times. The steps are identical in every row — subtract the projections onto what has already been processed, then optionally divide by the length. The only thing that varies is which inner product those projections are computed with, and the grouping below separates the familiar dot product from the integrals that replace it elsewhere.
The procedure never changes — subtract projections, optionally normalise. What changes from row to row is only the inner product being used, and with it what the word "orthogonal" turns out to mean.
Each vector loses everything it shares with the ones already processed, leaving the perpendicular remainder. The span is preserved at every prefix, so the output describes the same subspace as the input — differently oriented, not differently sized.
Normalisation is a separate step and strictly optional — orthogonality is already achieved. It is worth doing because projection onto an orthonormal set is a bare dot product, with no denominator to carry.
Run the algorithm on the columns of A and the outputs are the columns of Q; the projection coefficients discarded along the way are exactly the entries of R. The factorization is the algorithm with its bookkeeping written down — see QR.
The monomials are independent but not orthogonal under this product. Orthogonalizing them produces the Legendre polynomials — which is to say Legendre polynomials are not a discovery so much as what Gram–Schmidt returns when handed the obvious basis.
Here the algorithm has almost nothing to do: distinct frequencies are already orthogonal under this product, so it only normalises. That is the fact the Fourier basis rests on, and the reason a Fourier coefficient is a single integral rather than a linear system.
The general statement the rows above are instances of. Because the algorithm terminates and uses only the axioms, it proves the existence of an orthonormal basis rather than assuming it — a constructive proof, not an abstract one.
The algorithm only ever calls two things: the inner product and scalar multiplication. It never inspects what a vector is, which is why the same code orthogonalizes tuples, polynomials and functions without modification — and why it constitutes a constructive proof that every finite-dimensional inner product space has an orthonormal basis.
Under ⟨p,q⟩=∫−11p(x)q(x)dx, the cosine of the angle between x8 and x10 is 19357≈0.994, about 6∘. High powers look almost alike on [−1,1], so the monomials are close to dependent and Gram-Schmidt removes most of each higher power.
The second group is where the generality earns its keep. Under the integral inner product on [−1,1] the monomials 1,x,x2 are independent but not orthogonal, and orthogonalizing them yields the Legendre polynomials — so those are not a separate construction but simply what this algorithm returns when handed the obvious basis. Under the inner product on [0,2π], sines and cosines of distinct frequencies are already orthogonal, and the algorithm finds nothing to subtract.
That last observation is why a Fourier coefficient is a single integral rather than the solution of a linear system: the basis was orthogonal before anyone asked. The algorithm never inspects what a vector is — it calls the inner product and scalar multiplication and nothing else — which is what lets the same procedure serve tuples, polynomials and functions, and what makes it a constructive proof that every finite-dimensional inner product space has an orthonormal basis.
Common Pitfalls
Four slips account for many wrong Gram-Schmidt computations. Each is marked with a box where it happens in the sections above. Here each is worked through in full, with the wrong and the right working side by side.
Dropping the denominator
The coefficient of u1 is taken as the dot product u1⋅v2 alone, as if u1 had length 1. The subtracted vector then has the wrong length, and what remains is not perpendicular to u1.
Wrong working: with v1=(1,1,0) and v2=(1,0,1),
u2=v2−(u1⋅v2)u1=(1,0,1)−1⋅(1,1,0)=(0,−1,1)
and u1⋅u2=0−1+0=−1.
Right working: u1⋅u1=2, so
u2=(1,0,1)−21(1,1,0)=(21,−21,1)
and u1⋅u2=21−21+0=0.
Why it happens: the orthonormal version of the formula, (qi⋅vj)qi, has no denominator, and it is used for vectors that have not been normalized.
How to check: take the dot product of the new vector with every earlier one. Each product must be 0.
Projecting onto the original vectors
At step j, the projections are taken onto the inputs v1,…,vj−1 instead of onto the orthogonal vectors u1,…,uj−1 already built. At j=2 nothing changes, because u1=v1, so the error first shows at j=3.
Wrong working: with v1=(1,1,0), v2=(1,0,1) and v3=(0,1,1),
Then u1⋅u3=−32+32+0=0 and u2⋅u3=−31−31+32=0.
Why it happens: the inputs are the vectors the problem states, so they are the ones at hand. But a sum of projections onto single vectors gives the projection onto their span only when those vectors are orthogonal, and v1⋅v2=1=0.
How to check: test the new vector against all earlier ui, not only the last one. The wrong vector above fails against u1.
Normalizing the inputs first
The inputs are scaled to unit length before the process runs, in the hope that the output will then be orthonormal. The subtractions change the lengths again: each uj with j≥2 is shorter than the vector it came from, unless that vector was already perpendicular to the earlier ones.
Wrong working: scale to q1=21(1,1,0) and 21(1,0,1). The dot product of the two is 21, so the second output is
21(1,0,1)−21⋅21(1,1,0)=21(21,−21,1)
of length 21⋅23=23, not 1.
Right working: orthogonalize first, u2=(21,−21,1) with ∥u2∥=23, then divide:
q2=∥u2∥u2=61(1,−1,2)
which has length 61+1+4=1.
Why it happens: normalization looks like a preparation step that can be done at any point, but subtracting a projection shortens a vector.
How to check: compute the length of every output vector. In an orthonormal set each length is exactly 1, and here the second one is about 0.87.
Using the dot product of coefficients
In a polynomial space with an integral inner product, the polynomials are written as lists of coefficients and the ordinary dot product is used. Under that dot product 1,x,x2 are already orthonormal, so the process changes nothing.
Wrong working: 1→(1,0,0), x→(0,1,0) and x2→(0,0,1). All dot products are 0, so the output is 1,x,x2 unchanged. But
⟨1,x2⟩=∫−11x2dx=32=0
so 1 and x2 are not orthogonal under the inner product of the problem.
Right working: ⟨1,1⟩=2, ⟨1,x2⟩=32 and ⟨x,x2⟩=∫−11x3dx=0, so the third vector is
x2−22/3⋅1−0⋅x=x2−31
which is 32P2(x).
Why it happens: in Rn the dot product is the only inner product in use, and a coefficient list looks exactly like a vector in R3.
How to check: compute one inner product of the result with an earlier vector, using the integral. Here ∫−11(x2−31)dx=32−32=0.
Gram-Schmidt FAQ
Why does the sum stop at j−1 rather than running over all the vectors?
+
Because the later vectors have not been produced yet. At step j only u1 through uj−1 exist, so a fixed upper limit would ask the formula to use things that do not exist. The moving limit is also why the construction terminates, and at j=1 the empty sum makes u1=v1 automatic.Read more →
Are the ej here the standard basis vectors?
+
No, they are the unit vectors this process produced, not the coordinate axes. The letter is borrowed for its association with unit length, and only the surrounding construction says which unit vector is meant. Watch the projections too: they must be onto the ui, never the original vi, which is the substitution that silently breaks the algorithm.Read more →
Why does R come out upper triangular?
+
Because of what the algorithm builds. Each vj is assembled from only the first j orthogonal vectors, so any coefficient below the diagonal would refer to a vector that never contributed. Those entries are zero not by construction but by absence. Note that italic R here is one triangular matrix, unrelated to blackboard R.Read more →