Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Decompositions


Factoring Matrices into Simpler Pieces

A matrix decomposition writes a matrix as a product of simpler matrices — triangular, diagonal, orthogonal, or some combination — whose structure makes subsequent computation cheap. The upfront cost of factoring is repaid every time the factors are used to solve a system, compute eigenvalues, approximate data, or analyze stability. Decompositions are the computational backbone of applied linear algebra.


What a Decomposition Is

A matrix decomposition (or factorization) expresses a matrix AA as a product of two or more matrices with known, exploitable structure. The factors are typically triangular, diagonal, or orthogonal — matrices for which solving systems, computing determinants, and extracting eigenvalues are either trivial or dramatically simplified.

Fact: A way of working made the top ten
In 2000 the journal Computing in Science and Engineering named the ten algorithms most influential on 20th-century science. One entry was not a single algorithm but the decompositional approach itself, formalized by Alston Householder in 1951: factor the matrix, then reuse the factors.

A decomposition does not change the matrix. It reveals the internal structure of AA by splitting it into interpretable components. The product of the factors always reproduces AA exactly — the information is rearranged, not altered.

Every decomposition represents a trade: an upfront cost to compute the factors, followed by cheap operations that use them. The factorization is done once; the payoff is reaped every time the factors are applied.

The same factors serve many different questions. A single LU factorization solves a system for any right-hand side, gives the determinant from the diagonal of UU, and builds the inverse column by column; a single SVD gives the rank, the pseudoinverse and the best low-rank approximation at once. The work goes into finding the structure, and the answers are then read off it.

Why Decompositions Matter

Decompositions transform hard problems into sequences of easy ones.

Solving linear systems: the LU decomposition converts a single factorization into cheap triangular solves for any number of right-hand sides. The Cholesky decomposition does the same at half the cost when the matrix is symmetric positive definite.

Least squares: the QR decomposition avoids squaring the condition number, providing a numerically stable solution to overdetermined systems.

Eigenvalue computation: the QR algorithm — an iterative process built on repeated QR factorizations — is the standard method for finding eigenvalues of general matrices, entirely avoiding the characteristic polynomial.

Dimensionality reduction: the singular value decomposition identifies the most important directions in the data and discards the rest, enabling compression, noise removal, and low-rank approximation.

Numerical stability: orthogonal factors (QQ in QR, UU and VV in SVD) preserve lengths and condition numbers, keeping rounding errors under control throughout the computation.

LU Decomposition

The LU decomposition factors a square matrix as A=LUA = LU (or PA=LUPA = LU with row pivoting), where LL is lower triangular and UU is upper triangular. It captures the entire process of Gaussian elimination in matrix form: UU is the echelon form, and LL stores the multipliers used during elimination.

Solving Ax=bA\mathbf{x} = \mathbf{b} reduces to two triangular substitutions — forward (Ly=bL\mathbf{y} = \mathbf{b}) then backward (Ux=yU\mathbf{x} = \mathbf{y}) — each costing O(n2)O(n^2). The factorization itself costs 23n3\frac{2}{3}n^3, but each additional right-hand side costs only O(n2)O(n^2). For kk systems sharing the same coefficient matrix, LU amortizes the dominant cost over all kk solves.

QR Decomposition

The QR decomposition factors an m×nm \times n matrix as A=QRA = QR, where QQ has orthonormal columns and RR is upper triangular. It is produced by the Gram-Schmidt process, by Householder reflections, or by Givens rotations.

QR is the standard method for least-squares problems: the normal equations ATAx^=ATbA^TA\hat{\mathbf{x}} = A^T\mathbf{b} simplify to the triangular system Rx^=QTbR\hat{\mathbf{x}} = Q^T\mathbf{b}, avoiding the condition-number-squaring that comes from forming ATAA^TA directly.

The QR algorithm for eigenvalues — an iterative scheme that repeatedly factors and recombines — converges to the eigenvalues of a general matrix without computing the characteristic polynomial. It is the dominant eigenvalue algorithm in numerical software.

Cholesky Decomposition

The Cholesky decomposition factors a symmetric positive definite matrix as A=LLTA = LL^T, where LL is lower triangular with positive diagonal entries. It exists if and only if AA is symmetric positive definite — all eigenvalues strictly positive and A=ATA = A^T.

Cholesky exploits symmetry to achieve half the cost of LU: 13n3\frac{1}{3}n^3 versus 23n3\frac{2}{3}n^3. Only the lower triangle of AA is read, and only LL is computed — the upper factor LTL^T is just the transpose.

THEOREM
Cholesky requires no pivoting. Positive definiteness guarantees that every diagonal entry encountered during the algorithm is strictly positive, so no zero pivots can occur.

If the algorithm breaks down (a non-positive value under the square root), the matrix is not positive definite — the decomposition doubles as a definiteness test.

Pitfall: Applying Cholesky to any symmetric matrix
Starting Cholesky on the symmetric A=(1221)A = \begin{pmatrix} 1 & 2 \\ 2 & 1 \end{pmatrix} gives l11=1l_{11} = 1, l21=2l_{21} = 2, then l222=1−4=−3l_{22}^2 = 1 - 4 = -3, with no real square root. The eigenvalues of AA are 33 and −1-1, so it is not positive definite and has no Cholesky factor.

The two conditions are checked in different ways. Symmetry can be read directly from the entries, since each aija_{ij} must equal ajia_{ji}. Positive definiteness cannot be seen entry by entry: it is a property of the whole matrix, carried by the signs of its eigenvalues or, equivalently, of its leading principal minors.

Spectral Decomposition

The spectral decomposition factors a real symmetric matrix as A=QDQTA = QDQ^T, where QQ is orthogonal and DD is diagonal. This is the diagonalization of a symmetric matrix, with the additional guarantee that the diagonalizing matrix QQ is orthogonal — not merely invertible.

Pitfall: Using the spectral form on a non-symmetric matrix
For A=(2101)A = \begin{pmatrix} 2 & 1 \\ 0 & 1 \end{pmatrix}, with eigenvalues 22 and 11 and unit eigenvectors as the columns of QQ, the product is QDQT=(5/2−1/2−1/21/2)≠AQDQ^T = \begin{pmatrix} 5/2 & -1/2 \\ -1/2 & 1/2 \end{pmatrix} \neq A. These eigenvectors are not orthogonal, so the factorization is A=PDP−1A = PDP^{-1}.

In outer product form, A=λ1q1q1T+λ2q2q2T+⋯+λnqnqnTA = \lambda_1 \mathbf{q}_1\mathbf{q}_1^T + \lambda_2 \mathbf{q}_2\mathbf{q}_2^T + \cdots + \lambda_n \mathbf{q}_n\mathbf{q}_n^T. Each term is the eigenvalue times the projection matrix onto the corresponding eigenvector direction. The matrix is decomposed into a sum of independent rank-one projections, weighted by eigenvalues.

The spectral decomposition is the foundation of quadratic form analysis, principal component analysis, and the classification of symmetric matrices as positive definite, positive semi-definite, or indefinite.

Singular Value Decomposition

The singular value decomposition factors any m×nm \times n matrix as A=UΣVTA = U\Sigma V^T, where UU and VV are orthogonal and Σ\Sigma is diagonal with non-negative entries (the singular values). It exists for every matrix of every shape and every rank.

The SVD is the most informative factorization in linear algebra. The number of nonzero singular values equals the rank. The columns of UU and VV provide orthonormal bases for all four fundamental subspaces. The pseudoinverse is A+=VΣ+UTA^+ = V\Sigma^+ U^T. The best rank-kk approximation to AA is obtained by truncating the SVD at kk terms. The condition number is σ1/σr\sigma_1/\sigma_r.

Pitfall: Counting nonzero eigenvalues for the rank
Both eigenvalues of A=(0100)A = \begin{pmatrix} 0 & 1 \\ 0 & 0 \end{pmatrix} are 00, which suggests rank 00. Its singular values are 11 and 00, so the rank is 11, as the nonzero column shows.

Geometrically, every linear transformation is a rotation or reflection (VTV^T), followed by a coordinate-axis scaling (Σ\Sigma), followed by another rotation or reflection (UU). The SVD makes this decomposition explicit.
A2×23045=U2×20.31620.94870.9487−0.3162·Σ2×26.7082002.2361·Vᵀ2×20.70710.70710.7071−0.7071
The one factorisation every matrix has

Two orthogonal factors with a rectangular diagonal between them. Of the five decompositions catalogued on this page, this is the only one that demands nothing of its input — no squareness, no symmetry, no positive definiteness, no full set of eigenvectors. Compare its cost against the others on the SVD visualizer.

The cheaper factorisations above are worth using precisely when their conditions happen to hold; this one is the fallback when they do not.

Choosing the Right Decomposition

The choice of decomposition depends on the matrix structure and the question being asked.

For a square invertible system with one or many right-hand sides, LU is the standard choice — factor once, solve cheaply. For a symmetric positive definite system, Cholesky is faster and more stable. For a least-squares problem or an overdetermined system, QR avoids condition-number issues. For eigenvalues of a symmetric matrix, the spectral decomposition gives real eigenvalues and orthogonal eigenvectors. For rank determination, the pseudoinverse, low-rank approximation, or any problem where the matrix may be rectangular or rank-deficient, the SVD is the universal tool.

More specialized decompositions exist for more specialized structures. Banded matrices have banded LU factors. Sparse matrices benefit from fill-reducing permutations. Iterative methods (Krylov subspace methods) avoid explicit factorization entirely for very large systems. But the five decompositions on this page cover the vast majority of problems encountered in a standard linear algebra course and in applied work.

The decision compresses into a single lookup keyed on the type of problem at hand.
Problem / Matrix context Best decomposition Why
General square system, one or many right-hand sides LU (with pivoting if needed) factor once, then cheap forward/back substitution per right-hand side
Symmetric positive definite system Cholesky half the cost of LU, no pivoting required, doubles as a definiteness test
Least squares / overdetermined system QR avoids the condition-number squaring of the normal equations
Symmetric eigenvalue problem Spectral guarantees real eigenvalues and an orthogonal eigenvector basis
Rectangular, rank-deficient, or unknown structure SVD universal — exists for every matrix; reveals rank, pseudoinverse, low-rank approximation, and condition number

Relationships Between Decompositions

The five decompositions are not independent — each can be viewed as a refinement or generalization of another.

LU is Gaussian elimination recorded as a matrix product. QR is Gram-Schmidt recorded as a matrix product. Cholesky is the symmetric-positive-definite specialization of LU: when A=ATA = A^T with positive eigenvalues, the factorization A=LDLTA = LDL^T compresses into A=LLTA = LL^T by absorbing D\sqrt{D} into LL.

The spectral decomposition is eigendecomposition restricted to symmetric matrices, where the eigenvector matrix is guaranteed to be orthogonal. The SVD generalizes the spectral decomposition to non-symmetric and non-square matrices: for a symmetric positive semi-definite matrix, the SVD and spectral decomposition coincide.

Each decomposition occupies a specific niche — defined by the matrix structure it requires and the information it provides — but they are all connected through the common themes of triangularity, orthogonality, and diagonality.

Summary: The Five Decompositions Side by Side

The five decompositions covered above admit a single side-by-side comparison along four structural attributes: the algebraic form, the kind of matrix each one accepts, the structure of the factors it produces, and the primary application it enables. The table below collects this comparison as one reference card — useful both for orienting a new problem to the right factorization and for seeing how the family of decompositions is organized as a whole.
Decomposition Form Matrix requirement Factor structure Key application
LU A = LU (or PA = LU) square; pivoting handles general invertible L lower triangular, U upper triangular solving linear systems, especially with multiple right-hand sides
QR A = QR any m × n with linearly independent columns Q with orthonormal columns, R upper triangular least squares; iterative algorithm for eigenvalues
Cholesky A = LLT symmetric positive definite L lower triangular with positive diagonal SPD systems at half LU cost; positive-definiteness test
Spectral A = QDQT real symmetric Q orthogonal (eigenvectors), D diagonal of eigenvalues symmetric eigenproblems, quadratic forms, PCA
SVD A = UΣVT any m × n — no restriction U, V orthogonal; Σ diagonal of non-negative singular values rank, pseudoinverse, low-rank approximation, condition number
DownloadPNG2×PDF
Before you read
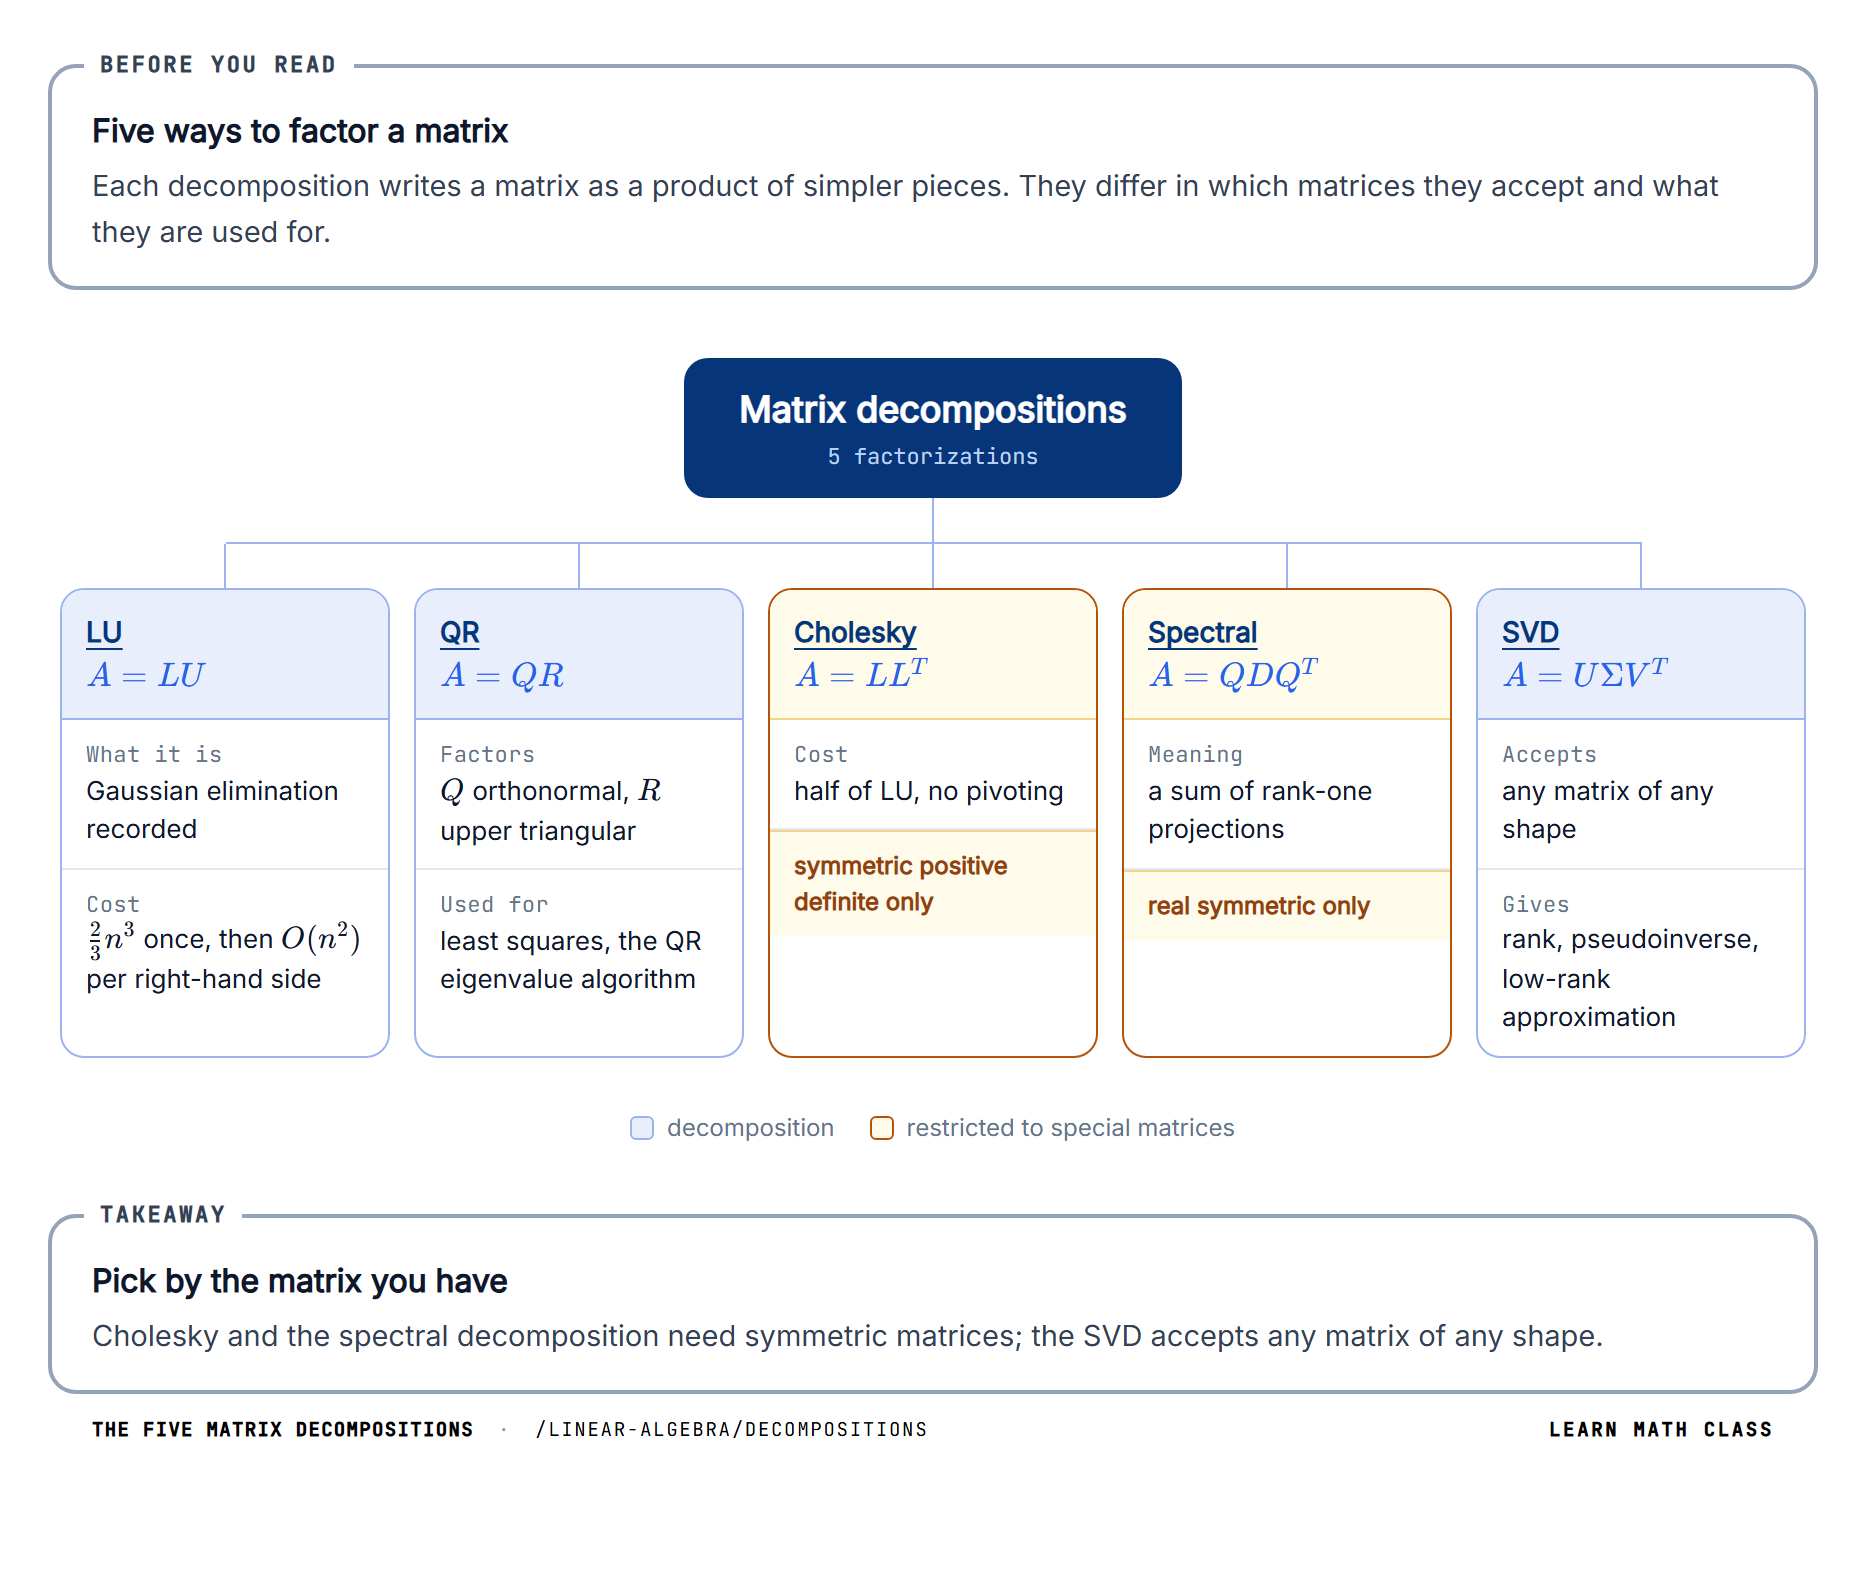
Five ways to factor a matrix
Each decomposition writes a matrix as a product of simpler pieces. They differ in which matrices they accept and what they are used for.
Matrix decompositions5 factorizations
LUA=LUA = LU
What it isGaussian elimination recorded
Cost23n3\frac{2}{3}n^3 once, then O(n2)O(n^2) per right-hand side
QRA=QRA = QR
FactorsQQ orthonormal, RR upper triangular
Used forleast squares, the QR eigenvalue algorithm
CholeskyA=LLTA = LL^T
Costhalf of LU, no pivoting

symmetric positive definite only

SpectralA=QDQTA = QDQ^T
Meaninga sum of rank-one projections

real symmetric only

SVDA=UΣVTA = U\Sigma V^T
Acceptsany matrix of any shape
Givesrank, pseudoinverse, low-rank approximation
decompositionrestricted to special matrices
Takeaway
Pick by the matrix you have
Cholesky and the spectral decomposition need symmetric matrices; the SVD accepts any matrix of any shape.
The five matrix decompositions·/linear-algebra/decompositionsLearn Math Class

Common Pitfalls

Three mistakes come from using a decomposition outside the conditions it needs, or from reading the wrong numbers off it. Each is marked with a box where it happens in the sections above; here each is worked through in full.

Applying Cholesky to any symmetric matrix

A symmetric matrix is factored as A=LLTA = LL^T because it is symmetric, without checking that it is positive definite. The algorithm then reaches a negative number under a square root, or the sign is quietly dropped to keep going.

Wrong working: for A=(1221)A = \begin{pmatrix} 1 & 2 \\ 2 & 1 \end{pmatrix}, l11=1=1l_{11} = \sqrt{1} = 1 and l21=2/1=2l_{21} = 2/1 = 2, then l22=1−22=−3l_{22} = \sqrt{1 - 2^2} = \sqrt{-3}. Taking l22=3l_{22} = \sqrt{3} instead gives
LLT=(1023)(1203)=(1227)≠ALL^T = \begin{pmatrix} 1 & 0 \\ 2 & \sqrt{3} \end{pmatrix}\begin{pmatrix} 1 & 2 \\ 0 & \sqrt{3} \end{pmatrix} = \begin{pmatrix} 1 & 2 \\ 2 & 7 \end{pmatrix} \neq A


Right working: test definiteness first. The leading principal minors are 1>01 > 0 and det⁡A=1−4=−3<0\det A = 1 - 4 = -3 < 0, and the eigenvalues are 33 and −1-1, so AA is indefinite and has no Cholesky factor. LU still works:
A=(1021)(120−3)A = \begin{pmatrix} 1 & 0 \\ 2 & 1 \end{pmatrix}\begin{pmatrix} 1 & 2 \\ 0 & -3 \end{pmatrix}

and the negative pivot −3-3 is the same sign of trouble.

Why it happens: Cholesky is introduced as the symmetric version of LU, and symmetry is the condition that can be seen at a glance. Positive definiteness is the half of the requirement that has to be computed.

How to check: every leading principal minor must be positive. Multiplying LLTLL^T back must also return AA exactly.

Using the spectral form on a non-symmetric matrix

A diagonalizable matrix that is not symmetric is written as A=QDQTA = QDQ^T, with its unit eigenvectors as the columns of QQ, as if QTQ^T were the inverse of QQ.

Wrong working: A=(2101)A = \begin{pmatrix} 2 & 1 \\ 0 & 1 \end{pmatrix} has eigenvalue 22 with unit eigenvector (1,0)(1, 0) and eigenvalue 11 with unit eigenvector 12(1,−1)\frac{1}{\sqrt{2}}(1, -1). Then
QDQT=2(1000)+12(1−1−11)=(5/2−1/2−1/21/2)≠AQDQ^T = 2\begin{pmatrix} 1 & 0 \\ 0 & 0 \end{pmatrix} + \frac{1}{2}\begin{pmatrix} 1 & -1 \\ -1 & 1 \end{pmatrix} = \begin{pmatrix} 5/2 & -1/2 \\ -1/2 & 1/2 \end{pmatrix} \neq A


Right working: the eigenvectors are not orthogonal, so the inverse must be computed. With P=(110−1)P = \begin{pmatrix} 1 & 1 \\ 0 & -1 \end{pmatrix}, P−1=PP^{-1} = P and
PDP−1=(110−1)(2001)(110−1)=(2101)=APDP^{-1} = \begin{pmatrix} 1 & 1 \\ 0 & -1 \end{pmatrix}\begin{pmatrix} 2 & 0 \\ 0 & 1 \end{pmatrix}\begin{pmatrix} 1 & 1 \\ 0 & -1 \end{pmatrix} = \begin{pmatrix} 2 & 1 \\ 0 & 1 \end{pmatrix} = A


Why it happens: the spectral decomposition and ordinary diagonalization have the same shape, and QT=Q−1Q^T = Q^{-1} is easy to apply without noticing that it needs orthonormal columns.

How to check: QDQTQDQ^T is always symmetric, so it can never equal a non-symmetric AA. The dot product of the two eigenvectors here is 1/21/\sqrt{2}, not 00.

Counting nonzero eigenvalues for the rank

The rank is read off as the number of nonzero eigenvalues instead of the number of nonzero singular values.

Wrong working: A=(0100)A = \begin{pmatrix} 0 & 1 \\ 0 & 0 \end{pmatrix} has characteristic polynomial λ2\lambda^2, so both eigenvalues are 00, and the count gives rank 00.

Right working: ATA=(0001)A^TA = \begin{pmatrix} 0 & 0 \\ 0 & 1 \end{pmatrix} has eigenvalues 00 and 11, so the singular values are σ1=1\sigma_1 = 1 and σ2=0\sigma_2 = 0. One is nonzero, and the rank is 11.

Why it happens: for symmetric matrices, and for diagonalizable ones in general, the two counts agree, so the shortcut works on most examples met first. A matrix that cannot be diagonalized breaks it.

How to check: rank 00 belongs only to the zero matrix. A matrix with any nonzero entry has rank at least 11.