Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Mode


The Most Likely Value


In a probability distribution, not all values are equally representative. Some outcomes occur more frequently—or are more strongly concentrated—than others.

This page introduces the mode as a measure that identifies the value (or values) at which a distribution is most concentrated. It explains how the notion of "most likely" depends on the type of distribution and how the mode captures local concentration rather than balance or averaging.


Key Terms

Probability Mass Function— mode is the xx maximizing pX(x)p_X(x) for discrete variables
Probability Density Function— mode is the xx maximizing fX(x)f_X(x) for continuous variables
Expected Value— E[X]E[X], an alternative center measure
Discrete Random Variable— mode as the most probable value
Continuous Random Variable— mode as the peak of the density

See All Probability Definitions →


Definition and Concept

A shoe shop has to decide which size to stock most of.
The average size sold is no help if it comes out at a size no shoe is made in. What the shop needs is the size customers ask for most often.
Of 60 pairs sold last month, size 40 sold most — 20 pairs, a third of all sales.
shoe sizepairs soldshare of sales
3855/60 ≈ 8%
391212/60 = 20%
402020/60 = 1/3 — the largest
411515/60 = 25%
4288/60 ≈ 13%
The mean size is 240960=40.15\frac{2409}{60} = 40.15, which no shoe comes in. The most common size, 4040, is an actual size on the shelf.
Turned into probabilities, the answer is the value with the largest probability — the tallest bar.
A customer picked at random wants size 4040 with probability 13\frac{1}{3}, more than any other size. Picking out the most probable value works the same way for any distribution, with bars for a discrete one and the highest point of the curve for a continuous one.
The definition
The mode of a distribution is the value with the highest probability (largest PMF) or, for a continuous distribution, the highest density (largest PDF).
The mode identifies where probability concentrates most heavily in a distribution. It's the value (or values) with the highest likelihood of occurring.

What is the Mode?


For any probability distribution, the mode is the point where the probability function reaches its maximum:

• Discrete distributions: The value kk where the PMF P(X=k)P(X = k) is largest
• Continuous distributions: The value xx where the PDF f(x)f(x) is largest

If you observe a single random draw from the distribution, the mode tells you which outcome has the best chance of appearing.
So the mode of the shoe-size distribution is 4040, with probability 13\frac{1}{3}.
The mode is one of three measures of the centre — and the only one that still works for categories.

Mode as a Measure of Central Tendency


The mode is one of three primary measures describing where a distribution centers, alongside the mean and median.

Unlike the mean, which balances all values through weighted averaging, or the median, which splits probability in half, the mode simply highlights where probability peaks. It reveals nothing about spread or tail behavior—only where the distribution concentrates most.

Why the Mode Matters


The mode provides immediate intuition about a distribution's shape:

• Where is the peak? The mode shows the most probable outcome
• How many peaks exist? Multiple modes reveal complex structure
• Is probability spread evenly? No clear mode suggests uniform distribution

For categorical data (eye color, product preference, defect type), the mode is often the only meaningful measure of central tendency since mean and median require numerical values.
The mode need not be unique, and it need not sit anywhere near the mean.

Mode vs Other Measures


The mode behaves differently from mean and median:

• Independence from tail behavior: Extreme values don't affect the mode
• May not be unique: Distributions can have multiple modes or none at all
• Location need not be central: The mode can sit at boundaries or far from the mean
• Simplest to identify visually: Just find the tallest bar or highest point on the curve

The mode complements mean and median by revealing where probability actually concentrates, regardless of how the distribution spreads elsewhere.
Distributions with two or more peaks are the subject of multiple modes.
The rest of the page covers the mode for discrete and continuous distributions, multiple modes, and how the mode relates to the other measures of the centre.

Mode for Discrete Distributions


    For discrete distributions, the mode is the value where the PMF reaches its peak.

    Definition


    The mode of a discrete random variable XX is the value kk that maximizes the probability mass function:

    Mode for Discrete Distributions
    mode=arg⁡max⁡kP(X=k)\text{mode} = \arg\max_k P(X = k)

    This is the outcome with the highest probability among all possible values in the support.

    How to Find the Mode


    Unlike expected value or variance, there's no universal formula. Find the mode through direct comparison:

    1. Evaluate P(X=k)P(X = k) for each value in the support
    2. Identify which kk produces the largest probability
    3. If multiple values tie for the maximum, all are modes

    Examples Across Distributions


    Discrete Uniform: All values are modes. Every outcome in {a,a+1,…,b}\{a, a+1, \ldots, b\} has equal probability 1b−a+1\frac{1}{b-a+1}, so no single value dominates.

    Binomial: The mode is ⌊(n+1)p⌋\lfloor (n+1)p \rfloor when (n+1)p(n+1)p is not an integer. When (n+1)p(n+1)p is an integer, both (n+1)p−1(n+1)p - 1 and (n+1)p(n+1)p are modes.

    Example
    For n=10,p=0.3n=10, p=0.3, we have (n+1)p=3.3(n+1)p = 3.3, so mode =3= 3.

    Geometric: The mode is always 11. Since P(X=k)=(1−p)k−1pP(X = k) = (1-p)^{k-1}p decreases monotonically, the first trial has the highest probability.

    Poisson: The mode is ⌊λ⌋\lfloor \lambda \rfloor when λ\lambda is not an integer. When λ\lambda is an integer, both λ−1\lambda - 1 and λ\lambda are modes.

    Example
    For λ=5.7\lambda = 5.7, mode =5= 5. For λ=6\lambda = 6, modes are 55 and 66.

    Visual Identification


    On a probability mass diagram (bar chart), the mode is simply the tallest bar. If multiple bars share the same maximum height, you have multiple modes.

    Key Properties


  • The mode always lies within the support
  • Discrete distributions can have one mode, several modes, or every value as a mode
  • The mode may differ significantly from the mean, especially in skewed distributions
  • Changing a single probability can shift the mode entirely, unlike the mean which moves gradually
0.0000.0500.1000.1500.2000.250024681012141618Value (k)Probability P(X = k)
Poisson PMF, lambda = 3: two bars tie for the peak

The mode of a discrete distribution is the value under the tallest bar; for the Poisson family with an integer lambda the bars at lambda minus 1 and lambda are equally tall, so the distribution has two modes, 2 and 3. Change lambda to a non-integer and the tie breaks. Watch the peak move on the PMF visualizer.

Continuous distributions replace the tallest bar by the highest point of a curve.

Mode for Continuous Distributions


    For continuous distributions, the mode is the value where the PDF reaches its peak.

    Definition


    The mode of a continuous random variable XX is the value xx that maximizes the probability density function:

    Mode for Continuous Distributions
    mode=arg⁡max⁡xf(x)\text{mode} = \arg\max_x f(x)

    This is the point where density concentrates most heavily, not the point with highest probability (which is always zero for continuous variables).

    How to Find the Mode


    Use calculus to locate the maximum of the PDF:

    1. Take the derivative: f′(x)f'(x)
    2. Solve f′(x)=0f'(x) = 0 to find critical points
    3. Check the second derivative: f′′(x)<0f''(x) < 0 confirms a maximum
    4. Check boundary values if the support is restricted

    Examples Across Distributions


    Normal Distribution: The mode equals the mean μ\mu. The bell curve peaks at its center, where f(x)f(x) is maximized.

    Exponential Distribution: The mode is 00. The PDF f(x)=λe−λxf(x) = \lambda e^{-\lambda x} decreases monotonically from its maximum at the boundary.

    Uniform Distribution: No unique mode. The PDF is constant at 1b−a\frac{1}{b-a} across [a,b][a,b], so every point has equal density.

    Beta Distribution: The mode depends on parameters α\alpha and β\beta:
  • If α,β>1\alpha, \beta > 1: mode =α−1α+β−2= \frac{\alpha - 1}{\alpha + \beta - 2}
  • If α,β<1\alpha, \beta < 1: bimodal at the boundaries 00 and 11
  • If α=β=1\alpha = \beta = 1: reduces to uniform (no unique mode)

  • Pitfall: Using the Beta mode formula outside its range
    Applying α−1α+β−2\frac{\alpha - 1}{\alpha + \beta - 2} to α=β=0.5\alpha = \beta = 0.5 gives −0.5−1=0.5\frac{-0.5}{-1} = 0.5, where the density 1πx(1−x)\frac{1}{\pi\sqrt{x(1-x)}} is at its lowest, 2π≈0.64\frac{2}{\pi} \approx 0.64. The modes are the ends 00 and 11.

    The three cases follow the shape of the density on [0,1][0, 1]. With both parameters above 11 the curve starts at 00, rises to a single interior peak and falls back to 00 at the right end. With both below 11 it is U-shaped, climbing without bound toward each end of the interval.

    Boundary Modes


    Some distributions have modes at the edge of their support rather than in the interior. The exponential distribution is a classic example—maximum density occurs at x=0x = 0, the leftmost point of the support [0,∞)[0, \infty).

    When the support is bounded, always check endpoint values even after finding interior critical points.

    Visual Identification


    On a density curve, the mode is the highest point on the graph. For symmetric unimodal distributions like the normal, the peak sits at the center. For skewed distributions, the peak shifts toward one tail.

    Key Properties


  • Continuous distributions typically have a unique mode (unimodal)
  • Some distributions have multiple local maxima (multimodal)
  • The mode can lie outside the mean ±\pm several standard deviations
  • Ties are possible: a uniform density is flat, and a symmetric two-peaked density has two equal peaks
  • Mode location reveals distribution shape: central peak suggests symmetry, edge peak suggests strong skew
0.000.200.400.600.801.0000.61.21.92.53.13.74.45.0xf(x)
Exponential density, lambda = 1: the peak sits at zero

The mode of a continuous distribution is where the density is highest; the exponential density starts at its maximum and only decreases, so its mode is 0, far from its mean of 1 and its median of about 0.69. A symmetric density would put all three together. Compare with the normal and uniform densities on the PDF visualizer.

Distributions with several peaks are classified next.

Multiple Modes (Modality)


Distributions are classified by the number of peaks in their probability function. This classification reveals important structural features.

Types of Modality


Unimodal: One clear peak. Most standard distributions fall into this category.

Examples: Normal, Binomial (usually), Poisson (usually), Exponential

Bimodal: Two distinct peaks with equal or nearly equal height.

Fact: Adult heights have only one peak
Men's and women's heights pooled together give a single hump, not two. An equal mix of two normal curves with spread σ\sigma dips in the middle only when the means are more than 2σ2\sigma apart, and the gap between the average heights of men and women is smaller than that.

This often indicates a mixture of two underlying populations or processes. Data from two separate groups (morning commuters vs evening commuters, weekday traffic vs weekend traffic) can produce bimodal patterns.

Multimodal: Three or more peaks.

Rare in simple probability models but common in complex real-world data. Multiple subgroups or cyclical patterns can create many modes.

Every value is a mode (no unique mode): Uniform distributions, where all values have equal probability or density.

Examples: Discrete Uniform, Continuous Uniform

When Distributions Have Multiple Modes


Discrete cases: Ties in the PMF create multiple modes.

Example: Binomial with (n+1)p(n+1)p an integer has two modes at (n+1)p−1(n+1)p - 1 and (n+1)p(n+1)p.

Example: Poisson with integer λ\lambda has modes at λ−1\lambda - 1 and λ\lambda.

Continuous cases: Multiple local maxima in the PDF.

Example: Beta distribution with α,β<1\alpha, \beta < 1 has modes at both boundaries, 00 and 11.

Example: Mixture distributions like 0.5⋅N(μ1,σ12)+0.5⋅N(μ2,σ22)0.5 \cdot N(\mu_1, \sigma_1^2) + 0.5 \cdot N(\mu_2, \sigma_2^2) create two peaks.

Mixture Distributions


Combining two or more distributions creates multimodal patterns naturally. A mixture of normals:

Multiple Modes (Modality)
f(x)=w1f1(x)+w2f2(x)f(x) = w_1 f_1(x) + w_2 f_2(x)

produces peaks at the modes of the component distributions, weighted by w1w_1 and w2w_2, provided the components are far enough apart.

This models scenarios where data comes from multiple sources: times between eruptions of the Old Faithful geyser (short + long waits), customer arrival times (rush hour + off-peak periods), or test scores (prepared + unprepared students).

Practical Interpretation


Discovering multiple modes in data suggests:

• The sample contains distinct subgroups
• Different underlying mechanisms are at work
• A single simple distribution may not fit well
• Further investigation into group structure is warranted

Bimodality is a signal to look deeper rather than force-fit a unimodal model.

Mode Count vs Distribution Complexity


More modes don't necessarily mean more parameters. The Discrete Uniform has b−a+1b - a + 1 modes but only two parameters (aa and bb). The Normal has one mode despite having two parameters (μ\mu and σ\sigma).

Modality describes shape, not parameter count.
DownloadPNG2×PDF
Layout
ModalityNumber of peaksExamples
Unimodalonenormal, binomial (typical), Poisson (typical), exponential
Bimodaltwobinomial with (n+1)p integer; Poisson with integer λ; mixture of two normals
Multimodalthree or morecomplex mixtures; data from multiple subpopulations or cyclical patterns
No unique modenone (or all values tied)discrete uniform, continuous uniform
Multiple Modes (Modality)Learn Math Class
Equal mixture of normals centred at -2 and 2 with standard deviation 1: two peaks near -2 and 2, the mean 0 sits in the dip between themxf(x)−5−4−3−2−112345mode ≈ −2mode ≈ 2mean 0: in the dip½ N(−2, 1) + ½ N(2, 1)dashed: each halfBimodal: two peaks, and the mean between them is rare
A bimodal mixture

Half the probability comes from a normal centred at −2 and half from one centred at 2, both with standard deviation 1 (dashed curves). Their sum, the solid curve, has two peaks, at about −2 and 2: two modes. The mean is 0, exactly between them, but 0 sits in the dip, where the density is about a quarter of the peak height: the average value is one of the less likely ones.

Move the two centres closer than 2 standard deviations apart and the dip disappears: one mode.

Mode, Mean, and Median Compared


Three measures describe where distributions center: mode, mean, and median. Each reveals different structural features.

Quick Definitions


Mode: Peak location—where probability or density reaches maximum

Mean: Weighted balance point calculated from all values

Median: The 50th percentile that divides total probability equally

Symmetric Distributions


When unimodal distributions mirror themselves around a center point, all three measures collapse to the same value.

Normal distribution: mode = median = mean = μ\mu

Discrete Uniform on {1,2,3,4,5}\{1,2,3,4,5\}: mean and median equal 33, and every value is a mode

Perfect symmetry with a single peak forces the peak, the balance point, and the probability split to occupy identical positions.

Skewed Distributions


Asymmetry separates the three measures in consistent patterns.

Right skew (tail stretches toward larger values):

Mode, Mean, and Median Compared
mode<median<mean\text{mode} < \text{median} < \text{mean}

Extreme large values drag the mean rightward. The median holds closer to the probability bulk. The mode stays fixed at the density peak.

Exponential distribution: mode = 00, median = ln⁡(2)λ\frac{\ln(2)}{\lambda}, mean = 1λ\frac{1}{\lambda}

Left skew (tail stretches toward smaller values):

Mode, Mean, and Median Compared
mean<median<mode\text{mean} < \text{median} < \text{mode}

The ordering reverses—mean pulled left, mode anchored at the right peak.

Comparison Table


Comparing Mode, Mean, and Median

FeatureModeMeanMedian
CalculationFind maximumWeight all valuesFind 50th percentile
UniquenessCan have multipleSingle valueSingle value (continuous)
Outlier impactNoneStrongNone
Data typeAny (including categorical)Numerical onlyNumerical only
InterpretationMost likely valueAverage outcomeMiddle value
,


## Robustness Differences

Mean: Vulnerable. One extreme observation can shift it substantially.

Median: Resistant. Values beyond the 50% threshold have no influence.

Mode: Immune. Tail behavior irrelevant unless it creates a new peak.

Income data illustrates this: billionaires inflate the mean drastically while leaving median and mode nearly unchanged.

Selection Criteria


Choose mode for:
• Categorical outcomes (colors, brands, types)
• Identifying the most frequent occurrence
• Detecting multiple concentration points

Choose mean for:
• Symmetric data without extreme values
• Leveraging mathematical properties (additivity, scaling)
• Incorporating all observations equally

Choose median for:
• Skewed distributions
• Data contaminated by outliers
• Representing a "central" value that's actually achievable

Spatial Relationships


Symmetric unimodal case: All three occupy the same point at distribution center.

Right-skewed case: Mode sits at the left peak, median slightly right, mean furthest right chasing the tail.

Left-skewed case: Reversed ordering with mean leftmost, mode rightmost.

Properties of the Mode


The mode exhibits specific mathematical behaviors that distinguish it from other central tendency measures.

Transformation Under Linear Operations


For a random variable XX with mode mm, consider the transformation Y=aX+bY = aX + b where a≠0a \neq 0.

The mode of YY is:

Properties of the Mode
mode(Y)=a⋅mode(X)+b\text{mode}(Y) = a \cdot \text{mode}(X) + b

Linear transformations shift and scale the mode predictably. Multiply by aa, add bb—the peak moves accordingly.

Example
If XX has mode 55, then Y=2X+3Y = 2X + 3 has mode 2(5)+3=132(5) + 3 = 13.

This differs from variance, which scales by a2a^2, not aa.

Non-Uniqueness


Unlike mean, which always produces a single value, the mode may not be unique:

• Every value is a mode (no unique mode): Uniform distributions where all probabilities equal
• One mode: Most standard distributions (unimodal)
• Two modes: Binomial when (n+1)p(n+1)p is integer
• Many modes: Complex mixture distributions or uniform discrete cases

Non-uniqueness complicates using the mode as a summary statistic but reveals important structural features.

Robustness to Outliers


The mode completely ignores tail behavior. Extreme values in either direction have zero impact unless they exceed the current maximum probability.

Change every value beyond the mode by any amount—the mode stays fixed as long as the peak remains unchanged.

This makes mode ideal for data with contamination or measurement errors in the tails.

Independence from Distribution Spread


The mode reveals nothing about variance or spread. Two distributions can share the same mode while having vastly different variability.

Example
Normal distributions N(0,1)N(0, 1) and N(0,100)N(0, 100) both have mode 00, yet their standard deviations are 11 and 1010.

The mode operates independently of scale—it tracks peak location, not dispersion.

Invariance Under Monotonic Transformations


For a discrete random variable and a strictly monotonic function gg (always increasing or always decreasing):

Properties of the Mode
mode(g(X))=g(mode(X))\text{mode}(g(X)) = g(\text{mode}(X))

A one-to-one gg only relabels the values: P(g(X)=g(x))=P(X=x)P(g(X) = g(x)) = P(X = x), so the most likely value moves to gg of the old one.

Example
If a discrete X>0X > 0 has mode 44, then Y=X2Y = X^2 has mode 1616.

For a continuous random variable this fails in general. The density of Y=g(X)Y = g(X) is fX(g−1(y))⋅∣ddyg−1(y)∣f_X(g^{-1}(y)) \cdot \left|\frac{d}{dy} g^{-1}(y)\right|, and the extra factor can move the peak. Take XX with density f(x)=2xf(x) = 2x on [0,1][0, 1], whose mode is 11. Then Y=X2Y = X^2 is uniform on [0,1][0, 1]: every point is a mode, not just 12=11^2 = 1. Only linear maps aX+baX + b carry the mode along for every continuous variable.

The median is preserved by every strictly increasing gg, discrete or continuous; the mean is not.

Location Flexibility


The mode need not lie near the mean or median. Skewed distributions place the mode far from the balance point.

Exponential distributions have mode at 00 while mean sits at 1λ\frac{1}{\lambda}—potentially far apart.

The mode can even sit at distribution boundaries when density peaks at the edge of support.

No Additivity


Unlike the mean, modes don't add:

Properties of the Mode
mode(X+Y)≠mode(X)+mode(Y)\text{mode}(X + Y) \neq \text{mode}(X) + \text{mode}(Y)

Even for independent XX and YY, the peak of the convolution (sum) doesn't generally equal the sum of individual peaks.

This limits the mode's usefulness in probability calculations involving sums or combinations.
Property Statement
Linear transformation mode(aX + b) = a · mode(X) + b for a ≠ 0
Non-uniqueness a distribution may have zero, one, two, or many modes
Robustness to outliers tail values cannot shift the mode unless they create a new higher peak
Independence from spread reveals only peak location; N(0, 1) and N(0, 100) share mode 0
Monotonic-transformation invariance mode(g(X)) = g(mode(X)) for strictly monotonic g when X is discrete; fails in general for continuous X
Location flexibility may sit at distribution boundaries or far from the mean
No additivity mode(X + Y) ≠ mode(X) + mode(Y) in general, even for independent X, Y

How to Find the Mode


The method for finding the mode depends on whether the distribution is discrete or continuous.

For Discrete Distributions


Step 1: List all values in the support

Identify every possible outcome the random variable can take.

Step 2: Evaluate the PMF at each value

Calculate P(X=k)P(X = k) for every kk in the support using the probability mass function.

Step 3: Identify the maximum

Find which value(s) produce the largest probability. If multiple values tie, all are modes.

Example
Binomial with n=10,p=0.3n = 10, p = 0.3
Compute P(X=k)P(X = k) for k=0,1,2,…,10k = 0, 1, 2, \ldots, 10. The maximum occurs at k=3k = 3 with probability approximately 0.2670.267.
Mode = 33.

Pitfall: Reporting the peak height instead of its location
Answering with the largest probability: here that gives mode =0.267= 0.267. The mode is the value where that probability occurs, k=3k = 3.

Step 3 searches the column of probabilities, but what it returns is a point of the support. In the binomial example the two columns live on different scales: the probabilities are numbers between 00 and 11, while the values are counts of successes from 00 to 1010.

Shortcut for known distributions: Many standard distributions have analytical expressions:
• Geometric: mode = 11 always
• Poisson: mode = ⌊λ⌋\lfloor \lambda \rfloor
• Binomial: mode = ⌊(n+1)p⌋\lfloor (n+1)p \rfloor

Pitfall: Dropping the second mode at a tie
Using ⌊(n+1)p⌋\lfloor (n+1)p \rfloor alone for n=5n = 5, p=0.5p = 0.5 gives one mode, 33. Here (n+1)p=3(n+1)p = 3 is an integer and P(X=2)=P(X=3)=0.3125P(X = 2) = P(X = 3) = 0.3125, so 22 and 33 are both modes.

Each shortcut comes from comparing neighbouring probabilities. For the binomial, P(X=k+1)≥P(X=k)P(X = k + 1) \geq P(X = k) exactly when k+1≤(n+1)pk + 1 \leq (n+1)p, so the probabilities rise as long as that holds and fall after it. The Poisson rule follows the same way, with λ\lambda in place of (n+1)p(n+1)p.

For Continuous Distributions


Step 1: Write the PDF

Start with the probability density function f(x)f(x).

Step 2: Take the derivative

Compute f′(x)f'(x) with respect to xx.

Step 3: Solve for critical points

Set f′(x)=0f'(x) = 0 and solve for xx. These are candidate locations for maxima.

Step 4: Verify maximum

Check the second derivative: f′′(x)<0f''(x) < 0 confirms a local maximum.

If f′′(x)>0f''(x) > 0, you've found a minimum. If f′′(x)=0f''(x) = 0, further analysis needed.

Step 5: Check boundaries

If the support is restricted (e.g., [0,∞)[0, \infty)), evaluate f(x)f(x) at the boundary points. The mode might sit at an edge.

Example: Normal distribution with PDF:

How to Find the Mode
f(x)=1σ2πe−(x−μ)22σ2f(x) = \frac{1}{\sigma\sqrt{2\pi}} e^{-\frac{(x-\mu)^2}{2\sigma^2}}

Taking the derivative and setting to zero yields x=μx = \mu.

Checking f′′(μ)<0f''(\mu) < 0 confirms maximum.

Mode = μ\mu.

Example: Exponential distribution with PDF:

Exponential PDF
f(x)=λe−λx,x≥0f(x) = \lambda e^{-\lambda x}, \quad x \geq 0
Learn more about this formula: Exponential PDF →


The derivative f′(x)=−λ2e−λx<0f'(x) = -\lambda^2 e^{-\lambda x} < 0 everywhere.

No interior critical points exist. The maximum occurs at the boundary x=0x = 0.

Mode = 00.

Numerical Methods


When analytical solutions don't exist or are intractable, use numerical optimization:

Grid search: Evaluate the probability function at many points, identify the maximum.

Gradient ascent: Iteratively move uphill following the derivative until reaching the peak.

Golden section search: Efficient method for unimodal functions on bounded intervals.

Most statistical software provides built-in mode-finding functions for common distributions.

Visual Inspection


For data visualization:
• Discrete: Look for the tallest bar in a bar chart or probability mass diagram
• Continuous: Look for the highest point on the density curve

Visual methods work well for quick identification but lack precision for formal analysis.

Multiple Modes


If the probability function has several local maxima, determine whether you want:
• Global mode: The highest peak overall
• All local modes: Every peak that's higher than its immediate neighbors

Multimodal distributions require identifying all peaks, not just the tallest.

To find the mode of your own data set, use the statistics calculator.

A mode search always looks for the highest point, bar or curve, and checks the edges of the support too.
The three steps on the binomial example of this section. Press Next to carry out one step at a time.
DownloadPNG2×PDF
Binomial with n=10n = 10, p=0.3p = 0.3Step 1 of 3
Step
Binomial with n=10n = 10, p=0.3p = 0.3
1
List all values in the support
k=0,1,2,…,10k = 0, 1, 2, \ldots, 10
2
Evaluate the PMF at each value
P(X=k)P(X = k) for every kk
3
Identify the maximumThe mode is the value, not the probability
largest at k=3k = 3, about 0.2670.267: mode =3= 3
Finding the mode of a discrete distribution·/probability/modeLearn Math Class

Mode for Common Distributions


Standard probability distributions have well-established mode formulas or behaviors. This section catalogs modes for the most frequently encountered distributions.

Discrete Distributions


Discrete Uniform on {a,a+1,…,b}\{a, a+1, \ldots, b\}

Mode: Every value in the support

All outcomes have equal probability 1b−a+1\frac{1}{b-a+1}, so no single value dominates.

Binomial with parameters nn and pp

Mode: ⌊(n+1)p⌋\lfloor (n+1)p \rfloor when (n+1)p(n+1)p is not an integer

When (n+1)p(n+1)p is an integer, both (n+1)p−1(n+1)p - 1 and (n+1)p(n+1)p are modes (bimodal).

Example: n=10,p=0.3n = 10, p = 0.3 gives (n+1)p=3.3(n+1)p = 3.3, so mode = 33

Example: n=11,p=0.5n = 11, p = 0.5 gives (n+1)p=6(n+1)p = 6, so modes are 55 and 66

Geometric with parameter pp

Mode: 11 (always)

The PMF P(X=k)=(1−p)k−1pP(X = k) = (1-p)^{k-1}p decreases monotonically. The first trial has highest probability.

Negative Binomial with parameters rr and pp

Mode: r+⌊(r−1)(1−p)p⌋r + \lfloor \frac{(r-1)(1-p)}{p} \rfloor when r>1r > 1, counting trials

When r=1r = 1, reduces to geometric with mode 11.

Hypergeometric with parameters N,K,nN, K, n

Mode: ⌊(n+1)(K+1)N+2⌋\lfloor \frac{(n+1)(K+1)}{N+2} \rfloor

This is exact. When (n+1)(K+1)N+2\frac{(n+1)(K+1)}{N+2} is an integer, that value and the one below it are both modes (bimodal).

Poisson with parameter λ\lambda

Mode: ⌊λ⌋\lfloor \lambda \rfloor when λ\lambda is not an integer

When λ\lambda is an integer, both λ−1\lambda - 1 and λ\lambda are modes (bimodal).

Example: λ=4.7\lambda = 4.7 gives mode = 44

Example: λ=5\lambda = 5 gives modes = 44 and 55

Continuous Distributions


Continuous Uniform on [a,b][a, b]

Mode: No unique mode

The PDF is constant at 1b−a\frac{1}{b-a} across the entire interval. Every point has equal density.

Normal (Gaussian) with parameters μ,σ\mu, \sigma

Mode: μ\mu

The bell curve peaks at the mean. Symmetry ensures mode = median = mean.

Exponential with parameter λ\lambda

Mode: 00

The PDF f(x)=λe−λxf(x) = \lambda e^{-\lambda x} decreases monotonically from its maximum at the left boundary.

Beta Distribution with parameters α,β\alpha, \beta

Mode depends on parameter values:

• If α,β>1\alpha, \beta > 1: mode = α−1α+β−2\frac{\alpha - 1}{\alpha + \beta - 2}
• If α,β<1\alpha, \beta < 1: bimodal at 00 and 11 (U-shaped)
• If α=β=1\alpha = \beta = 1: uniform on [0,1][0,1] (no unique mode)
• If α<1,β≥1\alpha < 1, \beta \geq 1: mode = 00
• If α≥1,β<1\alpha \geq 1, \beta < 1: mode = 11

Gamma Distribution with shape kk and rate θ\theta

Mode: k−1θ\frac{k-1}{\theta} when k≥1k \geq 1

When k<1k < 1, mode = 00 (at the boundary).

Weibull Distribution with shape kk and scale λ\lambda

Mode: λ(1−1k)1/k\lambda \left(1 - \frac{1}{k}\right)^{1/k} when k>1k > 1

When k≤1k \leq 1, mode = 00 (at the boundary).

Summary Pattern


Many distributions have modes expressible through their parameters. When no closed form exists, numerical evaluation of the probability function identifies the peak. Standard statistical software includes mode calculations for all common distributions.
DownloadPNG2×PDF
Layout
DistributionModeNotes
Discrete Uniform on {a, …, b}every value in the supportno single mode — all probabilities equal 1/(b−a+1)
Binomial(n, p)⌊(n+1)p⌋bimodal at (n+1)p and (n+1)p−1 when (n+1)p is an integer
Geometric(p)1PMF decreases monotonically; first trial is always most likely
Negative Binomial(r, p)r + ⌊(r−1)(1−p)/p⌋ for r > 1reduces to geometric when r = 1
Hypergeometric(N, K, n)⌊(n+1)(K+1)/(N+2)⌋exact; bimodal at x and x−1 when x = (n+1)(K+1)/(N+2) is an integer
Poisson(λ)⌊λ⌋bimodal at λ−1 and λ when λ is an integer
Continuous Uniform on [a, b]every point in [a, b]density is constant at 1/(b−a) — no unique peak
Normal(μ, σ)μbell curve peaks at the mean; mode = median = mean by symmetry
Exponential(λ)0boundary mode — PDF decreases monotonically from x = 0
Beta(α, β)(α−1)/(α+β−2) for α, β > 1bimodal at {0, 1} when α, β < 1; uniform when α = β = 1
Gamma(k, θ)(k−1)/θ for k ≥ 1mode = 0 (boundary) when k < 1
Weibull(k, λ)λ(1 − 1/k)1/k^{1/k} for k > 1mode = 0 (boundary) when k ≤ 1
Mode for Common DistributionsLearn Math Class

Special Cases and Edge Cases


Certain distributions exhibit unusual mode behavior that deviates from standard patterns.

Distributions with No Unique Mode


Uniform distributions: Every value qualifies as a mode since all probabilities or densities are equal.

Discrete uniform on {1,2,3,4,5}\{1, 2, 3, 4, 5\}: All five values are modes.

Continuous uniform on [0,10][0, 10]: Every point in the interval is a mode.

No single peak exists—probability spreads completely flat.

Constant distributions: If X=cX = c with probability 11 (degenerate distribution), then mode = cc trivially, though this hardly constitutes a meaningful peak.

Mode at Distribution Boundaries


Some distributions concentrate maximum density at the edge of their support rather than in the interior.

Exponential: Mode = 00, the leftmost point of support [0,∞)[0, \infty).

The PDF decreases monotonically from this boundary maximum.

Beta with α<1\alpha < 1 or β<1\beta < 1: Modes occur at boundaries 00 or 11.

When both parameters fall below 11, the distribution becomes U-shaped with modes at both boundaries (bimodal).

Weibull with k<1k < 1: Mode = 00 at the boundary.

Boundary modes indicate strong concentration near the support edge—probability piles up against the constraint.

Bimodal Cases in Standard Distributions


Binomial: When (n+1)p(n+1)p equals an integer, two adjacent values share the maximum probability.

Example
n=5,p=0.5n = 5, p = 0.5 gives (n+1)p=3(n+1)p = 3, producing modes at k=2k = 2 and k=3k = 3.

Poisson: When λ\lambda is an integer, both λ−1\lambda - 1 and λ\lambda are modes.

Example
λ=4\lambda = 4 creates modes at k=3k = 3 and k=4k = 4.

These bimodal situations arise from the discrete nature of the distributions combined with specific parameter values creating exact probability ties.
One row per kind of distribution where the mode is not one peak inside the support; click the boundary row for more.
DownloadPNG2×PDF
General
mode⁡(X)=arg⁡max⁡xf(x)\operatorname{mode}(X) = \arg\max_x f(x)
All values equally likelyno unique mode
Every value is a mode
discrete uniform on {1,2,3,4,5}\{1, 2, 3, 4, 5\}: all five; continuous uniform on [0,10][0, 10]: every point
No single peak exists: probability spreads completely flat.
X=cX = c with probability 11degenerate
Mode =c= c
a constant distribution
Trivially, though this hardly constitutes a meaningful peak.
Binomial, (n+1)p(n+1)p an integertwo modes
Two adjacent values share the maximum probability
n=5,p=0.5n = 5, p = 0.5: modes at k=2k = 2 and k=3k = 3
The discrete nature of the distribution, combined with this parameter value, creates an exact probability tie.
Poisson, λ\lambda an integertwo modes
Both λ−1\lambda - 1 and λ\lambda are modes
λ=4\lambda = 4: modes at k=3k = 3 and k=4k = 4
The discrete nature of the distribution, combined with this parameter value, creates an exact probability tie.
When the peak is not a single pointLearn Math Class
In every row the mode is still the value where the probability peaks; what changes is how many values reach the peak and where they sit.

Distributions Where Mode ≠ Mean


Skewed distributions always separate mode from mean.

Exponential: mode = 00, mean = 1λ\frac{1}{\lambda}

The gap can be arbitrarily large depending on parameters.

Lognormal distribution: Highly right-skewed with mode << median << mean.

The mode sits far left of the mean, which gets pulled right by the long tail.

Multimodal Mixture Distributions


Combining multiple distributions creates multiple peaks:

Special Cases and Edge Cases
f(x)=0.3⋅N(0,1)+0.7⋅N(5,1)f(x) = 0.3 \cdot N(0, 1) + 0.7 \cdot N(5, 1)

This mixture has two modes near 00 and 55, weighted by the mixture coefficients.

The global mode (highest peak) sits at 55 since it receives more weight (0.70.7 vs 0.30.3).

Real data often exhibits multimodality when samples come from multiple subpopulations.

Distributions with Undefined or Problematic Modes


Cauchy distribution: Has a well-defined mode at the location parameter, but the mean doesn't exist (infinite variance).

Mode behaves normally while other measures fail.

Heavy-tailed distributions: May have modes but extreme tail behavior dominates the mean.

The mode provides a more stable central measure than the mean in such cases.

Discrete Distributions with Interval Modes


For some discrete distributions, multiple consecutive values may satisfy the mode criterion when probabilities cluster without a single clear maximum.

Discrete uniform represents the extreme case—entire support forms the mode set.

Less extreme: distributions with nearly flat probability across several adjacent values create ambiguous mode identification.

When Mode Analysis Fails


Data with no clear structure: If observations scatter uniformly with no concentration points, mode identification becomes meaningless.

Continuous distributions approximated by discrete samples: Estimated modes depend heavily on bin width and placement choices.

Sparse data: Small samples may show spurious modes that disappear with more observations.

The mode works best when probability genuinely concentrates at identifiable peaks rather than spreading evenly or randomly.

Mode Notation

Notation

Mode Notation

Like the median, the mode never earned one settled symbol — but it did earn an operator all its own: the mark that asks not how high the peak is, but where it stands. This section fixes the operator spellings, the arg max that defines them, and the set braces that appear when the peak is shared. All catalogued among the probability symbols.
P(⋅)P(\cdot) and P(X=k)P(X = k) come from the probability function and random variable notation; the density ff from the probability function's mass/density split; the mean's μ\mu and E[X]E[X] from expected value notation.
mode⁡(X)\operatorname{mode}(X), Mo⁡(X)\operatorname{Mo}(X), MoM_o
the mode of X
The operator spelling written out or abbreviated, and the letter form MoM_o with a subscript "o" — the letter variant travels poorly, since MM already works as a maximum, a bound and a matrix elsewhere. Like the median, the mode has no universally adopted symbol; sources define their own, and careful reading starts by checking which convention is in force.
CasesThe sample/population split hats the letter: M^o\hat{M}_o for the mode observed in data against MoM_o for the distribution's own — the estimate hat of the two-hats convention, the same story xˉ\bar{x} tells against the population mean.
Do not confuseMM at its other jobs. In the same text MM may be a supremum bound or a moment cap; only the subscript "o" — and often only the surrounding sentence — marks the mode.
mode⁡(X)=arg⁡max⁡xf(x)\operatorname{mode}(X) = \arg\max_x f(x)
the argument that maximizes f — the location of the peak, not its height
max⁡f\max f returns how high the peak is; arg⁡max⁡f\arg\max f returns where it stands — the mode is the second kind of answer. The underscript names the variable being searched; discrete distributions swap the density for the mass, arg⁡max⁡kP(X=k)\arg\max_k P(X = k).
CasesThe same operator runs Bayesian statistics: the posterior's mode is the MAP estimate, θ^=arg⁡max⁡θπ(θ∣x)\hat{\theta} = \arg\max_\theta \pi(\theta \mid x) — one notation serving both a descriptive statistic and an estimation principle.
Do not confusemax⁡\max itself. Reading arg⁡max⁡xf(x)\arg\max_x f(x) as the maximum value swaps a location on the xx-axis for a height on the yy-axis — the two agree in neither units nor meaning, and the "arg" prefix is the only mark separating them.
mode⁡(X)={k1,…,km}\operatorname{mode}(X) = \{k_1, \ldots, k_m\}
the modes of X — plural, as a set
When several values tie for the highest probability, the operator returns a set: braces signal that "the" mode is not unique. Prose carries the same information as vocabulary — unimodal, bimodal, multimodal — where formulas use the braces.
CasesA uniform distribution is the degenerate extreme: every value ties, and the set-valued answer becomes the whole support — which is why "the mode" is only quoted for distributions with an actual peak; the mean and median never need this escape hatch, since averaging and halving always produce one number.
Do not confuseA flat top versus modes that are many. A flat top (every value tied) and a shared peak (several values stand out equally) both mean no unique mode, but only the second singles out a few values — on uniform data every value is a mode, so the set says nothing about where values concentrate.
DownloadPNG2×PDF
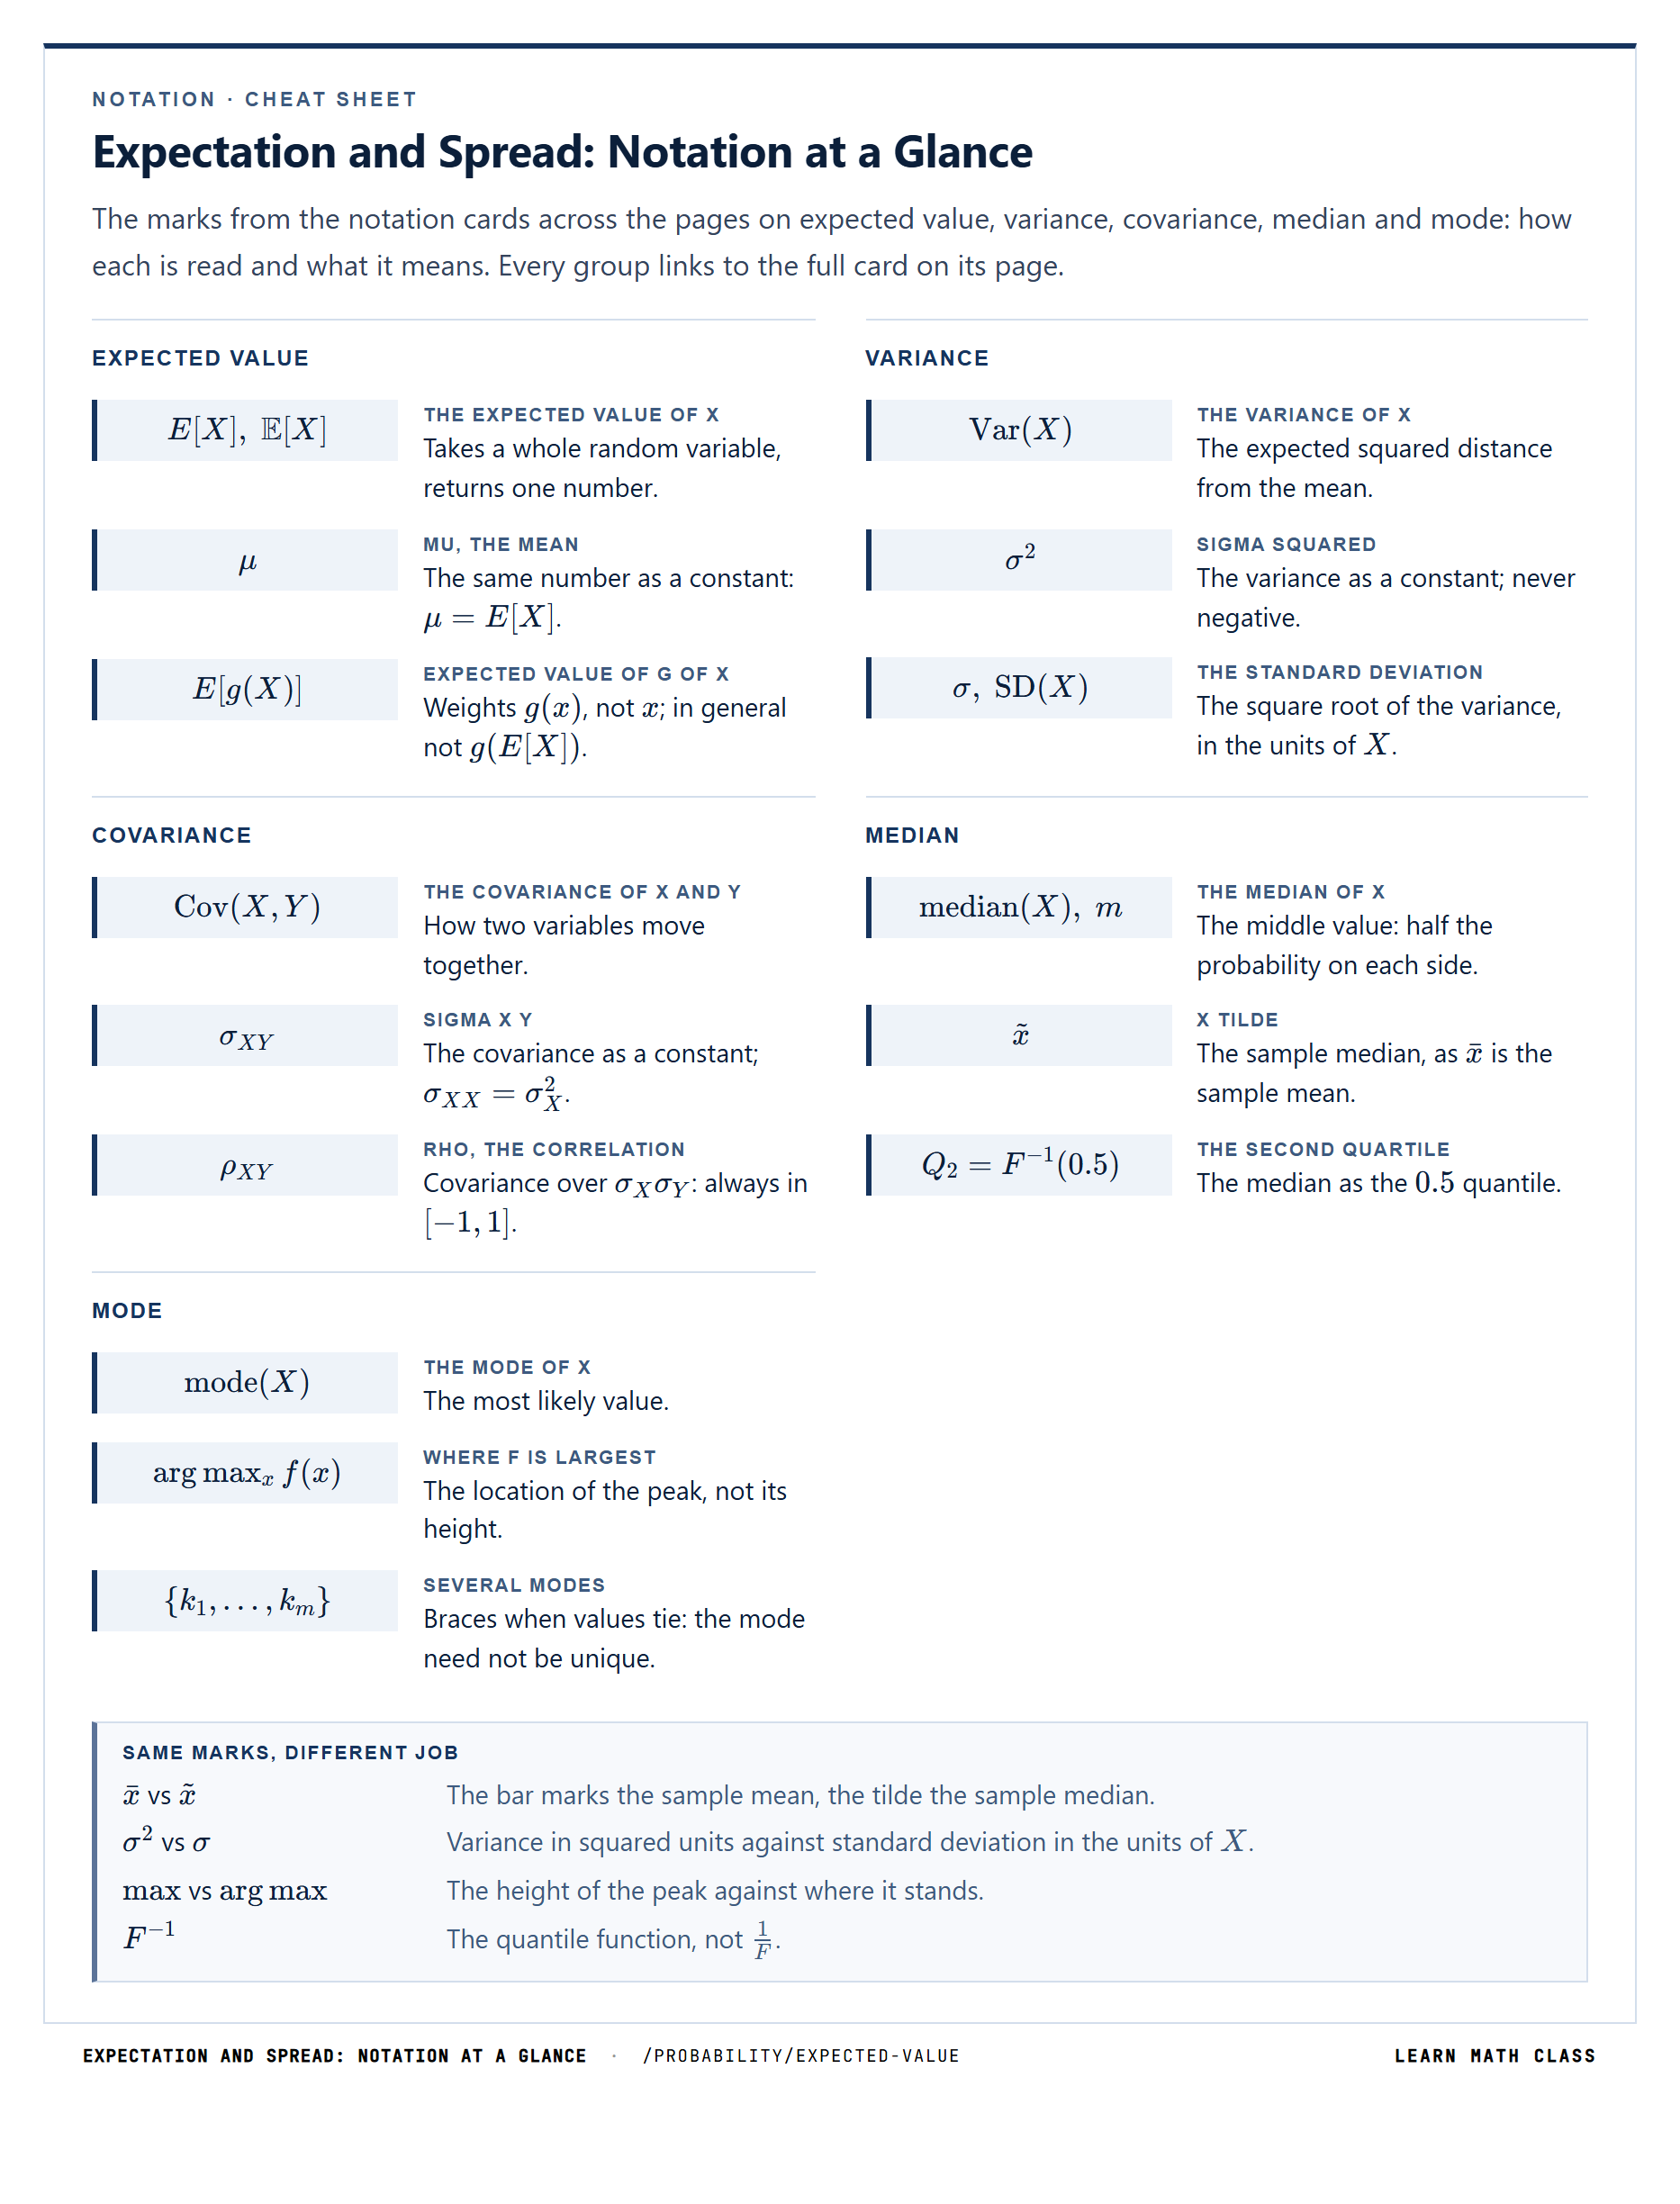
Notation · Cheat sheet
Expectation and Spread: Notation at a Glance
The marks from the notation cards across the pages on expected value, variance, covariance, median and mode: how each is read and what it means. Every group links to the full card on its page.
Expected value
E[X],  E[X]E[X], \; \mathbb{E}[X]
the expected value of X
Takes a whole random variable, returns one number.
μ\mu
mu, the mean
The same number as a constant: μ=E[X]\mu = E[X].
E[g(X)]E[g(X)]
expected value of g of X
Weights g(x)g(x), not xx; in general not g(E[X])g(E[X]).
Variance
Var⁡(X)\operatorname{Var}(X)
the variance of X
The expected squared distance from the mean.
σ2\sigma^2
sigma squared
The variance as a constant; never negative.
σ,  SD⁡(X)\sigma, \; \operatorname{SD}(X)
the standard deviation
The square root of the variance, in the units of XX.
Covariance
Cov⁡(X,Y)\operatorname{Cov}(X, Y)
the covariance of X and Y
How two variables move together.
σXY\sigma_{XY}
sigma X Y
The covariance as a constant; σXX=σX2\sigma_{XX} = \sigma_X^2.
ρXY\rho_{XY}
rho, the correlation
Covariance over σXσY\sigma_X\sigma_Y: always in [−1,1][-1, 1].
Median
median⁡(X),  m\operatorname{median}(X), \; m
the median of X
The middle value: half the probability on each side.
x~\tilde{x}
x tilde
The sample median, as xˉ\bar{x} is the sample mean.
Q2=F−1(0.5)Q_2 = F^{-1}(0.5)
the second quartile
The median as the 0.50.5 quantile.
ModeThis page
mode⁡(X)\operatorname{mode}(X)
the mode of X
The most likely value.
arg⁡max⁡xf(x)\arg\max_x f(x)
where f is largest
The location of the peak, not its height.
{k1,…,km}\{k_1, \ldots, k_m\}
several modes
Braces when values tie: the mode need not be unique.
Same marks, different job
xˉ\bar{x} vs x~\tilde{x}The bar marks the sample mean, the tilde the sample median.
σ2\sigma^2 vs σ\sigmaVariance in squared units against standard deviation in the units of XX.
max⁡\max vs arg⁡max⁡\arg\maxThe height of the peak against where it stands.
F−1F^{-1}The quantile function, not 1F\frac{1}{F}.
Expectation and Spread: Notation at a Glance·/probability/expected-valueLearn Math Class

Formula Summary

This summary collects the formulas of the page on ten cards. Each card gives the name of the formula, the formula and a sentence on what it means with a link to its section, and where a condition applies, a badge states it.

The first four cards locate the mode: the most probable value of a discrete variable, the peak of a density, the calculus test for that peak, and the shortcut for the binomial. The mixture card shows how several peaks arise. Two cards order the mode, median and mean under right and left skew, and the last three cover linear and monotonic transformations and the failure of additivity.
DownloadPNG2×PDF
Discrete mode
mode=arg⁡max⁡kP(X=k)\text{mode} = \arg\max_k P(X = k)
The value with the highest probability in the support, from mode for discrete distributions.
!ties give several modes
Continuous mode
mode=arg⁡max⁡xf(x)\text{mode} = \arg\max_x f(x)
The peak of the density, not a point of highest probability, which is always zero for a continuous variable (mode for continuous distributions).
Finding a continuous mode
f′(x)=0,f′′(x)<0f'(x) = 0, \quad f''(x) < 0
Critical points of the density with a negative second derivative are peaks, as how to find the mode shows step by step.
!also check the ends of a restricted support
Binomial shortcut
mode=⌊(n+1)p⌋\text{mode} = \lfloor (n+1)p \rfloor
One of the closed forms in how to find the mode, next to ⌊λ⌋\lfloor \lambda \rfloor for the Poisson and 11 for the geometric.
!when (n+1)p(n+1)p is a whole number, two modes
Mixture
f(x)=w1f1(x)+w2f2(x)f(x) = w_1 f_1(x) + w_2 f_2(x)
Mixing two distributions gives peaks at the modes of the components, as multiple modes explains.
!components far enough apart
Right skew
mode<median<mean\text{mode} < \text{median} < \text{mean}
The mode stays at the peak while the tail of large values drags the mean right (mode, mean and median compared).
Left skew
mean<median<mode\text{mean} < \text{median} < \text{mode}
The same three centres in reverse order, from the comparison.
Linear transformation
mode(Y)=a⋅mode(X)+b\text{mode}(Y) = a \cdot \text{mode}(X) + b
The peak moves with the data when it is scaled and shifted, one of the properties of the mode.
!Y=aX+bY = aX + b with a≠0a \neq 0
Monotonic transformation
mode(g(X))=g(mode(X))\text{mode}(g(X)) = g(\text{mode}(X))
A one-to-one gg only relabels the values, so the most likely value moves to its image (properties).
!discrete XX, strictly monotonic gg
No additivity
mode(X+Y)≠mode(X)+mode(Y)\text{mode}(X + Y) \neq \text{mode}(X) + \text{mode}(Y)
The peak of a sum is not the sum of the peaks, even for independent variables (properties of the mode).
Mode formulas·All probability formulasLearn Math Class
The mode is a location, not a height: report the value where the probability or density peaks, never the peak itself. On a restricted support check the end points too, and when two values tie, both are modes.

Common Mistakes


Several recurring errors appear when working with the mode.

Confusing Mode with Mean or Median


The three measures are fundamentally different:

Mode = peak location

Mean = balance point

Median = 50th percentile

Using "mode" when you mean "average" is incorrect. The mode identifies the most likely value, not the typical value in the sense of central balance.

Assuming the Mode Always Exists and is Unique


Uniform distributions have no unique mode—every value qualifies equally.

Bimodal distributions have two modes.

Some distributions have modes at multiple points.

Never assume exactly one mode without checking the probability function.

Thinking Mode Must Be "Central"


The mode can sit at distribution boundaries or far from the mean.

Exponential distributions have mode at zero while the mean sits at 1λ\frac{1}{\lambda}—potentially far apart.

Skewed distributions place the mode away from the center of mass.

The mode tracks the peak, which need not align with centrality measures.

Using Mode for Continuous Data Without Clear Peaks


When continuous data shows no distinct concentration points, estimating a mode becomes arbitrary and depends on binning choices.

Smooth, flat densities yield meaningless modes—there's no genuine peak to identify.

Reserve mode analysis for data with genuine multimodality or clear probability concentration.

Forgetting to Check Boundary Values


When finding the mode of continuous distributions through calculus, always evaluate the PDF at boundary points.

Setting f′(x)=0f'(x) = 0 finds interior critical points but misses boundary maxima.

Exponential and some Beta distributions have modes at support edges, not interior points.

Confusing High Probability with High Density


For continuous distributions, the PDF value f(x)f(x) is not a probability—it's a density that must be integrated.

A PDF can exceed 11 (like uniform on [0,0.5][0, 0.5] with f(x)=2f(x) = 2) without violating probability rules.

The mode is still the maximum of f(x)f(x), even when f(x)>1f(x) > 1.

Assuming Mode + Median + Mean Always Have Fixed Order


The relationship mode < median < mean typically holds for right-skewed distributions.

Symmetric unimodal distributions have all three equal.

Left-skewed distributions reverse the inequality.

Never apply the inequality blindly without checking skewness direction.

Treating Sample Mode as Population Mode


The mode observed in finite data may not reflect the true population mode, especially with small samples or continuous data.

Sampling variability affects mode estimation more than mean or median estimation.

Large samples and clear probability peaks increase reliability.

Ignoring Mode When It's the Right Measure


For categorical data (colors, types, categories), mode is often the only meaningful central tendency measure.

Calculating a mean of {red, blue, green} makes no sense—report the mode instead.

Similarly, multimodal data demands mode analysis rather than forcing a single-value summary.

Using the Beta mode formula outside its range

The formula α−1α+β−2\frac{\alpha - 1}{\alpha + \beta - 2} is applied to a Beta distribution without checking that both parameters exceed 11.

Wrong working, for α=β=0.5\alpha = \beta = 0.5:
mode=0.5−10.5+0.5−2=−0.5−1=0.5\text{mode} = \frac{0.5 - 1}{0.5 + 0.5 - 2} = \frac{-0.5}{-1} = 0.5


Right working: with α,β<1\alpha, \beta < 1 the density f(x)=1πx(1−x)f(x) = \frac{1}{\pi\sqrt{x(1-x)}} is U-shaped. At x=0.5x = 0.5 it takes its smallest value, f(0.5)=2π≈0.64f(0.5) = \frac{2}{\pi} \approx 0.64, and it grows without bound toward both ends, so the modes are at the boundaries 00 and 11.

Why it happens: the formula comes from solving f′(x)=0f'(x) = 0, and for α,β<1\alpha, \beta < 1 that equation still has a solution inside (0,1)(0, 1). That point is the bottom of the U, not a peak, and the formula cannot tell the two apart.

How to check: compare the density at the candidate with its value near an end. Here f(0.5)≈0.64f(0.5) \approx 0.64, while f(0.01)=1π0.0099≈3.2f(0.01) = \frac{1}{\pi\sqrt{0.0099}} \approx 3.2, so 0.50.5 cannot be the highest point.

Reporting the peak height instead of its location

The largest probability in the PMF is found correctly, but that probability is given as the mode instead of the value where it occurs.

Wrong working, for the binomial with n=10n = 10, p=0.3p = 0.3:
max⁡kP(X=k)=P(X=3)≈0.267  ⟹  mode=0.267\max_k P(X = k) = P(X = 3) \approx 0.267 \implies \text{mode} = 0.267


Right working: the mode is the argument of the maximum, not the maximum itself.
mode=arg⁡max⁡kP(X=k)=3\text{mode} = \arg\max_k P(X = k) = 3


Why it happens: the search in Step 3 runs over the probabilities, so the last number written down is a probability. The definition asks for the kk that produced it.

How to check: the mode must be a value the variable can take. Here XX counts successes, a whole number from 00 to 1010, so 0.2670.267 cannot be its mode.
DownloadPNG2×PDF
Layout
MistakeWrong thinkingCorrect view
Confusing mode with mean or mediantreating “mode” as the averagemode = peak; mean = balance point; median = 50th percentile
Assuming a unique mode always existsexpecting exactly one modeuniform distributions have no unique mode; binomial/Poisson can be bimodal
Thinking the mode must be centralplacing the mode near the mean by defaultthe mode can sit at boundaries (e.g. exponential at 0) or far from the mean
Forgetting boundary valuesonly solving f′(x) = 0 for interior critical pointsalso evaluate f(x) at support boundaries (exponential, Beta, Weibull)
Confusing density with probabilityreading f(x) as a probability for continuous variablesf(x) is density — can exceed 1; the mode is still argmax f(x)
Fixed mode/median/mean orderingalways applying mode < median < meanthat ordering typically holds for right-skewed (not guaranteed); usually reverses for left-skewed; ties for symmetric unimodal
Sample mode as population modetreating the observed mode as the true modesample modes are noisy, especially for small samples or continuous data
Ignoring mode when it's the right toolreporting a mean for categorical datafor categories (colors, brands), mode is often the only meaningful central tendency
Common MistakesLearn Math Class

Related Concepts


The mode connects to numerous other probability and statistics concepts.

Other Measures of Central Tendency


Mean (Expected Value): The probability-weighted average of all values. Balances the distribution.

Median: The 50th percentile that splits probability in half. Robust to outliers.

These three measures work together to characterize where distributions center and how they're shaped.

Measures of Dispersion


Variance: Quantifies spread around the mean. High variance means values scatter widely.

Standard Deviation: Square root of variance, measured in original units.

The mode reveals concentration points while variance reveals spread. Both are needed for complete distribution description.

Skewness


Skewness measures asymmetry. The relative positions of mode, median, and mean directly indicate skewness direction:

Right skew: mode < median < mean

Left skew: mean < median < mode

Symmetric unimodal: mode = median = mean

Distribution Shape


Unimodal, bimodal, multimodal: Classifications based on the number of modes.

Kurtosis: Measures tail heaviness and peak sharpness, complementing mode analysis.

Probability Functions


Probability Mass Function (PMF): For discrete distributions, the mode is where PMF maximizes.

Probability Density Function (PDF): For continuous distributions, the mode is where PDF maximizes.

Cumulative Distribution Function (CDF): Related through differentiation/summation but doesn't directly reveal the mode.

Specific Distribution Families


Discrete Distributions: Binomial, Geometric, Poisson, and others each have characteristic mode behaviors.

Continuous Distributions: Normal, Exponential, Beta, and others show diverse mode patterns.

Understanding distribution-specific modes helps identify which model fits observed data.

Percentiles and Quantiles


The mode can be thought of as a special type of location measure, distinct from percentiles.

The median is the 50th percentile; the mode is the maximum probability point.

Percentiles divide probability by cumulative area; the mode identifies peak density.

Maximum Likelihood Estimation


In statistics, the mode of the likelihood function identifies the maximum likelihood estimate (MLE) of parameters.

The concept of "finding the maximum" carries over from mode identification to parameter estimation.

Mixture Models


Mixture distributions create multiple modes by combining component distributions.

Each component contributes a potential mode, producing bimodal or multimodal patterns.

Identifying modes helps decompose mixtures into constituent parts.

Visual Representations


Histograms and bar charts reveal modes as tallest bars.

Density curves show modes as peaks.

Box plots don't display modes directly but show median and quartiles for comparison.

Optimization Theory


Finding the mode is a maximization problem: arg⁡max⁡f(x)\arg\max f(x).

Calculus provides tools (derivatives, critical points) for continuous cases.

Numerical optimization methods handle complex cases without closed forms.

Mode at a Glance

The page has taken the mode from its core definition through its discrete and continuous cases, modality classifications, comparison with mean and median, mathematical properties, finding procedures, common distribution formulas, and pitfalls. The table below collects the essentials into a single reference card, pairing each aspect of the mode with its concise statement and a concrete formula or example.
DownloadPNG2×PDF
Layout
AspectStatementExample or formula
What the mode isthe value where a probability distribution's mass or density reaches its maximummode = argmaxₓ pX_{X}(x) or argmaxₓ f(x)
Discrete casethe value k with the largest PMF; found by direct comparisonBinomial(10, 0.3): mode = 3
Continuous casethe value x where the PDF peaks; found via calculus (and boundary check)Normal(μ, σ): mode = μ; Exponential(λ): mode = 0
Modality classificationunimodal, bimodal, multimodal, or no unique modenormal = unimodal; mixture of two normals = bimodal; uniform = no unique mode
Compared with mean & medianpeak vs balance point vs 50th percentile — same for symmetric unimodal, separate for skewedright skew: mode < median < mean
Key propertieslinear under aX + b; invariant under monotonic g for discrete X; robust to outliers; not additivemode(aX + b) = a · mode(X) + b
When the mode shinescategorical data; detecting mixtures and subpopulations; outlier-heavy datamost-common color, most-frequent product category, MLE peak
When the mode is weaksums and convolutions (no additivity); flat distributions; small or sparse samplesmode(X + Y) ≠ mode(X) + mode(Y); uniform has no unique mode
Mode at a GlanceLearn Math Class

Skills You Should Learn

Each skill opens its step-by-step method page. Skills marked "On this page" are taught above.
Taught on this page
Random variable methods

Mode FAQ

What is the difference between max and arg max?

+
max f returns how high the peak is; arg max f returns where it stands. The mode is the second kind of answer — a location on the x-axis, not a height on the y-axis. The two agree in neither units nor meaning, and the “arg” prefix is the only mark separating them.Read more →

Does a uniform distribution have a mode?

+
Every value is a mode, so there is no unique mode. Every value ties for the highest probability, so the set-valued answer becomes the entire support — a flat top, every value tied, rather than a few separate peaks. Those two cases of no unique mode differ: a shared peak singles out a few values, a flat top does not.Read more →

What does M_o mean, and why the subscript?

+
M_o is one of the letter spellings for the mode, and the subscript “o” is doing necessary work: M alone is already busy as a maximum, a bound, a moment cap or a matrix. Only the subscript — and often only the surrounding sentence — identifies it as the mode. A hat marks the sample version against the distribution's own.Read more →

What is a MAP estimate?

+
The mode of a posterior distribution. MAP stands for maximum a posteriori: once Bayes' theorem produces a posterior over a parameter, the MAP estimate is the parameter value where that posterior peaks. It is arg max applied to a posterior rather than to a density, so one notation serves both a descriptive statistic and an estimation principle.Read more →

Does mixing two groups always give two modes?

+
No. An equal mix of two normal curves with the same spread σ\sigma dips in the middle only when their means are more than 2σ2\sigma apart; closer than that, the two humps merge into one peak. Adult heights are the standard example: men and women pooled together give a single hump, because the gap between their average heights is smaller than twice the spread within each group.Read more →

Can the mean be one of the least likely values?

+
Yes, in a distribution with two peaks. Mix normals centred at −2-2 and 22, each with σ=1\sigma = 1, half and half: the modes are near −2-2 and 22, and the mean is 00, exactly between them. But 00 sits in the dip, where the density is about a quarter of the peak height. The balance point of the distribution is a value it rarely produces.Read more →

Does the mode move with the variable when you transform it?

+
For a discrete variable and a one-to-one gg, yes: gg only relabels the values, so the mode becomes gg of the old mode. For a continuous variable it fails in general, because the density of g(X)g(X) picks up a stretching factor that can move the peak. If XX has density 2x2x on [0,1][0, 1], its mode is 11, yet X2X^2 is uniform on [0,1][0, 1]. Only linear maps aX+baX + b always carry the mode along.Read more →