When a random variable can vary continuously over an interval, probability is no longer assigned to individual points. Instead, probability is described through a density function that spreads likelihood smoothly across ranges of values.
This page introduces the Probability Density Function (PDF) as the core mathematical object behind continuous probability models. It explains how probability is recovered from areas under curves, why single points have zero probability, and how calculus—through integration and differentiation—governs every meaningful calculation involving continuous random variables.
The goal is not to catalog distributions, but to understand what a PDF is, how it works, and why it replaces discrete probability functions in the continuous setting.
For a discrete variable the probability function gives P(X = x). Try the same reading for a continuous one.
What is a PDF?
A PDF (Probability Density Function) describes how probability is distributed across a continuous random variable. Unlike discrete variables where probability sits at specific points, continuous variables spread probability across intervals.
Uniform on [0, 0.5] has f(x) = 2 at every point — and a probability of 2 is impossible.
interval
width
probability = 2 × width
[0.1, 0.2]
0.1
0.2
[0.1, 0.11]
0.01
0.02
the single point 0.1
0
0
the whole of [0, 0.5]
0.5
1
Read as an area, height times width, the same 2 gives sensible probabilities, and the whole interval gets exactly 1.
A single point has no width, so it carries no probability; only intervals do.
The Zero Probability Paradox
For any specific value a:
Definition & Physical Intuition
P(X=a)=0
This seems impossible. How can every individual outcome have zero probability, yet something must happen?
The resolution: Probability for continuous variables lives in intervals, not points. A single point is infinitesimally thin—it has no width, so it captures no probability mass. Just as a geometric point on a line has zero length, a single value in a continuous distribution has zero probability.
Example
Pick a random number between 0 and 1. What's P(X=0.5)? Exactly zero. What's P(0.49<X<0.51)? Positive. Probability only exists across ranges.
The definition
The probability density functionf of a continuous random variable gives probabilities as areas: P(a≤X≤b)=∫abf(x)dx.
Density ≠ Probability
The PDF value f(x) is not a probability. It's a density—a rate of probability per unit.
Probability is the area under the curve, not the height. This means f(x) can exceed 1, unlike a PMF where p(x)≤1 always.
So for the uniform variable on [0,0.5], P(0.1≤X≤0.2)=2×0.1=0.2.
Density is probability per unit length, as a rod has mass per unit length.
Think of it like the density of a material. A steel rod doesn't have "weight at a point"—it has density (mass per unit length). Similarly, a continuous random variable doesn't have "probability at a point"—it has probability density.
The PDF is the continuous analog of mass in the discrete case. Where mass concentrates at points, density spreads across regions.
Normal density, mean 0, standard deviation 1
Density is probability per unit length: the curve is highest at the mean, where a small interval captures the most probability, and the probability of any interval is the area above it. The height 0.4 at the centre is not itself a probability. Toggle to the CDF view and see the accumulated area on the PDF visualizer.
For a continuous variable a single point carries no probability; probability is the area under the density over an interval.
A density can be larger than 1; only its total area is fixed.
Example
Uniform distribution on [0,0.5] has f(x)=2. The density is 2, but the total probability integrates to 1.
The notation for all of this is fixed next.
The rest of the page covers notation, the support, the two axioms, the three views of a PDF, building one from a story, calculations, location and spread measures, change of variables, the link with the CDF and the densities of common distributions.
PDF Notation
Notation
PDF Notation
A function name with a subscript for the variable, and an integral wherever a probability is wanted — the notation itself says that a density is not a probability. All are catalogued among the probability symbols.
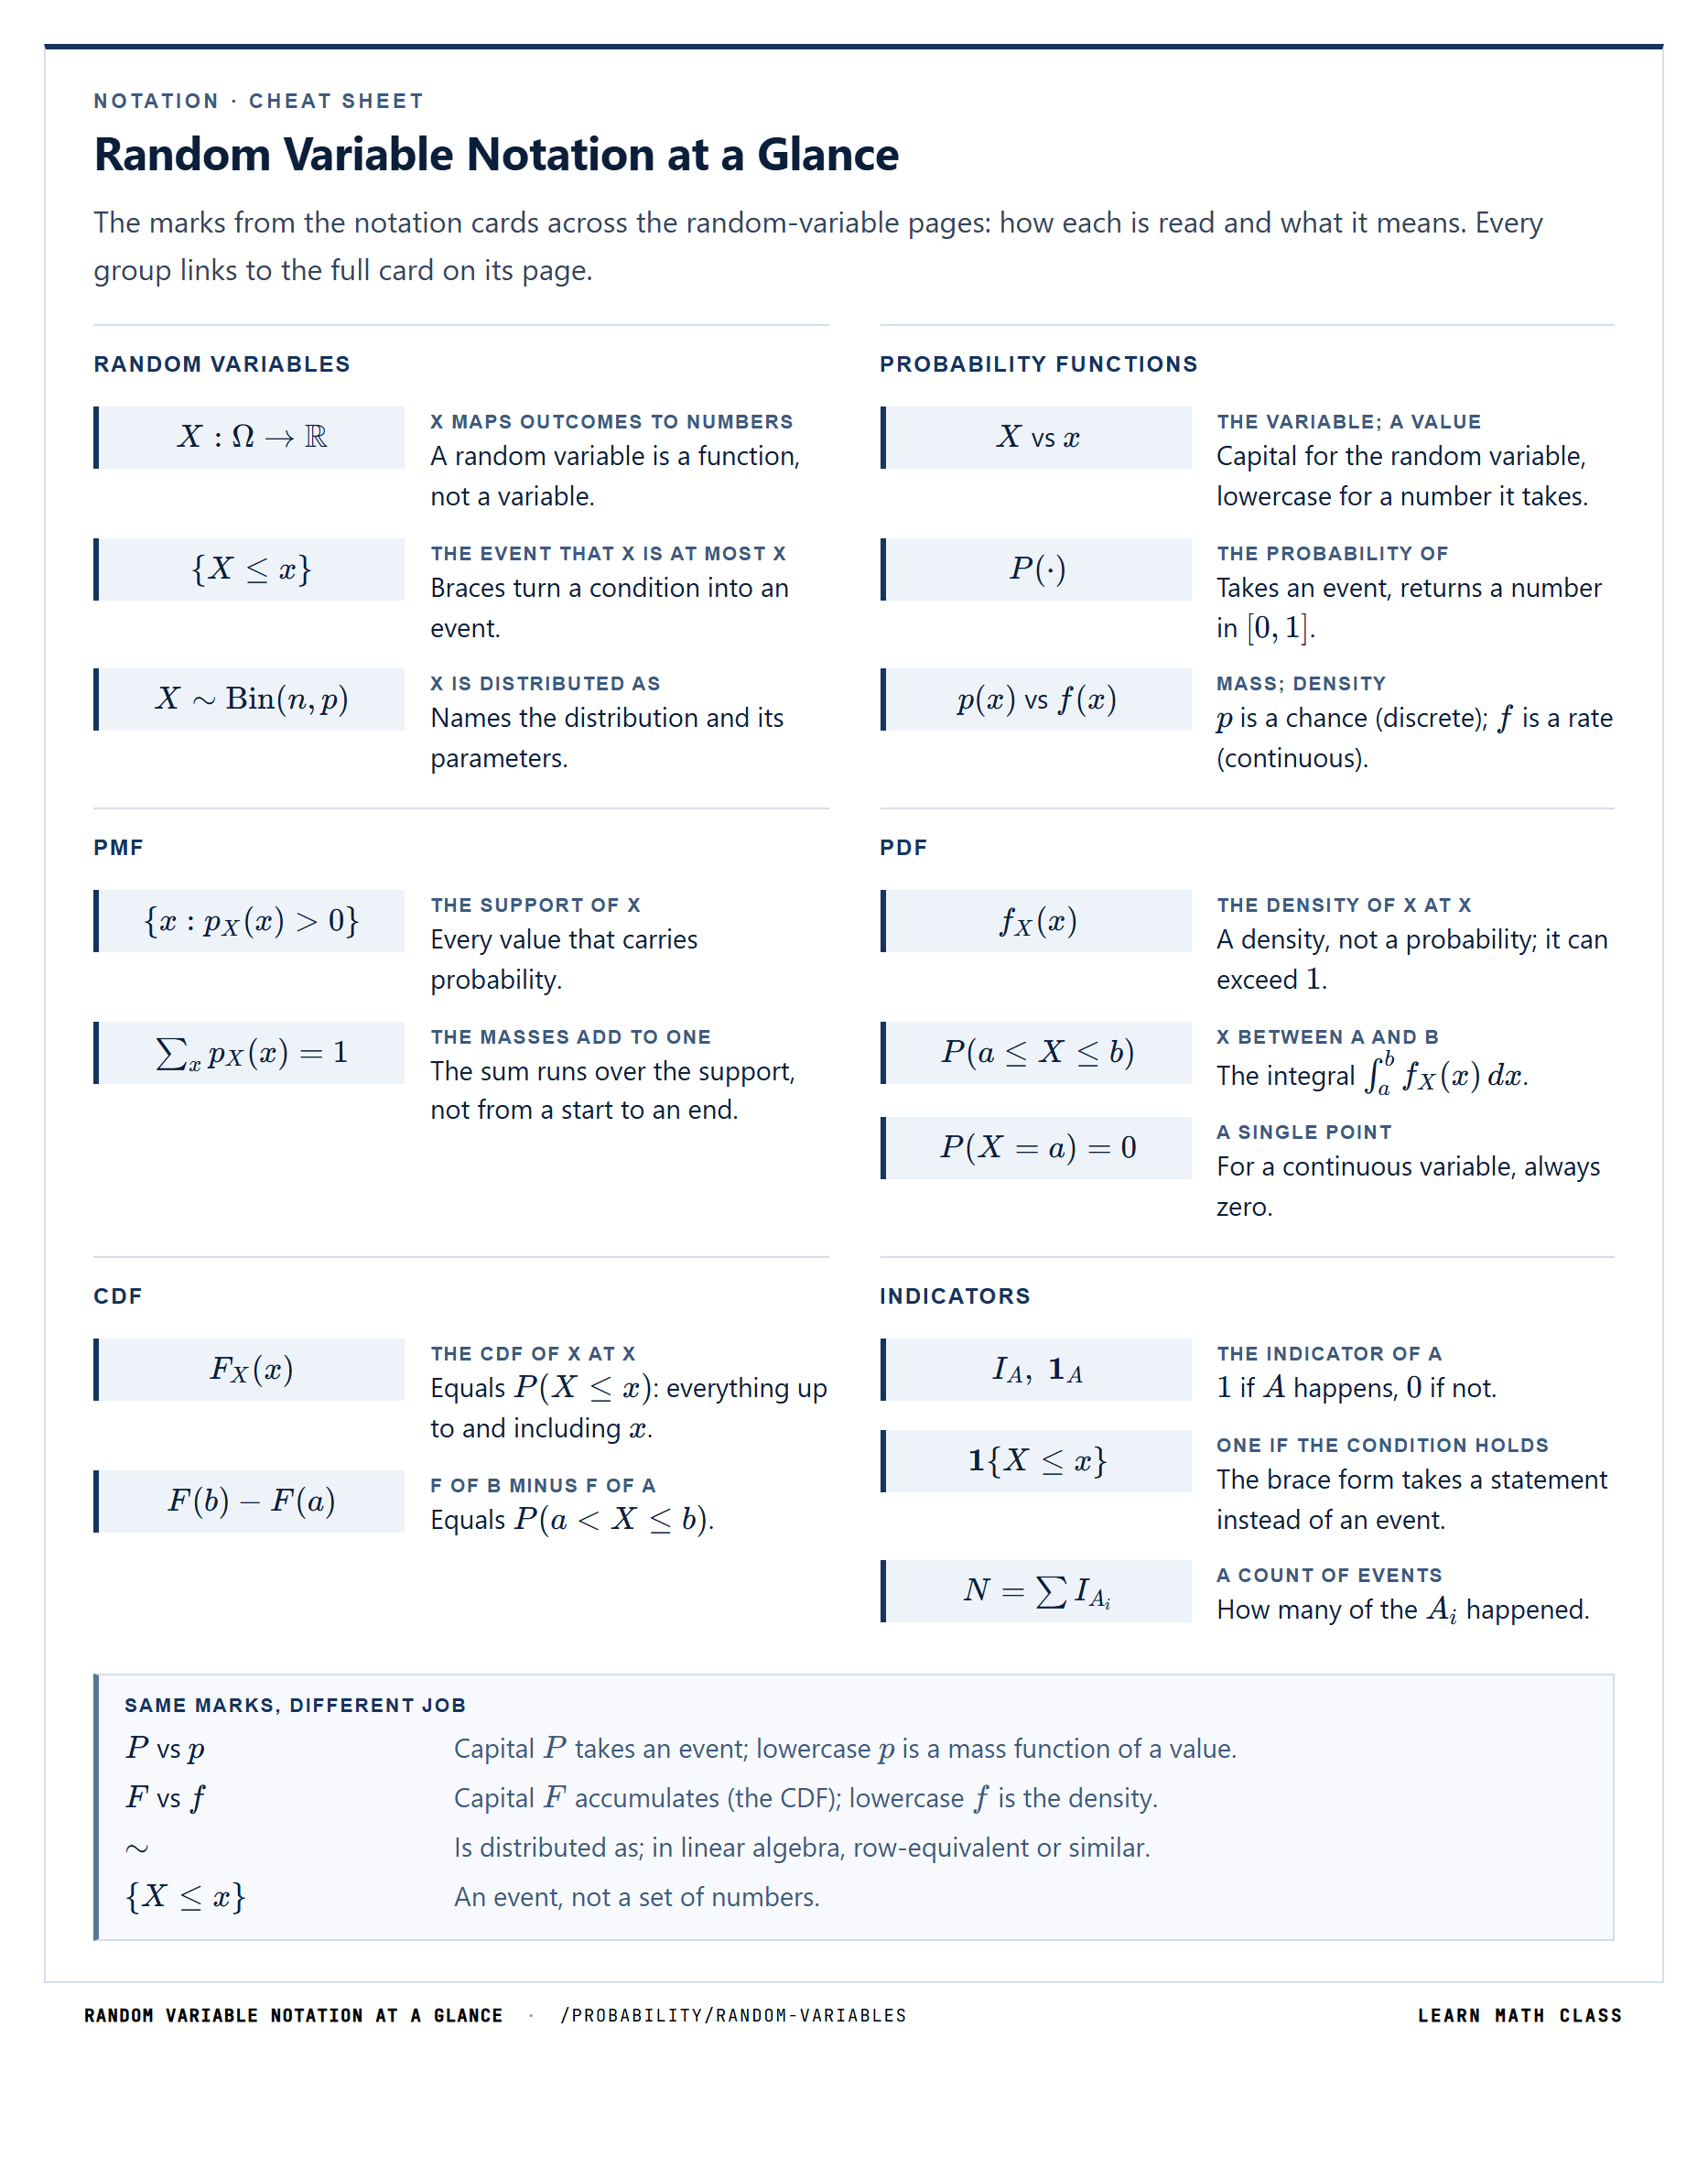
The marks from the notation cards across the random-variable pages: how each is read and what it means. Every group links to the full card on its page.
The support of a PDF is the set of values where the density is nonzero—the region where probability can be found.
Formally: The support of X is {x:fX(x)>0}.
Outside the support, fX(x)=0. No probability density exists there.
Types of Support
Bounded Support: The random variable is confined to a finite interval.
Example: Uniform distribution on [0,1]. Support is [0,1]. Outside this interval, f(x)=0.
Example: Beta distribution on [0,1]. All probability density concentrates within the unit interval.
Unbounded Support: The random variable can take values extending to infinity in both directions.
Example: Normal distribution on (−∞,∞). Support is the entire real line. Density never truly reaches zero, though it becomes negligible far from the mean.
Half-Bounded Support: Bounded on one side, unbounded on the other.
Example: Exponential distribution on [0,∞). Support starts at 0 and extends infinitely rightward.
Example: Gamma distribution on [0,∞).
Why Support Matters
The support determines: • Where to integrate when computing probabilities • What values are possible vs. impossible • The limits of integration: P(X∈A)=∫A∩SupportfX(x)dx
Pitfall: Using the formula outside the support
Integrating 2e−2x from −∞ to 1 for an exponential with λ=2 diverges, because the formula grows without bound for x<0. The density is 0 there, so P(X<1)=∫012e−2xdx=1−e−2≈0.865.
When computing P(X∈A) for some set A, only integrate over the intersection of A with the support. Outside the support contributes nothing—integrating over those regions just adds zeros.
The Two Fundamental Axioms
Every valid PDF must satisfy two non-negotiable rules. Just like the PMF in the discrete case, the PDF must obey the same foundational constraints.
The total area under the density curve must equal exactly 1.
This is your total probability budget. The entire curve must integrate to 1—no more, no less.
Fact: A density need not fade far out
Let f(x)=n on [n,n+n⋅2n1] for each whole number n≥1 and 0 elsewhere. The rectangles have areas 21,41,81,…, which add up to 1, so f is a valid density whose peaks grow without bound far out.
On an unbounded support the budget is spread over an infinitely long stretch of the line. The area out there is a sum of infinitely many pieces, one for each unit of length, and normalization only asks that these pieces add up to 1. It says nothing directly about how tall the curve may be at any particular place, near the center or far out in the tail.
To verify a function is a valid PDF: 1. Check f(x)≥0 everywhere in the support 2. Integrate over the entire support 3. Confirm the integral equals 1
If either axiom fails, you don't have a valid probability density function.
These two axioms are fundamental for both PMF and PDF. See axioms for the foundational probability principles.
A density taller than 1
The uniform density on [0, 0.5] from the page's example. It must enclose area 1 over an interval only 0.5 wide, so its height is 2. That breaks no rule: the axioms ask only that f is never negative and that the total area is 1. Probabilities come from areas, never from heights: P(0.1 < X < 0.2) = 0.1 · 2 = 0.2.
Narrow the interval to [0, 0.1] and the height rises to 10, still a valid density.
Representations: The Three Views
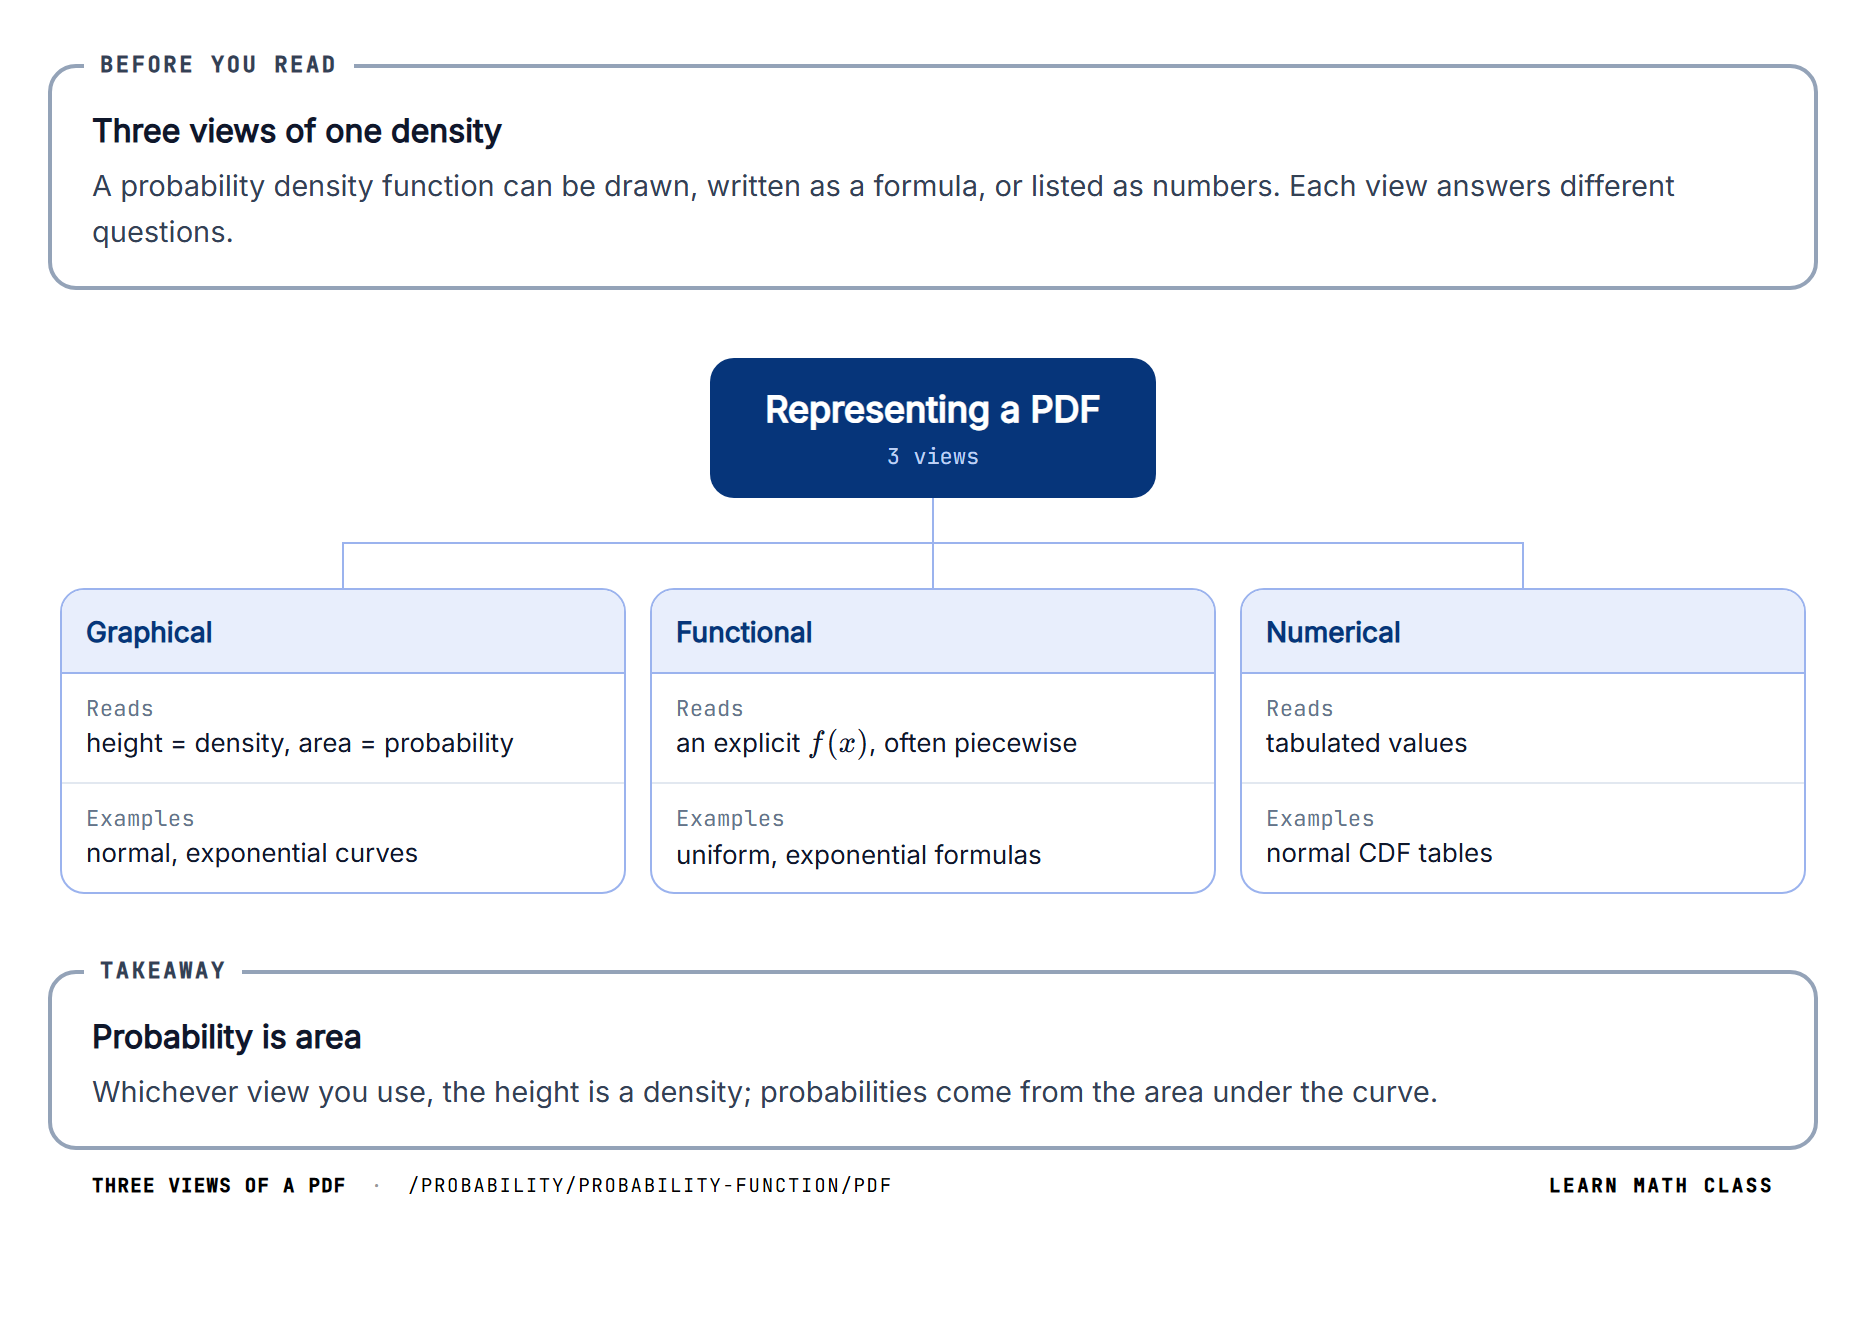
A PDF can be represented in three equivalent ways. Each offers different insights into how probability density distributes.
Graphical Representation
The PDF appears as a smooth curve on the x-y plane. The x-axis shows values of the random variable, the y-axis shows density.
Key features: • Height represents density, not probability • Area under the curve represents probability • Peaks indicate regions of high likelihood • The curve must stay non-negative • Total area under the entire curve equals 1
Example: The normal distribution shows a symmetric bell curve centered at the mean. The peak occurs at the mode, and density decreases smoothly on both sides.
Example: The exponential distribution starts at maximum density and decays monotonically toward zero.
Functional Representation
The PDF is defined by an explicit mathematical function f(x).
Every PDF starts with a story—the situation, the process, the experiment. Your job is to translate that concrete setup into mathematical form.
The Construction Process
Step 1: Identify the Random Variable
What continuous quantity are you measuring? Define it clearly.
Example: "Measure the time until a lightbulb fails" → Let T = time to failure (in hours).
Step 2: Determine the Support
What values can the random variable take? Is it bounded or unbounded?
Example: Time to failure must be positive. Support is [0,∞).
Step 3: Construct the Density Function
Use physical reasoning, symmetry, or modeling assumptions to derive f(x).
Methods: • Uniform spread: If all values in an interval are equally likely, use constant density • Exponential decay: If likelihood decreases at a constant rate, use exponential form • Symmetry: If the situation is symmetric around a center, build a symmetric density • Maximum entropy: Choose the density with maximum uncertainty given constraints
Example: Lightbulb with constant failure rate λ. The memoryless property suggests:
Building a PDF (From Story to Math)
f(t)=λe−λt for t≥0
Step 4: Verify the Axioms
Check non-negativity: Is f(x)≥0 everywhere? Yes, exponential is always positive.
Express the function clearly, including the support.
Building a PDF (From Story to Math)
fT(t)={λe−λt0if t≥0if t<0
From Physical Setup to Mathematical Object
The key skill is moving from a concrete scenario to a precise density function. Ask: • What values are possible? • How does likelihood vary across those values? • Does the assignment satisfy the axioms?
Once built, the PDF becomes a complete mathematical description of the random variable's behavior.
Calculations Using the PDF
Once you have a PDF, you can compute probabilities for any event involving the random variable. Unlike PMF, all calculations require integration.
Interval Probabilities
The core calculation: probability over an interval equals the area under the curve.
The exponential example follows the pattern every interval probability uses: find an antiderivative of the density, evaluate it at the upper limit, and subtract its value at the lower limit. Because this density decreases, the interval [1,3] holds far less probability than the interval [0,2] of the same length, which holds 1−e−4≈0.982.
Inequalities Are Irrelevant
For continuous variables, endpoint inclusion doesn't matter:
Calculations Using the PDF
P(X<a)=P(X≤a)
Calculations Using the PDF
P(X>a)=P(X≥a)
Calculations Using the PDF
P(a<X<b)=P(a≤X≤b)
Why? Because P(X=a)=0 for any single point. Adding or removing a zero-probability point doesn't change the total.
Example
P(X<5)=P(X≤5) exactly. No approximation, no difference.
Use the complement when integration is easier in the opposite direction:
Calculations Using the PDF
P(X∈/A)=1−P(X∈A)
Example: P(X>10)=1−P(X≤10)
The Core Pattern
Every probability question reduces to: 1. Identify the interval or region 2. Set up the integral with correct bounds 3. Integrate the PDF over that region 4. Evaluate
The PDF gives complete information. If you know fX(x) for all x, you can answer any probability question about X.
Derived Properties: Location Measures
The PDF contains all the information about a random variable. From it, we can compute summary measures that describe where the distribution is centered.
Expected Value (Mean)
The expected value is the probability-weighted average across all possible values, computed via integration.
A distribution can have multiple modes if the PDF has several local maxima.
Why These Matter
Location measures summarize where the distribution sits on the number line. They answer: "What's a typical value?" Each measure captures a different notion of "typical."
Derived Properties: Spread Measures
Location tells you where the distribution centers. Spread tells you how widely values scatter around that center.
Variance
Variance quantifies the average squared deviation from the mean, computed through integration.
Derived Properties: Spread Measures
Var(X)=∫−∞∞(x−E[X])2⋅fX(x)dx
Each squared distance from the mean is weighted by density. High-density regions far from the mean contribute heavily to variance.
Standard deviation has the same dimensionality as X itself, making interpretation more direct than variance.
Interquartile Range
The IQR measures spread using percentiles rather than deviations from the mean.
Derived Properties: Spread Measures
IQR=Q3−Q1
where Q1 is the 25th percentile and Q3 is the 75th percentile.
Find quartiles by solving: ∫−∞Q1fX(x)dx=0.25 and ∫−∞Q3fX(x)dx=0.75
IQR is robust to outliers and heavy tails—extreme values don't affect it the way they affect variance.
What Spread Reveals
Narrow spread means values cluster tightly, making individual outcomes more predictable. Wide spread means values scatter broadly, increasing uncertainty about any single observation. Two distributions with identical means can behave completely differently based on their spread.
Transformations (Change of Variables)
Apply a function to a random variable, and you create a new random variable with its own PDF. The transformation process requires careful handling of how density changes.
The Transformation Problem
Start with random variable X with PDF fX(x).
Apply function g to get Y=g(X).
The new PDF fY(y) must account for how g stretches or compresses intervals—this affects density.
The factor ∣a∣1 appears because scaling the variable by a compresses or stretches the density axis.
Example: If X is uniform on [0,1] with fX(x)=1, then Y=3X has:
Transformations (Change of Variables)
fY(y)=31⋅1=31 for y∈[0,3]
The density drops to 31 because the interval stretched by factor 3.
Pitfall: Leaving out the factor 1/|a|
Writing fY(y)=fX(3y)=1 on [0,3] substitutes without the factor, and the area under fY becomes 3. With the factor, fY(y)=31⋅1=31 and the area is 1.
Two things happen in the linear formula. The argument ay−b sends each value y back to the value of X it came from, which fixes where the density sits on the new axis. The factor in front sets how tall the density is there.
Example: Y=X+5 shifts the distribution but doesn't change density shape:
Transformations (Change of Variables)
fY(y)=fX(y−5)
General Transformations (Invertible)
For invertible g (strictly increasing or decreasing), the transformation formula includes the Jacobian:
The derivative term dydg−1(y) is the Jacobian—it measures how g locally stretches or compresses space.
Alternative form using g′(x):
Transformations (Change of Variables)
fY(y)=fX(x)⋅∣g′(x)∣1
where x=g−1(y)
Example: Y=X2 for X>0. Then g−1(y)=y and dydy=2y1.
Transformations (Change of Variables)
fY(y)=fX(y)⋅2y1
Fact: Squares pile up near zero
If X is uniform on [0,1], then Y=X2 has density 2y1, which grows without bound as y→0. A tenth of all the probability lands in [0,0.01], because Y≤0.01 exactly when X≤0.1, yet the total area is still ∫012y1dy=1.
Take X uniform on [0,1], so that fX=1 there and Y=X2 also stays inside [0,1]. Squaring moves every value strictly between 0 and 1 downward, and it squeezes the values near 0 hardest: 0.1 becomes 0.01, and 0.01 becomes 0.0001. Probability that was spread over a stretch of x values now sits on a much shorter stretch of y values.
Another route to the same density goes through the CDF of Y: find FY first, then differentiate.
The Jacobian includes ∣⋅∣ because density must remain non-negative. Whether g increases or decreases, the density adjustment stays positive.
Probability is preserved: P(a≤X≤b)=P(g(a)≤Y≤g(b)) for increasing g (for decreasing g the bounds swap: P(g(b)≤Y≤g(a)))
The Jacobian ensures total area under the new PDF still integrates to 1.
Non-Invertible Transformations
When g is not one-to-one, multiple x values map to the same y. Sum their contributions:
Transformations (Change of Variables)
fY(y)=x:g(x)=y∑∣g′(x)∣fX(x)
This generalizes the invertible case by collecting all pre-images.
Key Insight
Transformations redistribute probability density across a new domain. The Jacobian factor adjusts for how the transformation stretches or compresses regions, ensuring probability conservation. Density can change dramatically even when total probability stays fixed at 1.
Change of variables: Y = 3X
X is uniform on [0, 1] with density 1 (blue). Multiplying by 3 spreads the same probability over [0, 3], three times as wide, so the density of Y = 3X must drop to 1/3 (amber) for the area to stay 1. This is the factor |d/dy g⁻¹(y)| = 1/3 in the change-of-variables formula.
A shift, Y = X + 5, moves the rectangle without changing its height.
Connection to CDF (The Fundamental Theorem)
The PDF and the CDF (Cumulative Distribution Function) are two representations of the same probability distribution. They are connected through the fundamental operations of calculus: integration and differentiation.
From PDF to CDF (Integration)
The CDF accumulates probability from the PDF through integration:
Connection to CDF (The Fundamental Theorem)
FX(x)=P(X≤x)=∫−∞xfX(t)dt
The CDF at any point equals the total area under the PDF curve from −∞ up to that point.
This relationship is the Fundamental Theorem of Calculus applied to probability:
Connection to CDF (The Fundamental Theorem)
dxd∫−∞xfX(t)dt=fX(x)
Integration builds up cumulative probability. Differentiation recovers the density function. They are inverse operations.
Graphical Relationship
PDF: Shows where density concentrates (peaks and valleys)
CDF: Shows accumulated probability (always rising, reaches 1)
The steeper the CDF at point x, the higher the PDF at that point. Flat regions in the CDF correspond to zero density in the PDF.
Why Both Exist
The PDF answers: "How dense is probability at this point?"
The CDF answers: "What's the probability of at most this value?"
Different questions favor different representations. The PDF is better for understanding density and finding modes. The CDF is better for computing cumulative probabilities and percentiles. Both describe the same underlying distribution completely.
Normal CDF, mean 0, standard deviation 1
The CDF is the running area under the density, so its slope at any point is the density there: the S-curve is steepest at the mean where the bell is highest and flattens in the tails where the bell is low. Differentiating F recovers f and integrating f recovers F. Move along the curve and compare slope with density on the continuous CDF visualizer.
The named continuous families are catalogued next.
PDFs of Common Continuous Distributions
Certain probability scenarios appear so frequently that their PDFs have been studied, named, and cataloged. These are the standard continuous distributions.
Each distribution models a specific type of random process. Once you recognize the pattern, you can use the established PDF formula instead of deriving it from scratch.
Uniform Distribution
PDF: f(x)=b−a1 for x∈[a,b], zero elsewhere.
The PDF is completely flat—constant density across the entire support. Probability spreads evenly, with no value more likely than any other. This represents maximum uncertainty given only the interval bounds. The PDF height equals interval length1 to ensure total area equals 1. For [0,1], density is exactly 1. For [0,10], density drops to 101.
The PDF forms the iconic bell curve—symmetric, smooth, and unimodal. The peak sits at the mean μ, where density is maximized. Density decreases symmetrically on both sides following the exponential of a quadratic. The parameter σ controls spread: small σ creates a narrow, tall peak; large σ creates a wide, flat curve. The PDF never reaches zero but becomes negligibly small beyond μ±3σ. The exponential decay ensures finite total area despite infinite support. This is the most important distribution in statistics due to the Central Limit Theorem.
The PDF starts at maximum density λ at x=0 and decays exponentially toward zero. It decreases monotonically—no peaks or valleys, just continuous decline. The rate parameter λ controls how fast decay occurs: high λ produces rapid drop-off and concentration near zero; low λ produces slow decay and spread across larger values. The exponential PDF has the memoryless property—the remaining distribution shape doesn't depend on how much time has passed. Each step multiplies density by constant factor e−λ. Despite infinite support, the integral converges to 1 due to exponential shrinkage.
The PDF is remarkably flexible, changing shape dramatically based on parameters α and β. For α,β>1, it's unimodal with peak inside (0,1). For α,β<1, it's U-shaped with density concentrating at the endpoints. For α=β, it's symmetric around 21. For α=β, it's skewed. The normalizing constant B(α,β) ensures integration to 1. As α increases, mass shifts toward 1; as β increases, mass shifts toward 0. Special case: α=β=1 reduces to uniform on [0,1]. The bounded support makes it ideal for modeling proportions, probabilities, and rates.
PDF Patterns
Each PDF has characteristic behavior: where density concentrates, how it spreads, whether it's symmetric or skewed, how parameters reshape the curve. These patterns reflect the underlying random process and determine the distribution'sexpected value and variance. Recognizing PDF shapes helps identify which distribution models your data.
Exponential density, lambda = 1, with the mean marked
The catalogue of continuous densities includes this decaying curve for waiting times, the flat uniform density and the normal bell; each is a different rule for spreading unit area over the line. The explorer marks the mean on each, here at 1 over lambda. Compare the three shapes and their parameters on the distribution explorer.
Each family has its own page with parameters, moments and applications.
Common Pitfalls
Each of the three mistakes below is marked where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.
Using the formula outside the support
A density is given by a formula on its support and is 0 elsewhere. When a probability is set up, the formula is integrated over the whole interval of the event, including the part that lies outside the support.
Wrong working: for the exponential density f(x)=2e−2x, x≥0,
P(X<1)=∫−∞12e−2xdx=[−e−2x]−∞1
As x→−∞, e−2x grows without bound, so the integral diverges.
Right working: the density is 0 for x<0, so only the part of the event inside the support counts.
P(X<1)=∫012e−2xdx=[−e−2x]01=1−e−2≈0.865
Why it happens: the formula is the part of the PDF that is written large, while the condition x≥0 sits beside it and is easy to drop. The tail formula P(X<a)=∫−∞afX(x)dx then invites the lower limit −∞.
How to check: a probability is a number between 0 and 1. An infinite or negative result, or one above 1, means the integral has run where the density is 0. Writing the support next to the limits before integrating catches it.
Dropping the minus sign of the antiderivative
An interval probability for the exponential density is set up correctly, but the antiderivative of e−2x is taken without the factor that comes from the chain rule, so its sign is lost.
Right working: differentiating −e−2x gives 2e−2x, so −e−2x is the antiderivative.
∫132e−2xdx=[−e−2x]13=−e−6+e−2≈0.133
Why it happens: ex is its own antiderivative, and that rule is carried over to e−2x without accounting for the inner factor −2.
How to check: differentiate the antiderivative and compare it with the density; dxde−2x=−2e−2x, which has the wrong sign. A negative probability is always a sign of an error.
Leaving out the factor 1/|a|
The PDF of a linear transformation Y=aX+b is found by substituting ay−b into fX, and the factor ∣a∣1 in front is left out.
Wrong working: for X uniform on [0,1] and Y=3X,
fY(y)=fX(3y)=1 for y∈[0,3]
The area under this function is 1⋅3=3.
Right working: the factor ∣a∣1=31 scales the height.
fY(y)=31fX(3y)=31 for y∈[0,3]
The area is 31⋅3=1.
Why it happens: for a PMF the substitution alone is correct, because each value keeps its own probability when it is moved. A density is probability per unit length, and stretching the axis by a factor 3 spreads the same probability over three times the length.
How to check: integrate the new density over its support. If the area is not 1, the factor is missing; here the wrong answer has area 3, exactly ∣a∣.
PDF FAQ
Why is the probability at a single point zero for a continuous variable?
+
Because probability is the area under the density, and a single point has no width. Integrating f over an interval of zero length gives zero, whatever the density's height there. This does not mean the value cannot occur — every observation lands on some point. It means probability for a continuous variable lives on intervals, never on individual points.Read more →
Can a PDF value exceed 1?
+
Yes. A PMF returns probabilities, so its values are capped at 1; a PDF returns density, which has no such ceiling. What must equal 1 is the total area, not any height. A uniform distribution on [0, 0.1] has f(x) = 10 across that interval — perfectly valid, since 10 × 0.1 = 1.Read more →
Does it matter whether you use < or ≤ for a continuous variable?
+
No — they give identical answers. P(X < a) and P(X ≤ a) differ by the single point a, which carries zero probability, so all four of <, ≤, >, ≥ agree. This is the opposite of the discrete case, where including or excluding an endpoint changes the answer by that value's whole probability.Read more →
What does the value of a PDF actually tell you?
+
A rate, not a probability. f(5) = 0.8 means the density at 5 is 0.8 — roughly, probability per unit of x in that neighborhood — not that anything has probability 0.8. To get a probability you integrate over an interval. Saying “the probability at x = 5 is 0.8” is the phrasing to avoid.Read more →
Why does the change-of-variables formula need an absolute value?
+
To keep the density non-negative. Transforming a variable multiplies the density by the derivative of the inverse map, and that derivative is negative whenever the transformation reverses direction. Without the absolute value the result would be a negative density, violating the axioms. The bars record that only the magnitude of the stretch matters, not its orientation.Read more →
Does a PDF have to approach zero far out in the tails?
+
No. Normalization only asks that the total area be 1; it says nothing about the height at any particular place. Let f(x)=n on [n,n+n⋅2n1] for each whole number n≥1 and 0 elsewhere. The rectangles have areas 21,41,81,…, which add up to 1, so f is a valid density whose peaks grow without bound far out.Read more →
Can a PDF go to infinity and still be valid?
+
Yes, as long as the area stays 1. If X is uniform on [0,1], then Y=X2 has density 2y1, which grows without bound as y→0, yet ∫012y1dy=1. Squaring crowds the values toward 0: a tenth of all the probability lands in [0,0.01], because Y≤0.01 exactly when X≤0.1.Read more →