Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Cumulative Distribution Function (CDF)


Accumulating Probability


When working with random variables, we are often not interested in the probability of an exact value, but in how much probability lies up to a certain point. Questions like "How likely is the value to be below this threshold?" or "What fraction of outcomes fall to the left of this number?" appear naturally.

The cumulative distribution function captures this idea directly. Instead of focusing on individual outcomes, it tracks how probability accumulates as values increase along the number line. This single object provides a unified way to describe distributions, whether they are discrete, continuous, or a mixture of both.

The sections that follow explain how this accumulation works, how it is defined formally, and why the cumulative distribution function plays a central role in probability theory.

Key Terms

Cumulative Distribution Function— FX(x)=P(X≤x)F_X(x) = P(X \leq x)
Joint CDF— FX,Y(x,y)=P(X≤x,Y≤y)F_{X,Y}(x,y) = P(X \leq x, Y \leq y)
Probability Mass Function— relates to CDF by summation for discrete variables
Probability Density Function— relates to CDF by integration for continuous variables
Random Variable— the object the CDF characterizes

See All Probability Definitions →


From Events to Random Variables

Many questions about a random number ask whether it stays below some level.
Probability is first defined for events, but many questions involve numerical values rather than yes-or-no outcomes. A random variable connects these two views by assigning a number to each outcome of an experiment.
Once a random variable is defined, statements about its value naturally form events. Expressions like X≤xX \le x, X>xX > x, or a<X≤ba < X \le b describe collections of outcomes and therefore have probabilities attached to them.
question about a die roll Xas an event
at most 4?X ≤ 4
more than 2?X > 2
between 3 and 5?2 < X ≤ 5
Answering each such question from scratch is tedious. One list that answered every "at most xx" at once would answer the others too.
For a die, a running total of the probabilities builds that list.
A fair die shows each face with probability 16\frac{1}{6}. Go up the faces and keep a running total: the probability of rolling at most xx.
xP(X = x)P(X ≤ x): running total
11/61/6
21/62/6
31/63/6
41/64/6
51/65/6
61/66/6 = 1
"More than 22" is then 1−26=461 - \frac{2}{6} = \frac{4}{6}, and "between 33 and 55" is 56−26=36\frac{5}{6} - \frac{2}{6} = \frac{3}{6} — read off the same column.
Nothing in the running total was chosen: each entry is the last one plus one more probability.
So the column can only stay the same or grow, it starts at 00 before the smallest value and ends at 11 after the largest. Between faces nothing is added, so the total stays flat and then jumps at each face — a staircase.
0.00.20.40.60.81.0123456Value (k)Cumulative Probability F(k)
The running total for a die, drawn: flat between faces, a jump of 16\frac{1}{6} at each face, ending at 11. The same state is on the discrete CDF visualizer.
The definition
The cumulative distribution function of a random variable XX gives, for each real number xx, the probability that XX is at most xx: F(x)=P(X≤x)F(x) = P(X \le x).
For the die, F(4)=46F(4) = \frac{4}{6}. The next two sections state the meaning and the formal definition in full.
A CDF is a function, defined for every real number, not only for the values X can take.
Its input is any number xx and its output is a probability between 00 and 11. For the die, F(4.7)=46F(4.7) = \frac{4}{6} and F(−3)=0F(-3) = 0, even though the die never shows 4.74.7 or −3-3.
The cumulative distribution function is built exactly on this connection. It takes events of the form X≤xX \le x and assigns to each value xx the probability of that event, linking random variables back to the event-based foundation of probability.
Running totals generalize; the jumps were particular to a die, and they make ≤ and < differ.
What generalizes: every random variable has a CDF, built the same way. What was particular: a die's values are separate, so its CDF climbs in jumps; a continuous variable such as a measured height has a CDF that rises smoothly. And at a jump, "at most" and "less than" are different questions.
questionvalue
P(X ≤ 4)4/6
P(X < 4)3/6: the jump at 4 is left out
P(X ≤ 4.7)4/6: nothing new between 4 and 5
The rest of the page states the CDF's core meaning and formal definition, its notation and properties, the CDF of discrete, continuous and mixed variables, and how to use it to find probabilities.

CDF Defined (Core Meaning)


The cumulative distribution function describes how probability is distributed along the values of a random variable. For each possible value, it tells us how much probability has accumulated up to that point.

Instead of asking whether the random variable takes one specific value, the CDF answers a broader question: how likely it is that the value does not exceed a given level. As the value increases, the accumulated probability can only stay the same or grow.

This perspective is what makes the CDF so powerful. It focuses on accumulation rather than individual outcomes, providing a single, consistent way to describe the behavior of a random variable across its entire range.

Mathematical Definition


Formally, the cumulative distribution function of a random variable XX is defined by

CDF Definition
FX(x)=P(X≤x)F_X(x) = P(X \le x)
Learn more about this formula: CDF Definition →


For each real number xx, the CDF assigns the probability that the random variable takes a value less than or equal to xx. The function FXF_X maps numbers on the real line to values between 0 and 1.

The choice of "less than or equal to" is not arbitrary. It ensures that the CDF behaves consistently across discrete, continuous, and mixed random variables, allowing a single definition to cover all cases.

CDF Notation

Notation

CDF Notation

One capital letter, one subscript, and one inequality sign that was chosen rather than inherited. The case of the letter is the whole distinction between a probability and a density, and every mark here is catalogued among the probability symbols.
XX, xx, P(⋅)P(\cdot) and the density f(x)f(x) come from the probability function; the event braces {X≤x}\{X \le x\} that PP measures from random variable notation.
FX(x)F_X(x)
capital F sub X of x — the CDF of X at x
Capital FF names the cumulative function, and the subscript names which variable it belongs to: FX(x)=P(X≤x)F_X(x) = P(X \le x), per Mathematical Definition above. The subscript earns its place the moment two variables share a page — FXF_X and FYF_Y are different functions.
CasesThe subscript is dropped when only one variable is in play, leaving plain F(x)F(x); the argument is always a number on the real line, so FF is defined everywhere even where the variable never lands.
Do not confuseThe density f(x)f(x). One letter, two cases, two different objects: FF accumulates and is bounded by 11, while lowercase ff is a rate that may exceed 11 — CDF vs PMF vs PDF below sets them side by side, and calculus ties them together as F′=fF' = f.
P(X≤x)P(X \le x)
the probability that X is at most x
The inequality is a convention, not an accident: writing ≤\le rather than << includes the point itself, which is what makes the CDF right-continuous and lets one definition serve discrete, continuous and mixed variables alike.
CasesFor continuous variables the choice is invisible — P(X=x)=0P(X = x) = 0, so ≤\le and << agree; for discrete ones it decides whether a jump belongs to the step before or after it, which is exactly where Common Mistakes below finds its errors.
Do not confuseA strict inequality. F(3)F(3) includes the outcome 33 — the strict version P(X<3)P(X < 3) is what excludes it, and the two differ by exactly the mass sitting at the point.
F(b)−F(a)F(b) - F(a)
F of b minus F of a
The idiom for interval probabilities: accumulating to bb and subtracting what accumulated to aa leaves P(a<X≤b)P(a < X \le b) — the notation of Using the CDF to Compute Probabilities below, and the reason the CDF is a computational tool rather than a description.
CasesThe same shape as the evaluation bracket of definite integrals — and not by coincidence: for continuous variables F(b)−F(a)F(b) - F(a) is exactly ∫abf(x) dx\int_a^b f(x)\,dx.
Do not confuseWhich endpoint is included. The difference gives P(a<X≤b)P(a < X \le b) — open on the left, closed on the right; for discrete variables shifting to P(a≤X≤b)P(a \le X \le b) requires adding the mass at aa back in.
DownloadPNG2×PDF
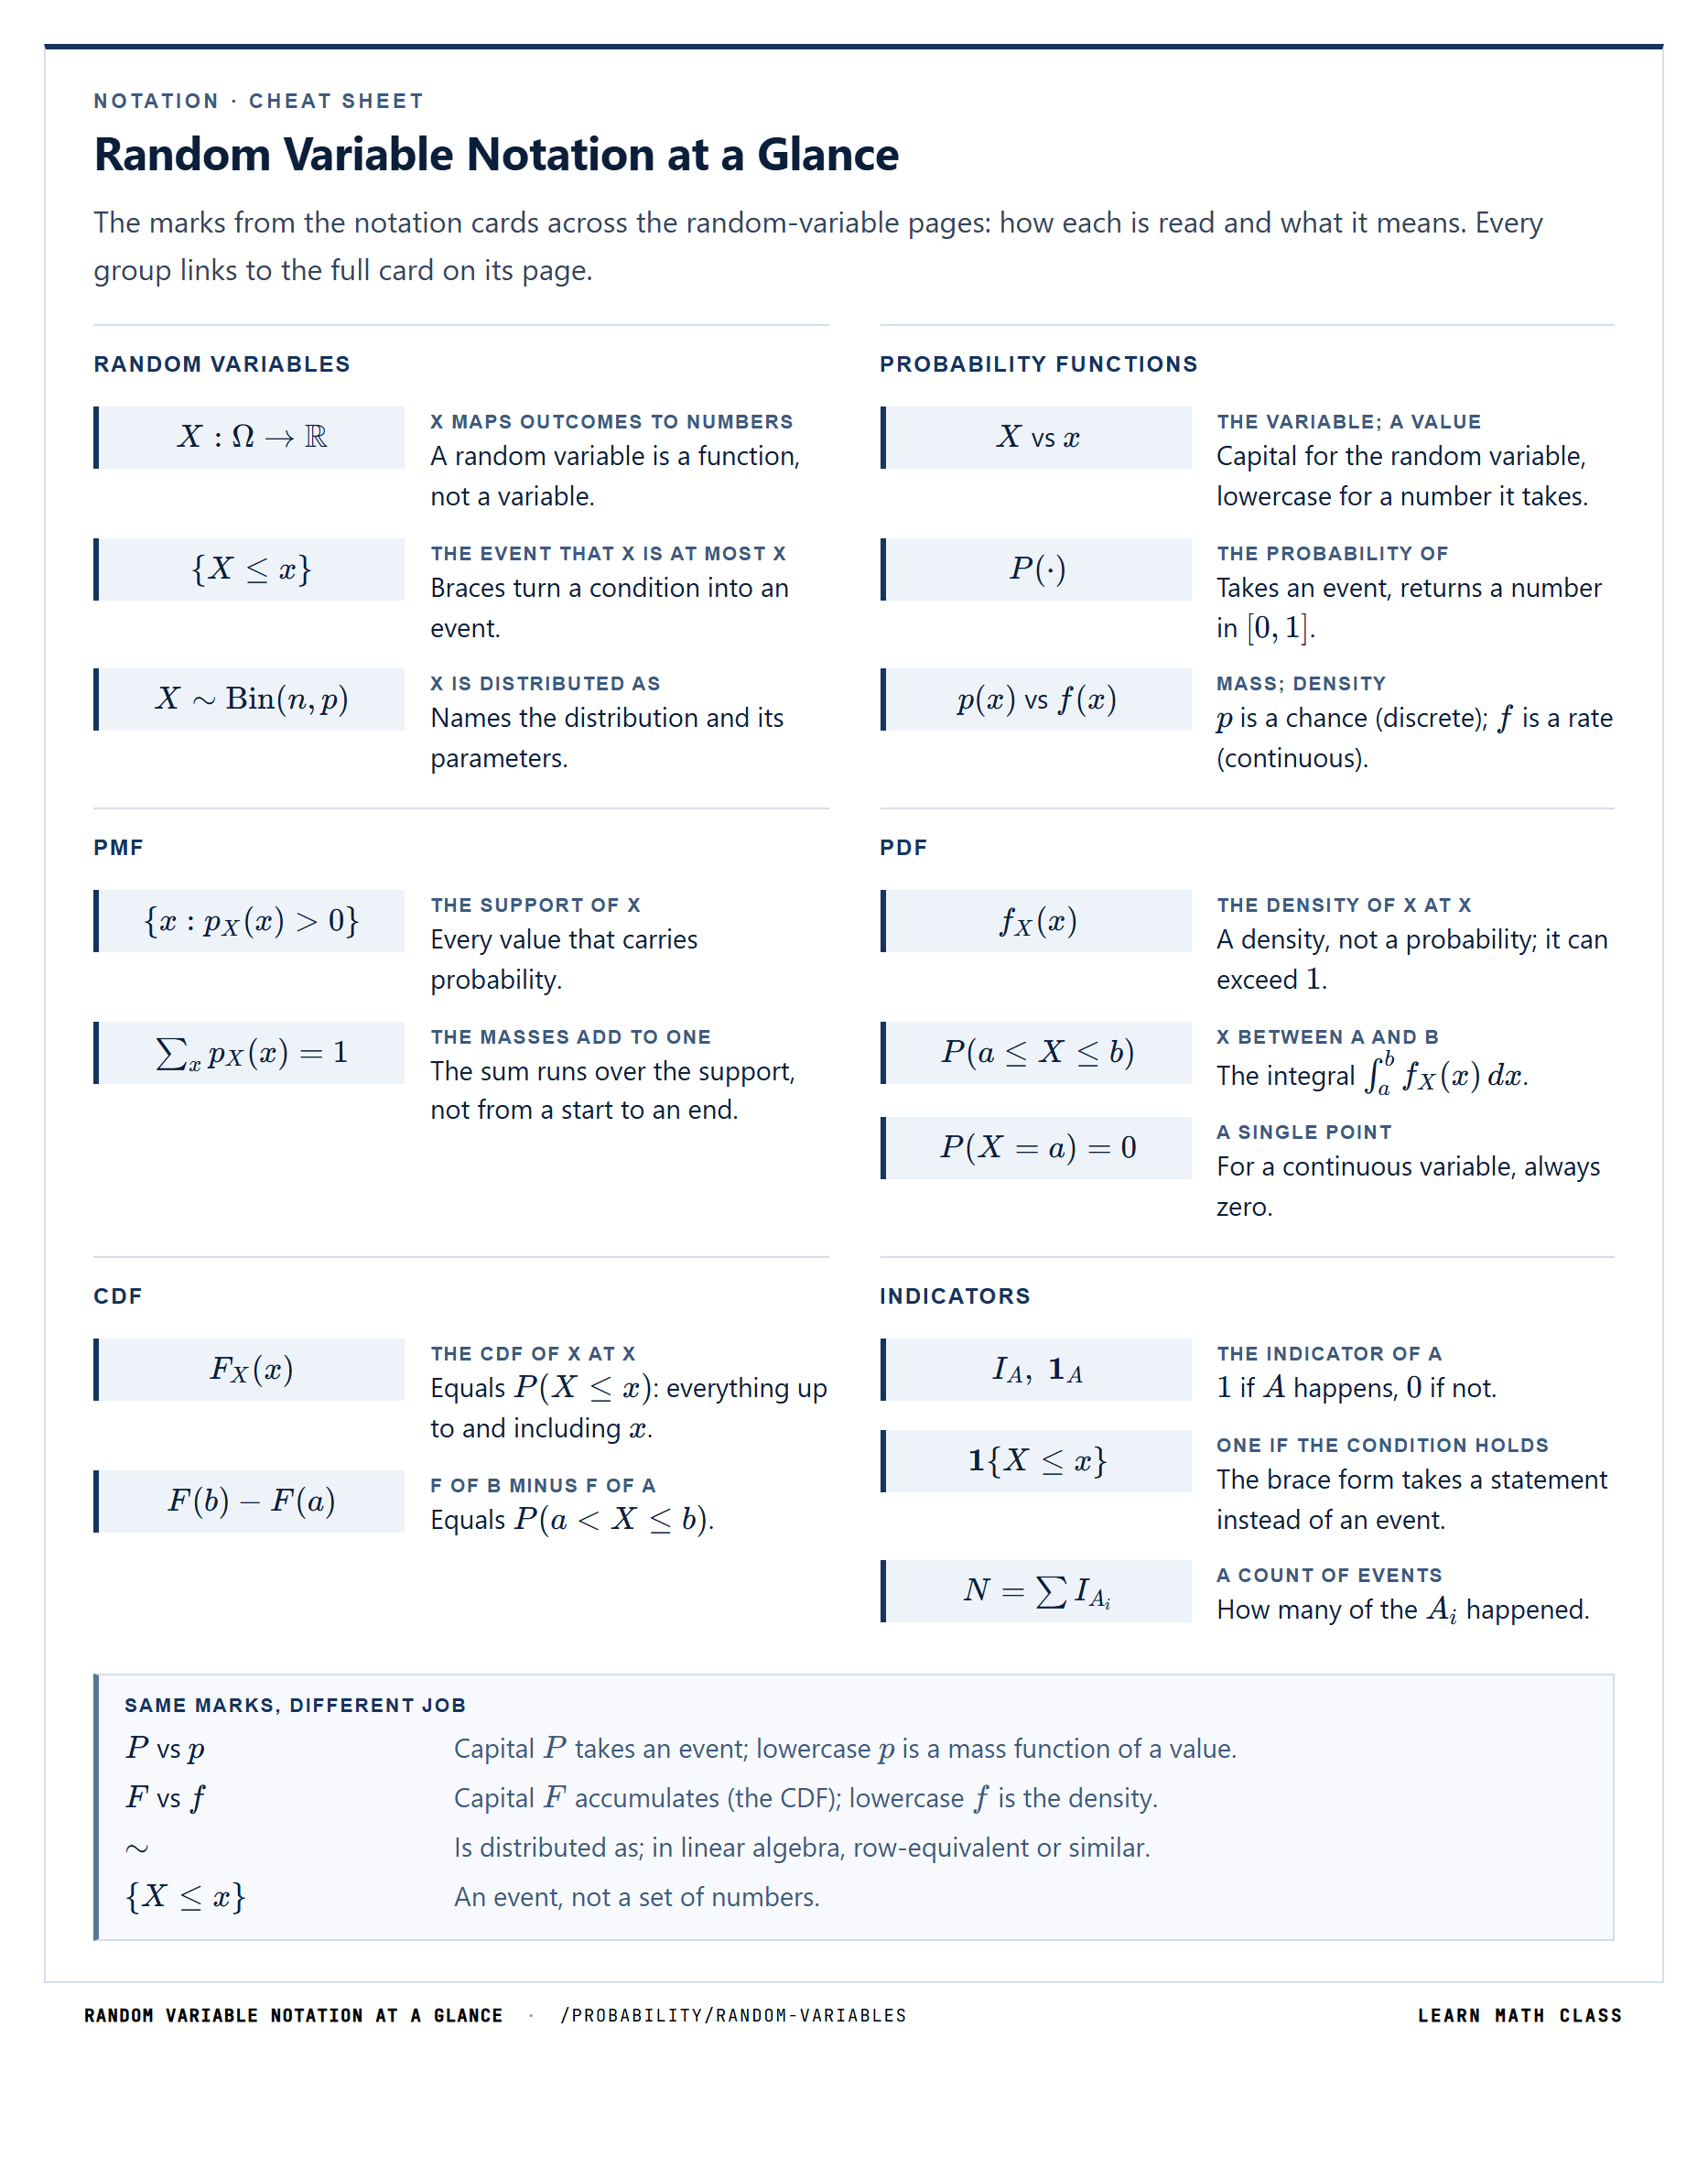
Notation · Cheat sheet
Random Variable Notation at a Glance
The marks from the notation cards across the random-variable pages: how each is read and what it means. Every group links to the full card on its page.
Random variables
X:Ω→RX : \Omega \to \mathbb{R}
X maps outcomes to numbers
A random variable is a function, not a variable.
{X≤x}\{X \le x\}
the event that X is at most x
Braces turn a condition into an event.
X∼Bin(n,p)X \sim \text{Bin}(n, p)
X is distributed as
Names the distribution and its parameters.
Probability functions
XX vs xx
the variable; a value
Capital for the random variable, lowercase for a number it takes.
P(⋅)P(\cdot)
the probability of
Takes an event, returns a number in [0,1][0, 1].
p(x)p(x) vs f(x)f(x)
mass; density
pp is a chance (discrete); ff is a rate (continuous).
PMF
{x:pX(x)>0}\{x : p_X(x) > 0\}
the support of X
Every value that carries probability.
∑xpX(x)=1\sum_{x} p_X(x) = 1
the masses add to one
The sum runs over the support, not from a start to an end.
PDF
fX(x)f_X(x)
the density of X at x
A density, not a probability; it can exceed 11.
P(a≤X≤b)P(a \le X \le b)
X between a and b
The integral ∫abfX(x) dx\int_a^b f_X(x)\,dx.
P(X=a)=0P(X = a) = 0
a single point
For a continuous variable, always zero.
CDFThis page
FX(x)F_X(x)
the CDF of X at x
Equals P(X≤x)P(X \le x): everything up to and including xx.
F(b)−F(a)F(b) - F(a)
F of b minus F of a
Equals P(a<X≤b)P(a < X \le b).
Indicators
IA,  1AI_A, \; \mathbf{1}_A
the indicator of A
11 if AA happens, 00 if not.
1{X≤x}\mathbf{1}\{X \le x\}
one if the condition holds
The brace form takes a statement instead of an event.
N=∑IAiN = \sum I_{A_i}
a count of events
How many of the AiA_i happened.
Same marks, different job
PP vs ppCapital PP takes an event; lowercase pp is a mass function of a value.
FF vs ffCapital FF accumulates (the CDF); lowercase ff is the density.
∼\simIs distributed as; in linear algebra, row-equivalent or similar.
{X≤x}\{X \le x\}An event, not a set of numbers.
Random Variable Notation at a Glance·/probability/random-variablesLearn Math Class

Key Properties of the CDF


    The cumulative distribution function obeys several fundamental properties that follow directly from the probability axioms.

  • Values between 0 and 1
    For every xx, the CDF satisfies 0≤FX(x)≤10 \le F_X(x) \le 1.

  • Non-decreasing
    As xx increases, FX(x)F_X(x) can only stay the same or increase. Accumulated probability never decreases.

  • Right-continuous
    The value of the CDF at a point includes the probability at that point, which ensures consistent behavior for jumps in discrete cases.

  • Limits at infinity
    As x→−∞x \to -\infty, FX(x)→0F_X(x) \to 0.
    As x→+∞x \to +\infty, FX(x)→1F_X(x) \to 1.

  • Stated formally:

    CDF Limits at Infinity
    lim⁡x→−∞FX(x)=0,lim⁡x→+∞FX(x)=1\lim_{x \to -\infty} F_X(x) = 0, \qquad \lim_{x \to +\infty} F_X(x) = 1
    Learn more about this formula: CDF Limits at Infinity →

    CDF Monotonicity
    x1≤x2  ⟹  FX(x1)≤FX(x2)x_1 \leq x_2 \implies F_X(x_1) \leq F_X(x_2)
    Learn more about this formula: CDF Monotonicity →

    CDF Right-continuity
    lim⁡y→x+FX(y)=FX(x)\lim_{y \to x^+} F_X(y) = F_X(x)
    Learn more about this formula: CDF Right-continuity →


    Pitfall: Forgetting where the CDF is zero
    Writing FX(x)=1−e−xF_X(x) = 1 - e^{-x} for every real xx gives FX(−1)=1−e≈−1.72F_X(-1) = 1 - e \approx -1.72, a negative probability, and FX(x)→−∞F_X(x) \to -\infty as x→−∞x \to -\infty. As a CDF it must read FX(x)=0F_X(x) = 0 for x<0x < 0 and 1−e−x1 - e^{-x} for x≥0x \ge 0.

    A CDF given by a formula is usually written for the values the variable can actually take, such as x≥0x \ge 0 for a waiting time, and that is where most of the work happens. The properties above, though, are statements about every real number xx, including the values far to the left and far to the right of anything the variable can produce.

    These properties are what distinguish a valid CDF from an arbitrary function and guarantee that it represents a genuine probability distribution. The table below names each property, states it formally, and gives the structural guarantee it provides.
Property Statement What it ensures
Bounded 0 ≤ FX(x) ≤ 1 for every x every value is a valid probability
Non-decreasing FX(x) stays the same or increases as x grows accumulated probability never decreases
Right-continuous the value at x includes the probability at x jumps in discrete and mixed cases behave consistently
Limits at infinity FX(x) → 0 as x → −∞; FX(x) → 1 as x → +∞ the function spans the full probability scale
These four properties are the whole test: every function that passes them is the CDF of some random variable.

Discrete Random Variables


For a discrete random variable, probability is concentrated at specific values. The CDF reflects this by increasing only at those values and remaining flat everywhere else.

In this case, the CDF is a step function. Each jump corresponds to a value the random variable can take, and the size of the jump equals the probability assigned to that value.

Formally, the CDF adds up the probabilities of all values up to xx:

CDF from PMF
FX(x)=∑k≤xpX(k)F_X(x) = \sum_{k \leq x} p_X(k)
Learn more about this formula: CDF from PMF →


Pitfall: Reading the CDF as a point probability
Taking FX(3)=12F_X(3) = \frac{1}{2} for a fair die as the chance of rolling a 33 counts the faces 11, 22 and 33 together. The chance of a 33 alone is the jump at 33: FX(3)−FX(2)=12−13=16F_X(3) - F_X(2) = \frac{1}{2} - \frac{1}{3} = \frac{1}{6}.

This makes the connection to the probability mass function clear: the PMF determines the jump sizes, while the CDF accumulates those jumps as the value increases. Reading the CDF from left to right shows how probability builds up one possible value at a time.

On a graph of the staircase, two different heights can be read at every possible value: the level of the step that starts there, and the size of the riser that leads up to it. The level is a running total collected from the far left; the riser belongs to the single value where it stands.
0.00.20.40.60.81.0012345678910Value (k)Cumulative Probability F(k)
Binomial CDF, n = 10, p = 0.5: a staircase

The cumulative probability is flat between the possible values and jumps at each one; the height of the jump at k is exactly P(X = k), so the whole probability mass function can be read off the risers. Nothing accumulates between integers because a discrete variable puts no probability there. Switch distributions and compare the staircases on the discrete CDF explorer.

Continuous variables give a very different picture.

Continuous Random Variables


For a continuous random variable, probability is spread smoothly over intervals rather than concentrated at individual points. As a result, the CDF increases continuously instead of jumping.

In this setting, the CDF describes how probability accumulates as the value grows along the real line. The slope of this accumulation is captured by the probability density function, which indicates how rapidly probability is building at each point.

In symbols, the CDF accumulates the density, and the density is the slope of the CDF:

CDF from PDF
FX(x)=∫−∞xfX(t) dtF_X(x) = \int_{-\infty}^{x} f_X(t)\,dt
Learn more about this formula: CDF from PDF →

PDF as CDF Derivative
fX(x)=ddxFX(x)f_X(x) = \frac{d}{dx} F_X(x)
Learn more about this formula: PDF as CDF Derivative →


COROLLARY
A key consequence is that a continuous random variable assigns zero probability to any single exact value.

Pitfall: Reading the density as a probability
For XX uniform on [0,12][0, \frac{1}{2}] the density is fX(x)=2f_X(x) = 2, and taking fX(14)=2f_X(\frac{1}{4}) = 2 as P(X≤14)P(X \le \frac{1}{4}) gives a probability above 11. The CDF gives it: FX(14)=2⋅14=12F_X(\frac{1}{4}) = 2 \cdot \frac{1}{4} = \frac{1}{2}.

Probabilities are obtained only by looking at intervals, and the CDF provides a direct way to compute them.

Two functions appear in this section, and both take a number xx and return a number. The CDF FX(x)F_X(x) returns accumulated probability, so its values always lie between 00 and 11. The density fX(x)f_X(x) returns the rate at which that probability is building near xx; where a lot of probability is packed into a short stretch, the rate is high. A narrow interval can therefore carry a large density and still hold very little probability.
0.00.20.40.60.81.0-4-3.0-2.0-1.0-0.01.02.03.04.0xF(x) = P(X ≤ x)
Normal CDF, mean 0, standard deviation 1

Here the cumulative probability rises without any jumps: probability is spread over intervals, so P(X = x) is zero for every single point and the curve climbs smoothly from 0 toward 1. The steepest part of the S-curve sits where the density is largest. Move along the curve and read the accumulated probability on the continuous CDF visualizer.

Mixed distributions combine both behaviours.

Mixed Distributions


Some random variables do not fit neatly into purely discrete or purely continuous categories. They may assign positive probability to certain specific values while also spreading probability continuously over intervals.

Fact: A CDF with no jumps and no density
Write XX in base 33, each digit a fair choice of 00 or 22: every single value has probability 00, so the CDF never jumps, yet XX stays in the Cantor set, of total length 00, so there is no density. This CDF, the devil's staircase, climbs from 00 to 11 while staying flat on gaps of total length 11 inside [0,1][0, 1].

The CDF handles this naturally. It combines flat regions, smooth increases, and sudden jumps within a single function. Jumps represent discrete probability masses, while smooth segments represent continuously distributed probability.

This is one reason the CDF is more general than the PMF or PDF. Even when neither of those fully describes a distribution on its own, the CDF still provides a complete and consistent representation.
A mixed CDF: flat at 0, a jump of 0.3 at x = 0, then a straight rise to 1 at x = 2, then flatxy−11231smooth rise: spread-out 0.7jump 0.3 = P(X = 0)flat: no probabilityOne CDF, both kinds: a jump for the mass at 0, a ramp for the rest
A CDF that jumps and ramps

A random variable that equals 0 with probability 0.3 and otherwise spreads the remaining 0.7 evenly over (0, 2]. Its CDF is 0 to the left of 0, jumps by 0.3 at x = 0 (the filled dot: the value at 0 includes the jump), rises in a straight line from 0.3 to 1 across (0, 2], and stays at 1 after that. No PMF and no PDF describes this variable on its own, but one CDF does.

The jump gives P(X = 0) = 0.3; any interval inside (0, 2] gets 0.35 per unit of length.

Using the CDF to Compute Probabilities


One of the main advantages of the cumulative distribution function is that it allows probabilities to be computed directly from differences of values.

For any two numbers a<ba < b, the probability that the random variable lies between them is obtained by subtracting accumulated probabilities:

Probability of Interval via CDF
P(a<X≤b)=FX(b)−FX(a)P(a < X \le b) = F_X(b) - F_X(a)
Learn more about this formula: Probability of Interval via CDF →


This works uniformly for discrete, continuous, and mixed random variables. One-sided probabilities are handled just as easily by reading the CDF at a single point.

Pitfall: Dropping the mass at the left endpoint
For a fair die, writing P(2≤X≤4)=FX(4)−FX(2)=46−26=13P(2 \le X \le 4) = F_X(4) - F_X(2) = \frac{4}{6} - \frac{2}{6} = \frac{1}{3} leaves out the face 22. Subtracting FX(1)F_X(1) keeps it: 46−16=12\frac{4}{6} - \frac{1}{6} = \frac{1}{2}.

For a discrete variable, the interval in the formula has to match the interval in the question exactly. The left side is open at aa and closed at bb, and the difference on the right reproduces precisely that: the mass sitting at bb is counted, the mass sitting at aa is not. Questions are phrased with every combination of << and ≤\le, so each one is matched to this shape before any value of FXF_X is read.

For a continuous random variable the same probability is the area under the density:

Probability of Interval Continuous
P(a≤X≤b)=∫abfX(x) dxP(a \leq X \leq b) = \int_{a}^{b} f_X(x)\,dx
Learn more about this formula: Probability of Interval Continuous →


Because of this, the CDF often simplifies probability calculations by replacing sums or integrals with simple evaluations of a single function.
0.00.20.40.60.81.0-2-0.31.53.25.06.78.410.211.9xF(x) = P(X ≤ x)
Continuous uniform CDF, a = 0, b = 10: a straight ramp

For a uniform variable the CDF is a straight line from 0 at a to 1 at b, so the probability of any interval inside [a, b] is the difference of the two ramp heights, which is the length of the interval divided by b minus a. The difference F(b) minus F(a) is the same calculation on every distribution, only the curve changes. Pick two points and read the difference on the continuous CDF visualizer.

The comparison with the PMF and PDF makes this role precise.

CDF vs PMF vs PDF


The CDF, PMF, and PDF describe probability distributions from different perspectives, but they are not interchangeable.

The CDF tracks accumulated probability. It tells how much probability lies at or below a given value and always exists for any random variable.

The PMF applies only to discrete random variables. It assigns probabilities to individual values, and the CDF is obtained by summing these probabilities up to a point.

The PDF applies only to continuous random variables. It describes how densely probability is spread, and the CDF is obtained by accumulating this density over an interval.

Because the CDF works in all cases, it serves as the most general representation of a probability distribution, with the PMF and PDF appearing as special cases derived from it. The table below sets the three side by side across what each function applies to, what it represents, and how it relates to the CDF.
Function Applies to What it represents Relation to CDF
CDF — FX(x) any random variable accumulated probability up to x the function itself
PMF — pX(x) discrete variables only probability at each individual value CDF is the cumulative sum of PMF values
PDF — fX(x) continuous variables only probability density at each point CDF is the integral of PDF from −∞ to x

Visual Interpretation


The cumulative distribution function can be understood visually as probability accumulating along the number line.

Starting from the far left, the CDF begins at zero and increases as more possible values are included. In discrete cases, this accumulation appears as upward jumps. In continuous cases, it appears as a smooth rising curve. Mixed distributions show both behaviors together.

Reading the CDF from left to right shows how probability builds up. At any point, the height of the curve represents how much of the total probability lies at or below that value.

Common Mistakes


The cumulative distribution function is often misunderstood because it looks simple but encodes a lot of structure.

A common mistake is confusing the CDF with a density or mass function. The CDF does not describe how much probability sits at a point, but how much has accumulated up to that point.

Another frequent error is forgetting that the CDF is cumulative. Interpreting its value as a probability of an exact outcome leads to incorrect conclusions, especially in continuous cases.

In discrete distributions, jumps in the CDF are sometimes misread as arbitrary features. Each jump has a precise meaning: its size equals the probability assigned to that value.

Finally, it is easy to forget that every valid CDF must satisfy basic properties such as monotonicity and proper limits. Violating these properties means the function cannot represent a probability distribution. The table below pairs each common mistake with the correction that prevents it.
Mistake Correction
Confusing CDF with a density or mass function FX(x) is probability accumulated up to x, not the probability at x
Forgetting the CDF is cumulative reading FX(x) as a point probability misreads it, especially in continuous cases where P(X = x) = 0
Misreading jumps in discrete CDFs each jump has a precise meaning — its size equals the probability assigned to that value
Ignoring required properties a function that is not monotonic or lacks the correct limits cannot represent a probability distribution

Two further mistakes come up once the CDF is used for calculations. Each one is marked where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.

Reading the density as a probability

For a continuous variable, the density fX(x)f_X(x) is evaluated at a point and its value is reported as a probability, either as P(X≤x)P(X \le x) or as the chance of landing at xx.

Wrong working: for XX uniform on [0,12][0, \frac{1}{2}], the density is fX(x)=2f_X(x) = 2 on that interval, so
P(X≤14)=fX(14)=2P\left(X \le \frac{1}{4}\right) = f_X\left(\frac{1}{4}\right) = 2


Right working: the probability is the area under the density up to 14\frac{1}{4}, which is the value of the CDF there.
FX(14)=∫01/42 dt=12F_X\left(\frac{1}{4}\right) = \int_0^{1/4} 2\,dt = \frac{1}{2}


Why it happens: for a discrete variable the PMF value at a point is a probability, and the habit carries over to the density, which looks like the same kind of function and is written with almost the same letter as FXF_X.

How to check: a probability can never exceed 11, while a density can. Here fX(x)=2f_X(x) = 2 at every point of [0,12][0, \frac{1}{2}], although the whole interval holds probability FX(12)=1F_X(\frac{1}{2}) = 1.

Dropping the mass at the left endpoint

For a discrete variable, the probability of a closed interval a≤X≤ba \le X \le b is computed as FX(b)−FX(a)F_X(b) - F_X(a), the formula for the half-open interval a<X≤ba < X \le b.

Wrong working: for a fair die,
P(2≤X≤4)=FX(4)−FX(2)=46−26=13P(2 \le X \le 4) = F_X(4) - F_X(2) = \frac{4}{6} - \frac{2}{6} = \frac{1}{3}


Right working: FX(2)F_X(2) already contains the face 22, so subtracting it removes that face from the answer. Subtract the CDF one value lower instead.
P(2≤X≤4)=FX(4)−FX(1)=46−16=12P(2 \le X \le 4) = F_X(4) - F_X(1) = \frac{4}{6} - \frac{1}{6} = \frac{1}{2}


Why it happens: the formula P(a<X≤b)=FX(b)−FX(a)P(a < X \le b) = F_X(b) - F_X(a) is remembered without its strict inequality on the left. For continuous variables the slip costs nothing, since P(X=a)=0P(X = a) = 0, so it goes unnoticed until a discrete problem.

How to check: count the values directly. The faces 22, 33 and 44 give 36=12\frac{3}{6} = \frac{1}{2}.

Why the CDF Matters


THEOREM
The cumulative distribution function fully characterizes the distribution of a random variable. Knowing the CDF is enough to recover all probability statements about the variable.

It provides a single framework that works for discrete, continuous, and mixed distributions. This makes it a central object in probability theory and a natural bridge between different types of models.

Fact: Every continuous variable hides a uniform one
Feed a continuous XX into its own CDF and FX(X)F_X(X) is uniform on [0,1][0, 1]: FX(X)≤uF_X(X) \le u means XX has not passed the point where FXF_X reaches uu, which has probability uu. Run backwards, FX−1(U)F_X^{-1}(U) for a uniform UU has CDF FXF_X, a standard way to simulate any distribution.

Many important concepts rely directly on the CDF, including quantiles, medians, percentiles, and probability intervals. In both theory and applications, the CDF is often the most convenient way to reason about probabilities.

A quantile reads the CDF backwards. The median is the value mm with FX(m)=12F_X(m) = \frac{1}{2}, and the 9090th percentile is the value where FXF_X first reaches 0.90.9. For a continuous variable every level uu between 00 and 11 is reached somewhere, so the CDF and its inverse pass freely between values of XX and probabilities.

Connections to Other Probability Concepts


The CDF ties together several core ideas in probability.

• Events appear as statements of the form X≤xX \le x.
• Random variables provide the numerical structure the CDF describes.
• PMF and PDF are specific ways probability is distributed, both derived from the CDF.
• Probability axioms guarantee the basic properties of the CDF.
• Quantiles and percentiles are defined by inverting the CDF.
• Expectation and variance can be expressed using the CDF.

Through these connections, the CDF serves as a unifying object that links foundational probability concepts with practical calculations.

CDF Across the Three Cases


The cumulative distribution function applies uniformly to discrete, continuous, and mixed random variables, yet its visual and structural behavior differs in each setting. The table below collects these three cases — naming the CDF's shape, how it changes as x grows, and the companion function (PMF or PDF) that captures the local detail behind each pattern.
Variable type CDF shape How it changes Companion function
Discrete step function — flat between values, jumps at possible values increases only at the possible values of X PMF — jump size at x equals pX(x)
Continuous smooth, continuously increasing curve, no jumps increases continuously across the real line PDF — slope of the CDF equals fX(x)
Mixed combines flat regions, smooth segments, and isolated jumps jumps at discrete masses and smooth growth over continuous parts partial PMF (at the masses) and partial PDF (over the continuous parts)

CDF FAQ

Why is the CDF defined with ≤ rather than <?

+
It is a deliberate choice, not an accident. Including the point itself is what makes the CDF right-continuous, and it lets a single definition cover discrete, continuous and mixed variables alike. For continuous variables the choice is invisible, since P(X = x) = 0. For discrete ones it decides whether a jump belongs to the step before it or the step after.Read more →

Does F(b) − F(a) include the endpoint a?

+
No. The difference gives P(a < X ≤ b) — open on the left, closed on the right. For a continuous variable that distinction costs nothing, since single points carry no probability. For a discrete variable it matters: to get P(a ≤ X ≤ b) you must add back the mass sitting at a, which F(a) has already subtracted away.Read more →

What is the difference between F(x) and f(x)?

+
One letter, two cases, two different objects. Capital F accumulates probability and is bounded by 1; lowercase f is a rate and may exceed 1. Calculus ties them together — f is the derivative of F, and F is the integral of f — but they answer different questions: F gives a probability directly, f does not.Read more →

What is the survival function?

+
The complement of the CDF: P(X > x) = 1 − F(x). Where the CDF accumulates probability up to a point, the survival function measures what is left beyond it. It leaves out the point itself, so it differs from P(X ≥ x) by exactly the mass sitting at x — invisible for continuous variables, but a real gap at a discrete jump. It is standard in reliability and time-to-event work.Read more →

Is the CDF defined for values the variable can never take?

+
Yes, for every real number. For a fair die, F(4.7)=46F(4.7) = \frac{4}{6}, because nothing is added between 44 and 55, and F(−3)=0F(-3) = 0. A CDF given by a formula needs the same care: 1−e−x1 - e^{-x} for a waiting time must be paired with F(x)=0F(x) = 0 for x<0x < 0, or it gives F(−1)=1−e≈−1.72F(-1) = 1 - e \approx -1.72, a negative probability.Read more →

Can a CDF have no jumps and no density?

+
Yes. Write XX in base 33 with each digit a fair choice of 00 or 22. Every single value has probability 00, so the CDF never jumps, yet XX always lies in the Cantor set, of total length 00, so no density can describe it. Its CDF, the devil's staircase, climbs from 00 to 11 while staying flat on gaps of total length 11 inside [0,1][0, 1].Read more →

Why is F(X) uniformly distributed?

+
Because of how FF accumulates. For a continuous XX and any uu between 00 and 11, the event FX(X)≤uF_X(X) \le u means XX has not passed the point where FXF_X reaches uu, which happens with probability exactly uu. So FX(X)F_X(X) is uniform on [0,1][0, 1]. Run backwards, FX−1(U)F_X^{-1}(U) for a uniform UU has CDF FXF_X, a standard way to simulate any distribution.Read more →