Continuous probability distributions model random variables whose possible values lie on intervals rather than isolated points. In these models, probabilities are assigned to ranges of values using density functions, and individual points have probability zero. This section organizes continuous distributions, highlights their shared structure, and provides access to individual distribution models.
For a die, a distribution lists each value with its probability. Try the same for a waiting time.
A bus arrives at a random moment in the next 10 minutes, every moment equally likely. What is the probability of waiting exactly 4 minutes?
Every exact waiting time gets probability 0 — yet some wait always happens.
question about the wait X
probability
between 4 and 5 minutes
1/10
between 4 and 4.1 minutes
1/100
between 4 and 4.01 minutes
1/1000
exactly 4 minutes
0
Each narrower interval holds a tenth as much probability. Squeezed down to the single value 4, nothing is left, and the same is true of every other value. A list of values and probabilities would be all zeros.
Probability lives on intervals, not on single points.
The key characteristic is that the probability of any single exact value is actually zero. This might seem counterintuitive, but consider measuring someone's height: the probability of someone being exactly 170.00000... centimeters tall (with infinite precision) is essentially zero. Instead, we calculate probabilities over intervals—like the probability of someone being between 170 and 171 cm tall.
The definition
A distribution is continuous when it belongs to a continuous random variable: one that can take any value in a range, with every single value having probability 0 and probabilities given by areas under a density curve.
A continuous probability distribution describes the behavior of a continuous random variable—one that can take any value within a given range, rather than being limited to distinct, separate values. Unlike discrete distributions where you can list individual outcomes (like rolling a 1, 2, 3, 4, 5, or 6 on a die), continuous distributions involve measurements that flow seamlessly along a continuum.
Mathematically, these distributions are described by a probability density function (PDF), where the area under the curve represents probability. The total area under the PDF always equals 1, representing certainty that some outcome will occur. To find the probability of a value falling within a specific range, we integrate the PDF over that interval—a process closely related to finding expected values and other moments of the distribution.
So for the bus, the density is 101 on [0,10], and P(4≤X≤5) is the area 1×101=101.
Continuous distributions model measurements: time, length, weight, error.
Common examples include the normal distribution (describing heights, test scores, measurement errors), the exponential distribution (modeling time between events), and the uniform distribution (representing equally likely outcomes across a range). These distributions are fundamental tools for modeling real-world phenomena involving measurements, time, distance, and other continuous variables.
Probability 0 does not mean impossible.
Some waiting time does happen, and whatever it turns out to be had probability 0 beforehand. For a continuous variable, an impossible outcome and an outcome of probability 0 are not the same thing. The contrast with discrete distributions is set out next.
The rest of the page covers continuous against discrete distributions, the main continuous families, their shared and differing properties, how to choose and work with them, and how to estimate, transform and read them.
Continuous vs Discrete Distributions
Understanding whether your random variable is continuous or discrete determines which distribution family to use and how to calculate probabilities. The distinction fundamentally changes your mathematical approach.
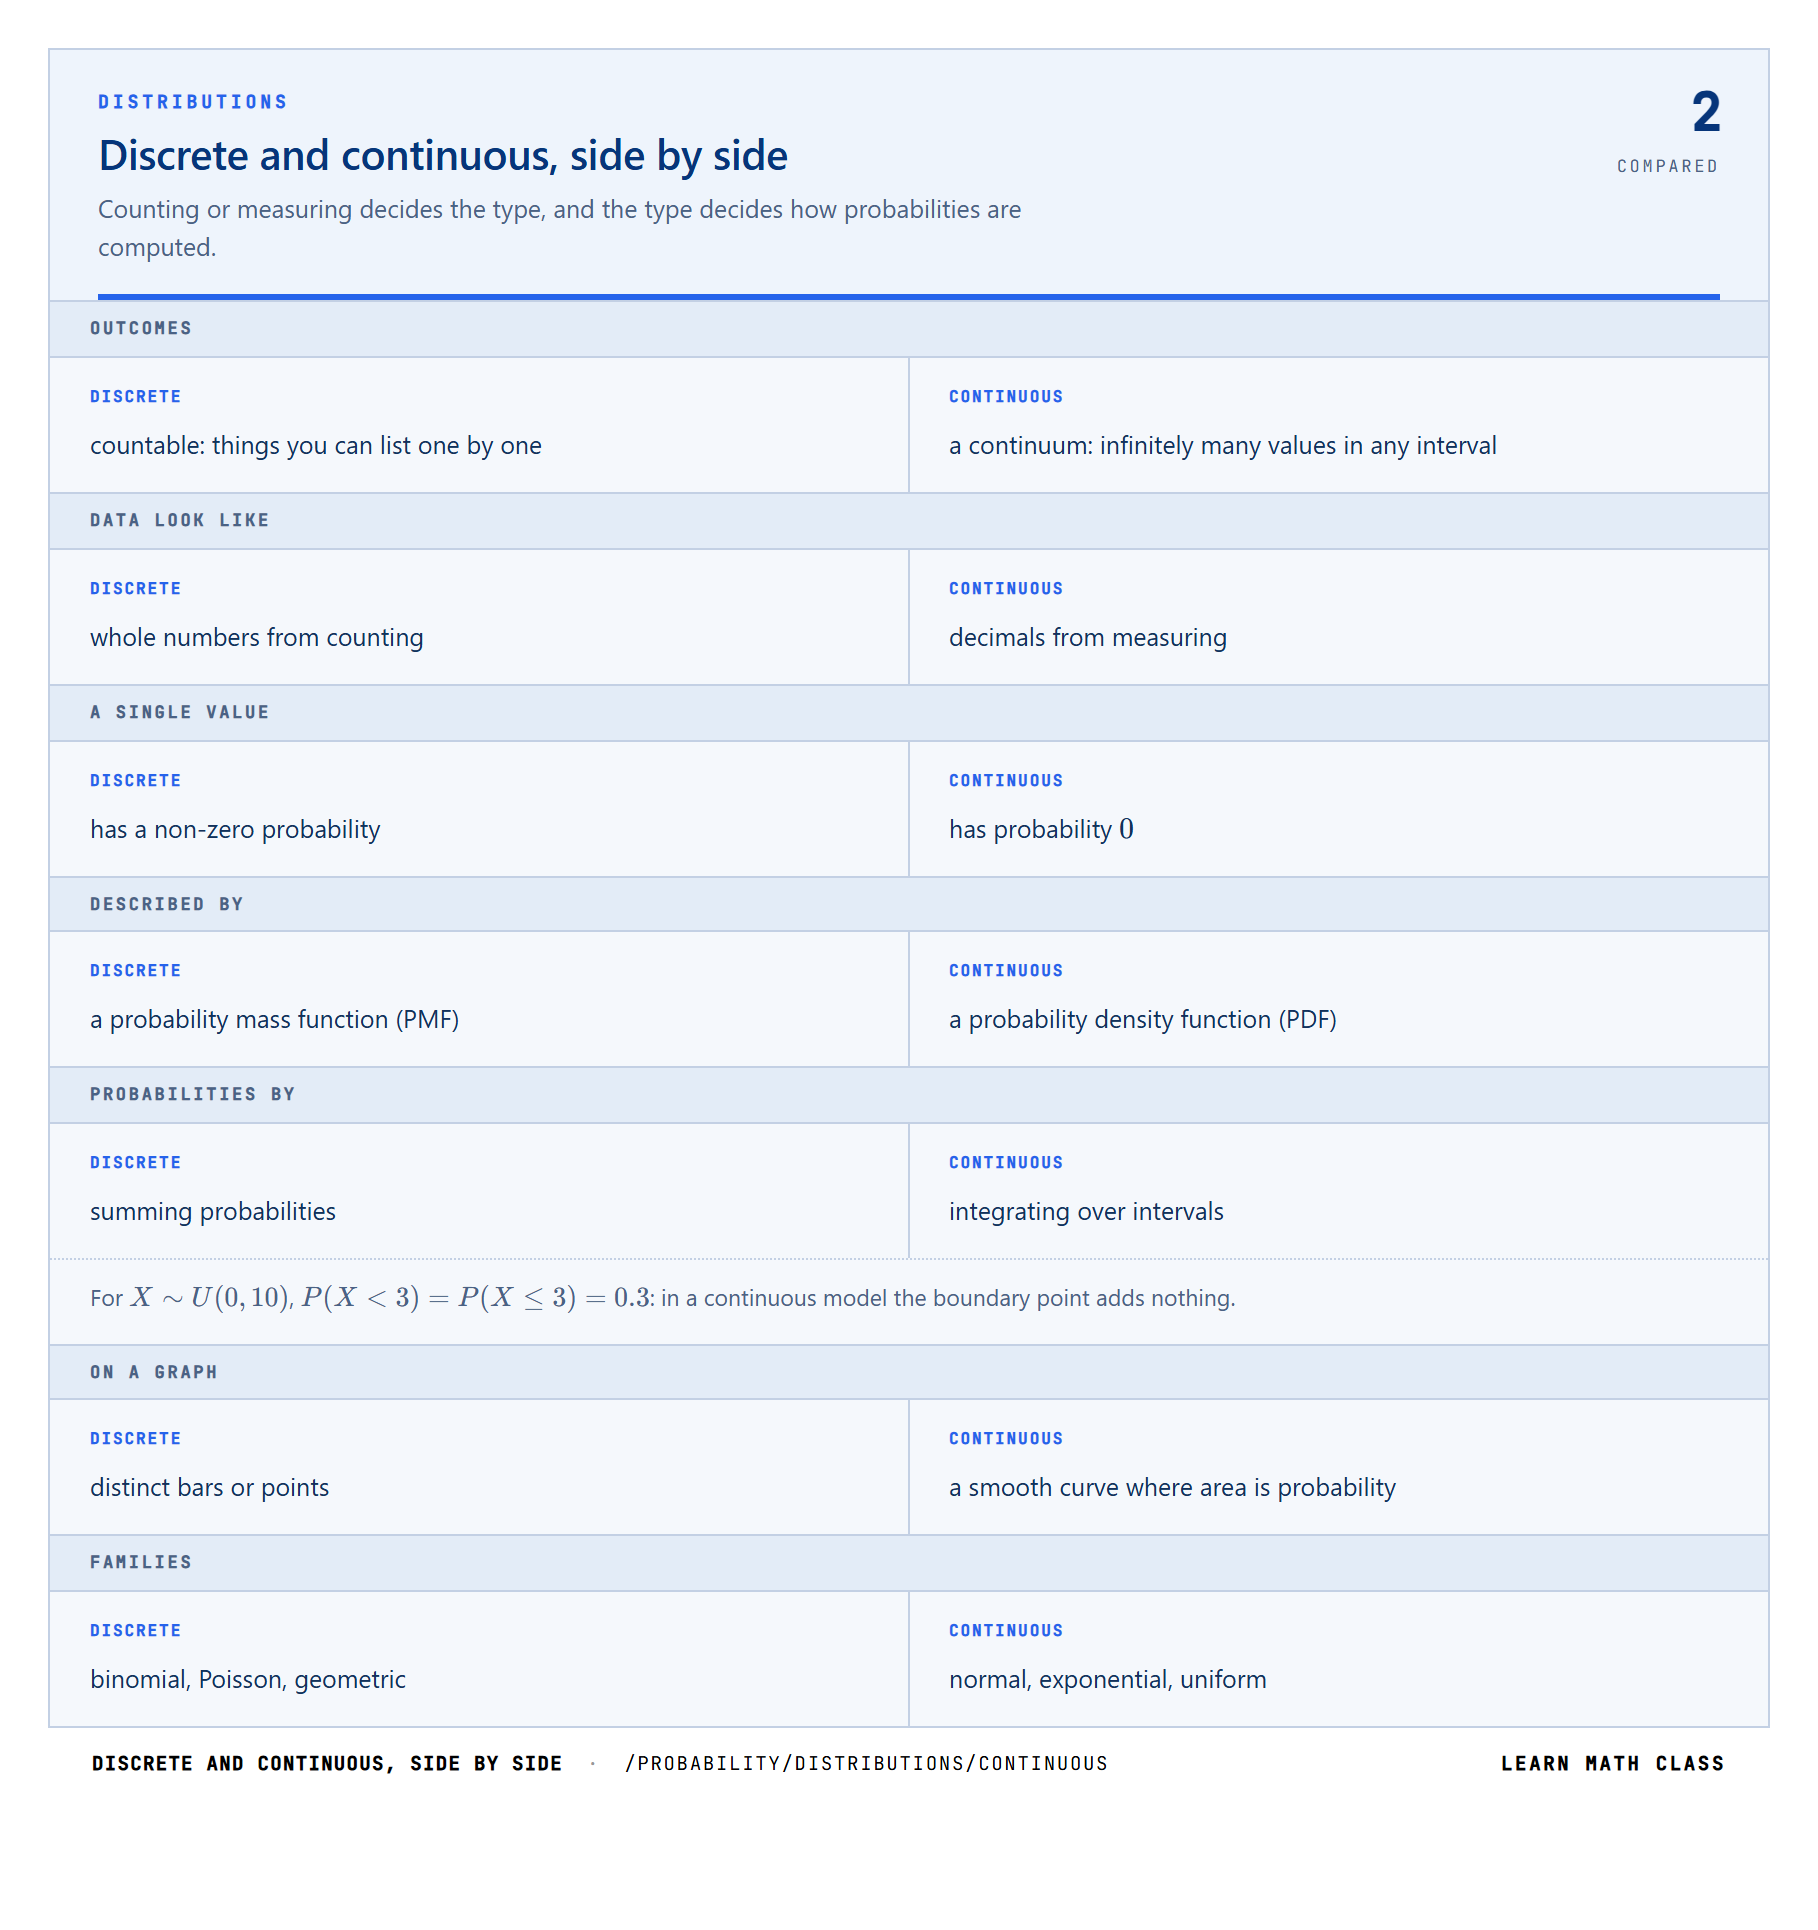
Discrete distributions deal with countable outcomes—things you can list individually. When you roll dice, count defective items, or track the number of customers arriving, you're working with discrete random variables. Here, each specific outcome has a non-zero probability, and you calculate probabilities by summing values from a probability mass function (PMF). On a graph, discrete distributions appear as distinct bars or points.
Continuous distributions handle measurements that flow along a continuum—height, time, temperature, distance. The underlying random variable can assume infinitely many values within any interval. Since individual points have probability zero, you must calculate probabilities over ranges by integrating the probability density function (PDF). Graphs show smooth curves where area represents probability.
Choosing the right type: • Can you count the possible outcomes? Use discrete (binomial, Poisson, geometric) • Are you measuring something? Use continuous (normal, exponential, uniform) • Does your data come in whole numbers from counting? Discrete • Does your data involve decimals from measurement? Continuous
In practice, this means: • A) Discrete: work with individual probabilities; Continuous: work with probability densities • B) Discrete: sum probabilities; Continuous: integrate over intervals • C) Discrete: bars on graphs; Continuous: smooth curves where area matters
Pitfall: Treating the density as a point probability
Writing P(X<3)=F(3)−f(3) for X∼U(0,10) gives 0.3−0.1=0.2. A single point has probability 0, so P(X<3)=P(X≤3)=0.3.
The switch from sums to areas also changes the role of the ends of an interval. In a discrete model, a strict or non-strict inequality decides whether the boundary value is counted. In a continuous model, the boundary is a single point on the axis, and the probability comes from the area between the ends.
Continuous uniform density, a = 0, b = 10
A continuous distribution has a density instead of probabilities at points: the flat line at height 1/10 is not a probability, and the probability of an interval is the area above it. A discrete variable would show separate bars whose heights are probabilities. Toggle to the CDF view and see the ramp that the area produces on the PDF visualizer.
The named families differ in the shape of that density.
Most rows follow from the third one. Once a single value has probability 0, probabilities have to come from intervals, sums become integrals, and bars become a curve whose area is the probability.
Types of Continuous Distributions
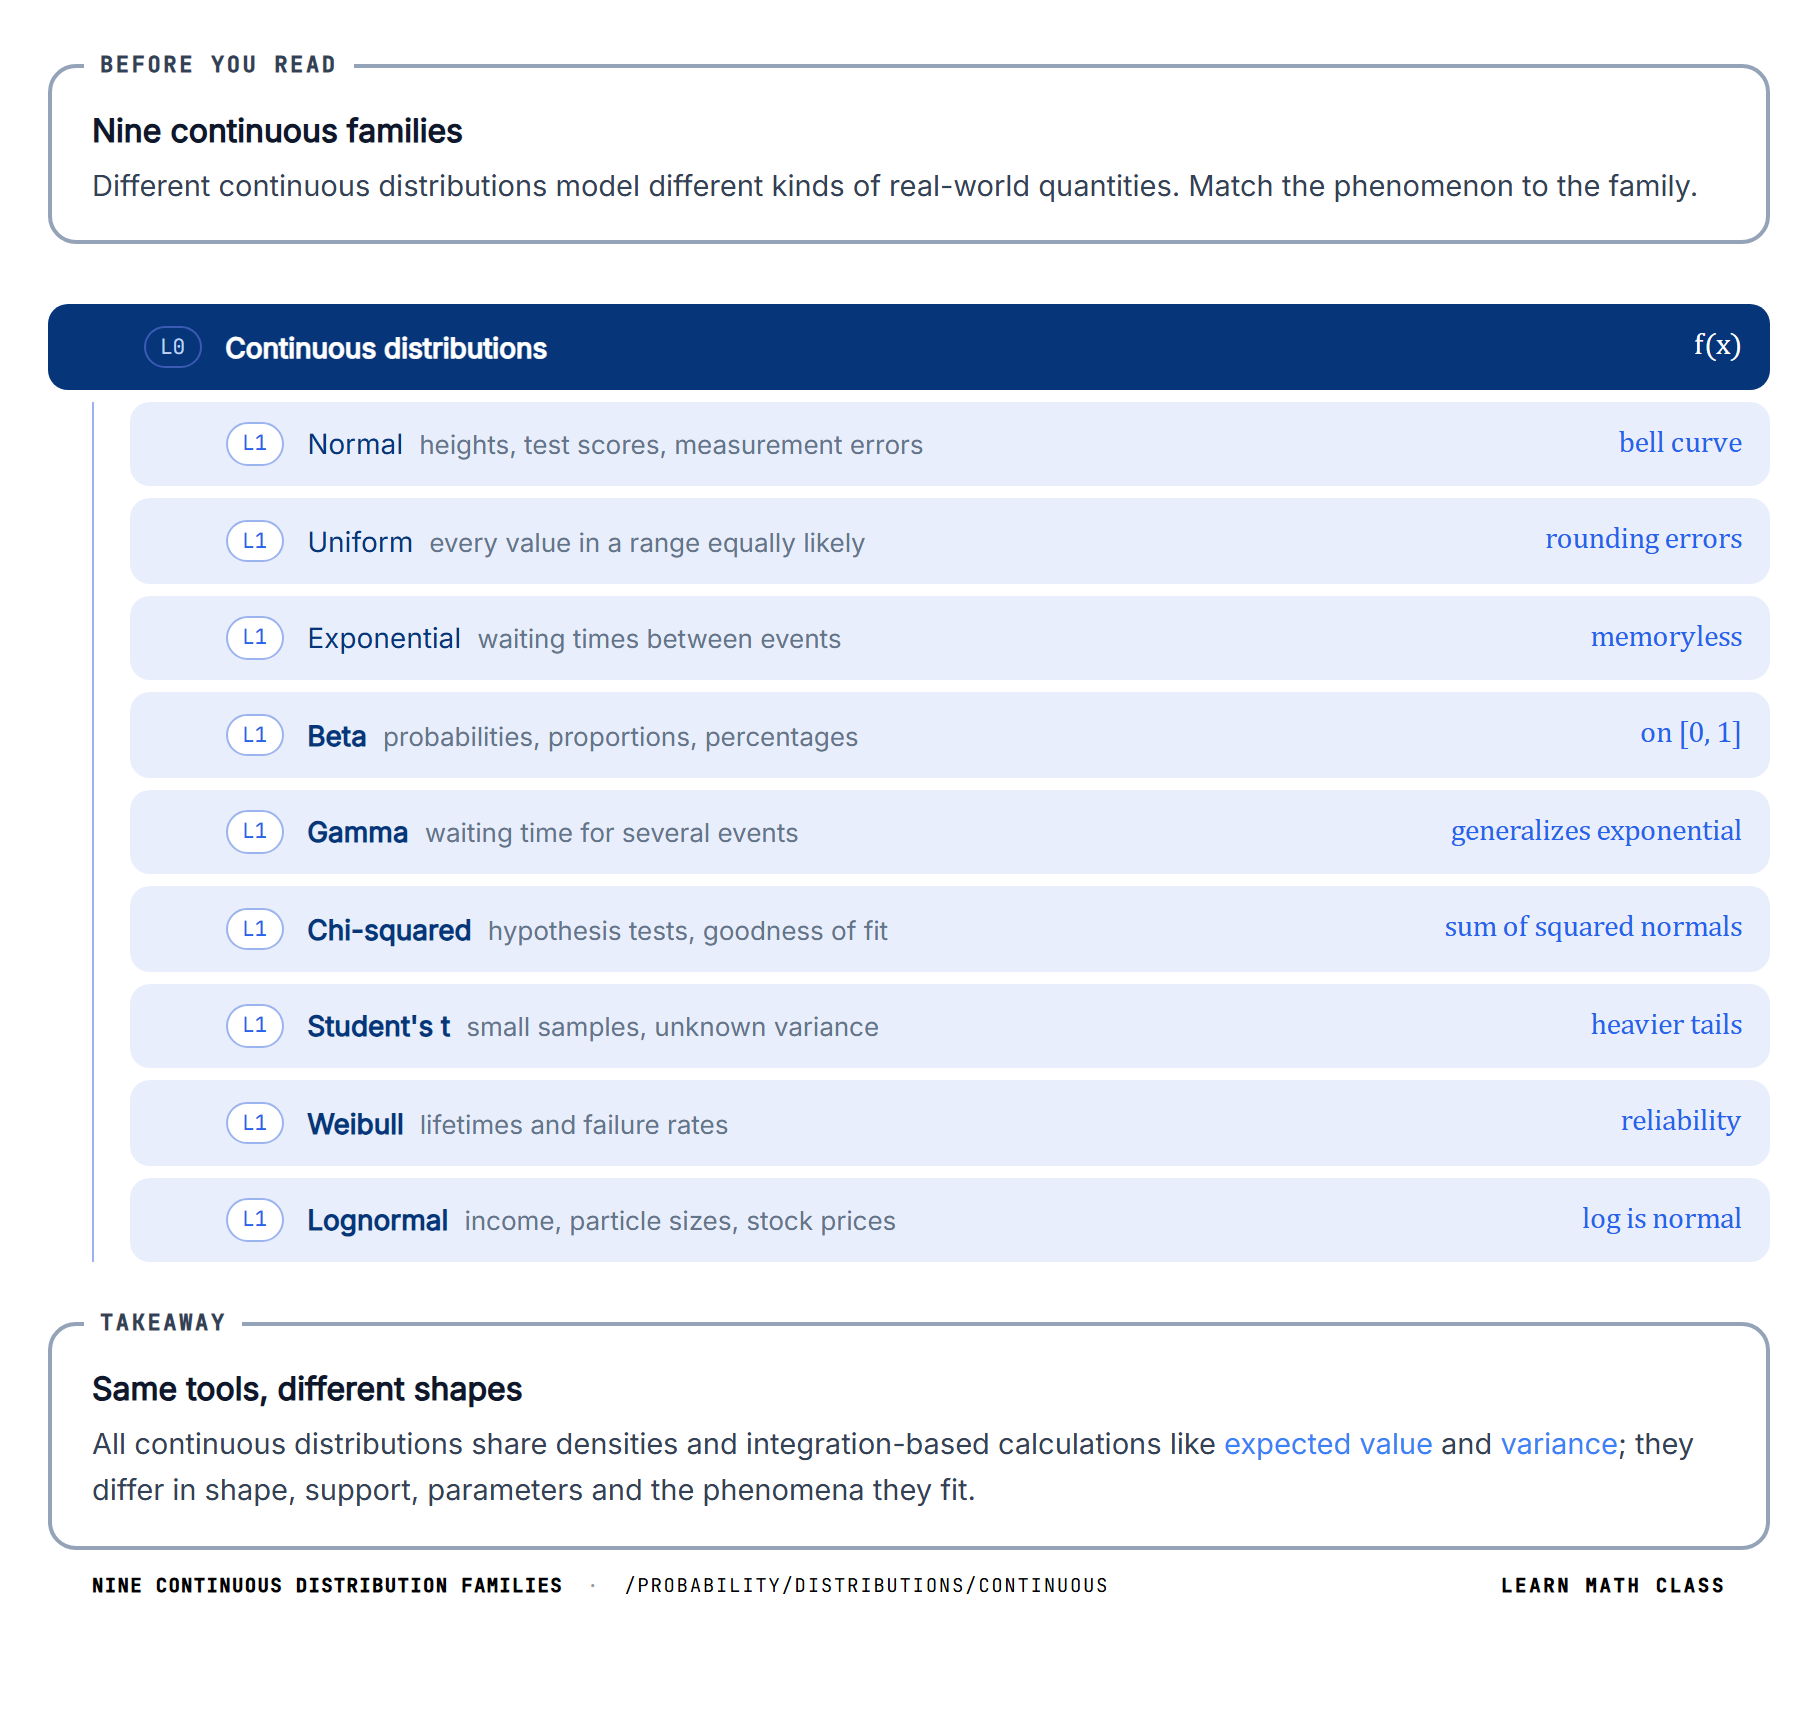
Different continuous distributions model different types of real-world phenomena. Here are the most commonly encountered distributions and their typical applications:
Normal (Gaussian) Distribution The bell-shaped curve that appears everywhere in nature and statistics. Models heights, test scores, measurement errors, and countless natural phenomena. Central to the Central Limit Theorem.
Uniform Distribution All values in a range are equally likely. Models random selection, rounding errors, or situations with no preference for any particular value within bounds.
Exponential Distribution Models waiting times between events in a Poisson process. Used for time until failure, time between arrivals, or radioactive decay. Memoryless property makes it unique.
Beta Distribution Bounded between 0 and 1, perfect for modeling probabilities, proportions, and percentages. Highly flexible shape based on two parameters.
Gamma Distribution Generalizes the exponential distribution to model waiting time for multiple events. Common in queuing theory and rainfall modeling.
Chi-Squared Distribution Sum of squared independent standard normal variables. Fundamental in hypothesis testing, confidence intervals, and goodness-of-fit tests.
Student's t-Distribution Similar to normal but with heavier tails. Used when sample sizes are small or population variance is unknown.
Weibull Distribution Models lifetime and failure rates in reliability engineering. Shape parameter determines whether failure rate increases, decreases, or remains constant.
Lognormal Distribution When the logarithm of a variable is normally distributed. Models income, particle sizes, stock prices, and anything involving multiplicative processes.
Classifying distributions into types helps you match real-world problems to the right mathematical model—whether you're analyzing lifetimes, measurements, or proportions. While all continuous distributions share common features like probability density functions and integration-based calculations(like expected value, variance , standard deviation etc), they differ in shape, support, parameters, and the specific phenomena they best represent.
The bell curve is the most used continuous family: symmetric about its mean, with a spread set by the standard deviation and tails that fall off quickly. The exponential and uniform families in the same explorer show a skewed and a flat alternative. Change the parameters and watch the bell move and widen on the distribution explorer.
All these families share the properties listed next.
L1Lognormalincome, particle sizes, stock priceslog is normal
Takeaway
Same tools, different shapes
All continuous distributions share densities and integration-based calculations like expected value and variance; they differ in shape, support, parameters and the phenomena they fit.
Selecting the appropriate continuous distribution is crucial for accurate modeling and analysis. Rather than memorizing formulas, focus on understanding the data-generating process and key characteristics of your measurements.
Ask These Key Questions
What is the support? Can your variable be negative, or only positive? If measuring time, distance, or counts, you need distributions with support [0, ∞) like exponential or gamma. For measurements that can go either direction (temperature changes, financial returns), consider the normal distribution. For bounded quantities like proportions or percentages, use beta or uniform distributions.
What generated this data? Understanding the underlying process is more important than fitting curves. Are you measuring time between events? Use exponential. Modeling lifetimes where failure rates change? Try Weibull. Dealing with products of random effects or growth processes? Consider lognormal. Measuring errors or natural variations? Normal distribution is likely appropriate.
Is the data symmetric or skewed? Plot your data first. Symmetric, bell-shaped data suggests normal or t-distributions. Right-skewed data (long tail toward higher values) points to exponential, lognormal, or gamma. Left-skewed data is rarer but might indicate a reflected distribution or beta with certain parameters.
The three questions above as columns, one row per distribution the section names. A dash means the section does not say.
Matching the data to a distributionLearn Math Class
No single column decides: the support narrows the field, and the process behind the data picks between what is left.
Common Mistakes to Avoid
Don't choose distributions solely by visual fit without considering the process. A skewed dataset might look exponential but actually be lognormal—the difference matters for predictions. Avoid using normal distributions for strictly positive data just because it's familiar. Don't ignore natural boundaries—modeling proportions with a normal distribution can predict impossible values below 0 or above 1.
When uncertain, let the data's origin guide you: what physical or logical process created these numbers? Match that process to the distribution's assumptions.
⋅ Models measurements and phenomena that cluster symmetrically around a central value. ⋅ Bell-shaped curve, symmetric about the mean mu. ⋅ Central Limit Theorem: sums and averages of independent random variables converge to normal.
⋅ Random variable X represents values that tend to concentrate near the mean with decreasing likelihood farther away.
⋅ Approximately 68% of values fall within one standard deviation of the mean. ⋅ Support: (−∞,∞). ⋅ Probability density function: f(x)=σ2π1e−2σ2(x−μ)2. ⋅ Parameters: μ∈R (mean), σ>0 (standard deviation). ⋅ Notation: X∼N(μ,σ2) or X∼Normal(μ,σ2).
Checklist for Identifying a Normal Distribution
✔ Data clusters symmetrically around a central value (the mean). ✔ Most values fall near the mean, with frequency decreasing as you move away. ✔ The distribution is bell-shaped and symmetric. ✔ Random variable X represents continuous measurements that can be positive or negative. ✔ Applicable to natural phenomena, measurement errors, and sums of random variables (Central Limit Theorem).
Key Properties and Special Characteristics
Symmetry: The normal distribution is perfectly symmetric about its mean. This means P(X≤μ−a)=P(X≥μ+a) for any value a.
Unimodal: The distribution has a single peak (mode) at x=μ, where the probability density is highest.
Asymptotic: The tails approach (but never touch) the horizontal axis as x→±∞. Theoretically, any value is possible, though extreme values are increasingly unlikely.
Central Limit Theorem: Perhaps the most important property—the sum or average of independent random variables tends toward a normal distribution as sample size increases, regardless of the original distribution (with some conditions).
Linear Transformations: If X∼N(μ,σ2), then aX+b∼N(aμ+b,a2σ2). This property preserves normality under scaling and shifting.
Standardization: Any normal random variable can be standardized: Z=σX−μ gives Z∼N(0,1), the standard normal distribution.
Sums of Normals: If X1∼N(μ1,σ12) and X2∼N(μ2,σ22) are independent, then X1+X2∼N(μ1+μ2,σ12+σ22).
Maximum Entropy: Among all distributions with specified mean and variance, the normal distribution has the maximum entropy (it's the "least informative" or "most random" distribution given those constraints).
Why It Matters: The normal distribution appears throughout statistics because of the Central Limit Theorem. Many statistical methods (t-tests, ANOVA, regression) assume normality or rely on it through the CLT. Understanding these properties helps you recognize when normal approximations are appropriate and when they break down.
Normal Distribution
Property
Normal Distribution
Description
Models measurements that cluster symmetrically around a central value with characteristic bell-shaped curve (e.g., heights, test scores, measurement errors)
Support (Domain)
X ∈ (-∞, ∞)
Finite or Infinite?
Infinite (continuous)
Bounds/Range
(-∞, ∞) - all real numbers
Parameters
μ (mu, the mean or center), σ (sigma, the standard deviation), where σ > 0
Distribution Property/Mechanism
Symmetric around the mean; values closer to μ are more likely; describes aggregated effects of many independent random factors
PDF (Probability Density Function)
f(x) = (1/(σ√(2π))) × e-((x-μ)²/(2σ²))
CDF (Cumulative Distribution Function)
F(x) = Φ((x-μ)/σ) where Φ is the standard normal CDF (no closed form, requires numerical methods or tables)
⋅ Models situations where all values in a continuous interval are equally likely. ⋅ No value in the interval is more probable than any other.
⋅ Random variable X takes values uniformly from the continuous interval [a, b].
⋅ Probability density is constant across the entire interval. ⋅ Support: [a,b] where a<b. ⋅ Probability density function: f(x)=b−a1 for a≤x≤b, and f(x)=0 otherwise. ⋅ Parameters: a,b∈R,a<b. ⋅ Notation: X∼Unif(a,b) or X∼U(a,b).
Checklist for Identifying a Continuous Uniform Distribution
✔ All values in a continuous interval are equally likely. ✔ The probability density is constant across the entire range. ✔ The distribution has a rectangular shape when graphed. ✔ Random variable X can take any value within a finite interval [a, b]. ✔ Often models situations with complete uncertainty within known bounds.
Key Properties and Special Characteristics
Perfect Symmetry: The uniform distribution is symmetric about its mean (a+b)/2. The probability density is identical at equal distances from the center: f(μ−d)=f(μ+d) for any d.
Memoryless in Relative Terms: While not memoryless in the exponential sense, the uniform distribution has no "preferred" region—every subinterval of equal length has equal probability.
Bounded Support: Unlike the normal or exponential distributions, the uniform distribution has strict bounds. Values outside [a, b] have zero probability, making it ideal for modeling quantities with known limits.
Maximum Entropy: Among all continuous distributions with bounded support [a, b], the uniform distribution has maximum entropy. It represents complete uncertainty about where the value will fall within the interval—no region is favored over any other.
Linear CDF: The CDF increases at a constant rate within [a, b]. This linearity makes probability calculations particularly straightforward and intuitive.
Transformation Properties: Linear transformations preserve uniformity. If X∼U(a,b), then cX+d∼U(ca+d,cb+d) for c>0. This includes the important case that b−aX−a∼U(0,1), the standard uniform.
Relation to Other Distributions: The standard uniform U(0,1) is fundamental in probability theory and simulation. Most random number generators produce uniform random numbers, which can then be transformed to generate samples from any other distribution using the inverse transform method.
Order Statistics: For a sample from U(0,1), the order statistics have well-known beta distributions, making the uniform distribution central to the study of order statistics.
Why It Matters: The uniform distribution represents the principle of indifference—when all outcomes in an interval are equally likely. It's essential for modeling complete uncertainty within known bounds, serves as the foundation for random number generation, and appears in numerous statistical procedures and simulation methods.
Continuous Uniform Distribution
Property
Continuous Uniform Distribution
Description
Models situations where all values in a continuous interval are equally likely (e.g., random arrival time within an hour, random point selection on a line segment)
Support (Domain)
X ∈ [a, b]
Finite or Infinite?
Finite (continuous)
Bounds/Range
[a, b] where a < b (finite interval)
Parameters
a (minimum value), b (maximum value), where a < b
Distribution Property/Mechanism
Constant probability density over the interval; all subintervals of equal length are equally probable; simplest continuous distribution
PDF (Probability Density Function)
f(x) = 1/(b - a) for a ≤ x ≤ b; f(x) = 0 otherwise
CDF (Cumulative Distribution Function)
F(x) = 0 for x < a; F(x) = (x - a)/(b - a) for a ≤ x ≤ b; F(x) = 1 for x > b
⋅ Models the time until the first event occurs in a Poisson process. ⋅ Events occur independently at a constant average rate lambda. ⋅ Exhibits the memoryless property: P(X>s+tmidX>s)=P(X>t).
⋅ Random variable X represents the waiting time until the first event occurs.
⋅ Continuous analog of the geometric distribution. ⋅ Support: [0,∞). ⋅ Probability density function: f(x)=λe−λx for x≥0, and f(x)=0 otherwise. ⋅ Parameter: λ>0 (rate parameter). ⋅ Notation: X∼Exp(λ).
Checklist for Identifying an Exponential Distribution
✔ Models the time until an event occurs in a continuous process. ✔ Events occur independently at a constant average rate. ✔ The distribution is memoryless: past waiting time doesn't affect future waiting time. ✔ Random variable X represents waiting time, which is always non-negative. ✔ Commonly used for modeling lifetimes, time between arrivals, and decay processes.
Key Properties and Special Characteristics
Memoryless Property: The exponential distribution's most distinctive feature. If X∼Exp(λ), then P(X>s+t∣X>s)=P(X>t) for all s,t≥0. The amount of time already waited doesn't affect the distribution of remaining waiting time. This is the continuous analog of the geometric distribution's memoryless property.
Long Right Tail: The distribution is strongly right-skewed with a long tail extending toward infinity. While most values cluster near zero, there's always some probability of observing very large values. The skewness coefficient is exactly 2 for all exponential distributions.
Constant Hazard Rate: The hazard rate (instantaneous failure rate) is constant and equal to λ. This means the risk of an event occurring in the next instant remains the same regardless of how much time has passed. This property is equivalent to memorylessness.
Relation to Poisson Process: If events occur according to a Poisson process with rate λ, the time between consecutive events follows an exponential distribution with parameter λ. Conversely, if inter-arrival times are exponential with rate λ, the counting process is Poisson with rate λ.
Minimum of Exponentials: If X1,X2,…,Xn are independent exponential random variables with rates λ1,λ2,…,λn, then min(X1,X2,…,Xn)∼Exp(λ1+λ2+⋯+λn). The minimum of exponentials is exponential with rate equal to the sum of rates.
Sum of Exponentials: The sum of n independent Exp(λ) random variables follows a gamma distribution with shape parameter n and rate parameter λ. This connects the exponential to the broader gamma family.
Lack of Memory in Reliability: In reliability engineering, the memoryless property implies that a component with exponential lifetime doesn't age—its probability of failure in the next time unit is the same whether it's new or has been functioning for years. This makes exponential distributions suitable for modeling random failures but not wear-out failures.
Transformation Properties: If X∼Exp(λ), then cX∼Exp(λ/c) for c>0. Scaling time scales the rate inversely.
Why It Matters: The exponential distribution is fundamental in queuing theory, reliability analysis, and survival analysis. Its memoryless property makes it mathematically tractable while providing reasonable models for many random arrival and failure processes. It's the continuous-time analog of the geometric distribution and serves as the building block for more complex models like the gamma and Weibull distributions.
Exponential Distribution
Property
Exponential Distribution
Description
Models the time between events in a process where events occur continuously and independently at a constant average rate (e.g., time until next phone call, equipment failure time, radioactive decay)
Support (Domain)
X ∈ [0, ∞)
Finite or Infinite?
Infinite (continuous)
Bounds/Range
[0, ∞) - non-negative real numbers
Parameters
λ (lambda, the rate parameter), where λ > 0
Distribution Property/Mechanism
Memoryless property; continuous analog of geometric distribution; models waiting times for Poisson processes; probabilities decay exponentially
Despite their different shapes and applications, all continuous distributions share a fundamental mathematical structure. Understanding these common properties allows you to work with any continuous distribution using the same conceptual framework.
Probability Density Function (PDF) Every continuous distribution has a PDF, f(x), that describes the relative likelihood of values. While the formula changes between distributions, the PDF always integrates to 1 over the entire support.
Cumulative Distribution Function (CDF) The CDF, F(x), gives the probability that the random variable is less than or equal to x. Calculated by integrating the PDF from negative infinity to x, it always ranges from 0 to 1 and is non-decreasing.
Mean (Expected Value) Expected Value is the center of mass of the distribution, calculated as the integral of x·f(x). Different distributions have different formulas, but the concept remains constant—it's where the distribution "balances."
Variance and Standard Deviation Measures of spread around the mean. Variance is the expected value of squared deviations from the mean, while standard deviation is its square root, providing a measure in the original units.
Quantiles and Percentiles The inverse of the CDF, quantiles identify values below which a given percentage of the distribution falls. The median (50th percentile) and quartiles work the same way across all continuous distributions.
These shared properties mean that once you understand how to work with one continuous distribution, you have the tools to work with any of them—only the specific formulas change.
How Continuous Distributions Differ
While all continuous distributions share common mathematical properties, each type serves a distinct purpose. Understanding what makes them different helps you select the right distribution for your specific problem.
Support: Where Values Can Exist Distributions differ fundamentally in their domain. The normal distribution spans the entire real line (-∞, +∞), suitable for measurements that can be positive or negative. The exponential distribution is restricted to non-negative values [0, ∞), perfect for waiting times that cannot be negative. The uniform and beta distributions have finite support [a, b] and [0, 1] respectively, ideal for bounded measurements like proportions or percentages.
Shape: Symmetry and Skewness Some distributions are perfectly symmetric (normal, uniform), while others exhibit skewness. The exponential distribution is heavily right-skewed with most probability near zero. The beta distribution can be symmetric, left-skewed, right-skewed, or U-shaped depending on its parameters. Shape matters because it reflects the underlying process—symmetric for balanced phenomena, skewed for processes with natural boundaries or accumulation patterns.
Modeling Intent: What They Represent Each distribution evolved to model specific phenomena. The normal distribution captures additive processes and measurement errors. The exponential models time between random events. The lognormal describes multiplicative processes like income or stock prices. The Weibull handles failure rates that change over time. Choosing correctly means matching your data's generation process to the distribution's assumptions.
Parameter Roles: Control and Flexibility Parameters serve different purposes across distributions. Location parameters (μ) shift the distribution horizontally. Scale parameters (σ) control spread. Shape parameters (like those in beta or Weibull) fundamentally alter the curve's form. Some distributions need just one parameter (exponential), while others require two or more (normal, beta) for adequate flexibility.
This diversity exists because real-world phenomena are diverse—no single distribution can model waiting times, proportions, measurements, and failure rates equally well.
Three continuous families side by side
A normal curve with mean 2 and standard deviation 1, a uniform density on [1, 4] and an exponential density with rate 1, on one axis. The normal spreads over the whole line and is symmetric; the uniform is flat on its interval and zero outside it; the exponential starts at its highest point at 0 and decays to the right. Each encloses total area 1. What differs is where the probability can sit and how it is spread.
The exponential's density reaches 1 at 0, yet no single value has positive probability.
Normal: measurements that can be positive or negative.
Non-negative values
[0,∞)
Exponential: waiting times that cannot be negative.
Finite support
[a,b], [0,1]
Uniform and beta: bounded measurements like proportions or percentages.
ShapeSymmetry and skewness
Symmetric
Normal and uniform: balanced phenomena.
Right-skewed
Exponential: most probability near zero.
Depends on its parameters
Beta: symmetric, left-skewed, right-skewed or U-shaped.
Modeling intentWhat they represent
Additive processes
Normal: also measurement errors.
Time between random events
Exponential.
Multiplicative processes
Lognormal: income or stock prices.
Failure rates that change over time
Weibull.
Parameter rolesControl and flexibility
Location
μ
Shifts the distribution horizontally.
Scale
σ
Controls spread.
Shape
Fundamentally alters the form of the curve, as in beta or Weibull.
How Continuous Distributions DifferLearn Math Class
Relationships Between Distributions
Continuous distributions aren't isolated mathematical objects—they're interconnected through special cases, generalizations, and limiting behaviors. Understanding these relationships reveals deeper structure in probability theory and helps you navigate between distributions efficiently.
Hierarchical Relationships Some distributions are generalizations of others. The gamma distribution generalizes the exponential: when the shape parameter equals 1, you get the exponential distribution back. Similarly, the chi-squared distribution is a special case of the gamma distribution. The beta distribution with parameters (1,1) becomes the uniform distribution on [0,1]. These hierarchies mean mastering one distribution gives you insight into several others.
Transformations and Derived Distributions New distributions arise from transforming existing ones. If X follows a normal distribution, then e^X follows a lognormal distribution—the transformation creates a fundamentally different shape. The chi-squared distribution emerges when you sum squared standard normal variables. Taking the ratio of two chi-squared variables (each divided by its degrees of freedom) yields an F-distribution, and a standard normal divided by the square root of a scaled chi-squared variable yields a Student's t-distribution. These connections explain why certain distributions appear in statistical testing.
Fact: One degree of freedom, no mean
With one degree of freedom, Student's t has density π(1+x2)1, and its tails are so heavy that ∫xf(x)dx diverges: there is no mean. The average of 1,000 such values is spread exactly as widely as a single one.
Limiting Behaviors As parameters change, distributions can converge to others. The Student's t-distribution approaches the normal distribution as degrees of freedom increase—its heavier tails gradually thin out. The binomial distribution (discrete) approaches the normal distribution under certain conditions, bridging the discrete-continuous divide. The Poisson process generates exponential waiting times, linking discrete event counts to continuous time intervals.
Why This Matters Recognizing relationships helps you choose distributions more strategically, understand why certain distributions appear in formulas, and see probability theory as a unified system rather than a collection of unrelated formulas. When you know the normal and understand transformations, the lognormal becomes intuitive rather than arbitrary.
Click a distribution to see how it connects. Hover to trace its links; click a line type to hide it.
Relationships Between DistributionsLearn Math Class
Working with PDFs and CDFs
Understanding probability density functions and cumulative distribution functions conceptually is one thing—knowing how to use them for actual calculations is another. Here's how these tools work in practice.
The PDF: Density, Not Probability
The probability density function f(x) tells you the relative likelihood of values, but f(x) itself is not a probability. In fact, f(x) can exceed 1, which would be impossible for a probability. Think of the PDF as describing the "concentration" of probability at different points. To find actual probabilities, you must integrate the PDF over an interval: P(a ≤ X ≤ b) = ∫[a to b] f(x)dx. This integral gives you the area under the curve between a and b.
The CDF: Your Probability Calculator
The cumulative distribution function F(x) = P(X ≤ x) answers the question "what's the probability the random variable is at most x?" This is directly usable. If you need P(X ≤ 5), just evaluate F(5). For P(X > 5), use 1 - F(5). For P(3 < X ≤ 7), calculate F(7) - F(3). The CDF eliminates the need for integration in many practical problems.
Pitfall: Reading F(x) as the right tail
Taking F(2) as P(X>2) for an exponential with λ=1 gives 1−e−2≈0.865, which is P(X≤2). The right tail is P(X>2)=1−F(2)=e−2≈0.135.
F always measures the area to the left of its argument. An event that lies to the right of a point, or between two points, is therefore built from left-hand areas and the total area of 1.
The Fundamental Relationship
The PDF and CDF are intimately connected: F(x) = ∫[-∞ to x] f(t)dt, and conversely, f(x) = dF(x)/dx.
THEOREM
The CDF is the accumulated area under the PDF from the left, while the PDF is the rate of change of the CDF.
This means if you have one, you can find the other through calculus.
Practical Workflow
For hand calculations with standard distributions, use CDF tables or software rather than integrating PDFs manually. For non-standard problems, numerical integration works. Most statistical software provides both PDF values (for plotting) and CDF values (for probability calculations).
Exponential CDF, lambda = 1
Calculations with a continuous distribution go through the CDF: the probability of an interval is F at its right end minus F at its left end, so the area under the density never has to be integrated by hand once F is known. For the exponential family F(x) equals 1 minus e to the minus lambda x, which the curve traces. Pick an interval and read the difference on the continuous CDF visualizer.
Fitting the parameters to data comes next.
A density value is never a probability; probabilities are areas, and the CDF delivers them by subtraction.
Parameter Estimation
When you have real-world data and believe it follows a particular distribution type, you still need to determine the specific parameter values that best fit your observations. Parameter estimation is the bridge between theoretical distributions and practical data analysis.
Why Parameters Matter
A normal distribution isn't useful until you know its mean μ and standard deviation σ. An exponential distribution requires its rate parameter λ. These parameters shape the distribution to match your specific dataset. Poor parameter estimates lead to inaccurate predictions and flawed decision-making.
Method of Moments
The simplest approach matches theoretical moments to sample moments. For a normal distribution, estimate μ with the sample mean x̄ and σ² with the sample variance s². For an exponential distribution, estimate λ as 1/x̄ since the theoretical mean equals 1/λ. This method is intuitive and computationally straightforward, though not always the most efficient.
Pitfall: Using the sample mean as the rate
Taking λ^=xˉ for waiting times with sample mean xˉ=4 minutes gives a rate of 4 events per minute. Matching E[X]=λ1 to xˉ gives λ^=41=0.25 per minute.
Each match runs through the formula that ties the parameter to the moment. For the normal distribution, μ is itself the mean. For the exponential, λ is a rate, counted in events per unit of time, while the sample mean x̄ is measured in units of time.
Maximum Likelihood Estimation (MLE)
MLE finds parameter values that make the observed data most probable. You construct a likelihood function—the probability of seeing your data given certain parameters—and maximize it. For many standard distributions, MLE formulas are well-established. For the normal distribution, MLE actually gives the same estimates as the method of moments. For others like the Weibull distribution, MLE requires numerical optimization but provides more accurate estimates, especially with smaller samples.
Choosing Your Method
Fact: A moment estimate the data rule out
Fitting U(0,b) to the data 1,2,9 by matching the mean 2b to xˉ=4 gives b^=8, an upper bound below the observed 9. Maximum likelihood takes b^=9, the largest value, which never contradicts the data.
Method of moments is quick and works well for simple distributions and large samples. MLE is preferred when you need optimal estimates, work with complex distributions, or have limited data. Modern statistical software handles both methods automatically, but understanding the principles helps you interpret results and recognize when estimates might be unreliable.
Transformations and Standardization
Transforming random variables is a powerful technique that simplifies calculations, enables comparisons across different scales, and reveals relationships between distributions. Understanding how transformations affect continuous distributions is essential for practical statistical work.
The Standard Normal Distribution
The most important transformation in statistics converts any normal distribution to the standard normal with mean 0 and variance 1. Using the transformation Z = (X - μ)/σ, you standardize your variable. This Z-score tells you how many standard deviations a value is from the mean. Why standardize? Because we have extensive tables and software for the standard normal, and all normal distribution problems reduce to this single reference distribution.
Pitfall: Dividing by the variance
Standardizing x=7 from X∼N(5,22) with the variance gives z=47−5=0.5. With the standard deviation σ=2, z=27−5=1: the value is one standard deviation above the mean.
A z-score counts standard deviations, so it carries no units. A height and a test score can both have z = 1, which means each lies one standard deviation above its own mean.
Linear Transformations
When you transform X to Y = aX + b, the distribution shifts and scales predictably. Adding b shifts the distribution's location—if X ~ N(μ, σ²), then X + b ~ N(μ + b, σ²). Multiplying by a scales both location and spread—if X ~ N(μ, σ²), then aX ~ N(aμ, a²σ²). The normal and uniform families are preserved by every such transformation with a ≠ 0, which only changes the parameters. Not every family is: an exponential variable stays exponential when multiplied by a positive a, but not after a shift or a sign change.
Nonlinear Transformations
Nonlinear transformations create entirely new distributions. Taking e^X when X is normal produces a lognormal distribution. Squaring a standard normal variable gives a chi-squared distribution with 1 degree of freedom. Taking the logarithm of a lognormal variable returns you to the normal distribution. These transformations explain why certain distributions appear in specific contexts and provide tools for normalizing skewed data.
Practical Applications
Standardization enables fair comparisons—comparing test scores from different exams, or measurements in different units. Transformations can stabilize variance, meet statistical assumptions, or reveal linear relationships hidden in raw data. Understanding transformations means recognizing that the same underlying randomness can manifest in multiple distributional forms depending on how you measure or scale it.
From X to the standard normal
X follows a normal distribution with mean 5 and standard deviation 2. Subtracting 5 slides the bell to centre 0; dividing by 2 squeezes it to spread 1, and the curve becomes taller so that its area stays 1. The result Z = (X − 5)/2 is standard normal. The value x = 7, one standard deviation above the mean, lands at z = 1: positions are kept, only the scale changes.
Every normal curve standardizes to the same Z, which is why one table serves them all.
Visualization and Interpretation
Visual representation transforms abstract mathematical concepts into intuitive understanding. Learning to read and interpret distribution graphs is essential for working effectively with continuous probability.
Density Curves as Shapes
The probability density function appears as a smooth curve when plotted. The shape tells a story: a normal distribution's symmetric bell curve shows values clustering symmetrically around the mean. An exponential distribution's steep decline from the origin reveals that small values are most likely, with probability dropping off rapidly. A uniform distribution's flat horizontal line indicates all values are equally probable. Shape recognition helps you identify distributions in real data and understand their behavior at a glance.
Probability as Area
RULE
The fundamental principle of continuous distributions is that probability equals area under the density curve.
To find P(2 ≤ X ≤ 5), locate 2 and 5 on the horizontal axis and measure the area between them under the curve. A wider interval captures more area, hence higher probability. The total area under any PDF always equals 1, representing certainty that some outcome will occur. This visual interpretation makes integration meaningful—you're literally measuring regions under curves.
Parameter Effects on Shape and Spread
Changing parameters reshapes the distribution dynamically. For the normal distribution, increasing σ flattens and widens the curve (more spread), while decreasing σ makes it taller and narrower (less spread). The mean μ slides the entire curve left or right without changing its shape. For the exponential distribution, increasing λ compresses probability toward zero (faster decay), while decreasing λ stretches it out (slower decay). Interactive visualizers let you manipulate parameters and immediately see these effects, building intuition about how distributions behave.
Common Pitfalls
Each of the four mistakes below is marked where it happens in the sections above; here each is worked through in full, with the wrong and the right working side by side.
A probability with a strict inequality is computed by taking the non-strict one and removing the boundary value, as for a discrete variable. The density at the boundary is used as the probability of that value.
Start
For X∼U(0,10),
Wrong turn
Error here
With F(3)=103=0.3 and f(3)=101=0.1,
P(X<3)
=P(X≤3)−P(X=3)
=F(3)−f(3)=0.3−0.1
=0.2
Right path
A single point has probability 0 for a continuous variable, so nothing is removed.
P(X<3)=P(X≤3)−0
=F(3)
=10−03−0=0.3
Why it happensFor a discrete variable, P(X<3) and P(X≤3) differ by the probability of the value 3, and that habit is carried over. The density f(3) looks like the natural stand-in for P(X=3), but it is a height, not an area.
How to checkShrink the interval. P(3≤X≤3+h)=0.1h for X∼U(0,10), which goes to 0 as h goes to 0; whatever the density, the area above one point is 0.
2Reading F(x) as the right tail
A question asks for the probability that X exceeds a value, and F at that value is given as the answer. F is the area to the left.
Wrong turn
Error here
For an exponential variable with λ=1,
P(X>2)=F(2)=1−e−2
≈0.865
Right path
The right tail is what remains of the total area after the left part.
P(X>2)=1−F(2)
=1−(1−e−2)
=e−2≈0.135
Why it happensThe CDF is the number that tables and software return, and it is easy to report it without asking which side of the point it covers. For the exponential, F(x)=1−e−λx already contains a "1−", which makes it look like a complement.
How to checkCompare with the shape. The exponential density with λ=1 is highest at 0 and falls quickly, so most of the area lies below 2, and the probability of exceeding 2 must be small.
3Using the sample mean as the rate
In the method of moments for the exponential distribution, the sample mean is used directly as the estimate of λ. But λ is a rate, and the mean of the distribution is λ1.
Wrong turn
Error here
Waiting times between arrivals have sample mean xˉ=4 minutes, so
λ^=xˉ=4 per minute
Right path
The theoretical mean λ1 is matched to the sample mean, and the equation is solved for λ.
λ^1=xˉ=4
⇒
λ^=41=0.25 per minute
Why it happensFor the normal distribution the parameter μ is the mean, so the sample mean is the estimate directly; the same shortcut is carried over to a distribution whose parameter is not the mean.
How to checkLook at the units. A mean of 4 minutes between arrivals means one arrival every 4 minutes, which is a quarter of an arrival per minute; a rate of 4 per minute would mean an arrival every 15 seconds.
4Dividing by the variance
A normal value is standardized with σ2 in the denominator instead of σ, often because the distribution is written as N(μ,σ2) and the second number is copied straight into the formula.
Start
For X∼N(5,22),
Wrong turn
Error here
Written N(5,4), and x=7,
z=47−5=0.5
Right path
The denominator is the standard deviation σ=4=2.
z=σx−μ=27−5=1
Why it happensThe usual notation N(μ,σ2) puts the variance in the second place, while the z-score formula needs its square root.
How to check7 is exactly one step of σ=2 above the mean 5, so its z-score must be 1. A z-score is a count of standard deviations, and it has to agree with that count on simple values.
Each slip reads a continuous distribution with a rule from somewhere else. A single point has probability 0, so strict and non-strict inequalities give the same answer; F(x) is the area to the left, so the right tail is 1−F(x); the method of moments estimates the rate as xˉ1; and a z-score divides by σ, not by σ2. Shrinking the interval, comparing with the shape of the density, or checking the units catches each slip.
Skills You Should Learn
Each skill opens its step-by-step method page. Skills marked "On this page" are taught above.
Find a binomial probabilityCount successes in n independent trials: name n, p and the values of k, then add PMF terms or use the complement.
Find a Poisson probabilityEvents at an average rate: scale λ to the interval asked about, then use e−λλk/k! or its complement.
Find a normal probabilityStandardize with z=(x−μ)/σ, then read the area from Φ: left tails, right tails and intervals.
Find a continuous uniform probabilityEqually likely anywhere on [a,b]: the probability of an interval is its length over b−a, after clipping to the support.
Can a method-of-moments estimate contradict the data?
+
Yes. Fit U(0,b) to the data 1,2,9 by matching the mean 2b to xˉ=4: the estimate is b^=8, an upper bound below the observed 9, so the fitted model calls a value that was seen impossible. Maximum likelihood takes b^=9, the largest value, which never contradicts the data. The method of moments is quick and works well for simple models and large samples; maximum likelihood is preferred with little data or complex models.Read more →
Which continuous distributions are special cases of others?
+
Several. The gamma distribution with shape parameter 1 is the exponential, and the sum of n independent Exp(λ) variables is gamma with shape n and rate λ. The chi-squared distribution with ν degrees of freedom is the gamma with shape 2ν and rate 21. The beta distribution with parameters (1,1) is the uniform on [0,1].Read more →
Why shouldn't you model a proportion with a normal distribution?
+
Because the normal spreads over the whole real line, so it gives positive probability to values below 0 and above 1, which a proportion cannot take. Bounded quantities call for a distribution with bounded support, such as the beta on [0,1] or a uniform. The same check applies to strictly positive data such as waiting times: there the support [0,∞) of the exponential or gamma fits, or a lognormal when the data come from multiplied effects.Read more →
When should you use Student's t instead of the normal distribution?
+
When the sample is small or the population variance is unknown. The t-distribution is a standard normal divided by the square root of a chi-squared variable scaled by its degrees of freedom, and the extra uncertainty shows as heavier tails. As the degrees of freedom grow, the tails thin out and t approaches the normal. At the other end, with one degree of freedom the density is π(1+x2)1, and its tails are so heavy that it has no mean.Read more →