Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Bayes' Theorem


Probability After Information


Probability does not stay fixed when new information appears. What we believe about a situation often changes once evidence is observed, data is collected, or a condition becomes known. Bayes' theorem captures this process in a precise and consistent way.

At its core, Bayes' theorem describes how probabilities should update when we move from what we believed before seeing evidence to what we should believe after. It connects prior knowledge with new information and explains how both should be combined rather than treated separately.

This idea is not an add-on to probability theory. Bayes' theorem sits at the intersection of conditional probability, total probability, and independence, tying them together into a single update mechanism. The sections that follow show how this connection works and why Bayes' theorem plays such a central role in probabilistic reasoning.

Key Terms

Conditional Probability— P(A∣B)P(A \mid B), the quantity Bayes' theorem inverts
Probability Measure— the function PP underlying all terms in the formula
Disjoint Sets— partition elements must be disjoint
Event— the hypothesis AA and the observed evidence BB

See All Probability Definitions →


How Information Changes Probability

A test catches 99% of people who have a disease, and the disease affects 1 person in 100. You test positive. How likely is it that you are sick?
Most people answer about 99%99\%. But that figure is the chance of a positive result for someone who is sick — the question asks for the reverse.
Counting 10,000 people settles it: only about 1 positive in 6 is actually sick.
out of 10,000 peoplehow manytest positive
have the disease (1%)10099 (the test catches 99%)
do not have it (99%)9,900495 (5% false alarms)
all positives594
positives who are sick99 out of 594 = 1/6 ≈ 17%
The healthy people are so many that their 5%5\% false alarms, 495495 of them, outnumber the 9999 true positives. The test is good; the disease is rare.
What is easy to know runs one way, from cause to evidence; what is wanted runs the other way, from evidence to cause.
Bayes' theorem appears in situations where we observe something directly, but care about something that is not directly visible. We see evidence, data, or outcomes, while the underlying cause or explanation remains uncertain.
In many problems, the probability of observing evidence given a cause is easier to assess than the probability of the cause given the evidence. This asymmetry creates a gap: we know how likely the evidence is under different scenarios, but we want to reason in the opposite direction.
The definition
Bayes' theorem turns the probability of the evidence given a cause into the probability of the cause given the evidence: P(A∣B)=P(B∣A) P(A)P(B)P(A \mid B) = \dfrac{P(B \mid A)\,P(A)}{P(B)}.
Bayes' theorem provides the bridge between these two perspectives. It shows how information flows from what we can observe to what we want to infer, allowing probabilities to be updated in a principled and consistent way.
So with P(D)=0.01P(D) = 0.01, P(+∣D)=0.99P(+ \mid D) = 0.99 and P(+)=0.0594P(+) = 0.0594, the chance of disease after a positive test is P(D∣+)=0.00990.0594=16P(D \mid +) = \frac{0.0099}{0.0594} = \frac{1}{6}.
Bayes' theorem is a rule for updating a probability when evidence arrives.
Before the test, the chance of disease was 1%1\%; after a positive result it is about 17%17\%. The same kind of update decides the well-known game-show puzzle below, where the host's choice of door is the evidence.
Fact: Switching doors wins two times in three
You pick door 1 of three, and the host, who knows where the car is, opens door 3 to show a goat. Switching to door 2 wins with probability 23\frac{2}{3}: a car behind door 2 forces him to open door 3, while a car behind door 1 leaves him a free choice he makes only half the time.
The starting probability cannot be skipped: a rare cause can stay fairly unlikely even after strong evidence.
Here the test is 99%99\% accurate on the sick, yet the answer is only 17%17\%, because the starting point was 1%1\%. The update is put into words in Bayes' theorem explained in words, and into symbols in the formula.
The rest of the page covers the theorem in words, its connection to conditional probability, notation, the formula, the law of total probability, the chain rule, independence, examples, and common mistakes.

Bayes' Theorem Explained in Words


Bayes' theorem describes how to update the probability of a situation once new information is taken into account. It explains how what we believed before should be adjusted after an observation is made.

The idea is simple in principle. We start with an initial assessment of how likely different possibilities are. We then consider how compatible each possibility is with what we observed. Finally, these assessments are combined and rescaled so that the updated probabilities remain consistent.

This verbal description captures the essence of Bayes' theorem before any symbols appear. The formula that follows is simply a precise way to express this update process using conditional probability.

To compute a posterior probability from your own prior and likelihoods, use the Bayes calculator.

An updated probability weighs each possibility twice: by how likely it was beforehand and by how well it explains the observation.

Connection to Conditional Probability


Bayes' theorem is built entirely from conditional probability. It does not introduce a new type of probability or a separate rule. Instead, it reorganizes conditional probabilities to answer a different kind of question.

Conditional probability tells us how likely one event is when another has occurred already. Bayes' theorem takes this idea and reverses the direction: it relates the probability of a cause given an observation to the probability of observing that outcome given the cause.

Because of this, Bayes' theorem cannot be understood in isolation. It is a direct consequence of how conditional probability works, and its meaning becomes clear only when conditioning is already familiar.
P(A) = 0.600P(Aᶜ) = 0.400P(B|A) = 0.700P(Bᶜ|A) = 0.300P(B|Aᶜ) = 0.300P(Bᶜ|Aᶜ) = 0.700AP = 0.6000AᶜP = 0.4000A ∩ BP = 0.4200A ∩ BᶜP = 0.1800Aᶜ ∩ BP = 0.1200Aᶜ ∩ BᶜP = 0.2800
Branches below A carry P(B given A) and P(not B given A)

Bayes theorem rearranges two ways of reaching the same leaf: along the upper path the joint probability is P(A) times P(B given A), and the same leaf is reached the other way round through P(B) times P(A given B). Equating the two products and dividing by P(B) is the whole theorem. Change the branch weights and watch both products stay equal on the conditional probability tree diagram.

Pitfall: Swapping the two conditionals
Reading a test's P(+∣D)=0.99P(+ \mid D) = 0.99 as the chance of disease after a positive result reverses the condition. With P(D)=0.01P(D) = 0.01 and P(+∣Dc)=0.05P(+ \mid D^c) = 0.05, the posterior is P(D∣+)=0.00990.0594=16≈0.17P(D \mid +) = \frac{0.0099}{0.0594} = \frac{1}{6} \approx 0.17.

In the tree, the two conditionals sit in different places. P(B∣A)P(B \mid A) is a branch weight, read forward from the situation to the observation, and it is usually the number a problem supplies. P(A∣B)P(A \mid B) does not appear on the tree at all: it has to be computed from the products along the paths that end in BB.

Both quantities are built from the same joint probability P(A∩B)P(A \cap B), but each measures it against a different event. The first measures it against AA, the second against BB.
The formula below writes this rearrangement out in symbols.

Bayes' Theorem Notation

Notation

Bayes' Theorem Notation

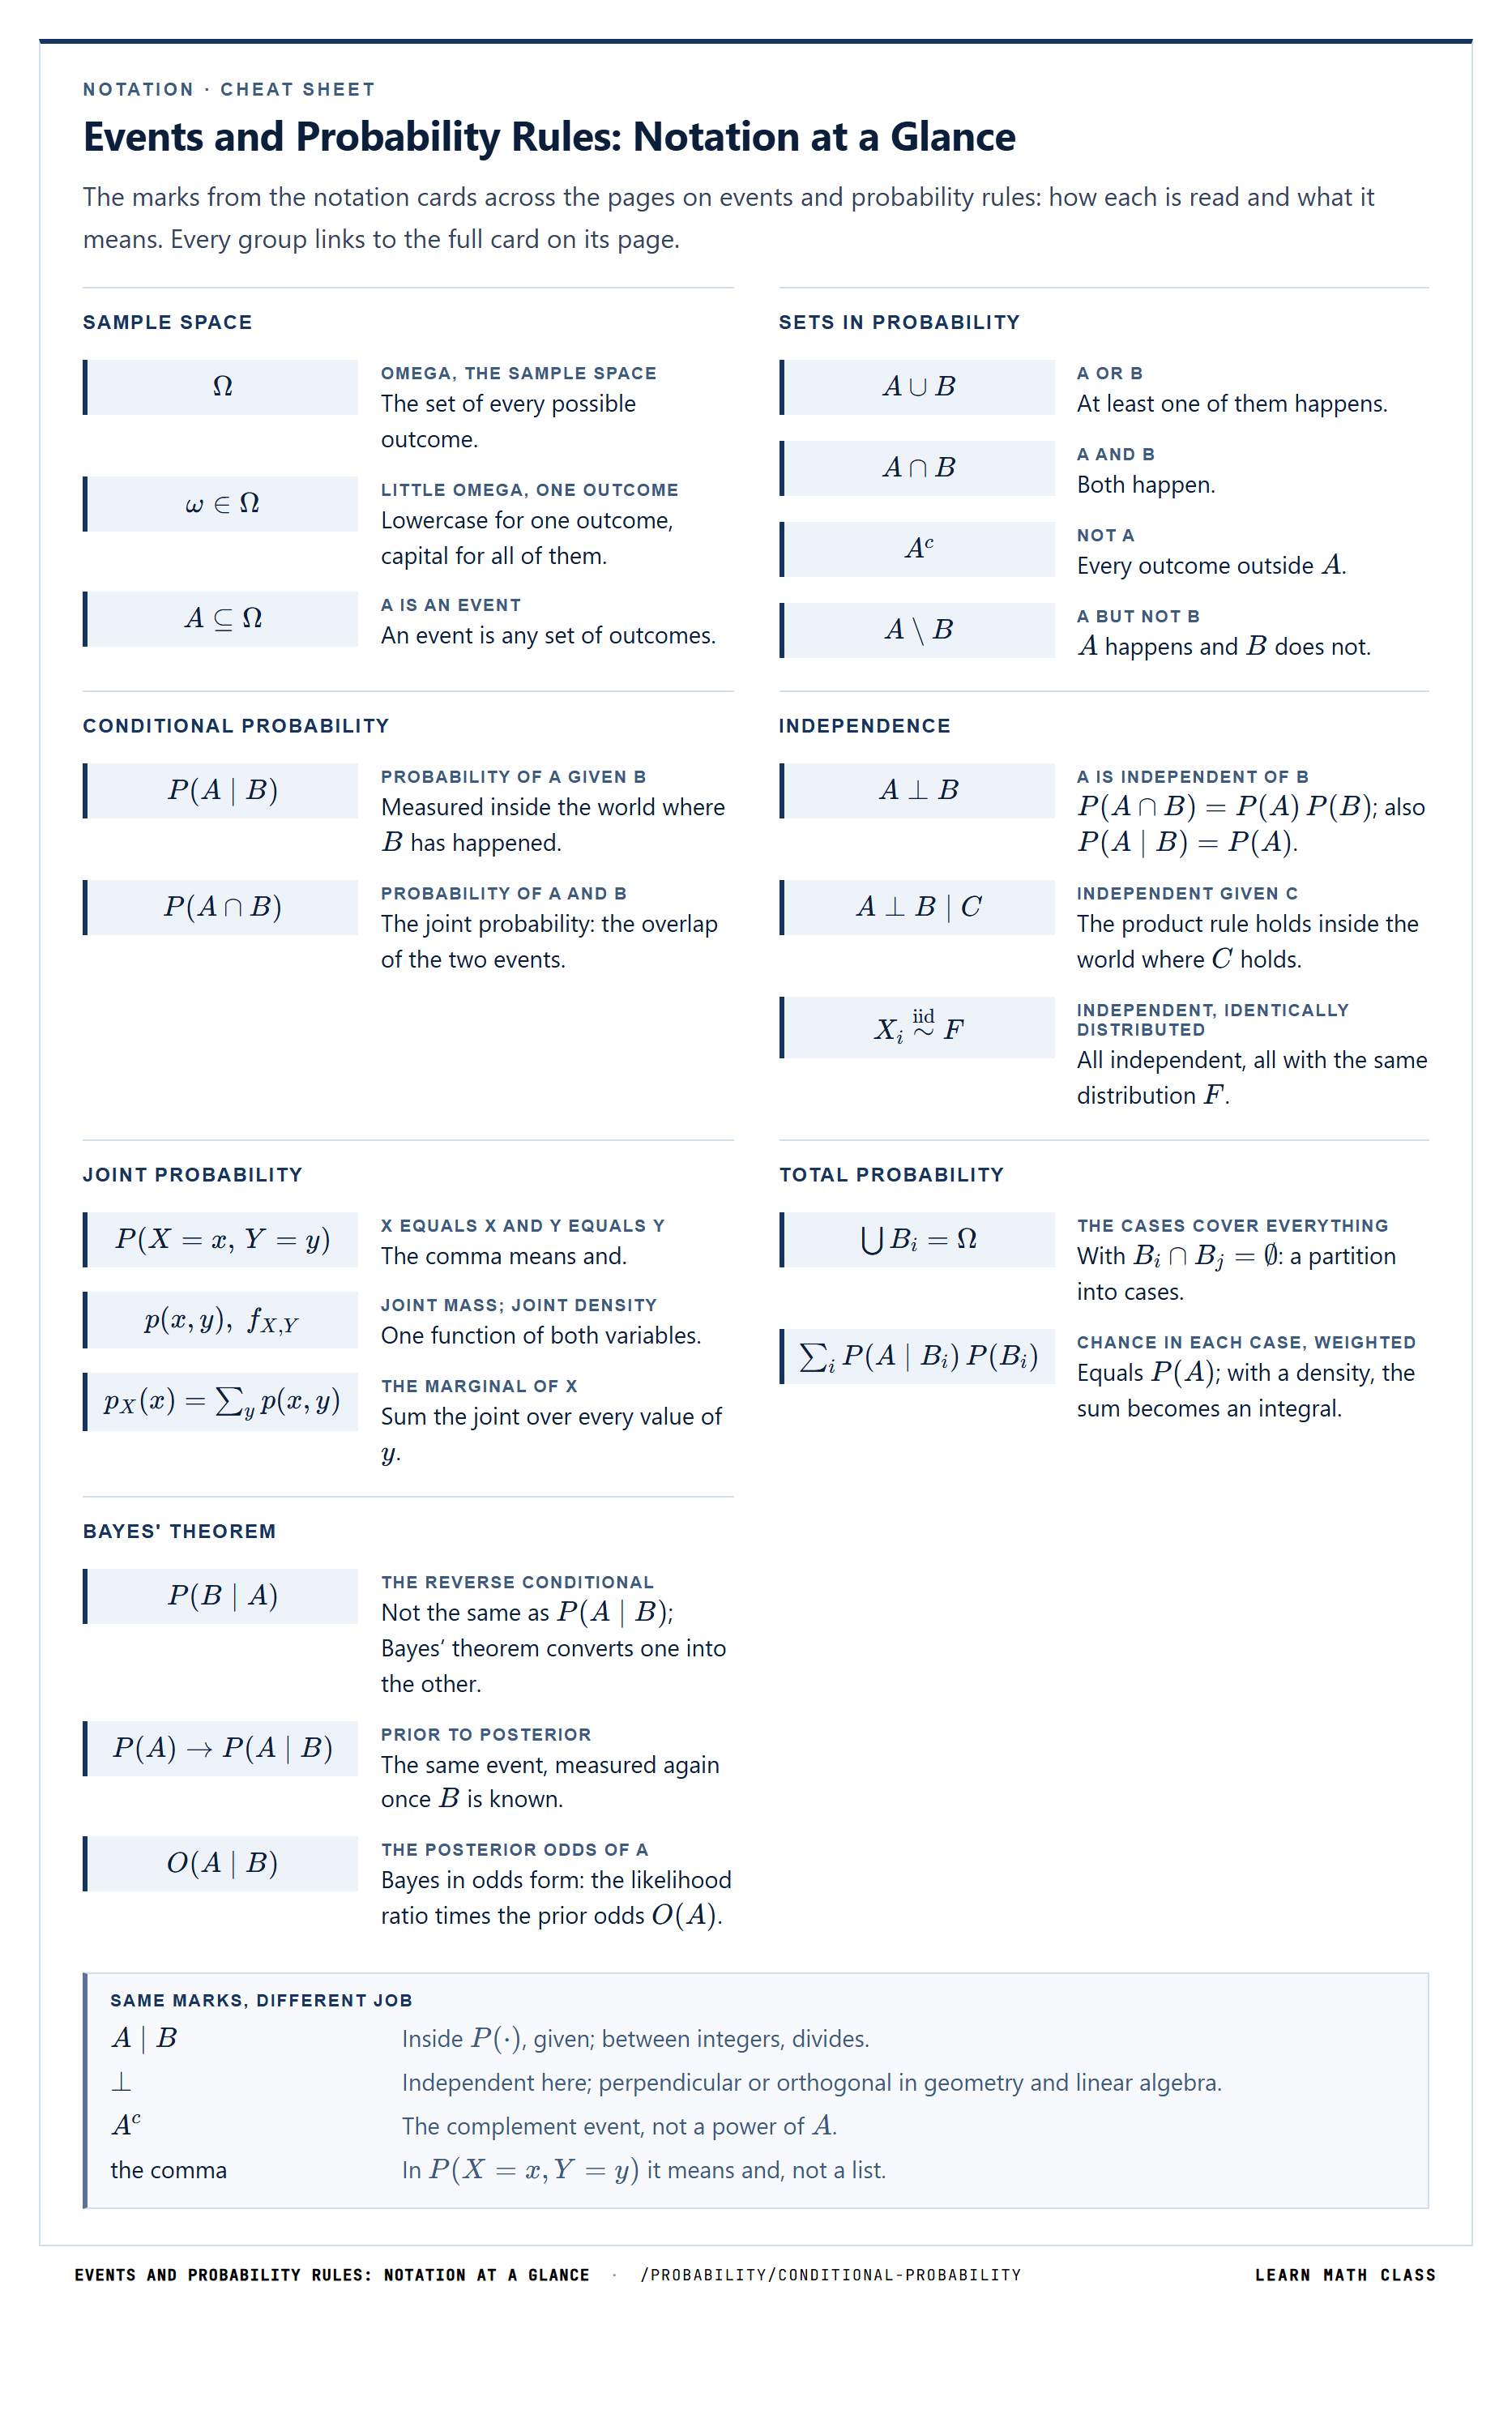
Bayes' theorem introduces no new marks — every symbol in it is already a conditional probability. What it adds is roles: the same P(⋅)P(\cdot) expressions read as prior, likelihood, evidence and posterior depending on where they stand, and the notation's whole job is keeping the bar's two directions from trading places. Every mark here is catalogued among the probability symbols.
The given-bar P(A∣B)P(A \mid B) and the joint P(A∩B)P(A \cap B) come from conditional probability notation, P(⋅)P(\cdot) itself from the probability function, the complement mark AcA^c from set operations, and the summation sign from sequence notation.
P(A∣B),  P(B∣A)P(A \mid B),\; P(B \mid A)
the probability of A given B — and of B given A
The same given-bar, standing in opposite directions: one conditions on the evidence, the other on the hypothesis. Bayes' theorem is the exchange rate between the two — it computes the direction you want from the direction you can measure.
CasesThe likelihood direction P(B∣A)P(B \mid A) is usually the computable one — a model says how the evidence behaves under each scenario; the posterior direction P(A∣B)P(A \mid B) is usually the question being asked. The formula below converts one into the other.
Do not confuseEach other — the transposed conditional, first row of the Common Mistakes table below. A test with P(positive∣disease)=0.99P(\text{positive} \mid \text{disease}) = 0.99 says nothing by itself about P(disease∣positive)P(\text{disease} \mid \text{positive}), which can be small when the disease is rare; in courtroom form this is the prosecutor's fallacy.
P(A)→P(A∣B)P(A) \to P(A \mid B)
from the prior of A to the posterior of A given B
One event, two probabilities: bare P(A)P(A) carries no bar — nothing assumed — and P(A∣B)P(A \mid B) is the same event re-measured once BB is in hand. "Prior" and "posterior" are positions relative to the evidence, not points in time.
CasesEvidence stacks on the right of the bar, P(A∣B1∩B2)P(A \mid B_1 \cap B_2), or arrives in rounds — each round's posterior serves as the next round's prior; hypothesis-flavored texts trade A,BA, B for H,EH, E (hypothesis, evidence) or H,DH, D (data), changing letters and nothing else.
Also writtenBayesian statistics writes the pair as densities over a parameter: π(θ)\pi(\theta) for the prior and π(θ∣x)\pi(\theta \mid x) for the posterior, with the distribution families supplying the shapes; the objectivist school writes even the prior conditionally, P(A∣I)P(A \mid I), with II the background information.
Do not confuseA timestamp. In sequential use one and the same number is the posterior of this round and the prior of the next — the words name roles in a single application of the formula, not the order in which anything happened.
P(B)=∑jP(B∣Aj) P(Aj)P(B) = \sum_j P(B \mid A_j)\,P(A_j)
the total probability of B, summed across all the hypotheses
The normalizer. Written compactly it is just P(B)P(B); expanded, it is the law of total probability doing denominator duty — every route to the evidence, weighted by its prior, so the posteriors across all hypotheses sum to one.
CasesCompact P(B)P(B) when the evidence's probability is known outright; the two-case split P(B∣A) P(A)+P(B∣Ac) P(Ac)P(B \mid A)\,P(A) + P(B \mid A^c)\,P(A^c) when there is only a hypothesis and its complement; the indexed sum when a full partition A1,…,AnA_1, \dots, A_n competes.
Also writtenNot at all: P(A∣B)∝P(B∣A) P(A)P(A \mid B) \propto P(B \mid A)\,P(A) — "posterior proportional to likelihood times prior" — postpones the division and normalizes at the end, the standard spelling in Bayesian computation.
Do not confuseAn independent input. P(B)P(B) is assembled from the same priors and likelihoods that fill the numerator — supplying it from elsewhere double-counts the evidence; omitting it leaves products that no longer sum to one, the Common Mistakes table's final row.
O(A∣B)=LR×O(A)O(A \mid B) = \mathrm{LR} \times O(A)
posterior odds equal the likelihood ratio times the prior odds
Bayes with the denominator cancelled: state the theorem for AA and for AcA^c and divide — P(B)P(B) drops out. Odds are the ratio O(A)=P(A)/P(Ac)O(A) = P(A)/P(A^c), and the likelihood ratio LR=P(B∣A)/P(B∣Ac)\mathrm{LR} = P(B \mid A)/P(B \mid A^c) carries the entire weight of the evidence in one number.
CasesIndependent pieces of evidence multiply their ratios one after another — the cleanest spelling of sequential updating; two-hypothesis problems, a diagnosis against its absence, are its natural habitat.
Also writtenΛ\Lambda for the likelihood ratio in detection and engineering texts; the Bayes factor in statistical model comparison — the same ratio, renamed by tradition.
Do not confuseProbability on the wrong scale. O=3O = 3 means 3:13{:}1, i.e. P=3/4P = 3/4 — odds live on [0,∞)[0, \infty), probabilities on [0,1][0, 1], and feeding one into a slot expecting the other corrupts the update without any visible error.
DownloadPNG2×PDF
Notation · Cheat sheet
Events and Probability Rules: Notation at a Glance
The marks from the notation cards across the pages on events and probability rules: how each is read and what it means. Every group links to the full card on its page.
Sample space
Ω\Omega
omega, the sample space
The set of every possible outcome.
ω∈Ω\omega \in \Omega
little omega, one outcome
Lowercase for one outcome, capital for all of them.
A⊆ΩA \subseteq \Omega
A is an event
An event is any set of outcomes.
Sets in probability
A∪BA \cup B
A or B
At least one of them happens.
A∩BA \cap B
A and B
Both happen.
AcA^c
not A
Every outcome outside AA.
A∖BA \setminus B
A but not B
AA happens and BB does not.
Conditional probability
P(A∣B)P(A \mid B)
probability of A given B
Measured inside the world where BB has happened.
P(A∩B)P(A \cap B)
probability of A and B
The joint probability: the overlap of the two events.
Independence
A⊥BA \perp B
A is independent of B
P(A∩B)=P(A) P(B)P(A \cap B) = P(A)\,P(B); also P(A∣B)=P(A)P(A \mid B) = P(A).
A⊥B∣CA \perp B \mid C
independent given C
The product rule holds inside the world where CC holds.
Xi∼iidFX_i \overset{\text{iid}}{\sim} F
independent, identically distributed
All independent, all with the same distribution FF.
Joint probability
P(X=x, Y=y)P(X = x, \, Y = y)
X equals x and Y equals y
The comma means and.
p(x,y),  fX,Yp(x, y), \; f_{X,Y}
joint mass; joint density
One function of both variables.
pX(x)=∑yp(x,y)p_X(x) = \sum_y p(x, y)
the marginal of X
Sum the joint over every value of yy.
Total probability
⋃Bi=Ω\bigcup B_i = \Omega
the cases cover everything
With Bi∩Bj=∅B_i \cap B_j = \emptyset: a partition into cases.
∑iP(A∣Bi) P(Bi)\sum_i P(A \mid B_i)\,P(B_i)
chance in each case, weighted
Equals P(A)P(A); with a density, the sum becomes an integral.
Bayes' theoremThis page
P(B∣A)P(B \mid A)
the reverse conditional
Not the same as P(A∣B)P(A \mid B); Bayes’ theorem converts one into the other.
P(A)→P(A∣B)P(A) \to P(A \mid B)
prior to posterior
The same event, measured again once BB is known.
O(A∣B)O(A \mid B)
the posterior odds of A
Bayes in odds form: the likelihood ratio times the prior odds O(A)O(A).
Same marks, different job
A∣BA \mid BInside P(⋅)P(\cdot), given; between integers, divides.
⊥\perpIndependent here; perpendicular or orthogonal in geometry and linear algebra.
AcA^cThe complement event, not a power of AA.
the commaIn P(X=x,Y=y)P(X = x, Y = y) it means and, not a list.
Events and Probability Rules: Notation at a Glance·/probability/conditional-probabilityLearn Math Class

Bayes' Theorem (The Formula)


Bayes' theorem expresses the update of probability in a single relation built from conditional probability:

Bayes Theorem
P(A∣B)=P(B∣A) P(A)P(B)P(A \mid B) = \dfrac{P(B \mid A)\,P(A)}{P(B)}
Learn more about this formula: Bayes Theorem →


Pitfall: Ignoring the prior
Comparing defect rates alone, P(D∣M2)=0.10>P(D∣M1)=0.02P(D \mid M_2) = 0.10 > P(D \mid M_1) = 0.02, blames machine 2 for a defective part. But machine 1 makes 90%90\% of the parts: P(M1∣D)=0.9⋅0.020.9⋅0.02+0.1⋅0.10=914≈0.64P(M_1 \mid D) = \frac{0.9 \cdot 0.02}{0.9 \cdot 0.02 + 0.1 \cdot 0.10} = \frac{9}{14} \approx 0.64.

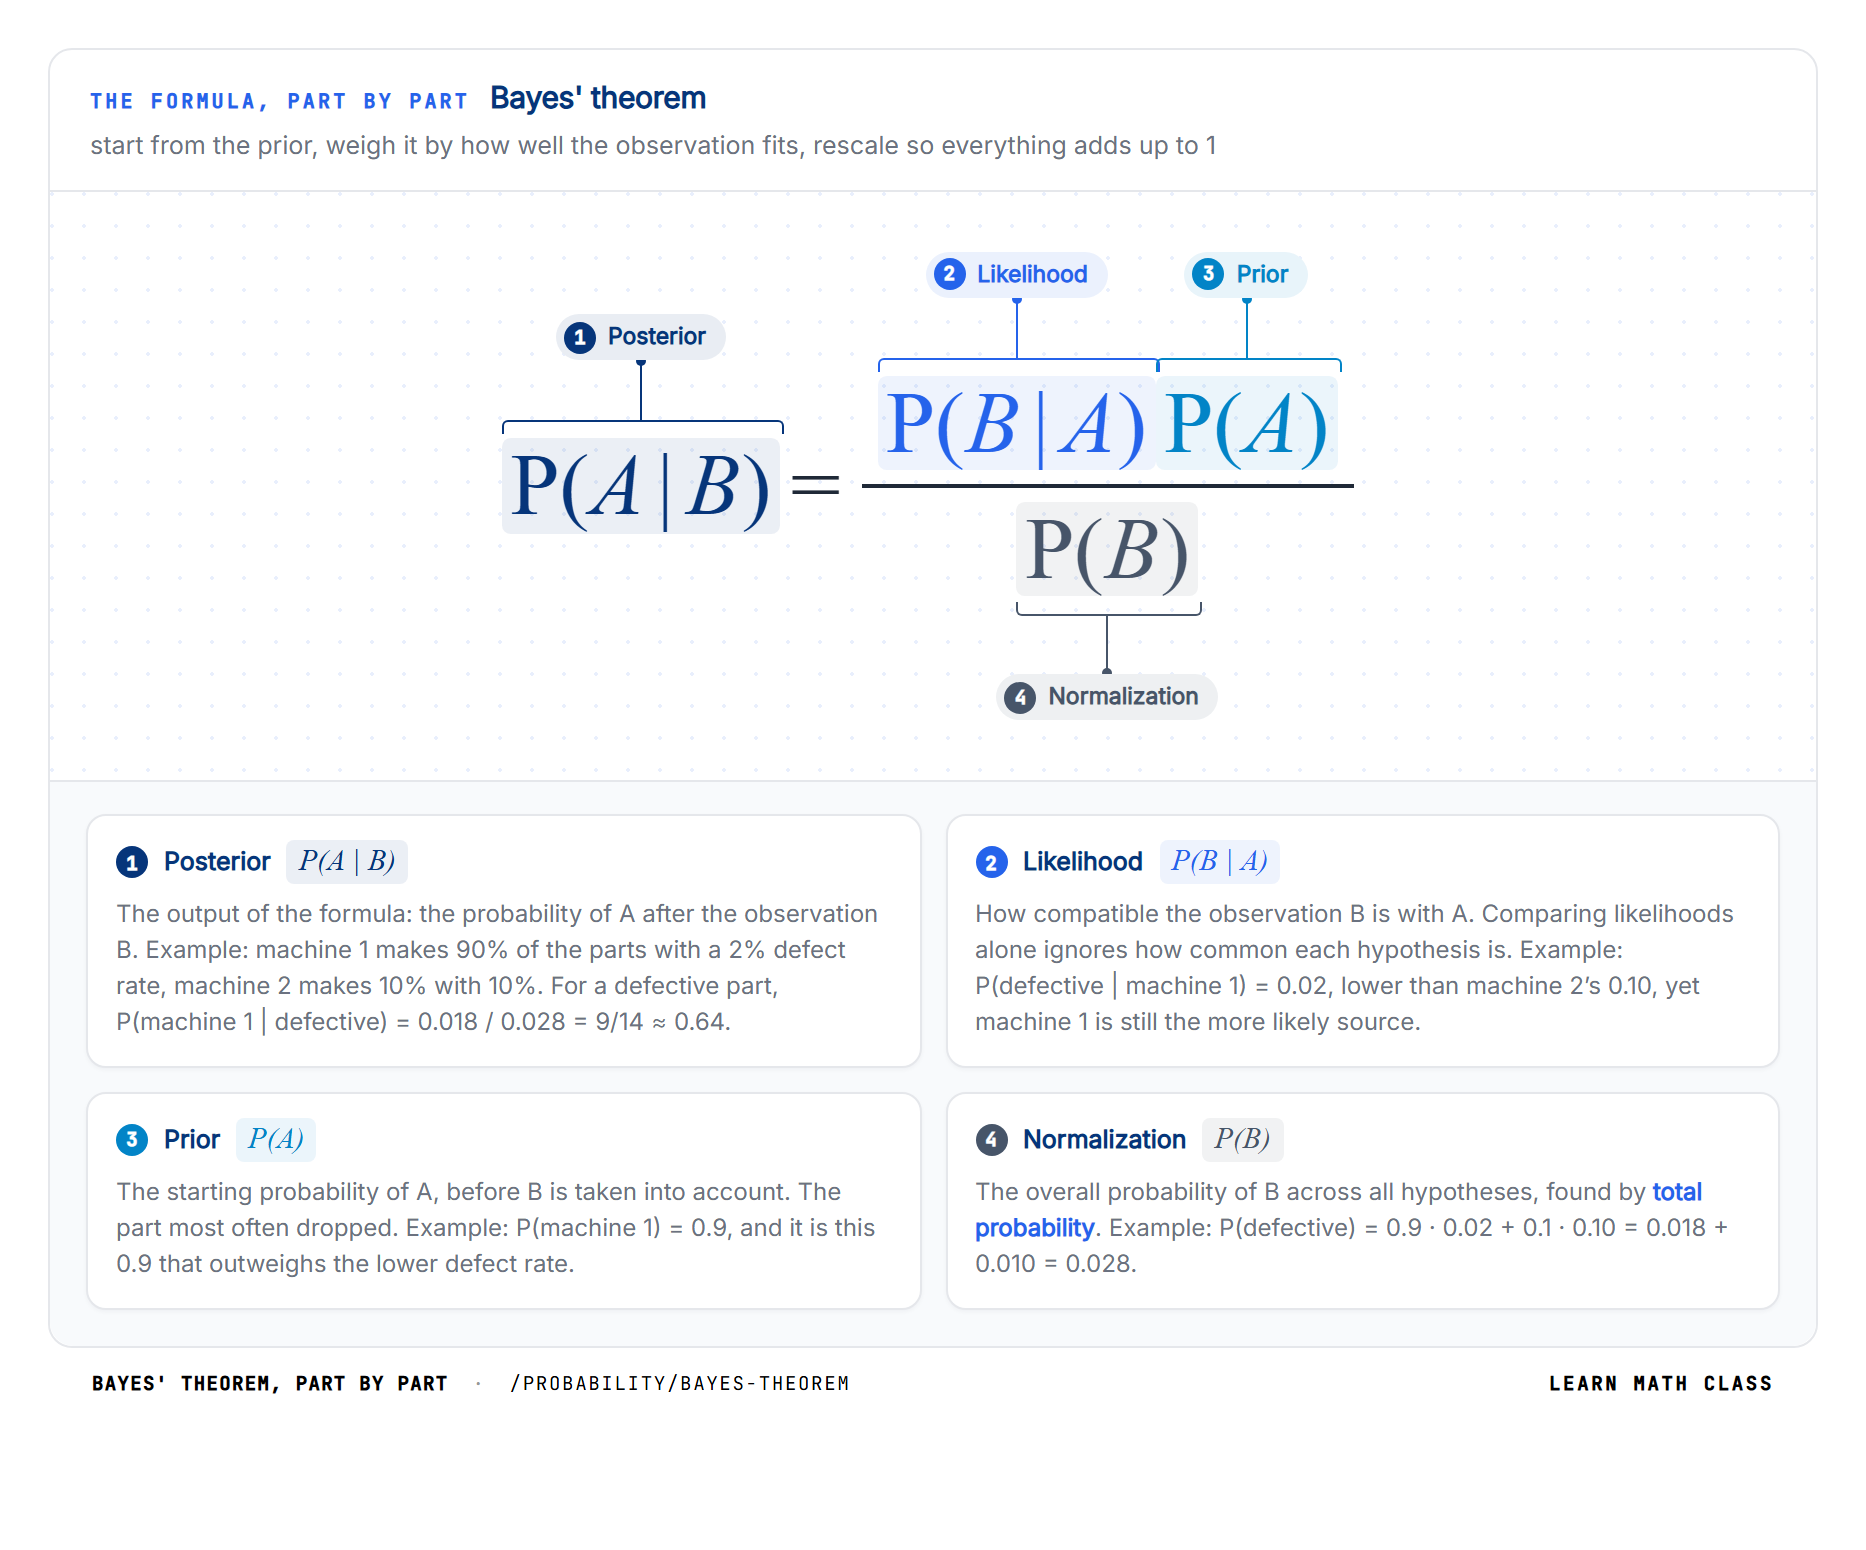
Each part of the formula has a clear role.

The term P(A)P(A) represents the starting assessment before any information is known.

The term P(B∣A)P(B \mid A) measures how compatible the observation is with that situation.

The denominator P(B)P(B) ensures that the updated probabilities remain properly scaled.

This formula does not introduce a new rule. It follows directly from the definition of conditional probability and the basic structure of probability theory. The table below pairs each symbol in the formula with its name and the role it plays in the update.
Symbol Name Role in the formula
P(A) Prior the starting probability of A before any evidence is taken into account
P(B|A) Likelihood how compatible the observation B is with the situation A
P(B) Normalization (total probability) the overall probability of B across all hypotheses; keeps the updated probabilities summing to 1
P(A|B) Posterior the updated probability of A after B is observed — the output of the formula
Taking the formula apart: the posterior on the left, the likelihood and the prior on top, the normalization below.
DownloadPNG2×PDF
the formula, part by part

Bayes' theorem

start from the prior, weigh it by how well the observation fits, rescale so everything adds up to 1
P(A|B)=P(B|A) P(A)P(B)
1PosteriorP(A | B)
The output of the formula: the probability of A after the observation B. Example: machine 1 makes 90% of the parts with a 2% defect rate, machine 2 makes 10% with 10%. For a defective part, P(machine 1 | defective) = 0.018 / 0.028 = 9/14 ≈ 0.64.
2LikelihoodP(B | A)
How compatible the observation B is with A. Comparing likelihoods alone ignores how common each hypothesis is. Example: P(defective | machine 1) = 0.02, lower than machine 2’s 0.10, yet machine 1 is still the more likely source.
3PriorP(A)
The starting probability of A, before B is taken into account. The part most often dropped. Example: P(machine 1) = 0.9, and it is this 0.9 that outweighs the lower defect rate.
4NormalizationP(B)
The overall probability of B across all hypotheses, found by total probability. Example: P(defective) = 0.9 · 0.02 + 0.1 · 0.10 = 0.018 + 0.010 = 0.028.
Bayes' theorem, part by part·/probability/bayes-theoremLearn Math Class
The part most often dropped is the prior: comparing likelihoods alone ignores how common each hypothesis was to begin with. The normalization P(B)P(B) comes from the law of total probability.

The Role of Total Probability


The denominator in Bayes' theorem is not arbitrary. It plays a precise role: it accounts for all the different ways the observed event could occur. This is exactly the idea captured by total probability.

When an observation can arise from several mutually exclusive situations, total probability combines their contributions into a single overall probability. Bayes' theorem uses this combined value to normalize the update, ensuring that the revised probabilities across all possibilities remain consistent.

Seen this way, Bayes' theorem is not complete on its own. Total probability is the mechanism that makes the update coherent, tying Bayes' theorem directly to how probability is distributed across cases.
P(A1) = 0.330P(A2) = 0.330P(A3) = 0.340P(B1|A1) = 0.400P(B2|A1) = 0.300P(B3|A1) = 0.300P(B1|A2) = 0.300P(B2|A2) = 0.500P(B3|A2) = 0.200P(B1|A3) = 0.200P(B2|A3) = 0.300P(B3|A3) = 0.500A1P = 0.330A1 ∩ B1 = 0.132A1 ∩ B2 = 0.099A1 ∩ B3 = 0.099A2P = 0.330A2 ∩ B1 = 0.099A2 ∩ B2 = 0.165A2 ∩ B3 = 0.066A3P = 0.340A3 ∩ B1 = 0.068A3 ∩ B2 = 0.102A3 ∩ B3 = 0.170
One outcome highlighted across every branch of the partition

The denominator P(B) collects the highlighted outcome from every branch: each branch contributes P(Ai) times P(B given Ai), and the sum of those contributions is the total probability of B. Bayes theorem then asks what share of that sum came from a single branch. Highlight an outcome and read the contributions on the law of total probability visualizer.

Pitfall: Leaving cases out of the denominator
With P(D)=0.01P(D) = 0.01, P(+∣D)=0.99P(+ \mid D) = 0.99 and P(+∣Dc)=0.05P(+ \mid D^c) = 0.05, taking P(+)P(+) from the disease branch alone, 0.00990.0099, gives P(D∣+)=1P(D \mid +) = 1. Adding the healthy branch, 0.05⋅0.99=0.04950.05 \cdot 0.99 = 0.0495, gives P(+)=0.0594P(+) = 0.0594 and P(D∣+)=16P(D \mid +) = \frac{1}{6}.

In a two-case problem the partition is a hypothesis and its complement, so P(B)P(B) has exactly two contributions: P(B∣A) P(A)P(B \mid A)\,P(A) from the first case and P(B∣Ac) P(Ac)P(B \mid A^c)\,P(A^c) from the second. With more hypotheses there are more contributions, one for each branch of the partition.

The numerator of Bayes' theorem is one of these contributions, and the denominator is their sum. The posterior is therefore the share of all routes to the evidence that pass through the hypothesis in question.
The chain rule offers a second way to read the same products.

Chain Rule Perspective


Bayes' theorem can also be understood as a rearrangement of joint probability. The chain rule expresses a joint event as a product of conditional probabilities taken in a particular order.

Bayes' theorem changes that order. It takes the same joint probability and factors it differently, allowing us to move from the probability of an observation given a situation to the probability of the situation given the observation.

This perspective removes any sense of mystery. Bayes' theorem is not an extra principle layered onto probability; it is a consequence of how joint probabilities can be decomposed and recombined.

When Independence Simplifies Bayes' Theorem


In some situations, the relationship between events is especially simple. When an observation does not depend on a particular situation, independence removes part of the Bayes' formula entirely.

If the observation behaves the same way regardless of whether a situation occurred, then knowing the situation adds no information about the observation. In this case, certain conditional terms collapse, and the update becomes much simpler.

This is powerful, but also risky. Independence assumptions can dramatically simplify reasoning, yet they must be justified. When independence is assumed without support, Bayes' theorem may produce results that look precise but are conceptually wrong.

Examples


1. Diagnostic reasoning
We observe an outcome and want to reason about its cause. Different situations could have produced what we saw, and Bayes' theorem weighs those possibilities according to both how plausible they were beforehand and how well they explain the observation.

2. Classification intuition
An item belongs to one of several categories, and we observe some of its features. Bayes' theorem updates the probability of each category by combining how common the category is with how typical the features are for that category.

3. When intuition fails
People often judge likelihoods by focusing only on how striking an observation is, ignoring how common the underlying situations are. Bayes' theorem corrects this by forcing both aspects to be considered together.

Fact: Most doctors answered 95%, not 2%
In a 1978 study at Harvard Medical School, the most common answer to this question was 95%, and only 11 of 60 doctors and students gave the right one, about 2%. Out of 1,000 people, 1 is ill, while about 50 healthy people also test positive.

A classic screening question shows the effect. A disease affects one person in a thousand, and a test always detects it but also gives a false positive to 5% of healthy people. A person with no symptoms tests positive. How likely is it that this person has the disease? The striking observation is the positive result; the common situation is being healthy.

These examples show Bayes' theorem as a reasoning tool rather than a calculation trick. It organizes how probabilities should change when information arrives.

Common Mistakes


Bayes' theorem is often misapplied, not because the formula is difficult, but because its structure is misunderstood.

A frequent mistake is confusing P(A∣B)P(A \mid B) with P(B∣A)P(B \mid A). These two quantities describe different questions, and swapping them can completely change the interpretation of a result.

Another common error is ignoring the starting probabilities and focusing only on how well an observation fits a situation. This leads to conclusions that feel intuitive but are mathematically inconsistent.

Independence is also often assumed without justification. Treating terms as independent when they are not can simplify the formula while quietly breaking its meaning.

Finally, the normalization step is sometimes overlooked. Without accounting for all the ways an observation can occur, the updated probabilities cannot be interpreted correctly. The table below pairs each mistake with the correction that prevents it.
Unit square: sick column 0.1 wide, 90% of it tests positive; healthy column 0.9 wide, 10% tests positive; both positive areas are 0.09, so P(sick | +) = 1/2sickhealthyP(sick) = 0.1P(healthy) = 0.90.090.09coloured parts: tested +blue: sick and +0.1 × 0.9 = 0.09amber: healthy and +0.9 × 0.1 = 0.09P(+ | sick) = 0.9P(sick | +)= 0.09 / 0.18 = 0.5P(sick | +) is the blue share of the coloured area: one half
P(+ | sick) is not P(sick | +)

The square is the whole population, total probability 1. The sick column is only 0.1 wide; 90% of it tests positive (blue). The healthy column is 0.9 wide; just 10% of it tests positive (amber). The two coloured parts have the same area, 0.09 each: the test is good, yet false positives from the large healthy group are as common as true ones. So P(+ | sick) = 0.9, while P(sick | +) = 0.09 / 0.18 = 0.5. Swapping the two, or ignoring the column widths, is exactly the mistake this section describes.

Halving the sick column to 0.05 would cut P(sick | +) to about 0.32, with the same test.
Mistake Correction
Confusing P(A|B) with P(B|A) these answer different questions; swapping them reverses the meaning of the result
Ignoring priors and focusing only on fit priors and likelihoods must both be weighed — base rates cannot be discarded just because the evidence is striking
Assuming independence without justification independence can simplify the formula, but treating dependent terms as independent quietly breaks the update
Skipping the normalization step without dividing by P(B) (or summing over all hypotheses), the posterior probabilities will not sum to 1 and cannot be interpreted correctly

Why Bayes' Theorem Matters


Bayes' theorem provides a principled way to revise probabilities when information changes. It formalizes how uncertainty should be updated rather than left to intuition or ad-hoc adjustments.

This update mechanism is central to learning from data, making decisions under uncertainty, and reasoning about hidden causes. It explains how observations influence beliefs without discarding prior structure or introducing inconsistencies.

Because of this, Bayes' theorem underlies a wide range of methods in statistics, data analysis, and probabilistic modeling. Wherever probabilities are revised in light of new information, Bayes' theorem is operating in the background, whether it is stated explicitly or not.
How Bayes' Theorem Fits into Probability


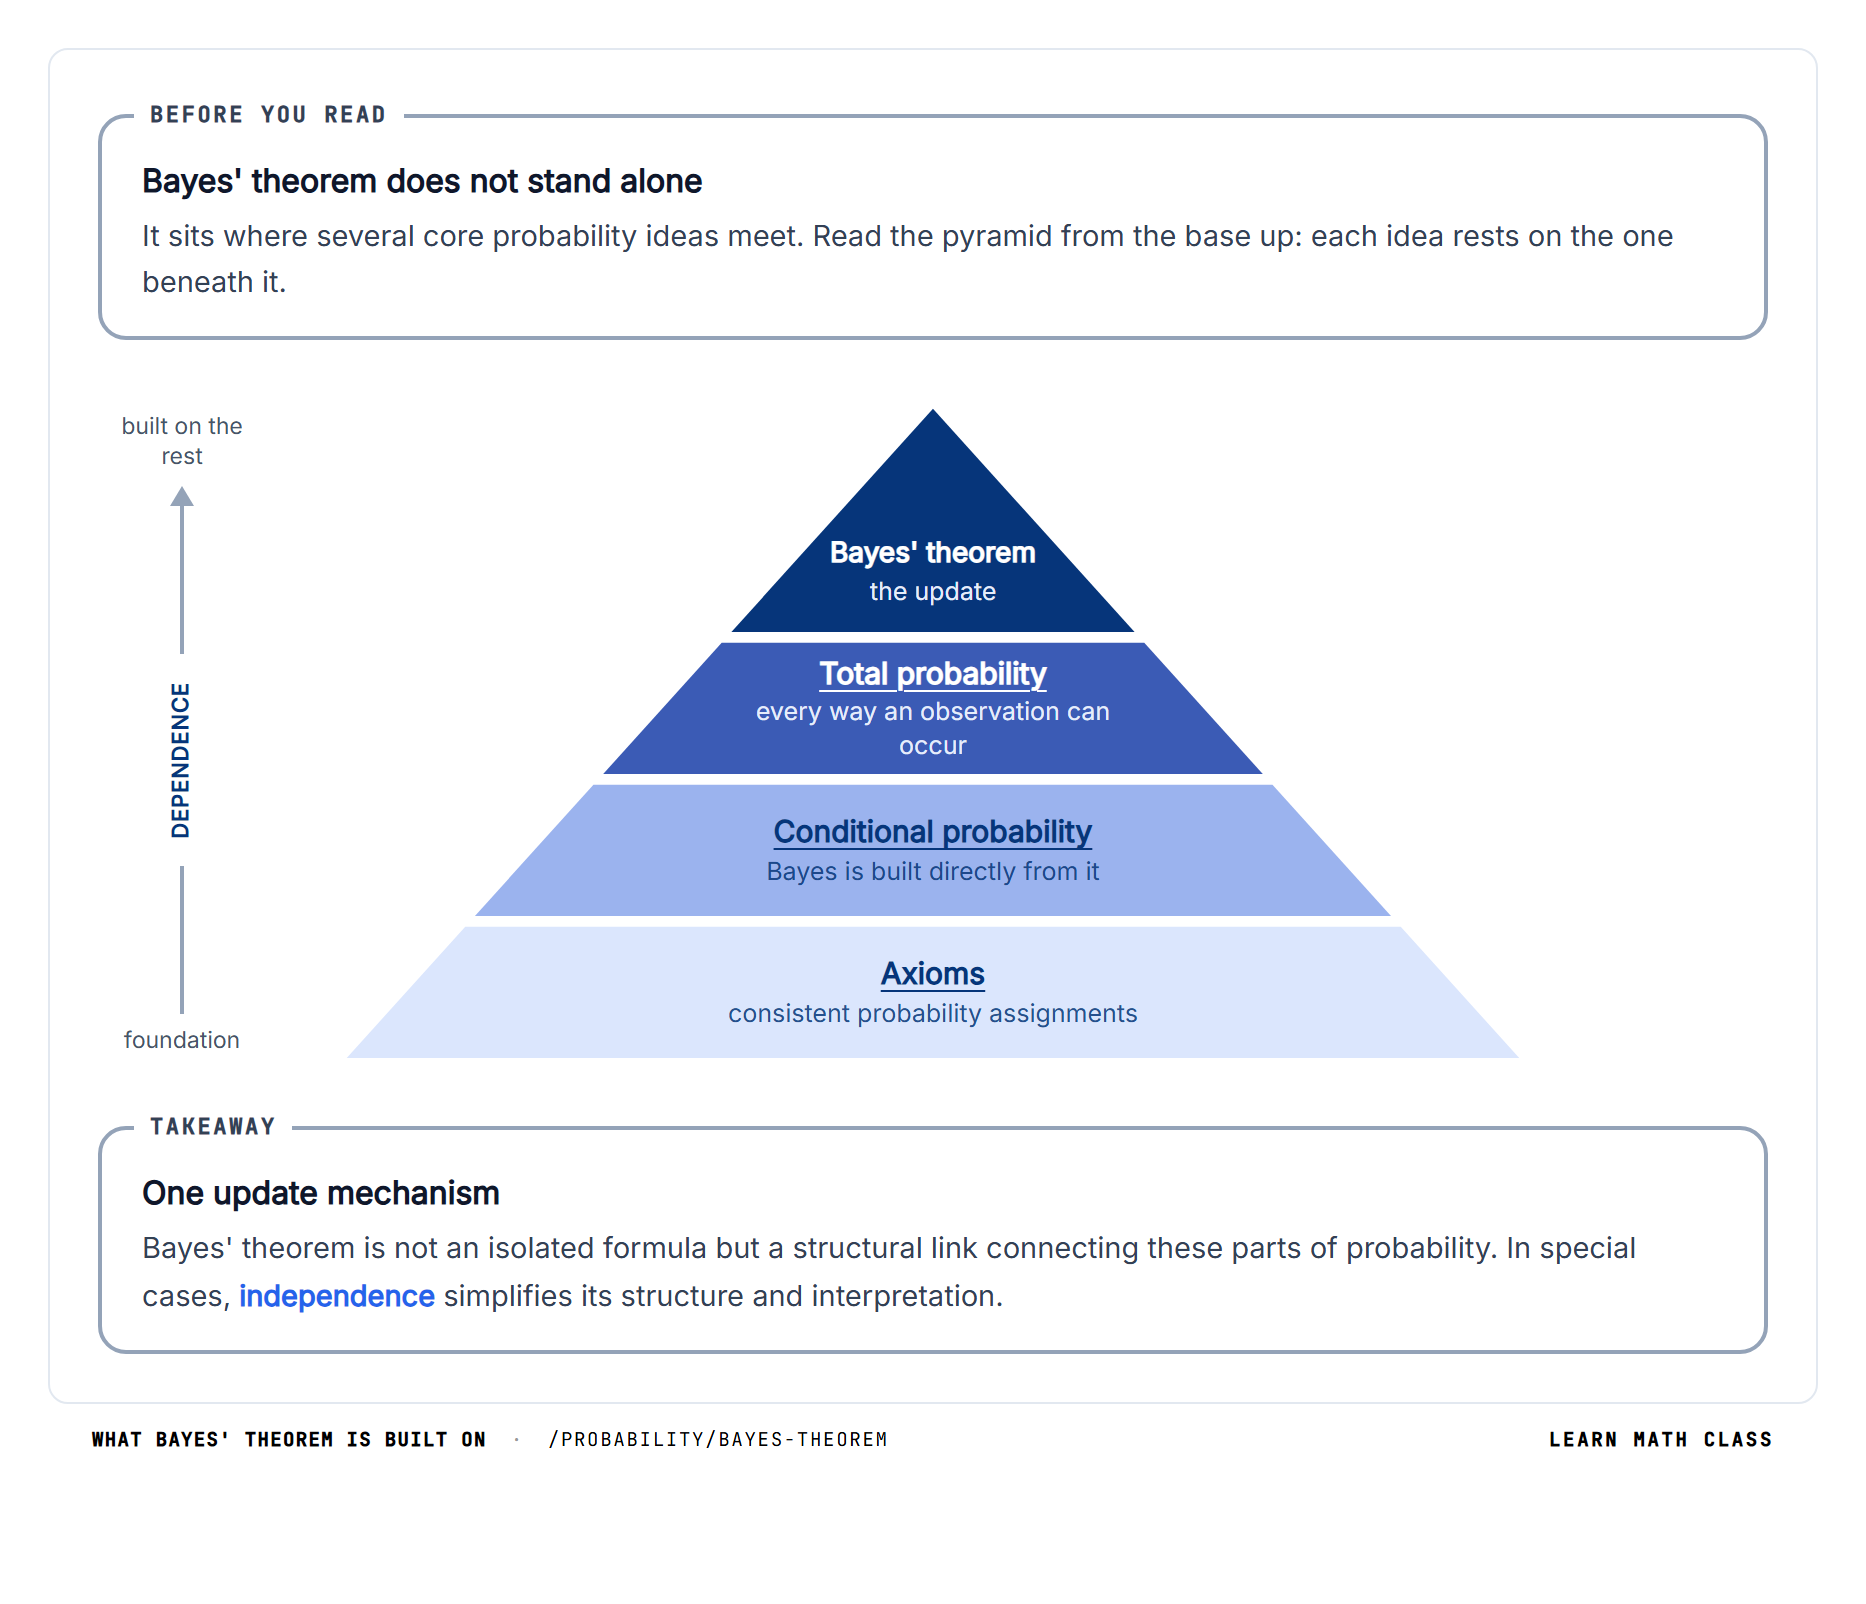
Bayes' theorem does not stand alone. It sits at a junction where several core probability ideas meet.

It relies on the axioms to ensure probabilities are assigned consistently. It is built directly from conditional probability. It uses total probability to account for all possible ways an observation can occur. In special cases, independence simplifies its structure and interpretation.

Seen this way, Bayes' theorem is not an isolated formula, but a structural link that connects many parts of probability into a single coherent update mechanism.
DownloadPNG2×PDF
Before you read
Bayes' theorem does not stand alone
It sits where several core probability ideas meet. Read the pyramid from the base up: each idea rests on the one beneath it.
built on the restdependencefoundation
Bayes' theoremthe update
Total probabilityevery way an observation can occur
Conditional probabilityBayes is built directly from it
Axiomsconsistent probability assignments
Takeaway
One update mechanism
Bayes' theorem is not an isolated formula but a structural link connecting these parts of probability. In special cases, independence simplifies its structure and interpretation.
What Bayes' theorem is built on·/probability/bayes-theoremLearn Math Class

Connections to Other Probability Concepts


Bayes' theorem connects directly to many of the core ideas in probability and helps unify them into a single framework.

• Conditional probability provides the basic mechanism Bayes' theorem reorganizes.
• Total probability supplies the normalization that keeps updated probabilities consistent.
• Independence identifies special cases where the update simplifies.
• Chain rule explains Bayes' theorem as a rearrangement of joint probability.
• Probability axioms guarantee that the update follows consistent rules.
• Random variables and distributions extend Bayes' theorem beyond events to numerical outcomes.

Through these connections, Bayes' theorem acts as a bridge rather than an endpoint, linking foundational principles with practical probabilistic reasoning.

Where Bayes' Theorem Fits — At a Glance


Bayes' theorem is built from several familiar pieces of probability — conditional probability, total probability, the chain rule, independence, and prior knowledge — and contributes a specific update mechanism on top of each. The table below collects these adjacencies, naming what Bayes' theorem draws from each concept and what it adds in return.
Concept What Bayes' theorem draws from it What Bayes' theorem adds in return
Conditional probability the basic mechanism of conditioning on an event a way to reverse the direction of conditioning — from P(B|A) to P(A|B)
Total probability a way to express P(B) as a sum across mutually exclusive hypotheses the denominator that keeps the posterior coherent across all hypotheses
Chain rule a decomposition of the joint probability of A and B a re-factoring of that decomposition that exposes the inverse conditional
Independence cases where P(B|A) equals P(B) a structural simplification: the formula collapses and the update becomes trivial
Prior knowledge an initial assessment of how likely each hypothesis is a principled rule for revising that prior in light of evidence

Bayes' Theorem FAQ

What is the difference between prior and posterior probability?

+
Prior is the probability of a hypothesis before the evidence is taken into account; posterior is the same hypothesis re-measured once the evidence is in hand — P(A) becoming P(A | B). The words name positions relative to the evidence, not moments in time; nothing has to happen in any particular order for the labels to apply.Read more →

Why doesn't a 99% accurate test mean a 99% chance of having the disease?

+
Because 99% accuracy is P(positive | disease), the likelihood, while what you want is P(disease | positive), the posterior. They point in opposite directions. When the disease is rare, the few true positives are swamped by false positives drawn from a much larger healthy population, so the posterior stays small. Swapping the two is called the transposed conditional; in a courtroom it is the prosecutor's fallacy.Read more →

Where does the denominator P(B) in Bayes' theorem come from?

+
From the same priors and likelihoods that build the numerator. It is the law of total probability doing denominator duty: every route to the evidence, weighted by its prior. Supplying P(B) from elsewhere double-counts the evidence; omitting it leaves posteriors that no longer sum to one.Read more →

What is the odds form of Bayes' theorem?

+
Posterior odds equal the likelihood ratio times the prior odds. State Bayes for A and for Aᶜ, then divide: P(B) cancels, leaving no denominator to compute. Watch the scale — odds of 3 mean 3:1, so a probability of 3/4, not 3.Read more →

Can you apply Bayes' theorem more than once?

+
Yes — that is the standard way to handle several pieces of evidence. Apply the formula to the first observation, then use the resulting posterior as the prior for the next round; the same number is the posterior of one step and the prior of the next. In odds form, independent pieces of evidence simply multiply their likelihood ratios.Read more →

Why does switching doors win two times in three in the Monty Hall problem?

+
Because the host's choice is evidence. You pick door 1, and the host, who knows where the car is, opens door 3. If the car is behind door 2 he had to open door 3; if it is behind door 1 he could open either and picks door 3 only half the time; a car behind door 3 rules it out. Bayes gives P(car 2∣opens 3)=13⋅113⋅12+13⋅1+13⋅0=23P(\text{car 2} \mid \text{opens 3}) = \frac{\frac{1}{3} \cdot 1}{\frac{1}{3} \cdot \frac{1}{2} + \frac{1}{3} \cdot 1 + \frac{1}{3} \cdot 0} = \frac{2}{3}.Read more →

What does “posterior is proportional to likelihood times prior” mean?

+
It is Bayes' theorem with the division postponed: P(A∣B)∝P(B∣A) P(A)P(A \mid B) \propto P(B \mid A)\,P(A). The denominator P(B)P(B) is the same for every hypothesis, so it does not change how they compare. Compute likelihood times prior for each hypothesis, then divide by their total at the end so the posteriors sum to 1. For the two machines the products 0.0180.018 and 0.0100.010 become 914\frac{9}{14} and 514\frac{5}{14}.Read more →