Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


The Law of Large Numbers


From Randomness to Reliable Averages


A single observation can be wildly unpredictable, but averages behave differently. The Law of Large Numbers is the theorem that explains why: as you collect more independent data from the same source, the sample mean stabilizes and moves toward a fixed target—the true expected value of the distribution.

This page presents the formal statement of the theorem, clarifies what kind of convergence it guarantees, and separates the LLN from nearby ideas such as the Central Limit Theorem. It’s the mathematical reason that sampling, estimation, simulation, and empirical measurement can be trusted at all.

Key Terms

Expected Value— μ=E[Xi]\mu = E[X_i], the value the sample mean converges to
Random Variable— the i.i.d. variables being averaged
Relative Frequency— the empirical counterpart the LLN formalizes

See All Probability Definitions →


Formal Statement of the Law of Large Numbers

Flip a fair coin again and again and keep track of the share of heads.
After a few flips the share can be almost anything. Does it settle down?
In a typical run the share wanders at first and then stays close to 1/2.
flipsheadsshare of heads
1070.7
100460.46
1 0005080.508
10 0004 9940.4994
These numbers are one possible run, not a rule. Another run gives other numbers, but the same narrowing around 12\frac{1}{2}.
The average of many independent tries closes in on the expected value.
Each flip is a random variable XiX_i equal to 11 for heads and 00 for tails, with mean μ=12\mu = \frac{1}{2}. The share of heads is their average.
The definition
The law of large numbers states that the sample mean of independent, identically distributed random variables with finite mean μ\mu converges in probability to μ\mu.
Let X1,X2,…,XnX_1, X_2, \dots, X_n be independent and identically distributed random variables with finite mean μ\mu.
Let Xˉn\bar X_n denote their sample mean:
Formal Statement of the Law of Large Numbers
Xˉn=1n∑i=1nXi\displaystyle \bar X_n = \frac{1}{n}\sum_{i=1}^n X_i
As the sample size nn increases, the sample mean converges to the population mean in probability:
Formal Statement of the Law of Large Numbers
Xˉn→Pμ\displaystyle \bar X_n \xrightarrow{P} \mu
This means that for any ε>0\varepsilon > 0, no matter how small:
Formal Statement of the Law of Large Numbers
lim⁡n→∞P(∣Xˉn−μ∣>ε)=0\displaystyle \lim_{n \to \infty} P(|\bar X_n - \mu| > \varepsilon) = 0
The probability that the sample mean differs from μ\mu by more than any fixed amount approaches zero as the sample size grows.
So the share of heads, the average of the XiX_i, gets arbitrarily close to 12\frac{1}{2} with probability approaching 11.
The law holds whatever the shape of the distribution.
This result does not depend on the shape of the original distribution.
Only independence, identical distribution, and finite mean are required.
Unlike the Central Limit Theorem, finite variance is not necessary.
The law is about the long-run average, not about the next flip.
After 77 heads in 1010 flips, tails is not due: the next flip is still 12\frac{1}{2} either way. The early surplus is diluted by many later flips, not cancelled, as explained in what the theorem is really describing.
The rest of the page covers what the theorem describes, the objects involved, visual intuition, the weak and strong laws, notation, when the law applies, common misconceptions, the comparison with the central limit theorem, why it matters, interactive tools and a summary.

What the Theorem Is Really Describing


The Law of Large Numbers is not about individual outcomes or single measurements.

Instead, it describes the behavior of the average as more and more observations are collected.

Fact: 10,000 tosses in an internment camp
Interned in Denmark during the Second World War, the mathematician John Kerrich tossed a coin 10,000 times and counted 5,067 heads. The share, 0.50670.5067, sat within 0.0070.007 of 12\frac{1}{2}: at that size its standard deviation is only 1210,000=0.005\frac{1}{2\sqrt{10{,}000}} = 0.005.

When you flip a coin once, the result is completely unpredictable. When you flip it ten times, the proportion of heads might be anywhere from 0 to 1. But when you flip it a thousand times, something remarkable happens: the proportion stabilizes near 0.5, and deviations become increasingly rare.

This stabilization is not coincidence—it is mathematical necessity.

THEOREMLaw of Large Numbers
The Law of Large Numbers guarantees that as the sample size grows, the sample mean gets arbitrarily close to the true expected value, with probability approaching certainty.

The theorem explains why averages are more reliable than individual observations. A single measurement tells you little. The average of many measurements tells you almost everything about the underlying mean.

Pitfall: Expecting tails to be due
Expecting tails to be more likely than 12\frac{1}{2} after 10 heads in a row gives the coin a memory it does not have; the next flip is still 12\frac{1}{2} either way. The share of heads settles by dilution: after 100 flips its expected value is 10+45100=0.55\frac{10 + 45}{100} = 0.55.

This is not about eliminating randomness—individual outcomes remain random. The theorem reveals that randomness, when aggregated, produces predictable patterns. Individual chaos becomes collective order through the simple act of averaging.

Objects Involved in the Theorem


The Law of Large Numbers involves several distinct mathematical objects, each playing a specific role. Understanding these objects separately is essential for correct interpretation.

Population mean (μ\mu)
The true expected value of the underlying distribution. This is the fixed, deterministic value that the sample mean approaches. It represents what we would obtain if we could average infinitely many observations.

Random variables (X1,X2,…,XnX_1, X_2, \dots, X_n)
Independent copies of the same underlying random variable, each drawn from the identical distribution with mean μ\mu. These are the individual observations or measurements.

Sample mean (Xˉn\bar X_n)
The average of the first nn observations,
Objects Involved in the Theorem
Xˉn=1n∑i=1nXi\displaystyle \bar X_n = \frac{1}{n}\sum_{i=1}^n X_i
This is itself a random variable—before data is collected, its value is uncertain. As nn increases, this random quantity becomes less random, concentrating near μ\mu.

Sample size (nn)
The number of observations used to compute the average. Larger nn produces stronger convergence. The theorem describes behavior as n→∞n \to \infty, but practical convergence begins at finite sample sizes.

The theorem does not describe how individual observations behave.
It describes how the sample mean behaves as the sample size grows—specifically, that it converges to the population mean in probability.

DownloadPNG2×PDF
μ\mu
Population mean
  • The true expected value of the underlying distribution.
  • The fixed value that the sample mean approaches.
X1,X2,…,XnX_1, X_2, \dots, X_n
Random variables
  • Independent copies of the same underlying random variable.
  • Each is drawn from the identical distribution with mean μ\mu.
Xˉn\bar X_n
Sample mean
  • The average of the first nn observations.Xˉn=1n∑i=1nXi\bar X_n = \frac{1}{n}\sum_{i=1}^n X_i
  • Itself a random variable; as nn increases it concentrates near μ\mu.
nn
Sample size
  • The number of observations used to compute the average.
  • Larger nn produces stronger convergence.
Law of Large Numbersthe objects involved
What the theorem describesNot how individual observations behave, but how the sample mean behaves as the sample size grows.
Objects Involved in the TheoremLearn Math Class

Visual Intuition


Visual Intuition


The Law of Large Numbers is best understood visually.
Rather than focusing on formulas, this section shows how the sample mean evolves as observations accumulate.

* Early samples (small n)
When the sample size is small, the sample mean is highly volatile. It can swing dramatically with each new observation, landing far from the true mean. Random fluctuations dominate the behavior.

* Increasing the sample size
As more observations are collected, the sample mean begins to stabilize. The wild swings become smaller. The running average starts to hover near the population mean, with deviations becoming less frequent and less severe.

* Convergence emerges (large n)
For sufficiently large samples, the sample mean stays very close to the true mean. Random fluctuations persist, but they become negligible relative to the sample size. The path may wander slightly, but it remains tightly clustered around μ\mu.

* Universal pattern across distributions
Whether the original data come from uniform, exponential, or discrete distributions, the sample mean always converges to the population mean. The specific distribution affects the speed of convergence, but not the eventual outcome.

These visuals highlight the core message of the theorem:
averaging transforms randomness into predictability. Individual values remain uncertain, but their average becomes certain at scale.
Running proportion of heads in two simulated sequences of 300 fair coin flips: wide swings early, both settle near 0.5nshare of heads501001502002503000.250.50.751two runs of 300 fair coin flipsnavy line: the true mean 0.5early: large swingslater: both hug 0.5The running average settles; single flips stay random
Two running averages of coin flips

Two simulated sequences of 300 fair coin flips (fixed for this figure). Each curve is the share of heads after n flips. In the first few dozen flips both swing widely, one starting at 1 and the other dropping toward 0.2. As n grows, each new flip moves the average less, and by n = 300 both sit at 0.5, the true mean. The individual flips never became less random; only their average settled.

Run it again and the early paths change completely; the place they settle does not.
Pitfall: Expecting the count of heads to even out
Expecting the number of heads to close in on n2\frac{n}{2} confuses the count with the share. The count's distance from n2\frac{n}{2} has standard deviation n2\frac{\sqrt{n}}{2}: 55 at n=100n = 100, 5050 at n=10,000n = 10{,}000. Only the share's gap shrinks, from 0.050.05 to 0.0050.005.

The curves in the figure follow the share of heads: the number of heads so far divided by the number of flips. The number of heads itself is a different quantity. After nn flips its mean is n2\frac{n}{2}, and every new flip still moves it by a full unit, no matter how long the run has been.

The law of large numbers is a statement about the share. Dividing by nn is the step that turns a count which keeps wandering into an average that settles.

Weak vs Strong Law of Large Numbers


The Law of Large Numbers actually comes in two versions, differing in the strength of their convergence guarantee.

Weak Law of Large Numbers (WLLN)
For any ε>0\varepsilon > 0, no matter how small:
Weak vs Strong Law of Large Numbers
lim⁡n→∞P(∣Xˉn−μ∣>ε)=0\displaystyle \lim_{n \to \infty} P(|\bar X_n - \mu| > \varepsilon) = 0

This says: the probability of the sample mean deviating from μ\mu by more than any fixed amount shrinks to zero. The sample mean converges to μ\mu in probability. This is a statement about probabilities, not about individual sequences.

Strong Law of Large Numbers (SLLN)
With probability 1:
Weak vs Strong Law of Large Numbers
Xˉn→μ as n→∞\displaystyle \bar X_n \to \mu \text{ as } n \to \infty

Fact: Proved for almost every number, not π\pi
In 1909 Émile Borel proved one of the first strong laws: for almost every number in [0,1][0, 1], each digit 00 to 99 has a long-run share of exactly 110\frac{1}{10} in its decimal expansion. Yet for π\pi, ee and 2\sqrt{2} no one has proved it.

This says: for almost every sequence of observations, the sample mean actually converges to μ\mu. This is almost sure convergence—a stronger form of convergence than the weak law provides. The set of sequences that fail to converge has probability zero.

Key Difference
The weak law guarantees that large deviations become unlikely. The strong law guarantees that convergence actually happens for the sequence you observe.

THEOREM
Almost sure convergence implies convergence in probability, but not vice versa.

In practice, both versions lead to the same intuition: averages stabilize at the true mean. The distinction matters primarily in theoretical contexts and when analyzing sequences with dependence or unusual tail behavior.

Weak vs Strong at a Glance


The two versions can be lined up side by side: the statement, the convergence mode they invoke, the structural conditions they need, and what each one practically guarantees.
DownloadPNG2×PDF
Layout
AspectWeak Law (WLLN)Strong Law (SLLN)
Formal statementlimn→∞_{n→∞} P(|X̄ₙ − μ| > ε) = 0P(X̄ₙ → μ as n → ∞) = 1
Convergence typein probabilityalmost sure
What it assertslarge deviations become arbitrarily unlikelythe observed sequence itself actually converges
Logical strengthweakerstronger — SLLN ⟹ WLLN, not vice versa
Typical conditionsfinite mean (variance not required)finite mean; classical proofs assume more
Practical takeawaya single sample mean is unlikely to stray far from μwhatever sequence you observe, its running average converges
Weak vs Strong Law of Large NumbersLearn Math Class
The weak law makes a large miss unlikely at each n; the strong law makes the path you observe actually arrive.

Law of Large Numbers Notation

Notation

Law of Large Numbers Notation

The two laws differ by a single notational choice — where the limit stands relative to PP — and the arrows that state them differ only by their riders. This section fixes the rider system, the ε-anatomy of the weak guarantee, and the probability-one spelling of the strong one. All of them are catalogued among the probability symbols.
X1,…,XnX_1, \dots, X_n, the i.i.d. declaration and Xˉn\bar{X}_n come from random variable, independence and central limit theorem notation; μ\mu from expected value notation; lim⁡n→∞\lim_{n \to \infty} from limit notation.
→P\xrightarrow{P}, →a.s.\xrightarrow{\text{a.s.}}
converges in probability — converges almost surely
One arrow, different riders: the rider names the mode, and the mode is the entire difference between the two laws Weak vs Strong Law of Large Numbers above separates. →P\xrightarrow{P} is the weak law's arrow from the Formal Statement; the strong law's own mark →a.s.\xrightarrow{\text{a.s.}} rarely appears in elementary texts, which write a bare arrow and say "with probability 1" in prose.
Also writtenplim⁡ Xˉn=μ\operatorname{plim}\, \bar{X}_n = \mu — econometrics' spelling of convergence in probability, the arrow traded for a limit operator; some texts set the rider as a subscript, →P\to_P.
Do not confuseThe CLT's →d\xrightarrow{d} from central limit theorem notation. The riders rank — almost-sure implies in-probability implies in-distribution — and an unmarked arrow leans entirely on context to say which is meant, which is why careful statements never drop the rider.
P(∣Xˉn−μ∣>ε)P(|\bar{X}_n - \mu| > \varepsilon)
the probability of deviating from the mean by more than epsilon
The anatomy of the weak law's guarantee: the absolute-value bar measures distance from the target, ε\varepsilon names an arbitrary tolerance, and P(⋅)P(\cdot) wraps the deviation into an event — the object whose probability the limit then sends to zero.
CasesThe claim is quantified: "for every ε>0\varepsilon > 0", so the statement must survive every shrinking of the tolerance, not one choice of it; the letter itself comes in two glyphs, ε\varepsilon and ϵ\epsilon — one typesetting tradition apart, mathematically identical.
Do not confuseA fixed small number. ε\varepsilon is not "some tiny constant" the statement picked — it is chosen by the challenger and ranges over everything positive; reading it as a single value quietly converts the law's guarantee into a far weaker claim.
P(lim⁡n→∞Xˉn=μ)=1P\big(\lim_{n \to \infty} \bar{X}_n = \mu\big) = 1
with probability one, the sequence itself converges
The strong law in marks — and the sharpest reading on this page: the position of the limit is the whole difference between the two laws. The weak law puts lim⁡\lim outside PP — a sequence of probabilities falls to zero; the strong law puts lim⁡\lim inside PP — the convergence itself becomes an event, and that event carries probability one.
CasesThe prose abbreviations line up by tradition: "a.s." (almost surely) in probability, "w.p. 1" (with probability 1) in applied writing, and "a.e." (almost everywhere) in measure theory — three spellings of the same probability-one qualifier.
Do not confuseCertainty. Probability one is not "always": with infinitely many outcomes, exceptional sequences exist — a coin can land heads forever — but the set of them collects probability zero; the "almost" in "almost surely" is doing precise work, not hedging.
DownloadPNG2×PDF
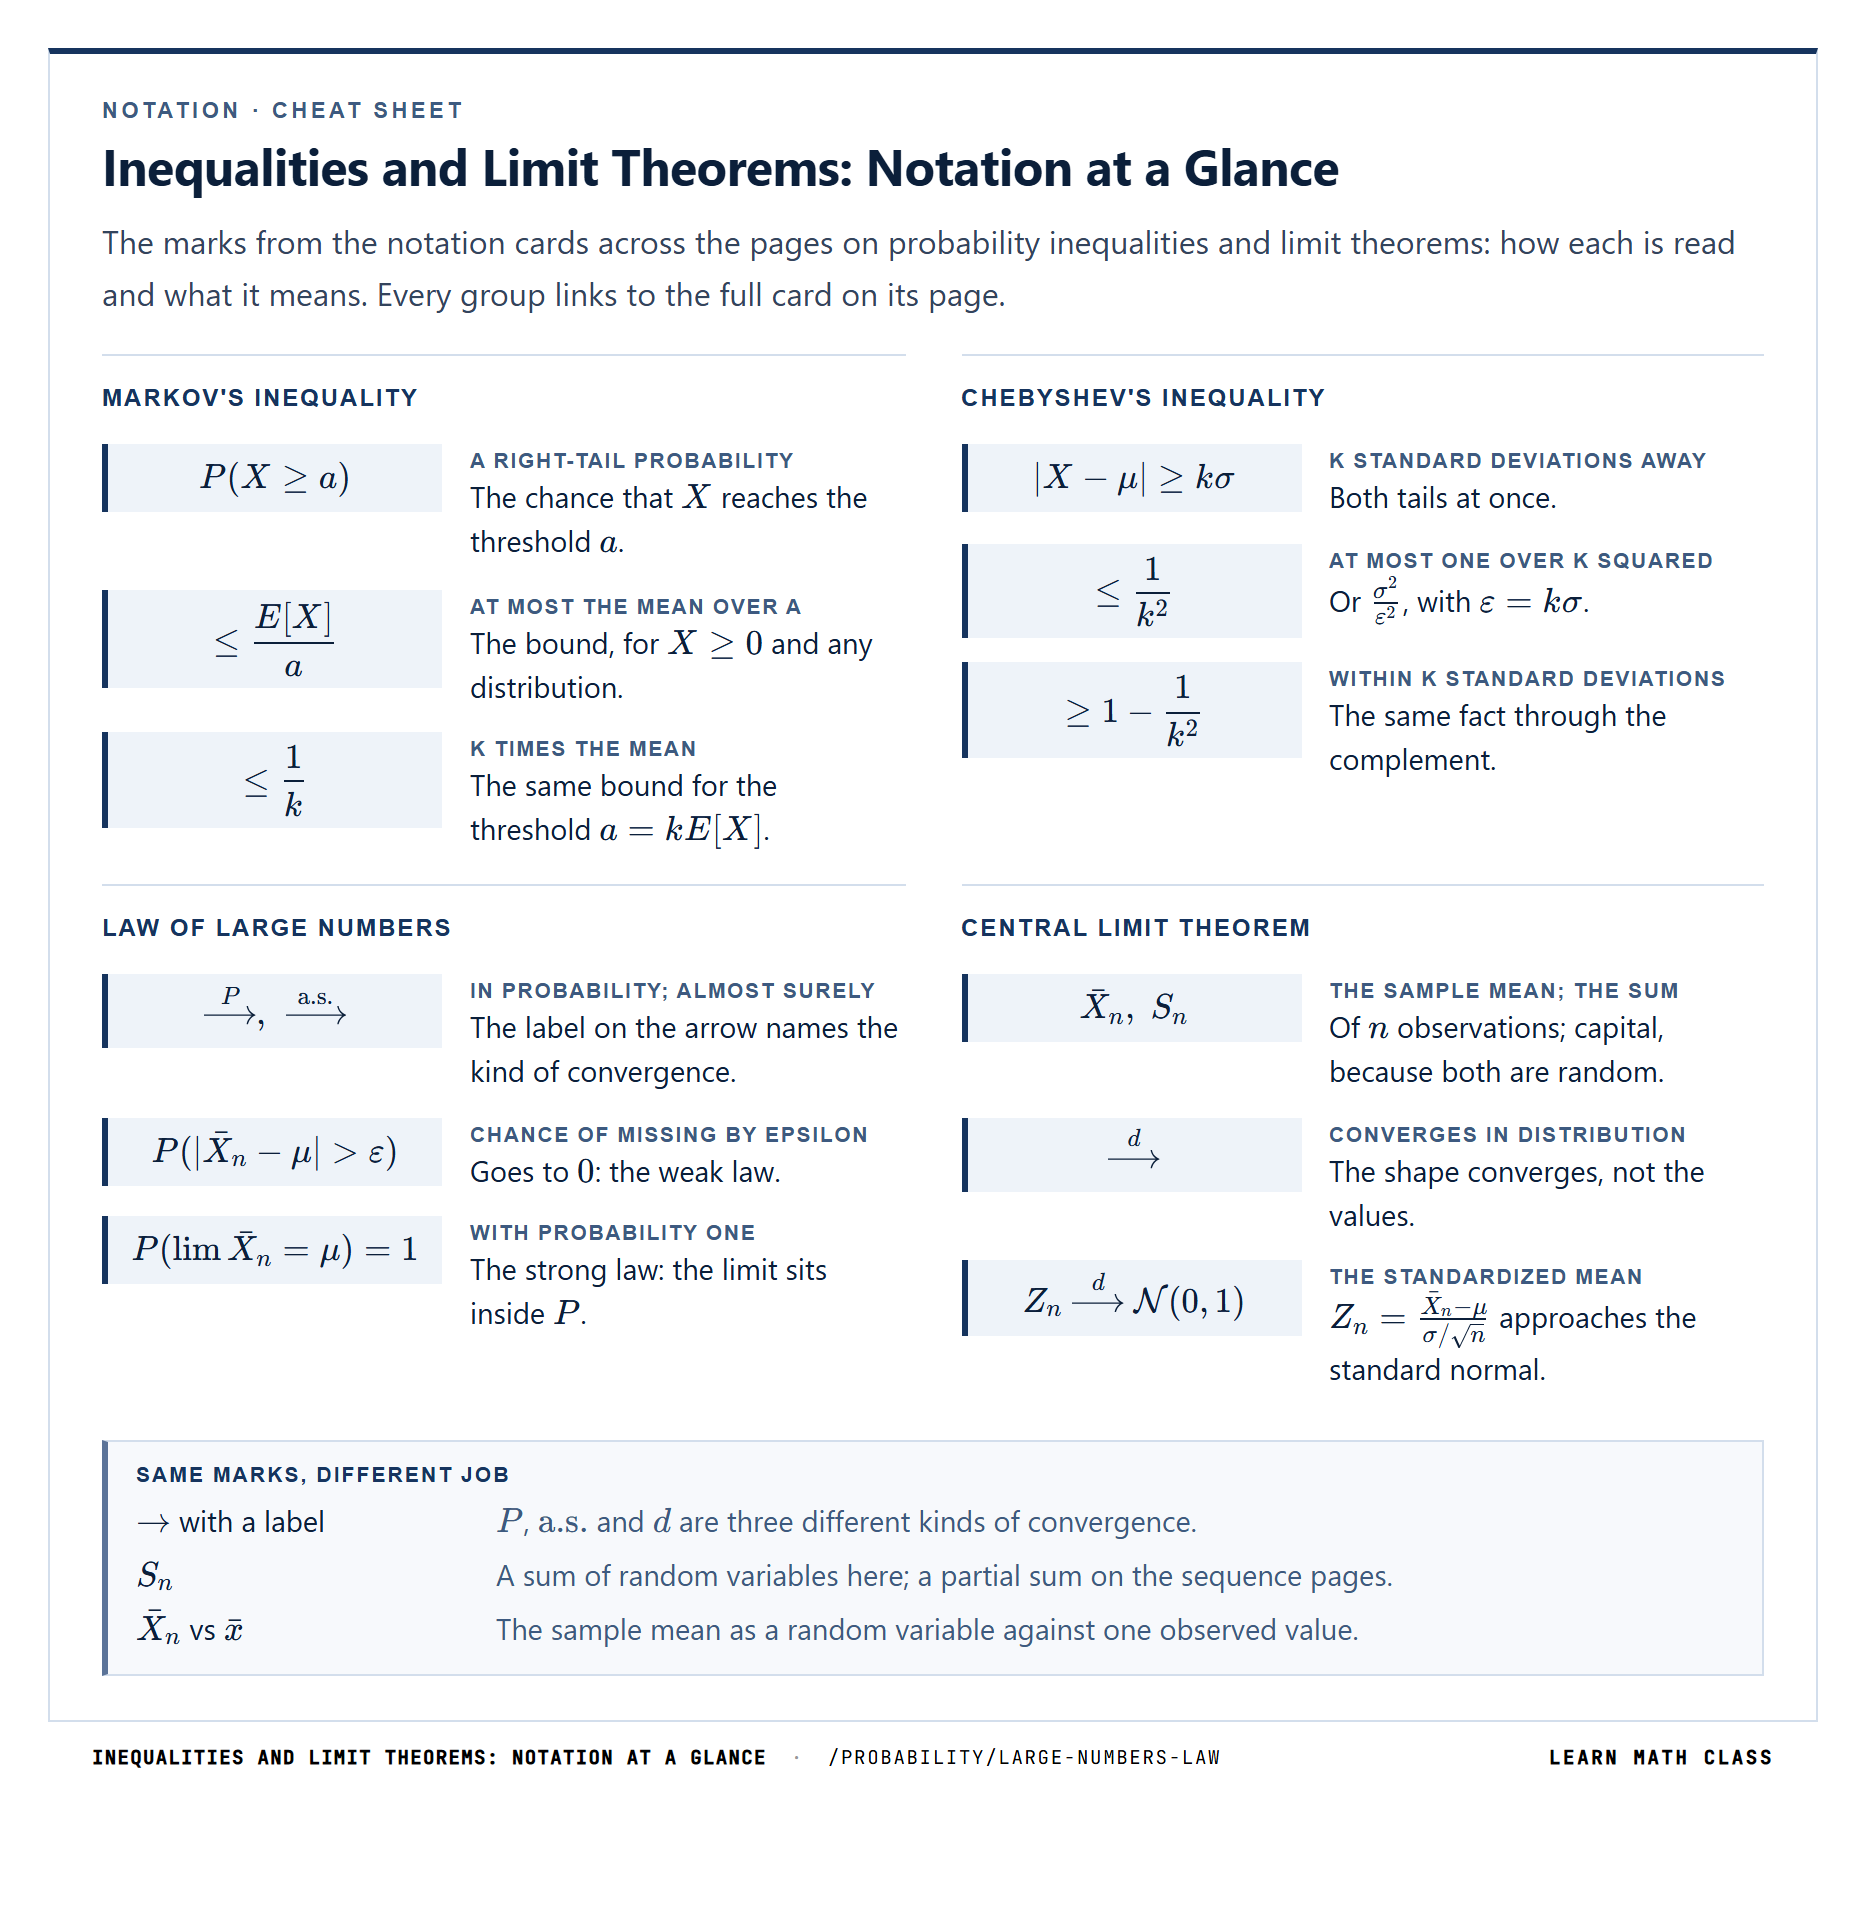
Notation · Cheat sheet
Inequalities and Limit Theorems: Notation at a Glance
The marks from the notation cards across the pages on probability inequalities and limit theorems: how each is read and what it means. Every group links to the full card on its page.
Markov's inequality
P(X≥a)P(X \ge a)
a right-tail probability
The chance that XX reaches the threshold aa.
≤E[X]a\le \dfrac{E[X]}{a}
at most the mean over a
The bound, for X≥0X \ge 0 and any distribution.
≤1k\le \dfrac{1}{k}
k times the mean
The same bound for the threshold a=kE[X]a = kE[X].
Chebyshev's inequality
∣X−μ∣≥kσ|X - \mu| \ge k\sigma
k standard deviations away
Both tails at once.
≤1k2\le \dfrac{1}{k^2}
at most one over k squared
Or σ2ε2\frac{\sigma^2}{\varepsilon^2}, with ε=kσ\varepsilon = k\sigma.
≥1−1k2\ge 1 - \dfrac{1}{k^2}
within k standard deviations
The same fact through the complement.
Law of large numbersThis page
→P,  →a.s.\xrightarrow{P}, \; \xrightarrow{\text{a.s.}}
in probability; almost surely
The label on the arrow names the kind of convergence.
P(∣Xˉn−μ∣>ε)P(|\bar{X}_n - \mu| > \varepsilon)
chance of missing by epsilon
Goes to 00: the weak law.
P(lim⁡Xˉn=μ)=1P(\lim \bar{X}_n = \mu) = 1
with probability one
The strong law: the limit sits inside PP.
Central limit theorem
Xˉn,  Sn\bar{X}_n, \; S_n
the sample mean; the sum
Of nn observations; capital, because both are random.
→d\xrightarrow{d}
converges in distribution
The shape converges, not the values.
Zn→dN(0,1)Z_n \xrightarrow{d} \mathcal{N}(0,1)
the standardized mean
Zn=Xˉn−μσ/nZ_n = \frac{\bar{X}_n - \mu}{\sigma/\sqrt{n}} approaches the standard normal.
Same marks, different job
→\to with a labelPP, a.s.\text{a.s.} and dd are three different kinds of convergence.
SnS_nA sum of random variables here; a partial sum on the sequence pages.
Xˉn\bar{X}_n vs xˉ\bar{x}The sample mean as a random variable against one observed value.
Inequalities and Limit Theorems: Notation at a Glance·/probability/large-numbers-lawLearn Math Class

When the Law of Large Numbers Applies


The Law of Large Numbers does not apply automatically in every situation.
Its validity depends on several key conditions.

Independence
The observations must not influence one another. If outcomes are correlated or dependent, the stabilization effect can break down. Dependence can cause the sample mean to wander without converging, or converge to the wrong value.

Identical distribution
Each observation must come from the same underlying distribution. Mixing different distributions—changing means, changing shapes—can prevent convergence. The theorem requires that μ\mu is the same for all XiX_i.

Finite mean
The expected value μ\mu must exist and be finite. Distributions with undefined or infinite means (like the Cauchy distribution) violate this requirement. Without a well-defined mean, there is nothing for the sample mean to converge to.

Variance requirement (context-dependent)
The weak law does not require finite variance—only finite mean. For independent, identically distributed variables the strong law also needs only a finite mean (Kolmogorov). Heavy-tailed distributions with infinite variance can still satisfy the weak law, but convergence may be slow.

When these conditions fail, the conclusion of the theorem may no longer hold.
In particular, strongly dependent data or distributions without finite means can produce sample means that never stabilize, even as the sample size grows arbitrarily large. Independence and identical distribution are the core structural requirements.

Conditions at a Glance


Each requirement plays a specific structural role, and each one fails in its own way; the table below pairs the condition with what it guarantees and the consequence of its violation.
DownloadPNG2×PDF
Layout
ConditionWhat it requiresWhat happens if it fails
Independenceobservations do not influence each othercorrelated data can prevent the sample mean from stabilizing
Identical distributionevery Xᵢ is drawn from the same distribution with the same μmixing distributions removes a single μ to converge to
Finite meanμ = E[Xᵢ] exists and is finiteno target value to converge to (e.g., Cauchy distribution)
Finite variance (context-dependent)not required by WLLN; sometimes assumed in classical SLLN proofsheavy-tailed but finite-mean distributions still converge, only more slowly
When the Law of Large Numbers AppliesLearn Math Class

Common Misconceptions


The Law of Large Numbers is often misunderstood. The following clarifications address the most common errors.

"Small samples are unreliable."
Small samples are not wrong—they are simply more variable. The sample mean from a small sample is an unbiased estimator of μ\mu; it is not systematically incorrect. The issue is variance, not bias. Small samples produce wider ranges of possible values, but their average is still centered at the true mean.

"The theorem guarantees convergence for any finite sample."
The Law of Large Numbers is an asymptotic result. It describes behavior as n→∞n \to \infty, not at any particular finite nn. There is no fixed sample size where convergence is guaranteed. Practical convergence depends on the distribution's properties—how skewed, how heavy-tailed, how volatile.

"Past results influence future outcomes" (the gambler's fallacy).
Independence means no memory. If a fair coin lands heads ten times in a row, the next flip is still 50-50. The Law of Large Numbers does not say that tails become "due" to balance things out. It says that with enough flips, the proportion approaches 0.5, but each individual flip remains independent.

"LLN and CLT are the same thing."
The Law of Large Numbers tells us the sample mean converges to a value (μ\mu). The Central Limit Theorem tells us the distribution of sample means is approximately normal. LLN describes where we go; CLT describes how we get there. They are complementary, not equivalent.

"Convergence means the sample mean equals the population mean."
Convergence in probability does not mean equality. It means the probability of large deviations shrinks. For any finite nn, Xˉn≠μ\bar X_n \neq \mu with positive probability. The theorem describes limiting behavior, not finite-sample certainty.

Pitfalls at a Glance


The errors above share a common pattern: confusing what the theorem says about long-run behavior with claims about single observations or finite samples. The table below collects them with the underlying confusion and the correct view.
DownloadPNG2×PDF
Layout
MisconceptionWhy it's wrongCorrect view
Small samples are biasedsmall samples are more variable, not systematically offthe sample mean is an unbiased estimator of μ at any n
Convergence is guaranteed at finite nthe LLN is an asymptotic statement about n → ∞no fixed n delivers certainty; practical convergence depends on the distribution
Past outcomes affect future ones (gambler's fallacy)independence means no memory across trialsproportions approach μ via more data, not by "correcting" past runs
LLN and CLT are the same theoremthey answer different questions about averagesLLN gives the limit value μ; CLT gives the limiting shape (normal)
Convergence means equalityconvergence in probability is not pointwise equalityat any finite n, X̄ₙ ≠ μ with positive probability
Common MisconceptionsLearn Math Class
Expected share of heads after ten heads in a row: 0.5 + 5/n, falling toward 0.5 without any compensating tailsnexpected share501001502002503000.250.50.7510.5 + 5/nstart: 10 heads in a rowevery later flip still 50-50expected heads: 10 + (n − 10)/2n = 200: 0.525The streak is diluted, not cancelled
Why tails are never due

Suppose the first 10 flips of a fair coin are all heads. Every later flip is still heads with probability 1/2, so after n flips the expected number of heads is 10 + (n − 10)/2 and the expected share is 0.5 + 5/n. The share falls toward 0.5 only because the streak becomes a smaller part of a growing total: no extra tails are needed or expected.

The surplus of 5 heads is still expected at n = 1000; it is just 0.5% of the flips.
One more mistake is worked through here in full, with the wrong and the right working side by side.
DownloadPNG2×PDF
1Expecting the count of heads to even out
The law is read as a statement about the number of heads: as the flips go on, the count is expected to come closer and closer to exactly half the number of flips.
Wrong turn
Error here
From Hnn→12\frac{H_n}{n} \to \frac{1}{2}, where HnH_n is the number of heads in nn flips, conclude that Hn−n2H_n - \frac{n}{2} shrinks toward 00, so that after 10,00010{,}000 flips the count should sit closer to 5,0005{,}000 than it sat to 5050 after 100100 flips.
Right path
HnH_n has variance n⋅12⋅12=n4n \cdot \frac{1}{2} \cdot \frac{1}{2} = \frac{n}{4}, so its distance from n2\frac{n}{2} has standard deviation n2\frac{\sqrt{n}}{2}:
n=100: 1002=5,n = 100: \ \frac{\sqrt{100}}{2} = 5,

n=10,000: 10,0002=50n = 10{,}000: \ \frac{\sqrt{10{,}000}}{2} = 50
The share Hnn\frac{H_n}{n} has standard deviation 12n\frac{1}{2\sqrt{n}}, which falls from 0.050.05 to 0.0050.005. The typical gap in the count grows tenfold while the gap in the share shrinks tenfold.
Why it happens"the average settles at 0.5" sounds like "heads and tails balance out". The law divides by nn, and that division is what makes the deviation small.
How to checkAt n=10,000n = 10{,}000, two standard deviations of the count is 2⋅50=1002 \cdot 50 = 100 heads, so the count usually lands anywhere from 4,9004{,}900 to 5,1005{,}100. As a share that same range is only 0.490.49 to 0.510.51.
Common pitfalls with the law of large numbers·/probability/large-numbers-lawLearn Math Class
The law of large numbers is about the proportion of heads, not their number. The proportion Hnn\frac{H_n}{n} settles at 12\frac{1}{2}, while the count HnH_n typically lies further and further from n2\frac{n}{2} as nn grows, by about n2\frac{\sqrt{n}}{2}. Comparing the spread of the count at a large nn catches the slip.

LLN vs Central Limit Theorem


The Law of Large Numbers and the Central Limit Theorem are often confused because both involve sample means and large sample sizes. However, they answer fundamentally different questions.

Law of Large Numbers (LLN)
Tells us that as we collect more observations, the sample mean gets closer and closer to the true population mean. This is a statement about convergence to a specific value. If you flip a fair coin many times, the proportion of heads approaches 0.5—that's the LLN at work.

Mathematically:
LLN vs Central Limit Theorem
Xˉn→Pμ\displaystyle \bar X_n \xrightarrow{P} \mu

The sample mean converges to a number. This is deterministic behavior emerging from randomness.

Central Limit Theorem (CLT)
Tells us something else entirely: it describes the shape of the distribution that sample means follow. Even if individual observations are far from normal, the CLT guarantees that the distribution of sample means will be approximately normal, centered at the population mean, with spread determined by the sample size.

Mathematically:
LLN vs Central Limit Theorem
Xˉn−μσ/n→dN(0,1)\displaystyle \frac{\bar X_n - \mu}{\sigma / \sqrt{n}} \xrightarrow{d} \mathcal{N}(0,1)

The sample mean follows a distribution. This is probabilistic structure revealed by aggregation.

Key Differences
• LLN: Sample mean → a value (where we're going)
• CLT: Sample means → a distribution (how they're distributed around where we're going)
• LLN: Requires only finite mean
• CLT: Requires finite variance
• LLN: Describes one sequence converging
• CLT: Describes many sample means forming a bell curve

Both involve averaging, both require large samples, but they reveal different aspects of how randomness behaves at scale. The LLN tells us where the mean goes; the CLT tells us the shape of the path.
0.0000.0800.1600.2400.3200.400-4-3-2-101234Value (k)Density f(x)E[X]=0.00
Standard normal density: the shape the central limit theorem adds

The law of large numbers says the sample mean settles at a single value; the central limit theorem adds the shape of the remaining fluctuation around that value, this bell curve, once the deviations are scaled up by the square root of n. Without the scaling the bell would shrink to a spike, which is the law itself. Compare the bell with other density shapes on the distribution explorer.

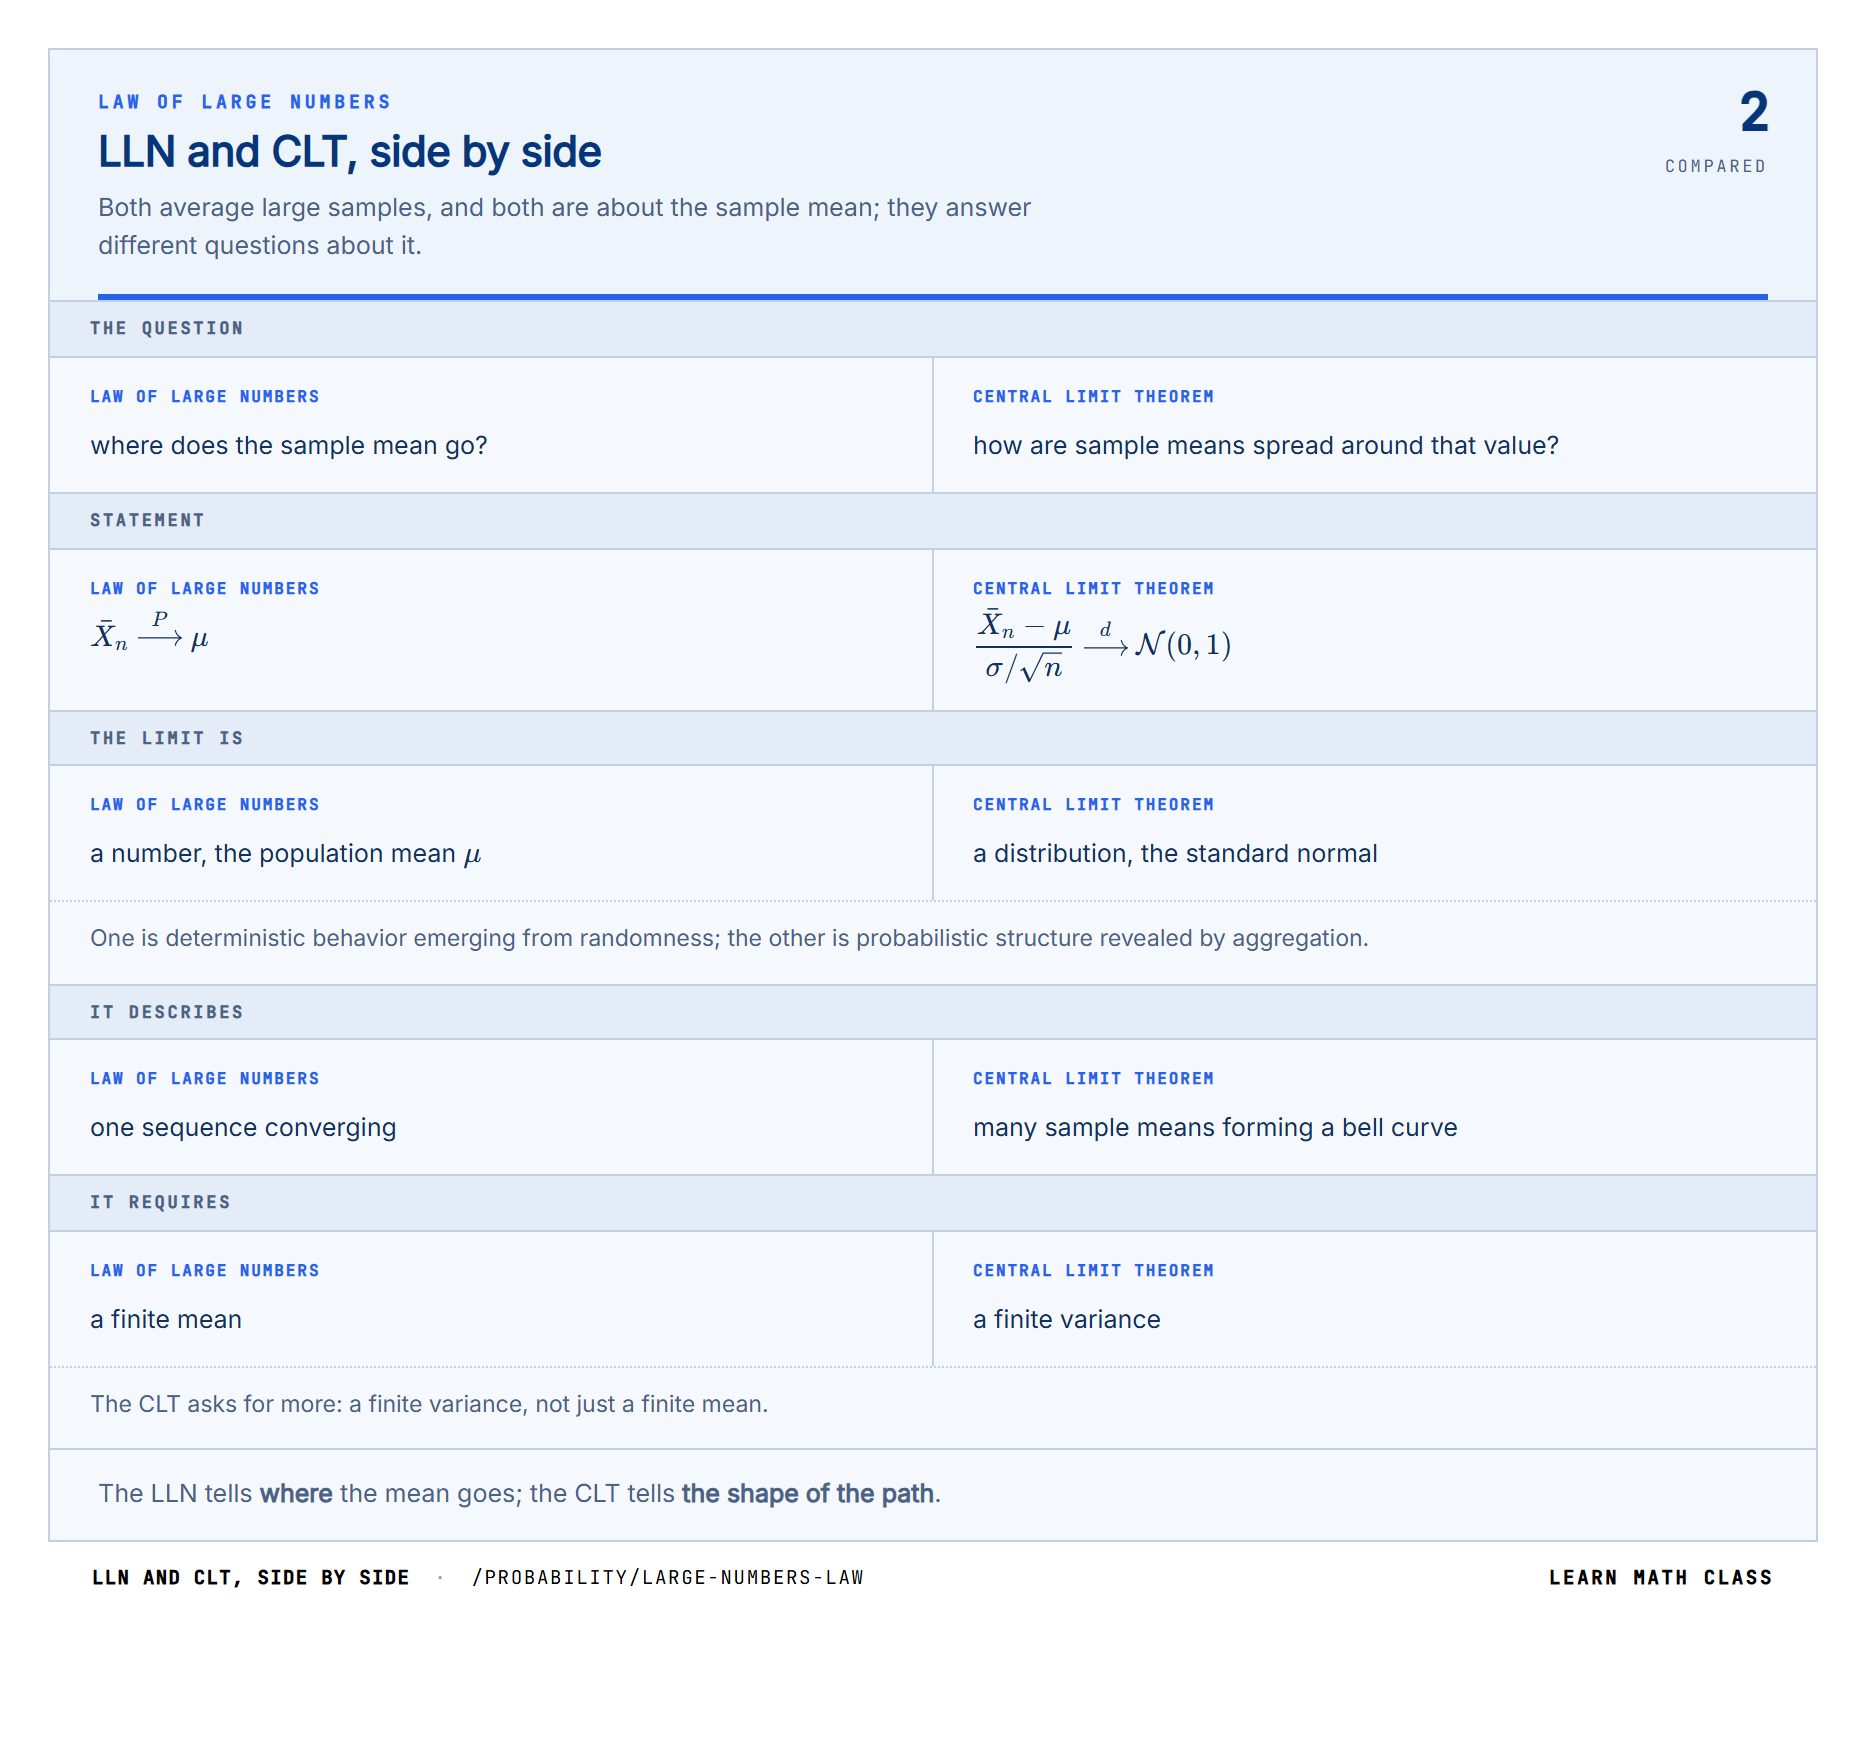
The key differences above, row by row, with the two theorems side by side.
DownloadPNG2×PDF
law of large numbers

LLN and CLT, side by side

Both average large samples, and both are about the sample mean; they answer different questions about it.

2compared
The question
Law of Large Numbers
where does the sample mean go?
Central Limit Theorem
how are sample means spread around that value?
Statement
Law of Large Numbers
Xˉn→Pμ\bar X_n \xrightarrow{P} \mu
Central Limit Theorem
Xˉn−μσ/n→dN(0,1)\dfrac{\bar X_n - \mu}{\sigma / \sqrt{n}} \xrightarrow{d} \mathcal{N}(0,1)
The limit is
Law of Large Numbers
a number, the population mean μ\mu
Central Limit Theorem
a distribution, the standard normal
One is deterministic behavior emerging from randomness; the other is probabilistic structure revealed by aggregation.
It describes
Law of Large Numbers
one sequence converging
Central Limit Theorem
many sample means forming a bell curve
It requires
Law of Large Numbers
a finite mean
Central Limit Theorem
a finite variance
The CLT asks for more: a finite variance, not just a finite mean.
The LLN tells where the mean goes; the CLT tells the shape of the path.
LLN and CLT, side by side·/probability/large-numbers-lawLearn Math Class
Read across any row and the two theorems split the same way: the LLN fixes the destination, and the CLT describes how sample means scatter around it on the way. The scatter is measured by σ/n\sigma / \sqrt{n}, which is why the CLT needs a finite variance while the LLN does not.
Why the law matters is set out next.

Why LLN Is So Important


The Law of Large Numbers is the foundation of statistical estimation and empirical science. It's the reason we trust averages to represent underlying truths.

Without the LLN, we couldn't justify using sample means as estimates of population parameters. The theorem guarantees that larger samples produce more reliable estimates, not as speculation but as mathematical certainty.

Statistical Estimation
Sample means are the most common estimators in statistics. The LLN proves they work: as sample size increases, the estimate converges to the true value. This justifies polls, surveys, clinical trials, and quality control sampling.

Monte Carlo Methods
Simulation-based techniques rely entirely on the LLN. Generate random samples, compute averages, and those averages converge to theoretical values. This enables numerical integration, risk analysis, and computational probability where closed-form solutions don't exist.

Insurance and Risk Management
Individual insurance claims are unpredictable. But portfolios of thousands of policies become remarkably stable. The LLN explains why: aggregate losses converge to expected losses. This makes insurance mathematically viable.

Polling and Survey Research
Surveying 1,000 people can predict the opinions of millions. The LLN guarantees that sample proportions converge to population proportions, enabling representative sampling to work.

Empirical Science
Repeated measurements converge to true values. Experimental averages approach theoretical predictions. The LLN is why replication matters in science—individual experiments may err, but their average reveals truth.

The Law of Large Numbers doesn't just describe probability—it enables the entire enterprise of learning from data. Understanding LLN means understanding why statistics works at all.

Interactive Tools


Explore the Law of Large Numbers through hands-on visualization:

Law of Large Numbers Simulator
Watch a single running mean converge to the expected value in real-time. Choose from different distributions—fair coin, biased coin, die rolls, uniform random numbers—and see how the sample mean stabilizes as observations accumulate. Adjust sample size and animation speed to see convergence unfold at your own pace.

Convergence Visualizer
Track the distance between sample mean and population mean as sample size grows. See how volatility decreases and deviations become rarer. Control the starting point and watch multiple simulation runs to observe the probabilistic nature of convergence.

Distribution Comparison Tool
Compare convergence speed across different distributions. See how uniform, exponential, and heavy-tailed distributions all converge to their means, but at different rates. Understand how distribution shape affects practical convergence speed.

These tools make abstract convergence tangible. The LLN describes behavior "as n approaches infinity"—but these simulators let you see exactly when "large enough" becomes large enough for practical purposes. Understanding comes from watching the process unfold, not just reading the theorem.

Summary


The Law of Large Numbers reveals that randomness becomes predictable through repetition. Individual outcomes remain uncertain, but their average converges to stability.

The theorem doesn't eliminate randomness—it organizes it. Each observation is still random, still variable, still unpredictable. But the average of many observations escapes this chaos and approaches a fixed value with mathematical certainty.

Three core insights define the LLN:
• Averaging reduces variability systematically
• Sample means converge to population means as sample size grows
• This convergence requires only independence, identical distribution, and finite mean

The Law of Large Numbers is why statistics works. It's why we trust sample averages to estimate population parameters. It's why polls can predict elections, why insurance companies stay solvent, why Monte Carlo methods compute probabilities, and why repeated experiments reveal truth.

Understanding the LLN means understanding why data, when collected carefully and aggregated properly, becomes trustworthy. It's the bridge between the random and the reliable, between individual uncertainty and collective certainty.

The theorem shows that chaos, when averaged, becomes order.

Law of Large Numbers at a Glance

The table below condenses the full LLN picture — its core claim, the weak and strong forms, the structural conditions it relies on, its relationship to the Central Limit Theorem, the practical reasons it matters, and the situations in which it fails — into a single quick-reference card.
DownloadPNG2×PDF
Layout
AspectStatementExample / note
Core claimthe sample mean X̄ₙ converges to the population mean μ as n growsfair coin: proportion of heads → 0.5
Weak form (WLLN)limn→∞_{n→∞} P(|X̄ₙ − μ| > ε) = 0 — convergence in probabilitylarge deviations become arbitrarily unlikely
Strong form (SLLN)P(X̄ₙ → μ) = 1 — almost sure convergencethe observed sequence itself converges, not just its probabilities
Required structureindependence, identical distribution, finite meanfinite variance is not required by the WLLN
Relation to CLTLLN names the target μ; CLT describes the shape of fluctuations around itLLN: where we go. CLT: how we get there.
Why it mattersjustifies estimation, polling, Monte Carlo simulation, insurance poolingsample averages are trustworthy precisely because of the LLN
When it failsstrong dependence, mixed distributions, or undefined meanCauchy: no finite mean, no convergence at all
Most common pitfallconfusing "long-run frequency" with "memory" of past outcomesthe gambler's fallacy
Law of Large Numbers at a GlanceLearn Math Class

Skills You Should Learn

Each skill opens its step-by-step method page.
Random variable methods

Law of Large Numbers FAQ

Does a run of heads make tails more likely?

+
No — that is the gambler's fallacy. Independence means the coin has no memory: after ten heads, the next flip is still 50-50. The Law of Large Numbers does not say tails become “due” to balance the record. It says the proportion of heads approaches 0.5 over enough flips, which happens by dilution, not by correction.Read more →

How large does the sample need to be for the Law of Large Numbers to apply?

+
There is no such number. The law is asymptotic: it describes behavior as n → ∞, not at any particular finite n. No sample size guarantees convergence. How quickly the sample mean settles depends on the distribution — skewness, heavy tails and high variance all slow it down. Rules of thumb like n ≥ 30 come from elsewhere, not from this theorem.Read more →

Does convergence mean the sample mean eventually equals the true mean?

+
No. Convergence in probability means the chance of a large deviation shrinks toward zero, not that the gap closes to nothing. For any finite n, the sample mean differs from μ with positive probability. The theorem describes limiting behavior, not finite-sample certainty — there is no point at which the two become equal.Read more →

Are small samples wrong, or just noisy?

+
Noisy. A sample mean from a small sample is an unbiased estimator — it is centered on the true mean, not systematically off it. What small samples have is higher variance: a wider range of plausible values around the right center. The problem is spread, not bias, and the two get conflated constantly.Read more →

Does the number of heads get closer to half the number of flips?

+
No, only the share of heads does. The count HnH_n has variance n4\frac{n}{4}, so its typical distance from n2\frac{n}{2} is n2\frac{\sqrt{n}}{2}: about 55 heads after 100100 flips and 5050 after 10,00010{,}000. The share Hnn\frac{H_n}{n} has standard deviation 12n\frac{1}{2\sqrt{n}}, which falls from 0.050.05 to 0.0050.005 over the same flips. Dividing by nn is the step that makes the gap shrink.Read more →

Does the Law of Large Numbers work for the Cauchy distribution?

+
No. The Cauchy distribution has no finite mean, so the law's finite-mean condition fails and there is no value for the sample mean to settle at. Its tails are so heavy that single huge observations keep dragging the average around however large nn becomes: the average of nn standard Cauchy values is again standard Cauchy, as spread out as one observation. The missing ingredient is the mean, not the variance.Read more →

Can the share of heads fail to converge to one half?

+
Yes, in principle, but with probability zero. A fair coin can land heads forever, and that sequence's share is 11, not 12\frac{1}{2}; infinitely many other sequences miss too. The strong law says all such exceptional sequences together carry probability 00, which is what almost surely means: P(lim⁡n→∞Xˉn=μ)=1P\big(\lim_{n \to \infty} \bar{X}_n = \mu\big) = 1. Probability one is not the same as always.Read more →