Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Central Limit Theorem


Central Limit Theorem (CLT)-Presenting the Idea


Individual random outcomes often look irregular and unpredictable.
Yet, when many such outcomes are combined, a striking regularity begins to appear.

Across experiments, measurements, and simulations, averages tend to form the same familiar bell-shaped pattern — even when the original data are skewed, discrete, or uneven. This recurring behavior is not accidental. It reflects a fundamental mechanism in probability: randomness smooths out when aggregated.

The Central Limit Theorem explains why this happens.
It describes how combining many independent random contributions leads to a stable and universal distribution, forming the mathematical backbone of statistical reasoning, sampling methods, and inference.

Key Terms

Normal Distribution— the limiting distribution in the CLT
Random Variable— the i.i.d. variables being summed
Expected Value— μ=E[Xi]\mu = E[X_i], the mean of each term
Variance— σ2=Var⁡(Xi)\sigma^2 = \operatorname{Var}(X_i), the spread of each term
Standard Deviation— σ\sigma, used in the standardization formula

See All Probability Definitions →


Formal Statement of the Central Limit Theorem

One roll of a fair die is equally likely to show 1, 2, 3, 4, 5 or 6 — a flat pattern. What pattern does the average of several rolls follow?
Each roll on its own stays flat however often the die is thrown. The question is about the average of a handful of rolls, taken again and again.
As more dice are averaged, the averages crowd toward 3.5 and take on a bell shape.
dice averagedpossible averageschance the average is between 3 and 4shape
11, 2, 3, 4, 5, 62/6 ≈ 33%flat
21, 1.5, 2, …, 616/36 ≈ 44%a triangle peaked at 3.5
101, 1.1, 1.2, …, 6about two thirdsa narrow bell around 3.5
Extreme averages need every die to land high, or every die low, which grows rare as the number of dice grows. Middling averages can happen in many ways.
Averages pile up around the true mean in a bell shape, whatever the shape of a single observation.
This result does not depend on the shape of the original distribution.
Only independence, identical distribution, and finite variance are required.
The definition
The central limit theorem says that the average of nn independent, identically distributed observations with finite mean μ\mu and variance σ2\sigma^2 is approximately normal for large nn, centred at μ\mu with spread σn\frac{\sigma}{\sqrt{n}}.

Formal Statement of the Central Limit Theorem

Let X1,X2,…,XnX_1, X_2, \dots, X_n be independent and identically distributed random variables with finite mean μ\mu and finite variance σ2\sigma^2.
Let Xˉn\bar X_n denote their sample mean.
As the sample size nn increases, the standardized sample mean converges in distribution to a normal random variable:
(Xˉn−μ) / (σ/n);→d;N(0,1)\displaystyle (\bar X_n - \mu)\, / \, (\sigma / \sqrt{n}) ;\xrightarrow{d}; \mathcal{N}(0,1)
So the average of many dice is close to a normal distribution centred at 3.53.5, with a spread that shrinks as 1n\frac{1}{\sqrt{n}}.
The theorem is about the distribution of averages, not about single observations.
A single roll never becomes bell-shaped; only the average does. The next section, what the theorem is really describing, puts this in words.
The conditions are not decoration: the observations must be independent, share one distribution, and have finite variance.
When the variance is infinite, averages need not settle into a bell at all. The ingredients are listed one by one in objects involved in the theorem.
The rest of the page covers what the theorem describes, the objects involved, notation, and how it is used.

What the Theorem Is Really Describing


The Central Limit Theorem is not concerned with individual outcomes or single measurements.
Instead, it describes the behavior of the distribution of averages formed from many observations.

THEOREMCentral Limit Theorem
Even when the original random variable has a skewed, irregular, or discrete distribution, the distribution of the sample mean becomes approximately normal once the sample size is sufficiently large.

As the number of observations increases, this distribution moves closer to the familiar bell-shaped curve.

The theorem explains why normal patterns appear so often in aggregated data.
It shows that regularity emerges from the process of averaging itself, largely independent of the original source of randomness.

Objects Involved in the Theorem


The Central Limit Theorem involves several distinct objects, each playing a different role. Keeping these roles separate is essential for correct interpretation.

* Original random variable (XX)
Represents the outcome of a single experiment or measurement, with mean μ\mu and variance σ2\sigma^2.

* Sample (X1,X2,…,XnX_1, X_2, \dots, X_n)
Independent copies of the original random variable, drawn under identical conditions.

* Sample mean (Xˉn\bar X_n)
The average of the sample values,
Xˉn=1n∑i=1nXi\bar X_n = \frac{1}{n}\sum_{i=1}^n X_i,
which is itself a random variable.

* Limiting normal distribution
The normal distribution that the standardized sample mean approaches in distribution as nn increases.

The theorem does not describe how individual observations behave.
It describes how the distribution of the sample mean behaves as the sample size grows. The table below collects these objects with their notation and the role each plays in the theorem.
Object Symbol Role in the theorem
Original random variable X a single experiment or measurement with mean μ and variance σ²
Sample X₁, X₂, …, Xₙ n independent copies of X drawn under identical conditions
Sample mean X̄ₙ the average (X₁ + … + Xₙ) ⁄ n; itself a random variable
Limiting normal distribution N(0, 1) the distribution that the standardized sample mean approaches as n → ∞

Central Limit Theorem Notation

Notation

Central Limit Theorem Notation

The theorem's statement packs three layers of marks into one line: an average that is itself a random variable, an arrow that carries convergence of distributions rather than numbers, and a standardization whose denominator earned its own name. Objects Involved in the Theorem above sorts the roles; this section fixes the marks. All of them are catalogued among the probability symbols.
X1,…,XnX_1, \dots, X_n, the capital/lowercase split and the i.i.d. declaration come from random variable and independence notation; μ\mu and σ2\sigma^2 from expected value and variance notation; the family form N(μ,σ2)N(\mu, \sigma^2) from distribution notation; the summation sign from sequence notation.
Xˉn\bar{X}_n, SnS_n
X-bar-sub-n — the sample mean of n observations; S-sub-n — their sum
The data-average bar lifted to a random variable: capital XX under the bar means the average is itself random, and the subscript nn keeps the sample size in view — the whole theorem is about what happens as that subscript grows. The partial sum Sn=∑i=1nXiS_n = \sum_{i=1}^n X_i is its sibling spelling, with Xˉn=Sn/n\bar{X}_n = S_n / n.
CasesThe theorem wears both: the mean form concentrates while the sum form spreads — SnS_n is approximately N(nμ, nσ2)N(n\mu,\, n\sigma^2) while Xˉn\bar{X}_n is approximately N(μ, σ2/n)N(\mu,\, \sigma^2/n) — same statement, rescaled; texts pick whichever makes their application's arithmetic cleaner.
Do not confusexˉ\bar{x} the number. Lowercase xˉ\bar{x} is one computed average from one data set; capital Xˉn\bar{X}_n is the random variable ranging over every sample that might have been drawn — the capital/lowercase convention doing its most important job on this page.
→d\xrightarrow{d}
converges in distribution, as n grows
An arrow with a rider: the dd says what converges is the distribution — the histogram's shape — not the values themselves. It is the moving version of the equality in distribution mark =d\overset{d}{=}: one compares two laws, the other tracks a sequence of laws approaching a limit.
Also written→D\xrightarrow{D} with a capital rider; ⇒\Rightarrow — the bare double arrow of weak convergence in advanced probability texts, no rider at all; some sources write the limit variable over the arrow instead.
Do not confuseThe plain limit arrow. Xˉn→μ\bar{X}_n \to \mu (the law of large numbers' statement) drives values to a constant; →d\xrightarrow{d} preserves a whole spread-out limit shape — reading the CLT's arrow as a plain limit collapses the bell curve the theorem exists to deliver.
Zn=Xˉn−μσ/nZ_n = \dfrac{\bar{X}_n - \mu}{\sigma / \sqrt{n}}, N(0,1)\mathcal{N}(0,1)
the standardized sample mean — and the standard normal it approaches
Subtract the center, divide by the spread: the numerator recenters at zero, and the denominator σ/n\sigma/\sqrt{n} — the standard error of the mean, a mark with its own name — rescales to unit spread, which is why the limit's slots hold (0,1)(0, 1). Why Scaling by the Square Root Matters below tells the story behind the n\sqrt{n}.
CasesCalligraphic N\mathcal{N} and plain NN name the same family — a typographic preference, not a distinction; for finite nn the exact arrow statement is often traded for the approximation idiom, Xˉn≈N(μ,σ2/n)\bar{X}_n \approx N(\mu, \sigma^2/n), precise enough for practice and silent about the limit.
Do not confuseThe standard error with the variance slot. σ/n\sigma/\sqrt{n} is a standard deviation while σ2/n\sigma^2/n is a variance — the same second-slot convention trap as N(μ,σ2)N(\mu, \sigma^2) vs N(μ,σ)N(\mu, \sigma), and mixing them mis-scales every interval built on the theorem.
DownloadPNG2×PDF
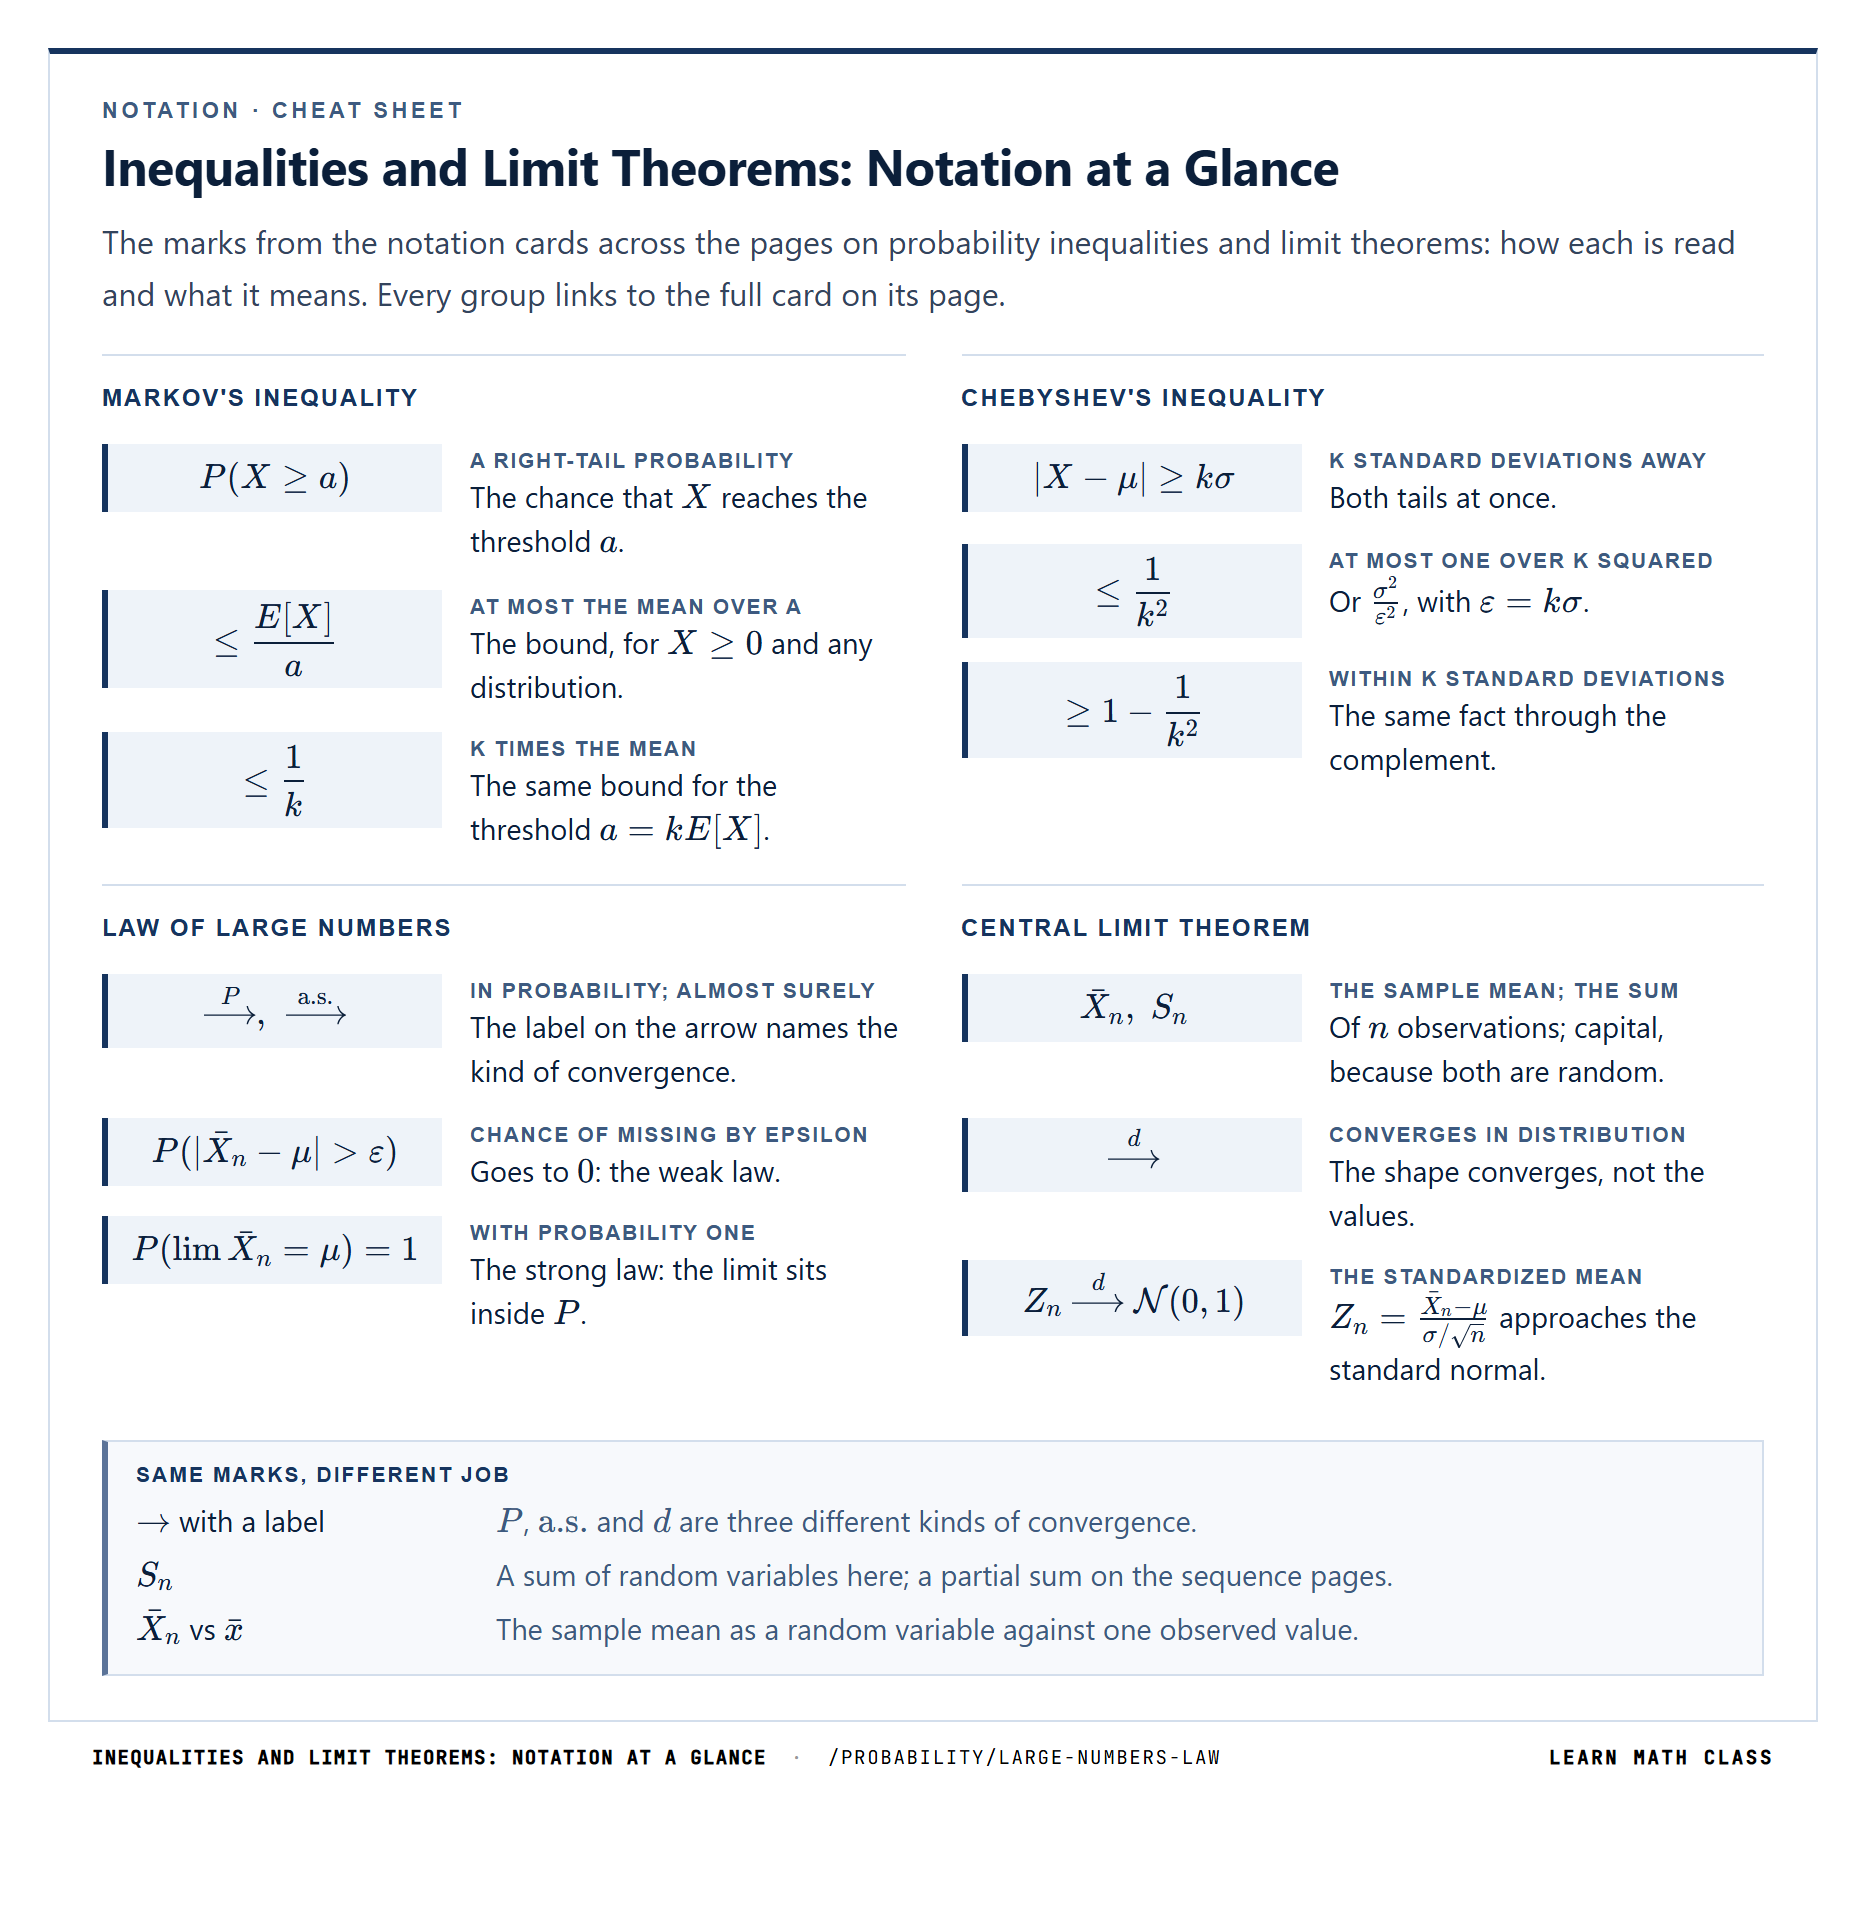
Notation · Cheat sheet
Inequalities and Limit Theorems: Notation at a Glance
The marks from the notation cards across the pages on probability inequalities and limit theorems: how each is read and what it means. Every group links to the full card on its page.
Markov's inequality
P(X≥a)P(X \ge a)
a right-tail probability
The chance that XX reaches the threshold aa.
≤E[X]a\le \dfrac{E[X]}{a}
at most the mean over a
The bound, for X≥0X \ge 0 and any distribution.
≤1k\le \dfrac{1}{k}
k times the mean
The same bound for the threshold a=kE[X]a = kE[X].
Chebyshev's inequality
∣X−μ∣≥kσ|X - \mu| \ge k\sigma
k standard deviations away
Both tails at once.
≤1k2\le \dfrac{1}{k^2}
at most one over k squared
Or σ2ε2\frac{\sigma^2}{\varepsilon^2}, with ε=kσ\varepsilon = k\sigma.
≥1−1k2\ge 1 - \dfrac{1}{k^2}
within k standard deviations
The same fact through the complement.
Law of large numbers
→P,  →a.s.\xrightarrow{P}, \; \xrightarrow{\text{a.s.}}
in probability; almost surely
The label on the arrow names the kind of convergence.
P(∣Xˉn−μ∣>ε)P(|\bar{X}_n - \mu| > \varepsilon)
chance of missing by epsilon
Goes to 00: the weak law.
P(lim⁡Xˉn=μ)=1P(\lim \bar{X}_n = \mu) = 1
with probability one
The strong law: the limit sits inside PP.
Central limit theoremThis page
Xˉn,  Sn\bar{X}_n, \; S_n
the sample mean; the sum
Of nn observations; capital, because both are random.
→d\xrightarrow{d}
converges in distribution
The shape converges, not the values.
Zn→dN(0,1)Z_n \xrightarrow{d} \mathcal{N}(0,1)
the standardized mean
Zn=Xˉn−μσ/nZ_n = \frac{\bar{X}_n - \mu}{\sigma/\sqrt{n}} approaches the standard normal.
Same marks, different job
→\to with a labelPP, a.s.\text{a.s.} and dd are three different kinds of convergence.
SnS_nA sum of random variables here; a partial sum on the sequence pages.
Xˉn\bar{X}_n vs xˉ\bar{x}The sample mean as a random variable against one observed value.
Inequalities and Limit Theorems: Notation at a Glance·/probability/large-numbers-lawLearn Math Class
Pitfall: Multiplying σ by n for a sum
Giving the total of 36 packages, each with μ=5\mu = 5 kg and σ=2\sigma = 2 kg, the spread 36⋅2=7236 \cdot 2 = 72 kg adds standard deviations and gives P(S36>200)≈0.39P(S_{36} > 200) \approx 0.39. Variances add: 36⋅22=14436 \cdot 2^2 = 144, so the spread is 144=12\sqrt{144} = 12 kg and the probability is about 0.0480.048.

Many applied questions ask about a total rather than an average: the combined weight of a shipment, the total waiting time of a day's customers, the total claims an insurer pays in a year. The sum Sn=X1+⋯+XnS_n = X_1 + \dots + X_n is the sample mean multiplied by nn, so the theorem covers it under the same conditions, and its distribution is approximately normal as well, centered at nμn\mu.

The two forms move in opposite directions as nn grows. The mean concentrates around μ\mu, while the sum spreads out, because every new observation brings its own variability into the total.
0.0000.0800.1600.2400.3200.400-4-3-2-101234Value (k)Density f(x)E[X]=0.00
The standard normal density, the limit shape of averages

The bell curve is the destination of the theorem: whatever shape the original distribution has, the standardised sample mean approaches this density as the sample size grows. Its centre is the population mean and its spread shrinks with the square root of the sample size. Compare the bell with the skewed and flat shapes it emerges from on the distribution explorer.

The scaling behind that shrinking spread is the subject of the next section.

Visual Intuition


The Central Limit Theorem is best understood visually.
Rather than focusing on formulas, this section shows how distributions change as averaging takes place.

* Sample means for small sample sizes
When the sample size is small, the distribution of the sample mean still reflects the shape of the original distribution. Skewness, discreteness, or irregular structure may remain visible.

* Increasing the sample size
As the sample size grows, the distribution of the sample mean becomes smoother and more symmetric. Random fluctuations are reduced, and a bell-shaped form begins to emerge.

* Convergence toward a normal shape
For sufficiently large samples, the histogram of sample means closely resembles a normal distribution, regardless of the original distribution's shape.

* Different starting distributions, same outcome
Whether the original data are uniform, skewed, or discrete, the averaging process drives the sample mean toward the same normal pattern.

Fact: Twelve flat numbers make a bell
Adding 12 random numbers from [0,1][0, 1] and subtracting 66 was once a standard way for computers to make normal values: each number has variance 112\frac{1}{12}, so the total has variance exactly 11. The result can never pass ±6\pm 6, yet every probability P(Z≤z)P(Z \le z) it gives is within 0.0030.003 of the bell's.

These visuals highlight the core message of the theorem:
it is the act of averaging that produces normality, not the nature of the original data.

A flat starting distribution shows the effect at its plainest. A number drawn uniformly from [0,1][0, 1] has no peak at all: every value in the interval is equally likely. The sum of two such numbers is already triangular, most likely near 11, because a total near the middle can come from many pairs, while a total near 00 or 22 needs both numbers near the same end. Each further term rounds the corners of the shape a little more.
Density of the mean of n exponential observations for n = 1, 4 and 30: skewed at n = 1, a narrowing bell around 1 by n = 30x̄y12312μ = 1n = 1n = 4n = 30original data: skewedmeans of 30: a bellspread shrinks like 1/√nAveraging a skewed variable: the sample mean turns bell-shaped
Means of a skewed variable becoming a bell

Start from a strongly skewed variable: an exponential with mean 1 (amber, n = 1). The blue curve is the distribution of the average of 4 such observations: still lopsided, but with a hump. The navy curve is the average of 30: nearly symmetric, bell-shaped and centred on the mean 1, and much narrower. The data never change shape; it is the distribution of the sample mean that turns normal, with spread shrinking like 1/√n.

For a skewed start like this one, n = 30 is a reasonable size; a symmetric start needs far fewer.
Pitfall: Using the standard error for single values
Reading the narrow bell of means as the spread of single values: for the exponential above, with μ=σ=1\mu = \sigma = 1, about 95% of means of 30 lie within 1±2301 \pm \frac{2}{\sqrt{30}}, from 0.630.63 to 1.371.37. Only about 28% of single observations do: e−0.63−e−1.37≈0.28e^{-0.63} - e^{-1.37} \approx 0.28.

The figure holds two different spreads. The amber curve is the distribution of a single observation, and it keeps the same shape and width whatever the sample size. The navy curve is the distribution of the average of 30 observations, and it narrows as the sample grows.

Every probability question built on the theorem refers to one of these curves. A question about one waiting time or one measurement is answered from the original distribution; a question about the average of a sample is answered from the distribution of the sample mean.

Why Scaling by n\sqrt{n} Matters


As more observations are averaged together, the variability of the sample mean naturally decreases. Larger samples produce more stable averages, with less random fluctuation from one sample to another.

If we looked at the raw sample mean alone, this shrinking variability would eventually hide all randomness. Scaling by n\sqrt{n} counteracts this effect by keeping the spread of the distribution at a visible, meaningful scale.

Pitfall: Standardizing the mean with σ
Finding P(Xˉ25>106)P(\bar X_{25} > 106) for μ=100\mu = 100, σ=15\sigma = 15 with z=106−10015=0.4z = \frac{106 - 100}{15} = 0.4 uses the spread of one observation and gives about 0.340.34. The mean's spread is 1525=3\frac{15}{\sqrt{25}} = 3, so z=2z = 2 and the probability is about 0.0230.023.

The factor σ/n\sigma / \sqrt{n} reflects how uncertainty decreases with sample size. It captures the rate at which averaging reduces variability and explains why this term appears in the standardized form of the theorem.

This scaling does not change the shape of the distribution.
It allows the limiting normal behavior to be observed and compared across different sample sizes.

The spread of an average shrinks like σn\frac{\sigma}{\sqrt{n}}, and dividing by exactly that keeps the bell from collapsing to a point.

When the Central Limit Theorem Applies


The Central Limit Theorem does not apply automatically in every situation.
Its validity depends on several key conditions.

* Independence
The observations must not influence one another. Dependence can distort the behavior of averages and prevent normal convergence.

* Identical distribution
Each observation must come from the same underlying distribution. Mixing different distributions can break the aggregation effect described by the theorem.

* Finite mean
The expected value of the original random variable must exist. Without a well-defined mean, averaging loses its stabilizing effect.

* Finite variance
The variability of the original distribution must be finite. Extremely heavy-tailed distributions can violate this requirement.

When these conditions fail, the conclusion of the theorem may no longer hold.
In particular, heavy-tailed or strongly dependent data can produce averages that do not resemble a normal distribution, even for large sample sizes. The table below pairs each condition with what it ensures and what tends to break when it is violated.
Condition What it ensures What breaks without it
Independence observations don't influence one another, so averaging behaves predictably dependence distorts the distribution of the average and prevents normal convergence
Identical distribution a single source of randomness is being aggregated mixing different distributions breaks the aggregation effect
Finite mean averages have a well-defined center to stabilize around no stable center exists; averaging loses its stabilizing effect
Finite variance spread is bounded enough for a normal limit to emerge heavy-tailed distributions can produce non-normal limits even for large n

Common Misconceptions


The Central Limit Theorem is often misunderstood. The following clarifications address the most common errors.

* "The data become normal."
The theorem does not claim that the original data change their distribution. Only the distribution of the sample mean is involved.

* "The theorem works for any small sample."
There is no universal sample size at which the approximation becomes accurate. The required size depends on the shape of the original distribution.

* "The theorem is only about sums."
While sums appear in the mathematics, the meaningful object is the average. The scaling by n\sqrt{n} is what reveals the limiting behavior.

* "Normal data are required."
Normality of the original distribution is not an assumption. Skewed, discrete, and irregular distributions can all satisfy the theorem's conditions.

The table below sets each misconception alongside the corresponding correct view so the contrasts are easy to scan.
Common misconception What is actually true
"The data become normal." only the distribution of the sample mean approaches normal; the original data are unchanged
"The theorem works for any small sample." the required sample size depends on the shape of the original distribution
"The theorem is only about sums." sums appear in the math, but the meaningful object is the average — the scaling by √n is what reveals the limit
"Normal data are required." skewed, discrete, or irregular distributions all satisfy the theorem when the four conditions hold

The misconceptions above concern what the theorem says. Three more errors appear when it is used in a calculation, and each one comes from taking the wrong spread. Each is marked where it happens in the sections above.

Multiplying σ by n for a sum

A question asks about the total of nn observations, and the spread of the total is taken as nn times the spread of one observation. The standard deviations are added as if they were lengths laid end to end.

Wrong working: for 36 independent packages, each with mean weight 55 kg and standard deviation 22 kg, the total S36S_{36} has mean 36⋅5=18036 \cdot 5 = 180 kg and
σS=36⋅2=72,z=200−18072≈0.28,P(S36>200)≈0.39\sigma_{S} = 36 \cdot 2 = 72, \quad z = \frac{200 - 180}{72} \approx 0.28, \quad P(S_{36} > 200) \approx 0.39


Right working: the variances of independent terms add, so the variance of the sum is nσ2n\sigma^2.
Var⁡(S36)=36⋅22=144,σS=144=12,z=200−18012≈1.67,P(S36>200)≈0.048\operatorname{Var}(S_{36}) = 36 \cdot 2^2 = 144, \quad \sigma_{S} = \sqrt{144} = 12, \quad z = \frac{200 - 180}{12} \approx 1.67, \quad P(S_{36} > 200) \approx 0.048


Why it happens: the mean of the sum is nμn\mu, so multiplying the standard deviation by nn looks like the same step. But independent deviations partly cancel, and the spread of the total grows like n\sqrt{n}, not like nn.

How to check: compare the spread with the mean. With spread nσn\sigma, the total would be exactly as uncertain relative to its mean, 72180=0.4\frac{72}{180} = 0.4, as a single package is, 25=0.4\frac{2}{5} = 0.4, and adding packages would steady nothing. The correct spread gives 12180≈0.067\frac{12}{180} \approx 0.067, which keeps shrinking as nn grows.

Using the standard error for single values

The spread σn\frac{\sigma}{\sqrt{n}} of the sample mean is used to describe individual observations, as though the narrow bell of averages showed where single values fall.

Wrong working: for the exponential variable with μ=σ=1\mu = \sigma = 1 from the Visual Intuition figure, with n=30n = 30,
σ30≈0.183,1±2⋅0.183≈0.63 to 1.37\frac{\sigma}{\sqrt{30}} \approx 0.183, \quad 1 \pm 2 \cdot 0.183 \approx 0.63 \text{ to } 1.37

and this interval is read as holding about 95% of single observations.

Right working: about 95% of sample means of 30 fall in that interval, but single observations keep their own skewed distribution. For one observation,
P(0.63<X<1.37)=e−0.63−e−1.37≈0.53−0.25=0.28P(0.63 < X < 1.37) = e^{-0.63} - e^{-1.37} \approx 0.53 - 0.25 = 0.28


Why it happens: both spreads come from the same σ\sigma, and the standard error is the quantity written in the theorem's formula, so it is the one at hand.

How to check: the spread of single values does not depend on nn. If an interval meant for single observations gets narrower when the sample size grows, it is describing the mean, not the observations.

Standardizing the mean with σ

A probability about the sample mean is found by standardizing with σ\sigma, the spread of one observation, instead of with the standard error σn\frac{\sigma}{\sqrt{n}}.

Wrong working: for μ=100\mu = 100, σ=15\sigma = 15 and n=25n = 25,
z=106−10015=0.4,P(Xˉ25>106)≈0.34z = \frac{106 - 100}{15} = 0.4, \quad P(\bar X_{25} > 106) \approx 0.34


Right working: the spread of the mean is the standard error.
σn=1525=3,z=106−1003=2,P(Xˉ25>106)≈0.023\frac{\sigma}{\sqrt{n}} = \frac{15}{\sqrt{25}} = 3, \quad z = \frac{106 - 100}{3} = 2, \quad P(\bar X_{25} > 106) \approx 0.023


Why it happens: the z-score x−μσ\frac{x - \mu}{\sigma} is first learned for single values, and the same pattern is reused for the mean with the denominator left unchanged.

How to check: the answer must depend on nn. With σ\sigma in the denominator the probability is 0.340.34 for a sample of 25 and for a sample of 2,500 alike, although the mean of a larger sample strays less from μ\mu.

CLT vs Law of Large Numbers


    The Central Limit Theorem and the Law of Large Numbers are often confused because both involve sample means and large sample sizes. However, they answer fundamentally different questions.

    The Law of Large Numbers (LLN) tells us that as we collect more observations, the sample mean gets closer and closer to the true population mean. This is a statement about convergence to a specific value. If you flip a fair coin many times, the proportion of heads approaches 0.5—that's the LLN at work.

    Fact: The bell curve began with coin tosses
    In 1733 Abraham de Moivre found that the chance of xx heads more or fewer than n2\frac{n}{2} in nn fair tosses falls off like e−2x2/ne^{-2x^2/n}: the bell curve, first met as a shortcut for counting heads. It was the first central limit theorem, 76 years before Gauss used the curve for measurement errors.

    The Central Limit Theorem (CLT) tells us something else entirely: it describes the shape of the distribution that sample means follow. Even if individual observations are far from normal, the CLT guarantees that the distribution of sample means will be approximately normal, centered at the population mean, with spread determined by the sample size.

    In short:
  • LLN → the sample mean converges to a number (deterministic behavior)
  • CLT → the sample mean follows a distribution (probabilistic behavior)

  • Both involve averaging, both require large samples, but they reveal different aspects of how randomness behaves at scale. The LLN tells us where the mean goes; the CLT tells us how it gets there. The table below sets the two theorems side by side across the aspects that most often get confused.
Aspect Law of Large Numbers Central Limit Theorem
What it describes convergence of the sample mean to a single value the shape of the distribution the sample mean follows
Type of statement convergence of the mean to the single number μ distributional limit
Target the population mean μ the standard normal distribution N(0, 1) after standardizing
Scaling none — the raw sample mean converges divide by σ ⁄ √n to keep variability visible
Question answered where does the sample mean go? how does it get there?

Why CLT Is So Important


The Central Limit Theorem is arguably the most important result in probability and statistics. It's the reason statistical inference works at all.

Without the CLT, we couldn't construct confidence intervals or perform hypothesis tests. These methods rely on knowing the distribution of sample statistics—and the CLT tells us that distribution is approximately normal, regardless of the underlying data. This universality is extraordinary.

The theorem also explains why the normal distribution appears everywhere in nature and science. Measurement errors, biological traits, financial returns—many phenomena involve summing or averaging independent factors, which is exactly the setup where the CLT applies.

In practical terms, the CLT allows researchers to:

• Make probability statements about sample means
• Quantify uncertainty using standard errors
• Use z-scores and t-statistics confidently
• Apply parametric methods even when data aren't perfectly normal

Perhaps most remarkably, the CLT provides a bridge from probability theory to applied statistics. It transforms abstract mathematical results into usable tools for real-world inference. When you see a confidence interval or a p-value, you're seeing the CLT at work—it's the invisible foundation beneath nearly all of statistical practice.

Interactive Tools


Explore the Central Limit Theorem through hands-on visualization:

Central Limit Theorem Simulator
Watch how sample means from any distribution converge to normality. Adjust sample size, number of samples, and choose from uniform, exponential, or binomial distributions. See the histogram transform in real-time as n increases—it's the most direct way to understand what the CLT actually claims.

Distribution Explorer
Compare original distributions with their sampling distributions side-by-side. Visualize the exact relationship between population shape and the distribution of sample means. Perfect for seeing why the CLT works across wildly different starting points.

Sampling Visualizer
Generate random samples and track how sample means behave. Control independence, sample size, and repetition count. Watch individual samples scatter, then observe the emergent bell curve as you accumulate hundreds or thousands of trials.

These tools make abstract convergence tangible. The CLT describes behavior "as n approaches infinity"—but these simulators let you see exactly when "large enough" becomes large enough for practical purposes. Understanding comes from seeing the process unfold, not just reading the theorem.
Summary


The Central Limit Theorem reveals a profound pattern in randomness: when we average independent observations, the result becomes predictable, regardless of how irregular the original data appear.

The theorem doesn't require normality in the source data. It doesn't matter if observations come from uniform distributions, exponential distributions, or discrete jumps—the distribution of sample means will approach a normal shape as sample size increases.

This transformation happens through aggregation. Individual values may be chaotic, but their average converges to stability. The randomness doesn't disappear—it reorganizes into a predictable form.

Three core insights define the CLT:
• Averaging smooths randomness into regular patterns
• The normal distribution emerges universally from aggregation
• Probability becomes predictable at scale

The Central Limit Theorem is why statistical inference works. It's why we can quantify uncertainty, build confidence intervals, and make probability statements about sample statistics. It connects the irregular world of individual observations to the ordered world of statistical theory.

Understanding the CLT means understanding why chaos, when averaged, becomes cosmos.

Central Limit Theorem FAQ

Does the Central Limit Theorem require normal data?

+
No — that is the point of it. The original distribution can be skewed, discrete, uniform, exponential or thoroughly irregular. What the theorem requires is independence, identical distribution, a finite mean and a finite variance. Normality is the conclusion about sample means, never an assumption about the data.Read more →

Does the Central Limit Theorem make my data normal?

+
No. Nothing about the data changes — the observations keep whatever distribution they always had. What becomes approximately normal is the distribution of the sample mean, which is a different object: it describes the spread of averages across all samples you might have drawn, not the spread of values within one sample.Read more →

How large does n need to be for the Central Limit Theorem to work?

+
There is no universal number. How fast the approximation improves depends on the shape of the original distribution: a mildly skewed one settles quickly, a heavy-tailed one may need thousands. The familiar n ≥ 30 is a rule of thumb for moderately behaved distributions, not a result the theorem provides.Read more →

Is the standard error σ/√n or σ²/n?

+
σ/√n. The standard error is a standard deviation, so it carries the same units as the data; σ²/n is the corresponding variance. They differ by a square root, and swapping them mis-scales every confidence interval and test statistic built on the theorem. It is the same second-slot trap as N(μ, σ²) versus N(μ, σ).Read more →

What does the arrow in convergence in distribution mean?

+
The d above the arrow says that what converges is the distribution — the shape of the histogram — not the values themselves. That distinguishes it from the plain limit arrow of the law of large numbers, which drives the sample mean to a single constant. Convergence in distribution preserves a whole spread-out limit shape.Read more →

How do you use the Central Limit Theorem for a sum instead of an average?

+
Treat the total SnS_n as approximately N(nμ, nσ2)N(n\mu,\, n\sigma^2): the means add and so do the variances, so the spread is σn\sigma\sqrt{n}, not nσn\sigma. For 36 packages with μ=5\mu = 5 kg and σ=2\sigma = 2 kg, the total has mean 180180 kg and spread 144=12\sqrt{144} = 12 kg, giving P(S36>200)≈0.048P(S_{36} > 200) \approx 0.048. Taking the spread as 36⋅2=7236 \cdot 2 = 72 kg gives about 0.390.39 instead.Read more →

Is the standard error the spread of single observations?

+
No, it is the spread of the sample mean. Single values keep the spread σ\sigma of the original distribution whatever the sample size. For the exponential with μ=σ=1\mu = \sigma = 1 on this page, about 95% of means of 30 fall between 0.630.63 and 1.371.37, yet only about 28% of single observations do: e−0.63−e−1.37≈0.28e^{-0.63} - e^{-1.37} \approx 0.28. An interval that narrows as nn grows is describing the mean.Read more →

Why does adding 12 uniform random numbers give a normal value?

+
Because the sum is already close to normal, and the numbers 12 and 6 standardize it. Each draw from [0,1][0, 1] has mean 12\frac{1}{2} and variance 112\frac{1}{12}, so the total of 12 has mean 66 and variance exactly 11; subtracting 66 centres it at 00. The result can never pass ±6\pm 6, so it is not exactly normal, but every probability P(Z≤z)P(Z \le z) it gives is within 0.0030.003 of the bell's.Read more →