Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Joint Probability


When More Than One Random Variable Matters


Joint probability appears whenever more than one outcome matters at the same time. Real situations often involve several random quantities unfolding together—events happening simultaneously, measurements taken jointly, or variables interacting within the same scenario.

Because of this, probability must describe not only individual outcomes but the combined possibilities they create. Joint probability provides that structure: it represents how outcomes coexist, how variables relate, and how multivariate behaviour is organized.

The sections below outline how joint probability is represented, how it connects to marginals and conditionals, and how it forms the foundation for analysing relationships between random variables.

Key Terms

Bivariate Random Variable— a pair (X,Y)(X, Y) considered jointly
N-Variate Random Variables— a vector (X1,…,Xn)(X_1, \ldots, X_n) of random variables
Joint PMF— pX,Y(x,y)=P(X=x,Y=y)p_{X,Y}(x,y) = P(X = x, Y = y)
Joint PDF— fX,Y(x,y)f_{X,Y}(x,y), joint density for continuous variables
Joint CDF— FX,Y(x,y)=P(X≤x,Y≤y)F_{X,Y}(x,y) = P(X \leq x, Y \leq y)
Marginal Distribution— distribution of one variable from a joint distribution
Conditional Probability— used to derive conditional distributions from joint ones
Independent Random Variables— joint distribution factorizes into marginals

See All Probability Definitions →


Definition and Meaning of Joint Probability

A survey records two facts about each person: whether they smoke, and whether they exercise.
The share of smokers and the share of people who exercise each describe one fact on its own. Neither says how often the two facts come together.
A table of both facts at once gives the probability of every combination.
exercisesdoes not exercisetotal
smoker0.100.200.30
non-smoker0.500.200.70
total0.600.401
The entry 0.100.10 is the probability that a person both smokes and exercises. The totals at the edges recover each fact on its own.
Joint probability looks at the whole outcome, not at one part of it.
This estimates the likelihood of combinations rather than isolated outcomes. When we ask "what is the chance that both A happens and B happens together," we are asking about joint probability. It shows how different outcomes line up within the same situation and how they naturally occur side by side.
In simple terms, it is a way to look at the whole outcome, and it is the first place where any kind of relationship between variables becomes visible.
The definition
The joint probability of events AA and BB is the probability that both occur, P(A∩B)P(A \cap B); for random variables, it is the probability that they take given values together.
Joint probability measures the likelihood that two or more events occur simultaneously and that multiple random variables take specific values at the same time.
So P(smoker∩exercises)=0.10P(\text{smoker} \cap \text{exercises}) = 0.10 in the survey above.
Joint probabilities show whether outcomes move together.
Joint probability also captures how random quantities behave together, whether their outcomes depend on each other or not, and how their joint behavior forms patterns that cannot be seen by looking at each variable alone. This is the point where dependence and independence start to show up: joint probability reveals whether outcomes tend to move together, avoid each other, or behave completely separately.
Here 0.30×0.60=0.180.30 \times 0.60 = 0.18, but the joint probability is only 0.100.10: smokers exercise less often than everyone else.
The totals at the edges do not determine the entries inside.
Many different tables share the totals 0.300.30 and 0.600.60; the joint entries carry information that the separate probabilities lack. The totals are the subject of marginal probability.
The rest of the page covers notation, joint probability tables, ways to calculate joint probability, marginal probability, independence, properties, conditional probability, joint distributions, why joint probability matters, common mistakes and related concepts.

Joint Probability Notation

Notation

Joint Probability Notation

Joint probability's marks are about reading several names inside one parenthesis: what the comma is doing there, which subscripts say who survived, and how to tell from the letters alone whether an expression holds the whole two-variable picture or only a shadow of it. All of them are catalogued among the probability symbols.
The event comma P(A,B)P(A, B) and the joint P(A∩B)P(A \cap B) come from conditional probability notation; the capital/lowercase split XX vs xx from random variable notation; pp vs ff and FF from the probability function and CDF notation; the coordinate pair (x,y)(x, y) and the plane R2\mathbb{R}^2 from vector notation.
P(X=x, Y=y)P(X = x,\, Y = y)
the probability that X equals x and Y equals y
The comma is a quiet ∩\cap: each equality names an event, and the comma intersects them. With random variables the comma form is not an alternative spelling but the standard one — the intersection sign all but disappears once two or more variables share the parenthesis.
CasesMore variables simply extend the list, P(X=x,Y=y,Z=z)P(X = x, Y = y, Z = z); events and variables mix freely on the same comma, P(A, X=x)P(A,\, X = x); the fully compressed P(x,y)P(x, y) drops the capitals and keeps only the values, readable because the lowercase letters advertise whose values they are.
Do not confuseThe ordered pair. The same comma builds the point (x,y)(x, y) in the plane, so P(x,y)P(x, y) can misread as "P applied to a point" — it is an intersection of two events, not a function evaluated at coordinates.
p(x,y)p(x, y), fX,Y(x,y)f_{X,Y}(x, y)
the joint mass function — the joint density
The one-variable split between mass pp and density ff carries over unchanged from the probability function; what is new is the argument list. Two names inside the parenthesis declare a function over pairs — a table of cells in the discrete case, a surface over the plane in the continuous one.
CasesThe subscript pair fX,Yf_{X,Y} names exactly which variables the function describes — bookkeeping that becomes load-bearing the moment marginals enter and fXf_X, fYf_Y and fX,Yf_{X,Y} circulate in the same computation; when only one joint function is in play, the bare f(x,y)f(x, y) is standard.
Do not confuseA product. fX,Y(x,y)f_{X,Y}(x, y) does not split into fX(x) fY(y)f_X(x)\,f_Y(y) in general — when it does, that factorization is independence, and assuming the split is precisely the error Common Mistakes below warns against.
pX(x)=∑yp(x,y)p_X(x) = \sum_y p(x, y)
the marginal of X: sum the joint over every value of y
Marginalization: collapse the joint by adding up everything the other variable can do. The surviving variable is named in the subscript; the summed-away one appears only under the ∑\sum. For densities the sum becomes an integral, fX(x)=∫fX,Y(x,y) dyf_X(x) = \int f_{X,Y}(x, y)\,dy.
Also writtenThe name is literal: in a contingency table these are the row and column totals written in the table's margins — the layout Contingency Tables above draws — and the notation inherited the word from the printed page.
Do not confuseThe conditional. pX(x)p_X(x) averages over the other variable while p(x∣y)p(x \mid y) pins it to one value — in a table, a row total versus a single cell divided by its column total; mixing the two is the table-reading error Common Mistakes below lists.
F(x,y)=P(X≤x, Y≤y)F(x, y) = P(X \le x,\, Y \le y)
the joint CDF: both variables at or below their thresholds
CDF notation with the comma spliced in: one accumulated probability over the quarter-plane south-west of (x,y)(x, y). Capital FF keeps its accumulate-and-bound role; the argument list keeps the comma's intersection reading.
CasesProbabilities of rectangles come out by inclusion–exclusion on corner values, F(b,d)−F(a,d)−F(b,c)+F(a,c)F(b, d) - F(a, d) - F(b, c) + F(a, c) — the two-variable analogue of the one-variable F(b)−F(a)F(b) - F(a) subtraction.
Do not confuseA componentwise product. F(x,y)F(x, y) is not FX(x) FY(y)F_X(x)\,F_Y(y) unless the variables are independent — the same factorization trap as the density, one storey up.
DownloadPNG2×PDF
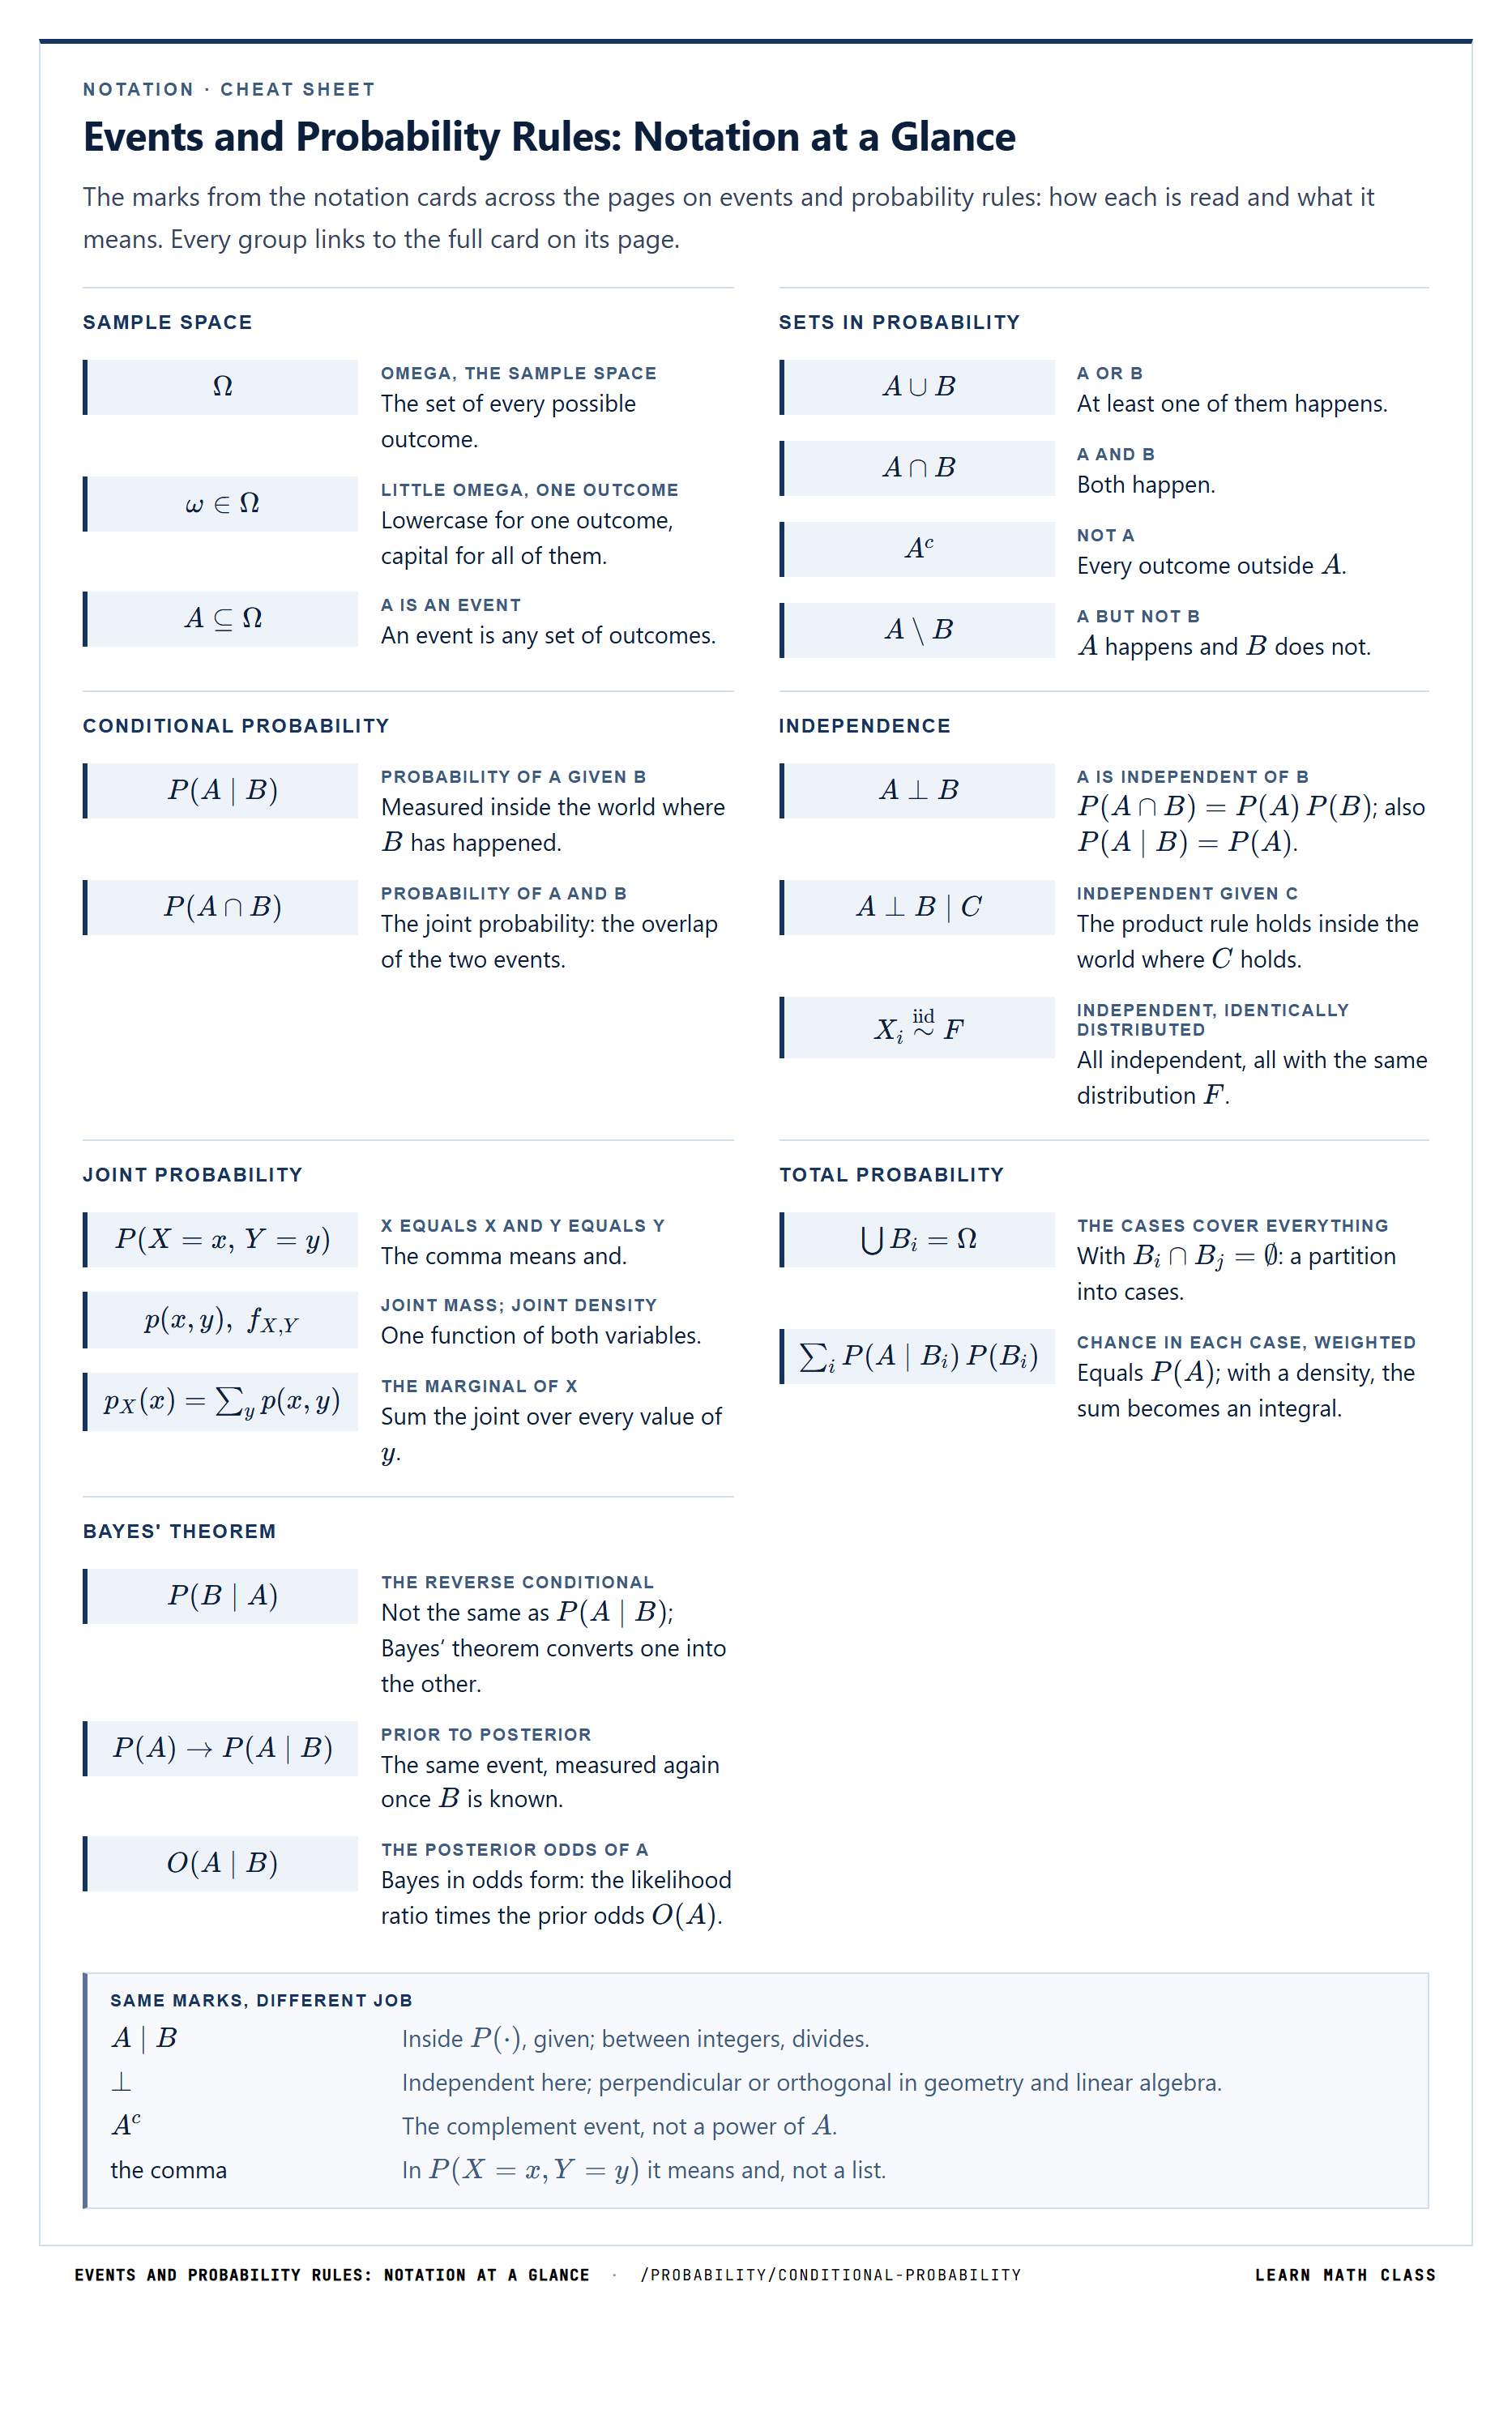
Notation · Cheat sheet
Events and Probability Rules: Notation at a Glance
The marks from the notation cards across the pages on events and probability rules: how each is read and what it means. Every group links to the full card on its page.
Sample space
Ω\Omega
omega, the sample space
The set of every possible outcome.
ω∈Ω\omega \in \Omega
little omega, one outcome
Lowercase for one outcome, capital for all of them.
A⊆ΩA \subseteq \Omega
A is an event
An event is any set of outcomes.
Sets in probability
A∪BA \cup B
A or B
At least one of them happens.
A∩BA \cap B
A and B
Both happen.
AcA^c
not A
Every outcome outside AA.
A∖BA \setminus B
A but not B
AA happens and BB does not.
Conditional probability
P(A∣B)P(A \mid B)
probability of A given B
Measured inside the world where BB has happened.
P(A∩B)P(A \cap B)
probability of A and B
The joint probability: the overlap of the two events.
Independence
A⊥BA \perp B
A is independent of B
P(A∩B)=P(A) P(B)P(A \cap B) = P(A)\,P(B); also P(A∣B)=P(A)P(A \mid B) = P(A).
A⊥B∣CA \perp B \mid C
independent given C
The product rule holds inside the world where CC holds.
Xi∼iidFX_i \overset{\text{iid}}{\sim} F
independent, identically distributed
All independent, all with the same distribution FF.
Joint probabilityThis page
P(X=x, Y=y)P(X = x, \, Y = y)
X equals x and Y equals y
The comma means and.
p(x,y),  fX,Yp(x, y), \; f_{X,Y}
joint mass; joint density
One function of both variables.
pX(x)=∑yp(x,y)p_X(x) = \sum_y p(x, y)
the marginal of X
Sum the joint over every value of yy.
Total probability
⋃Bi=Ω\bigcup B_i = \Omega
the cases cover everything
With Bi∩Bj=∅B_i \cap B_j = \emptyset: a partition into cases.
∑iP(A∣Bi) P(Bi)\sum_i P(A \mid B_i)\,P(B_i)
chance in each case, weighted
Equals P(A)P(A); with a density, the sum becomes an integral.
Bayes' theorem
P(B∣A)P(B \mid A)
the reverse conditional
Not the same as P(A∣B)P(A \mid B); Bayes’ theorem converts one into the other.
P(A)→P(A∣B)P(A) \to P(A \mid B)
prior to posterior
The same event, measured again once BB is known.
O(A∣B)O(A \mid B)
the posterior odds of A
Bayes in odds form: the likelihood ratio times the prior odds O(A)O(A).
Same marks, different job
A∣BA \mid BInside P(⋅)P(\cdot), given; between integers, divides.
⊥\perpIndependent here; perpendicular or orthogonal in geometry and linear algebra.
AcA^cThe complement event, not a power of AA.
the commaIn P(X=x,Y=y)P(X = x, Y = y) it means and, not a list.
Events and Probability Rules: Notation at a Glance·/probability/conditional-probabilityLearn Math Class
2×3 contingency tableB₁B₂B₃totalA0.3000.1800.1200.60Aᶜ0.1200.1600.1200.40total0.420.340.241.00
A 2 by 3 contingency table with marginal totals

Each cell holds the joint probability of one row outcome and one column outcome; the rows sum to the marginal probabilities of the first variable and the columns to those of the second, and the grand total is 1. Every joint, marginal and conditional probability of the two variables can be read from this one table. Edit the cells and watch the margins update on the contingency tables explorer.

Several methods of computing the entries follow.

Contingency Tables (Joint Probability Tables)


    A contingency table is a simple way to organize joint probabilities for discrete variables. One variable forms the rows, the other forms the columns, and each cell shows the likelihood of the two outcomes occurring together.

    The table displays the entire joint distribution at once, making it easy to see which combinations are more likely, which are rare, and how the variables behave side by side.

  • Rows represent the possible values of one variable
  • Columns represent the values of the other
  • Cells contain the joint probabilities for each pair of outcomes
  • All cell values together must sum to 1
  • Patterns in the table often hint at dependence or independence

  • A small table illustrates the idea:

    | | y1y_1 | y2y_2 |
    |--------|--------|--------|
    | x1x_1 | P(x1,y1)P(x_1, y_1) | P(x1,y2)P(x_1, y_2) |
    | x2x_2 | P(x2,y1)P(x_2, y_1) | P(x2,y2)P(x_2, y_2) |

    This layout makes it easy to read, compare, and analyze how outcomes pair up across the two variables.

    To compute joint and marginal probabilities from your own 2×2 table, use the joint probability calculator.

Ways to Calculate Joint Probability


Joint probability does not rely on a single formula. How we compute it depends on the situation, the type of variables, and the information available. Here are the general ways it is actually done.

1. Direct reasoning from the situation.
Sometimes we do not start with tables, formulas, or densities. We simply look at the scenario and ask how many combined outcomes are possible and how many of them satisfy the conditions we care about.
If all outcomes are equally likely, joint probability can be found by counting the favourable combined outcomes and dividing by the total number of combined outcomes.
This is the most basic way to calculate joint probability and often the first step before any formal tool is introduced.

2. Using tables (discrete variables).
When outcomes are discrete, we often organize all combinations into a contingency table.
Each cell shows the likelihood of a specific pair of values, and probabilities for larger sets are found by adding the relevant cells.
Tables make joint behaviour easy to read and compare.

Fact: A broken stick makes a triangle 1 time in 4
Break a stick at two points chosen uniformly at random. The three pieces form a triangle with probability 14\frac{1}{4}: in the unit square of the two cut points, the pairs that leave every piece shorter than half the stick cover exactly a quarter of the area.

3. Using densities (continuous variables).
For continuous variables, we compute joint probability by integrating the joint density over the region of interest.
This replaces the idea of adding cell values with measuring how probability mass is spread over an area.

4. Using the joint CDF.
Sometimes we use the joint cumulative distribution function, which gives the probability that both variables fall within certain ranges.
Joint probabilities for rectangles or regions can be found by evaluating or combining CDF values.

5. Applying probability rules to combined conditions.
In both discrete and continuous settings, joint probability is obtained by applying the appropriate rules—adding probabilities for unions, integrating or summing over regions, or combining conditions that involve more than one variable.

In short, joint probability is calculated by reasoning about the combined outcomes and then using the tool that matches the type of variables involved—whether pure logic, tables, densities, or cumulative functions.

The five methods above each suit a different setting; the table below collects them with what each method actually does and when to reach for it.
Method What you do When to use
Direct reasoning count favourable combined outcomes ÷ total combined outcomes small, equally likely discrete sample spaces
Contingency table read individual cells, sum relevant cells for compound conditions discrete variables with finite support
Joint density integration ∫∫R fX,Y(x, y) dx dy over the region R continuous variables when the joint PDF is known
Joint CDF evaluate FX,Y at the corners of a rectangle and combine probabilities over rectangular / box-shaped regions
Probability rules apply union, complement, conditional, and product rules to combined events compound conditions expressed as combinations of simpler ones
Two dice: first die even has 18 outcomes, sum at least 9 has 10, both together 6, so the joint probability is 6/36second diefirst die1122334455661,11,21,31,41,51,62,12,22,32,42,52,63,13,23,33,43,53,64,14,24,34,44,54,65,15,25,35,45,55,66,16,26,36,46,56,6A: first die even18 of 36 outcomesB: sum ≥ 910 of 36 outcomesA and B: the shared cells(4,5) (4,6) (6,3)(6,4) (6,5) (6,6)P(A, B) = 6/36 = 1/6Joint probability by counting combined outcomes
Method 1: counting combined outcomes

Two fair dice give 36 equally likely combined outcomes. A, first die even, covers the blue rows (18 cells); B, sum at least 9, covers the amber corner (10 cells). The joint event A and B is the cells that are in both, outlined in navy: (4,5), (4,6), (6,3), (6,4), (6,5), (6,6). Six favourable combined outcomes out of 36 give P(A, B) = 6/36 = 1/6.

Not P(A) + P(B) = 28/36, and not P(A) · P(B) = 5/36: A and B are not independent here.

Marginal Probabilities


Marginal probabilities describe the likelihood of each variable on its own, after we set aside the combined outcomes. They are obtained from the joint distribution by "collecting" all probabilities that correspond to a particular value of one variable.

From a table (discrete variables).
In a contingency table, marginals appear naturally as the row totals and column totals.
• Row totals give the probabilities for the values of one variable.
• Column totals give the probabilities for the values of the other.
They represent the standalone behaviour of each variable, separated from the combinations.

Pitfall: Reading one cell as the marginal
Taking P(X=x1)P(X = x_1) from the single cell P(x1,y1)=0.20P(x_1, y_1) = 0.20 leaves out the other column. The marginal is the row total, 0.20+0.10=0.300.20 + 0.10 = 0.30.

Suppose the first row of a table holds P(x1,y1)=0.20P(x_1, y_1) = 0.20 and P(x1,y2)=0.10P(x_1, y_2) = 0.10. Each of these cells pairs x1x_1 with one particular value of YY, and together the cells of the row list every way in which x1x_1 can occur.

The question P(X=x1)P(X = x_1) asks about x1x_1 alone, whatever value YY happens to take. It does not single out any one column of the table.

From a density (continuous variables).
For continuous variables, marginal probabilities (densities) are obtained by integrating the joint density over the other variable.
This gathers all the mass that belongs to a specific value or range of one variable.

Why marginals matter.
They show how each variable behaves individually, without the influence of the other. But they also lose information: once we collapse the joint structure, any patterns of dependence disappear. Joint behaviour is richer; marginals are only the isolated pieces.

Marginals form the bridge between the full joint picture and the behaviour of each variable on its own.

Independence in Joint Probability


Two variables are independent when knowing the value of one tells us nothing about the other. In terms of joint probability, this means that the likelihood of their combined outcome is just the product of their individual probabilities.

How it appears in a table (discrete case).
In a contingency table, independence shows up when every cell equals
(row marginal) × (column marginal).
The entire table follows this pattern — no row or column deviates from it.

How it appears with densities (continuous case).
For continuous variables, independence means the joint density breaks into the product of the two marginal densities. The density surface has no tilt, stretch, or pattern linking the variables.

Pitfall: Assuming independence by default
Multiplying the marginals for two cards drawn without replacement gives P(both aces)=113⋅113=1169P(\text{both aces}) = \frac{1}{13} \cdot \frac{1}{13} = \frac{1}{169}. The draws are dependent, and the joint value is 452⋅351=1221\frac{4}{52} \cdot \frac{3}{51} = \frac{1}{221}.

What independence means in practice.
Independence says the variables do not influence each other, do not track each other, and do not create patterns together. Most real-world variables are not independent — dependence is the norm, independence is the special case.

Independence is the cleanest possible relationship between variables: completely separate behaviour.

Properties of Joint Probability


  • Non-negativity: joint values can never be negative
  • Normalization: all joint probabilities together sum (or integrate) to 1
  • Reduction to marginals: summing or integrating over one variable gives the marginal for the other
  • Full description: the joint distribution contains all information about the variables' combined behaviour
  • Dependence visible: any relationship between variables shows up in the joint structure


Connection to Conditional Probability


• Conditional probability is built directly from the joint distribution
• P(X=x∣Y=y)P(X=x \mid Y=y) is found by taking the joint value and dividing by the marginal of YY
• In a table: cell ÷ column total
• In a density: joint density ÷ marginal density
• The chain rule comes from this relationship and breaks joint probabilities into conditional pieces
• Bayes' theorem is a direct consequence of joint and marginal probabilities working together

Pitfall: Confusing joint with conditional
Reporting the cell P(x1,y1)=0.20P(x_1, y_1) = 0.20 as P(X=x1∣Y=y1)P(X = x_1 \mid Y = y_1) skips the division. With the column total P(Y=y1)=0.50P(Y = y_1) = 0.50, the conditional is 0.20/0.50=0.400.20 / 0.50 = 0.40.

The joint value and the conditional value answer different questions about the same cell. The joint P(x1,y1)P(x_1, y_1) measures the cell against the whole table, whose total is 11.

The conditional P(X=x1∣Y=y1)P(X = x_1 \mid Y = y_1) measures the same cell against its own column only, since conditioning on Y=y1Y = y_1 removes every other column from view. A cell holding 0.200.20 is a small share of the whole table but can be a large share of a column whose total is small.
P(A) = 0.600P(Aᶜ) = 0.400P(B|A) = 0.700P(Bᶜ|A) = 0.300P(B|Aᶜ) = 0.300P(Bᶜ|Aᶜ) = 0.700AP = 0.6000AᶜP = 0.4000A ∩ BP = 0.4200A ∩ BᶜP = 0.1800Aᶜ ∩ BP = 0.1200Aᶜ ∩ BᶜP = 0.2800
One path through the tree: the joint probability of A and B

The joint probability of the highlighted leaf is the product along its path, P(A) times P(B given A), so conditional probability is the joint divided by the marginal of the conditioning event. The same leaf reached from the other variable first gives the same product. Follow other paths and multiply on the conditional probability tree diagram.

Named joint distributions organise such tables at scale.

Joint Distributions

  • Multinomial distribution: joint outcomes for repeated categorical trials
  • Bivariate normal distribution: joint behaviour of two correlated normal variables
  • Joint uniform distribution: probability spread evenly over a region
  • Joint Bernoulli / 2×2 models: simplest case of two binary variables
    These serve as standard examples of how joint behaviour can be shaped by dependence patterns and constraints.

  • The table below lines up these standard families with the type they belong to, what each one models, and the shape of the resulting joint structure.
Distribution Type What it models Joint structure
Multinomial discrete counts across k categories over n trials joint PMF over (n1, ..., nk) with ∑ni = n
Bivariate normal continuous two correlated normal variables bell-shaped joint density tilted by correlation ρ
Joint uniform continuous probability spread evenly over a region R f(x, y) = 1 / area(R) on R, zero elsewhere
Joint Bernoulli (2×2) discrete two binary outcomes considered together four cells P(0,0), P(0,1), P(1,0), P(1,1) summing to 1

Why Joint Probability Matters in Practice


• Real systems involve several quantities changing together
• Joint probability captures relationships that single-variable views miss
• Essential for modeling risk with multiple factors
• Forms the basis for classification and many machine-learning methods
• Used in finance to understand co-movement of assets
• Needed in weather and environmental modeling with multiple measurements
• Critical for interpreting medical tests, symptoms, and diagnostic patterns

Common Mistakes


• Confusing joint probability with conditional probability
• Assuming independence when variables are actually dependent
• Treating P(A,B)P(A, B) as if it were P(A)+P(B)P(A) + P(B)
• Forgetting that all joint values must sum or integrate to 1
• Mixing up marginals and conditionals when reading tables
• Misinterpreting patterns in contingency tables as independence

The pitfalls above can be lined up with what makes each one a misreading and what the correct view actually looks like.
Mistake Why it's wrong Correct view
Confusing joint with conditional P(A, B) is co-occurrence; P(A | B) is A given B already happened conditional = joint ÷ marginal of the conditioning variable
Assuming independence by default real-world variables are usually dependent independence ⇔ every cell equals (row marginal) × (column marginal)
Treating P(A, B) as P(A) + P(B) addition is for disjoint unions, not co-occurrence use the product P(A) · P(B) — and only under independence
Forgetting normalization a joint that doesn't sum / integrate to 1 isn't a distribution verify ∑∑ p(x, y) = 1 or ∫∫ f(x, y) dx dy = 1 before reasoning
Mixing marginals and conditionals in a table row / column totals are marginals, individual cells are joints conditional = (cell) ÷ (row or column total)
Reading "balanced" cells as independence visual symmetry is not the same as factorization independence is a quantitative product test, not a pattern check

One further mistake is marked where it happens in Marginal Probabilities above; here it is worked through in full.

Reading one cell as the marginal

A table gives the joint probabilities, and the probability of one value of XX on its own is needed. Instead of adding the cells across the row of that value, a single cell of the row is taken as the answer.

Wrong working: in a table whose first row holds P(x1,y1)=0.20P(x_1, y_1) = 0.20 and P(x1,y2)=0.10P(x_1, y_2) = 0.10,
P(X=x1)=P(x1,y1)=0.20P(X = x_1) = P(x_1, y_1) = 0.20


Right working: x1x_1 can occur together with y1y_1 or with y2y_2, so both cells count.
P(X=x1)=P(x1,y1)+P(x1,y2)=0.20+0.10=0.30P(X = x_1) = P(x_1, y_1) + P(x_1, y_2) = 0.20 + 0.10 = 0.30


Why it happens: the cell sits in the row labelled x1x_1, so it looks like the number that belongs to x1x_1. But every cell also carries a value of YY; only the row total is free of it.

How to check: the marginals of one variable must add up to 11. With the second row P(x2,y1)=0.30P(x_2, y_1) = 0.30 and P(x2,y2)=0.40P(x_2, y_2) = 0.40, the single cells of the first column give 0.20+0.30=0.500.20 + 0.30 = 0.50, while the row totals give 0.30+0.70=10.30 + 0.70 = 1.

Connections to Other Probability Concepts


Joint Probability at a Glance

The table below condenses joint probability into a single quick-reference card — what it represents, how it is expressed in the discrete and continuous cases, how marginals and conditional probabilities are recovered from it, what independence looks like in the joint structure, why it matters in practice, and the pitfall most frequently confused with it.
Aspect What it captures Example / note
What it is likelihood that multiple outcomes occur together P(X = x, Y = y) or P(A ∩ B)
Discrete representation joint PMF / contingency table with cells summing to 1 2×2 table, multinomial counts
Continuous representation joint PDF fX,Y(x, y) integrating to 1 over the plane bivariate normal, joint uniform
Marginal from joint sum or integrate out the other variable row / column totals in a contingency table
Conditional from joint divide joint by the marginal of the conditioning variable foundation of the chain rule and Bayes' theorem
Independence joint factorizes into the product of marginals every cell equals (row marginal) × (column marginal)
Why it matters reveals dependence patterns invisible in single-variable marginals risk, finance, ML classifiers, medical diagnostics
Most common pitfall treating P(A, B) as if it were P(A) + P(B) addition is for disjoint events; joint co-occurrence calls for the product (and only under independence)

Joint Probability FAQ

What does the comma mean in P(X = x, Y = y)?

+
It is a quiet intersection. Each equality names an event, and the comma joins them with “and” — P(X = x, Y = y) is P({X = x} ∩ {Y = y}). With random variables the comma is the standard spelling, not an alternative; the ∩ sign all but disappears. Do not read P(x, y) as a function evaluated at the point (x, y).Read more →

Can you always split a joint density into a product of marginals?

+
No. f(x, y) equals f_X(x)·f_Y(y) only when X and Y are independent — the factorization is not a rule, it is what independence means for densities. Assuming the split without justification is the most common error here, and the same trap appears one storey up with joint CDFs.Read more →

What is the difference between a marginal and a conditional probability?

+
A marginal averages over the other variable; a conditional pins it to one value. In a contingency table that is the difference between a row total and a single cell divided by its column total. The marginal answers how likely X is overall, the conditional how likely X is among the cases where Y took one particular value.Read more →

Why is it called a marginal probability?

+
Because of where the numbers used to be printed. In a contingency table the row and column totals are written in the margins, and those totals are exactly the individual probabilities of each variable. The name stuck even when no table is drawn: a marginal is what you get by summing the joint over everything the other variable can do.Read more →

How do you find the probability of a rectangle from a joint CDF?

+
By inclusion–exclusion on the four corners: P(a < X ≤ b, c < Y ≤ d) = F(b, d) − F(a, d) − F(b, c) + F(a, c). Subtracting the two overhanging strips removes the corner region twice, so it has to be added back once. It is the two-variable analogue of F(b) − F(a).Read more →

Can you rebuild a joint distribution from its marginals?

+
Not in general. Marginals keep each variable's own behaviour and drop how the two move together, so many joint tables share the same margins. The table with 0.20, 0.10 in its first row and 0.30, 0.40 in its second has row totals 0.30 and 0.70 and column totals 0.50 and 0.50; so does the table 0.15, 0.15, 0.35, 0.35. Only under independence, where every cell is row total times column total, do the marginals fix the joint.Read more →

What is the probability that a stick broken at two random points forms a triangle?

+
One in four. Treat the two cut points as a pair (X,Y)(X, Y) spread uniformly over the unit square, so probability is area. The three pieces form a triangle exactly when every piece is shorter than half the stick, and the pairs that satisfy this cover a quarter of the square. It is a joint probability found by measuring a region rather than by counting cells.Read more →