Visual Tools
Calculators
Tables
Mathematical Keyboard
Converters
Other Tools


Markov Inequality


Markov's Inequality


In many situations, very little is known about a random variable beyond its average size.

Even without knowing the distribution, it is often possible to rule out extreme behavior. Markov's inequality does exactly this: it places an upper bound on the probability that a non-negative random variable exceeds a given level, using only its expected value.

The result is deliberately simple and broadly applicable. It trades precision for generality, providing a guaranteed bound under minimal assumptions.

Key Terms

Expected Value— E[X]E[X], the only quantity needed in Markov's bound
Random Variable— must be non-negative

See All Probability Definitions →


What Markov's Inequality Applies To


Markov's inequality applies to random variables that satisfy very minimal conditions.

Specifically:
• the random variable must be non-negative
• its expected value must exist and be finite
• no assumptions are made about the shape of the distribution

There is no requirement of symmetry, boundedness, or continuity.
The inequality holds equally for discrete and continuous random variables, as long as non-negativity is satisfied.

These minimal assumptions explain both the strength and the weakness of the result: it applies very broadly, but the bound it provides is often coarse.

Statement of Markov's Inequality

The average wait at a counter is 5 minutes. Knowing nothing else, how likely can a wait of 20 minutes or more be?
Waits are never negative, so a long wait has to be balanced by many short ones to keep the average at 55. That alone limits how often long waits can happen.
Different waiting patterns with the same mean give different chances — but none goes above 1/4.
waiting times (mean 5 min)chance of waiting 20 min or more
always exactly 5 min0
0 min or 10 min, half the time each0
0 min (3/4 of the time) or 20 min (1/4)1/4 — as high as it can go
If more than a quarter of customers waited 2020 minutes or more, those customers alone would push the average above 55.
The ceiling is the mean divided by the threshold: 5/20 = 1/4.
This inequality provides an upper bound on the probability that XX exceeds a given threshold, expressed solely in terms of its expectation.
No additional assumptions on the distribution of XX are required.
The definition
Markov's inequality says that a non-negative random variable XX with finite mean satisfies P(X≥a)≤E[X]a\mathbb{P}(X \ge a) \le \frac{\mathbb{E}[X]}{a} for every a>0a > 0.
Let XX be a non-negative random variable with finite expected value E[X]\mathbb{E}[X].
For any real number a>0a > 0, Markov's inequality states:
Statement of Markov's Inequality
P(X≥a)≤E[X]a\mathbb{P}(X \ge a) \le \frac{\mathbb{E}[X]}{a}
So with E[X]=5\mathbb{E}[X] = 5, P(X≥20)≤520=14\mathbb{P}(X \ge 20) \le \frac{5}{20} = \frac{1}{4}, whatever the distribution.
It is a guaranteed upper bound, not an estimate: often loose, never wrong.
xPDFE[X]=10a=15010203040
Markov bound for an exponential variable, mean 10, threshold 15

The bound is the mean over the threshold, 10 over 15, and the shaded tail is the true probability of exceeding 15, which for the exponential family is e to the minus 1.5, about 0.22. The inequality holds for any non-negative variable with that mean, whatever its shape. Slide the threshold and watch bound and tail move on the Markov inequality visualizer.

What the inequality says in words is spelled out next.
The variable must be non-negative: negative values can pull the mean down without shrinking the tail.
Pitfall: Applying it to a variable that can be negative
For XX equal to −10-10 or 1010 with probability 12\frac{1}{2} each, the bound gives P(X≥5)≤05=0\mathbb{P}(X \ge 5) \le \frac{0}{5} = 0, yet the true probability is 12\frac{1}{2}. Negative values pull the mean down without shrinking the tail; the bound holds only for X≥0X \ge 0.
The conditions are listed in what Markov's inequality applies to.
The rest of the page covers notation, what the inequality says, when the bound is tight, and its connection to Chebyshev's inequality.

Markov's Inequality Notation

Notation

Markov's Inequality Notation

This page is the first in the inequalities family to write its marks down, so the shared grammar starts here: the tail event, the bound chain that reads as a guarantee, and the normalized threshold that hands the story on to Chebyshev. All of them are catalogued among the probability symbols.
XX and the event-building braces come from random variable notation; E[X]E[X] from expected value notation; the blackboard register P\mathbb{P}, E\mathbb{E} from distribution notation.
P(X≥a)P(X \ge a)
the probability that X reaches the threshold a — a tail probability
The event "at least aa" wrapped in P(⋅)P(\cdot): everything from the threshold rightward, which is why it is called the right tail. The mirror P(X≤a)P(X \le a) is the left tail — and accumulated left tails are exactly what CDF notation packages as F(a)F(a), making the right tail 1−F(a)1 - F(a) wherever no atom sits at the boundary.
Cases≥\ge versus >> matters only where probability concentrates at the threshold itself: for continuous variables the two spellings agree, for discrete ones they differ by the atom P(X=a)P(X = a) — the same boundary bookkeeping the CDF's chosen ≤ settles on the left side.
Do not confuseA value of XX. P(X≥a)P(X \ge a) is a number about the variable, not a region of outcomes or a truncated variable — bounding it says nothing about which particular large values occur, only about their collective weight.
P(X≥a)≤E[X]a\mathbb{P}(X \ge a) \le \dfrac{\mathbb{E}[X]}{a}
the tail probability never exceeds the mean over the threshold
A probability on the left, a distribution-free recipe on the right, and ≤\le standing between them as a guarantee, not an estimate — the reading What the Inequality Is Saying below insists on. The bound is a ceiling: the truth can sit far beneath it.
CasesThe claim is quantified over every threshold — "for any a>0a > 0" — one inequality per choice of aa, all true at once; when the right side exceeds 11 the statement stays true and says nothing, which is the notation's way of admitting the threshold was too small for the information used.
Do not confuseAn approximation. Reading ≤\le as ≈\approx converts a worst-case ceiling into a prediction — the single most common misuse of the mark, and the reason the page calls the inequality a constraint.
P(X≥k E[X])≤1k\mathbb{P}(X \ge k\,\mathbb{E}[X]) \le \dfrac{1}{k}
at least k times the mean happens with probability at most one over k
The same inequality with the threshold rewritten in units of the mean: substituting a=k E[X]a = k\,\mathbb{E}[X] makes the bound dimensionless — no more than a fifth of the mass can sit at five times the average, whatever the distribution.
CasesThis units-of-the-mean spelling is the bridge to Chebyshev's inequality, which measures its threshold in units of the standard deviation instead — kσk\sigma rather than k E[X]k\,\mathbb{E}[X] — trading wider assumptions for a squared improvement in the bound.
Do not confuseA count. kk is a scale factor on the mean, not a number of events or trials — the same letter that counts successes elsewhere here stretches a threshold, and only the position next to E[X]\mathbb{E}[X] signals which job it holds.
DownloadPNG2×PDF
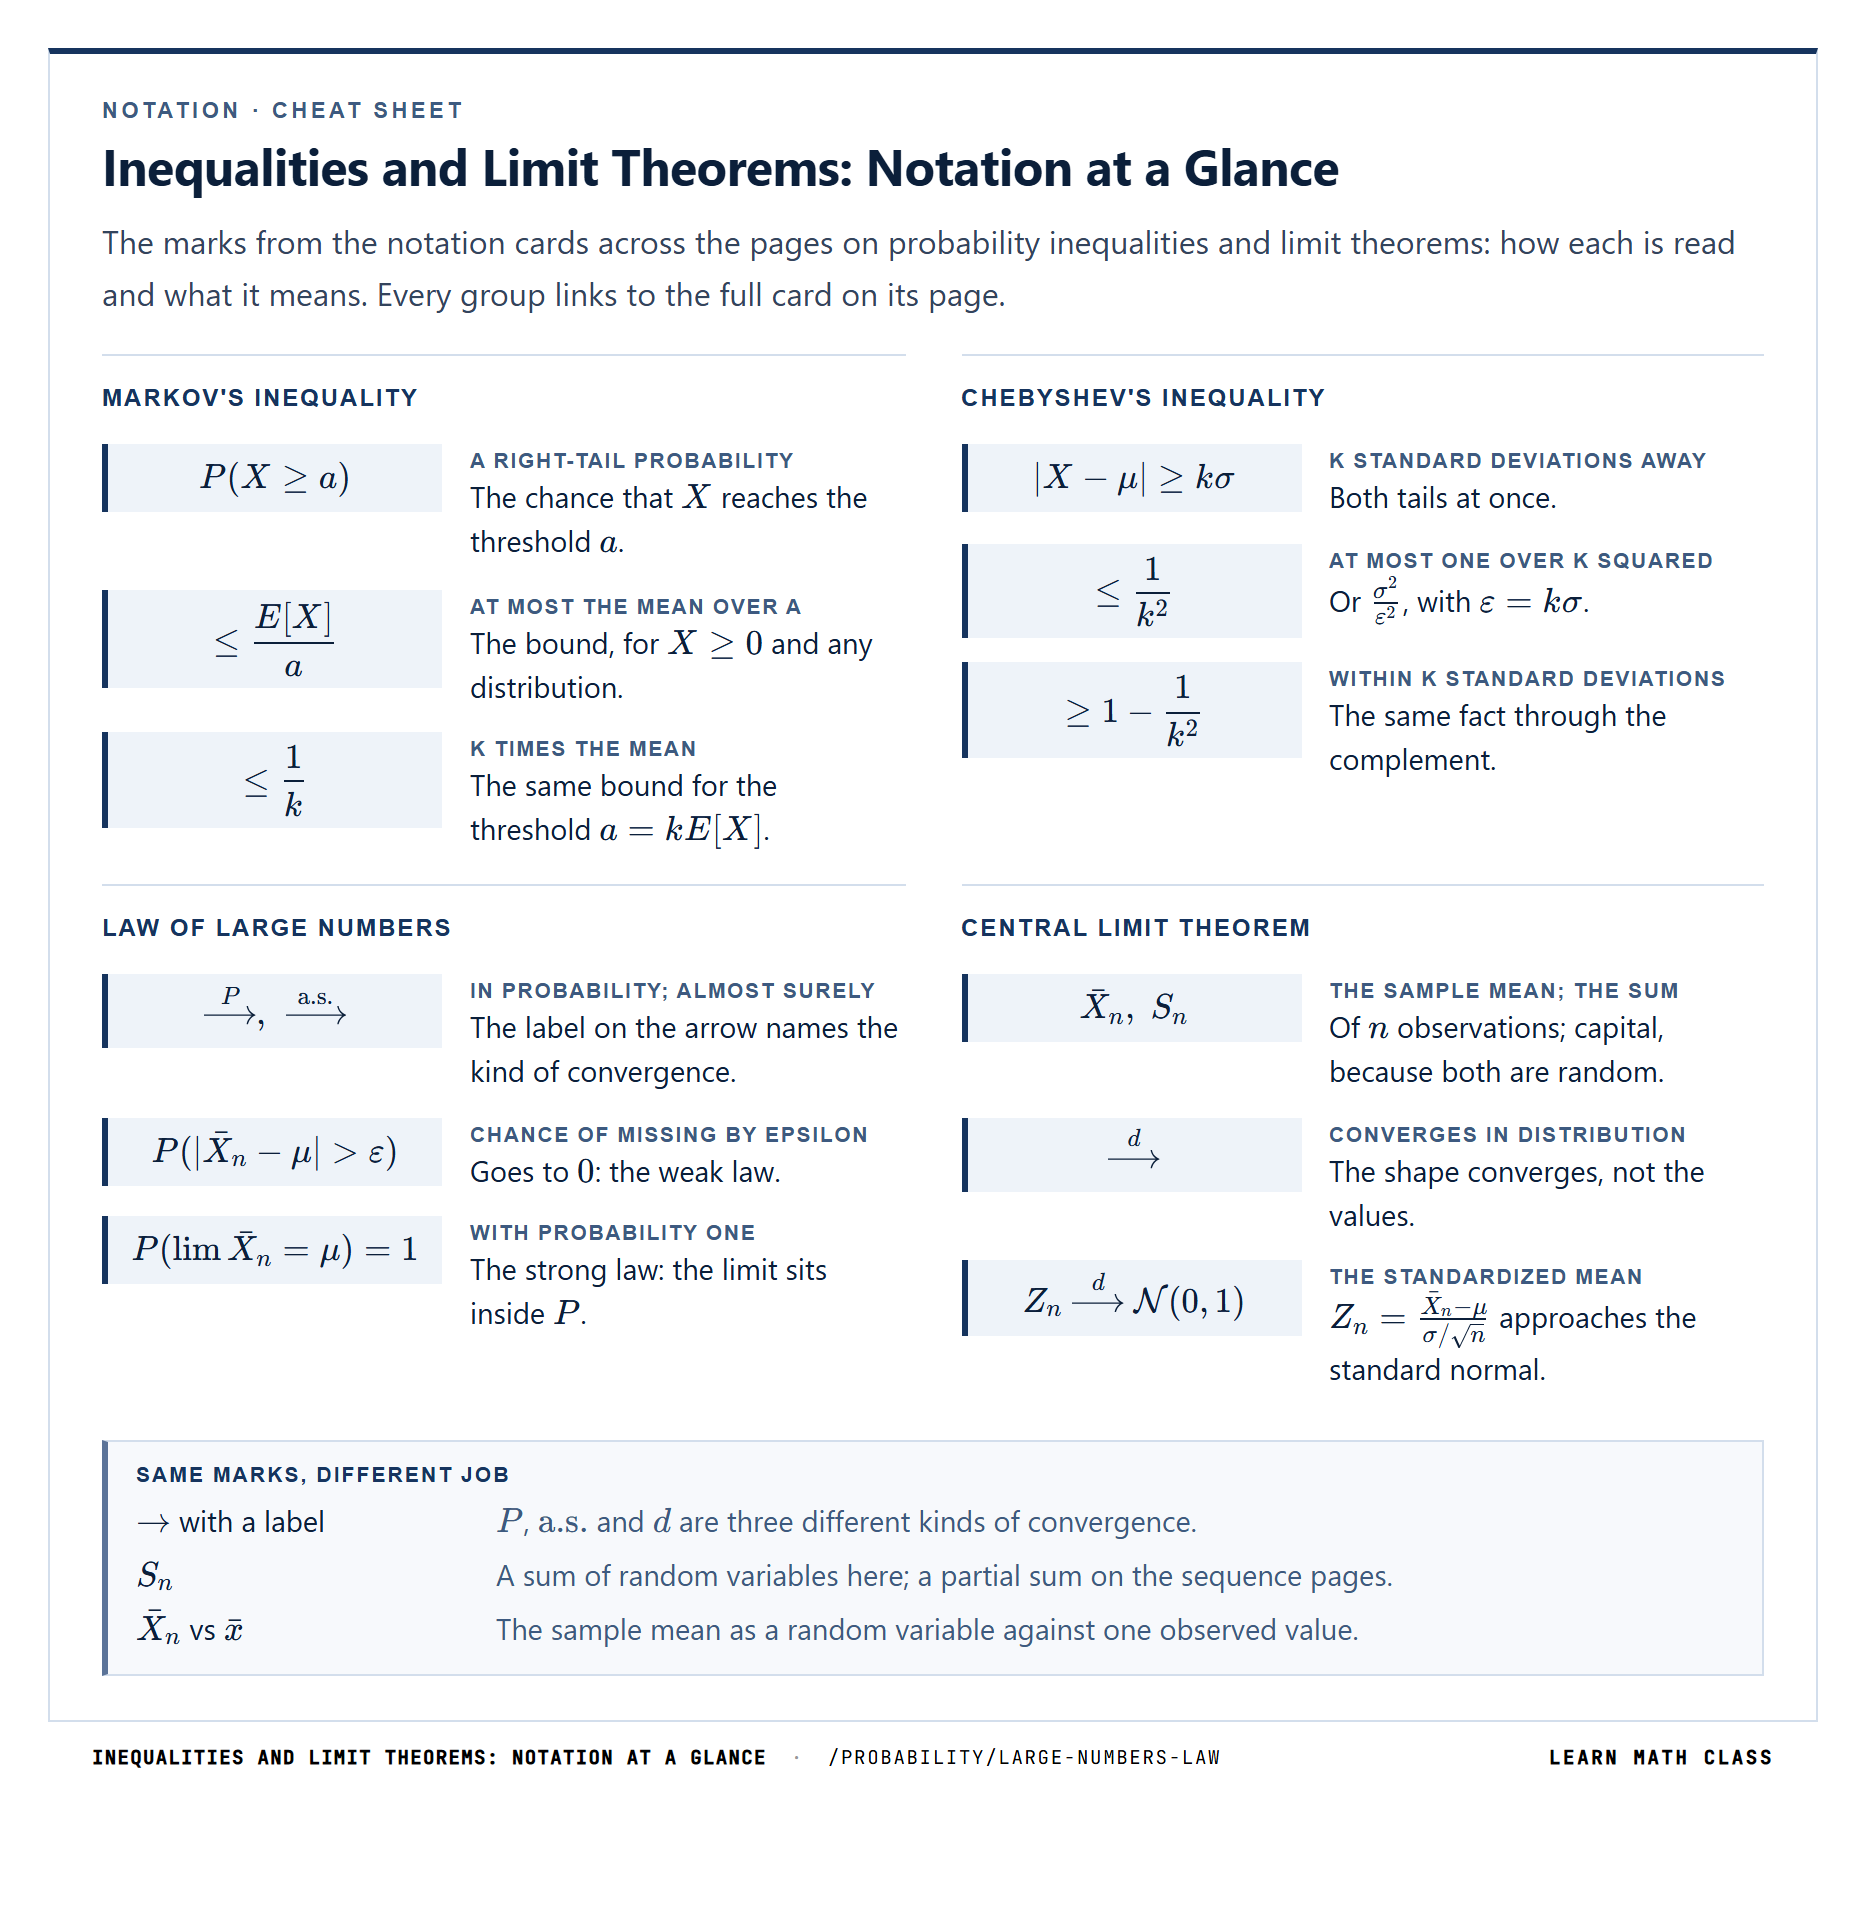
Notation · Cheat sheet
Inequalities and Limit Theorems: Notation at a Glance
The marks from the notation cards across the pages on probability inequalities and limit theorems: how each is read and what it means. Every group links to the full card on its page.
Markov's inequalityThis page
P(X≥a)P(X \ge a)
a right-tail probability
The chance that XX reaches the threshold aa.
≤E[X]a\le \dfrac{E[X]}{a}
at most the mean over a
The bound, for X≥0X \ge 0 and any distribution.
≤1k\le \dfrac{1}{k}
k times the mean
The same bound for the threshold a=kE[X]a = kE[X].
Chebyshev's inequality
∣X−μ∣≥kσ|X - \mu| \ge k\sigma
k standard deviations away
Both tails at once.
≤1k2\le \dfrac{1}{k^2}
at most one over k squared
Or σ2ε2\frac{\sigma^2}{\varepsilon^2}, with ε=kσ\varepsilon = k\sigma.
≥1−1k2\ge 1 - \dfrac{1}{k^2}
within k standard deviations
The same fact through the complement.
Law of large numbers
→P,  →a.s.\xrightarrow{P}, \; \xrightarrow{\text{a.s.}}
in probability; almost surely
The label on the arrow names the kind of convergence.
P(∣Xˉn−μ∣>ε)P(|\bar{X}_n - \mu| > \varepsilon)
chance of missing by epsilon
Goes to 00: the weak law.
P(lim⁡Xˉn=μ)=1P(\lim \bar{X}_n = \mu) = 1
with probability one
The strong law: the limit sits inside PP.
Central limit theorem
Xˉn,  Sn\bar{X}_n, \; S_n
the sample mean; the sum
Of nn observations; capital, because both are random.
→d\xrightarrow{d}
converges in distribution
The shape converges, not the values.
Zn→dN(0,1)Z_n \xrightarrow{d} \mathcal{N}(0,1)
the standardized mean
Zn=Xˉn−μσ/nZ_n = \frac{\bar{X}_n - \mu}{\sigma/\sqrt{n}} approaches the standard normal.
Same marks, different job
→\to with a labelPP, a.s.\text{a.s.} and dd are three different kinds of convergence.
SnS_nA sum of random variables here; a partial sum on the sequence pages.
Xˉn\bar{X}_n vs xˉ\bar{x}The sample mean as a random variable against one observed value.
Inequalities and Limit Theorems: Notation at a Glance·/probability/large-numbers-lawLearn Math Class

What the Inequality Is Saying


THEOREMMarkov's inequality
Markov's inequality states that a non-negative random variable cannot take large values too frequently if its average size is small.

If the expected value of a quantity is limited, then the probability of observing values far above that average must also be limited. The larger the threshold chosen, the smaller the guaranteed upper bound on the probability of exceeding it.

The inequality does not attempt to predict how likely large values actually are.
It only guarantees that they cannot occur more often than the bound allows.

For this reason, Markov's inequality should be read as a constraint, not an approximation.
Markov bound 2/a for a non-negative X with mean 2, against the true tail of an exponential with mean 2aP(X ≥ a)2468100.250.50.751Markov 2/aexponential, mean 2any X ≥ 0 with E[X] = 2a = 6: bound 0.33, true 0.05a ≤ 2: bound ≥ 1 says nothingLarger thresholds, smaller bounds, never below the truth
The bound across all thresholds

For any non-negative X with E[X] = 2, Markov gives P(X ≥ a) ≤ 2/a. The navy curve is that bound for every threshold a; the blue curve is the true tail of one such variable, an exponential with mean 2. The bound shrinks as a grows and is never below the truth, but at a = 6 it allows 0.33 where the exponential has only 0.05. For a ≤ 2 the bound is 1 or more and tells nothing.

Doubling the threshold halves the bound: the curve is E[X]/a.

Why the Bound Is So General


Markov's inequality is extremely general because it relies on almost no information.

It uses only two facts:
• the random variable cannot take negative values
• its expected value exists

Nothing else about the distribution matters. The inequality does not depend on symmetry, spread, shape, or tail behavior. As a result, it applies equally to very different random mechanisms.

This generality comes at a cost.
Because the inequality ignores most of the structure of the distribution, the bound it produces is often far from tight.

Markov's inequality is therefore best understood as a baseline bound: it sets a limit that cannot be violated, but it rarely captures the true probability accurately.
Typical Use Cases


Markov's inequality is most often used when only minimal information about a random variable is available.

Common situations include:
• obtaining a quick upper bound on a tail probability
• reasoning about extreme outcomes without knowing a distribution
• providing a first step in theoretical arguments or proofs
• serving as a baseline before applying stronger inequalities

Fact: Proving existence without an example
Erdős's 1947 argument, in one case: color each link among 10241024 points red or blue by a coin toss. The expected number of 2020-point groups whose links all share one color is about 7×10−167 \times 10^{-16}, so some coloring has no such group at all, though the argument never shows one.

A common first step in proofs applies Markov's inequality to a count. If NN counts how many objects of some kind occur, then NN is never negative, and the threshold a=1a = 1 gives P(N≥1)≤E[N]\mathbb{P}(N \ge 1) \le \mathbb{E}[N]. When the expected count is below 11, the chance of at least one such object is below 11 as well, so with positive probability there is none.

In practice, Markov's inequality is rarely the final result.
It is used to establish a guaranteed bound that can later be improved by introducing additional assumptions or information.

Relationship to Other Inequalities


Markov's inequality is the most basic member of a larger family of probability bounds.

It relies only on non-negativity and expectation, which makes it broadly applicable but weak. Other inequalities strengthen this bound by incorporating additional information about the random variable.

A direct refinement is Chebyshev's inequality, which applies Markov's inequality to squared deviations and uses variance to obtain a tighter bound. Further inequalities introduce higher moments or independence assumptions to sharpen the result even more.

Pitfall: Leaving the threshold unsquared
Applying Markov to (X−μ)2(X - \mu)^2 with threshold ε\varepsilon gives σ2ε\frac{\sigma^2}{\varepsilon}, which is 43\frac{4}{3} for σ2=4\sigma^2 = 4 and ε=3\varepsilon = 3. The event ∣X−μ∣≥ε|X - \mu| \ge \varepsilon is (X−μ)2≥ε2(X - \mu)^2 \ge \varepsilon^2, so the bound is σ2ε2=49\frac{\sigma^2}{\varepsilon^2} = \frac{4}{9}.

The squared deviation (X−μ)2(X - \mu)^2 is never negative, so Markov's inequality applies to it directly, with E[(X−μ)2]=σ2\mathbb{E}[(X - \mu)^2] = \sigma^2 in the place of the mean. The event of interest, a deviation of at least ε\varepsilon from the mean, is first rewritten as an event about the squared deviation, and the bound is then read off for that event.

In this sense, Markov's inequality serves as a starting point.
Many stronger probability inequalities can be viewed as extensions or refinements built on its underlying idea.
DownloadPNG2×PDF
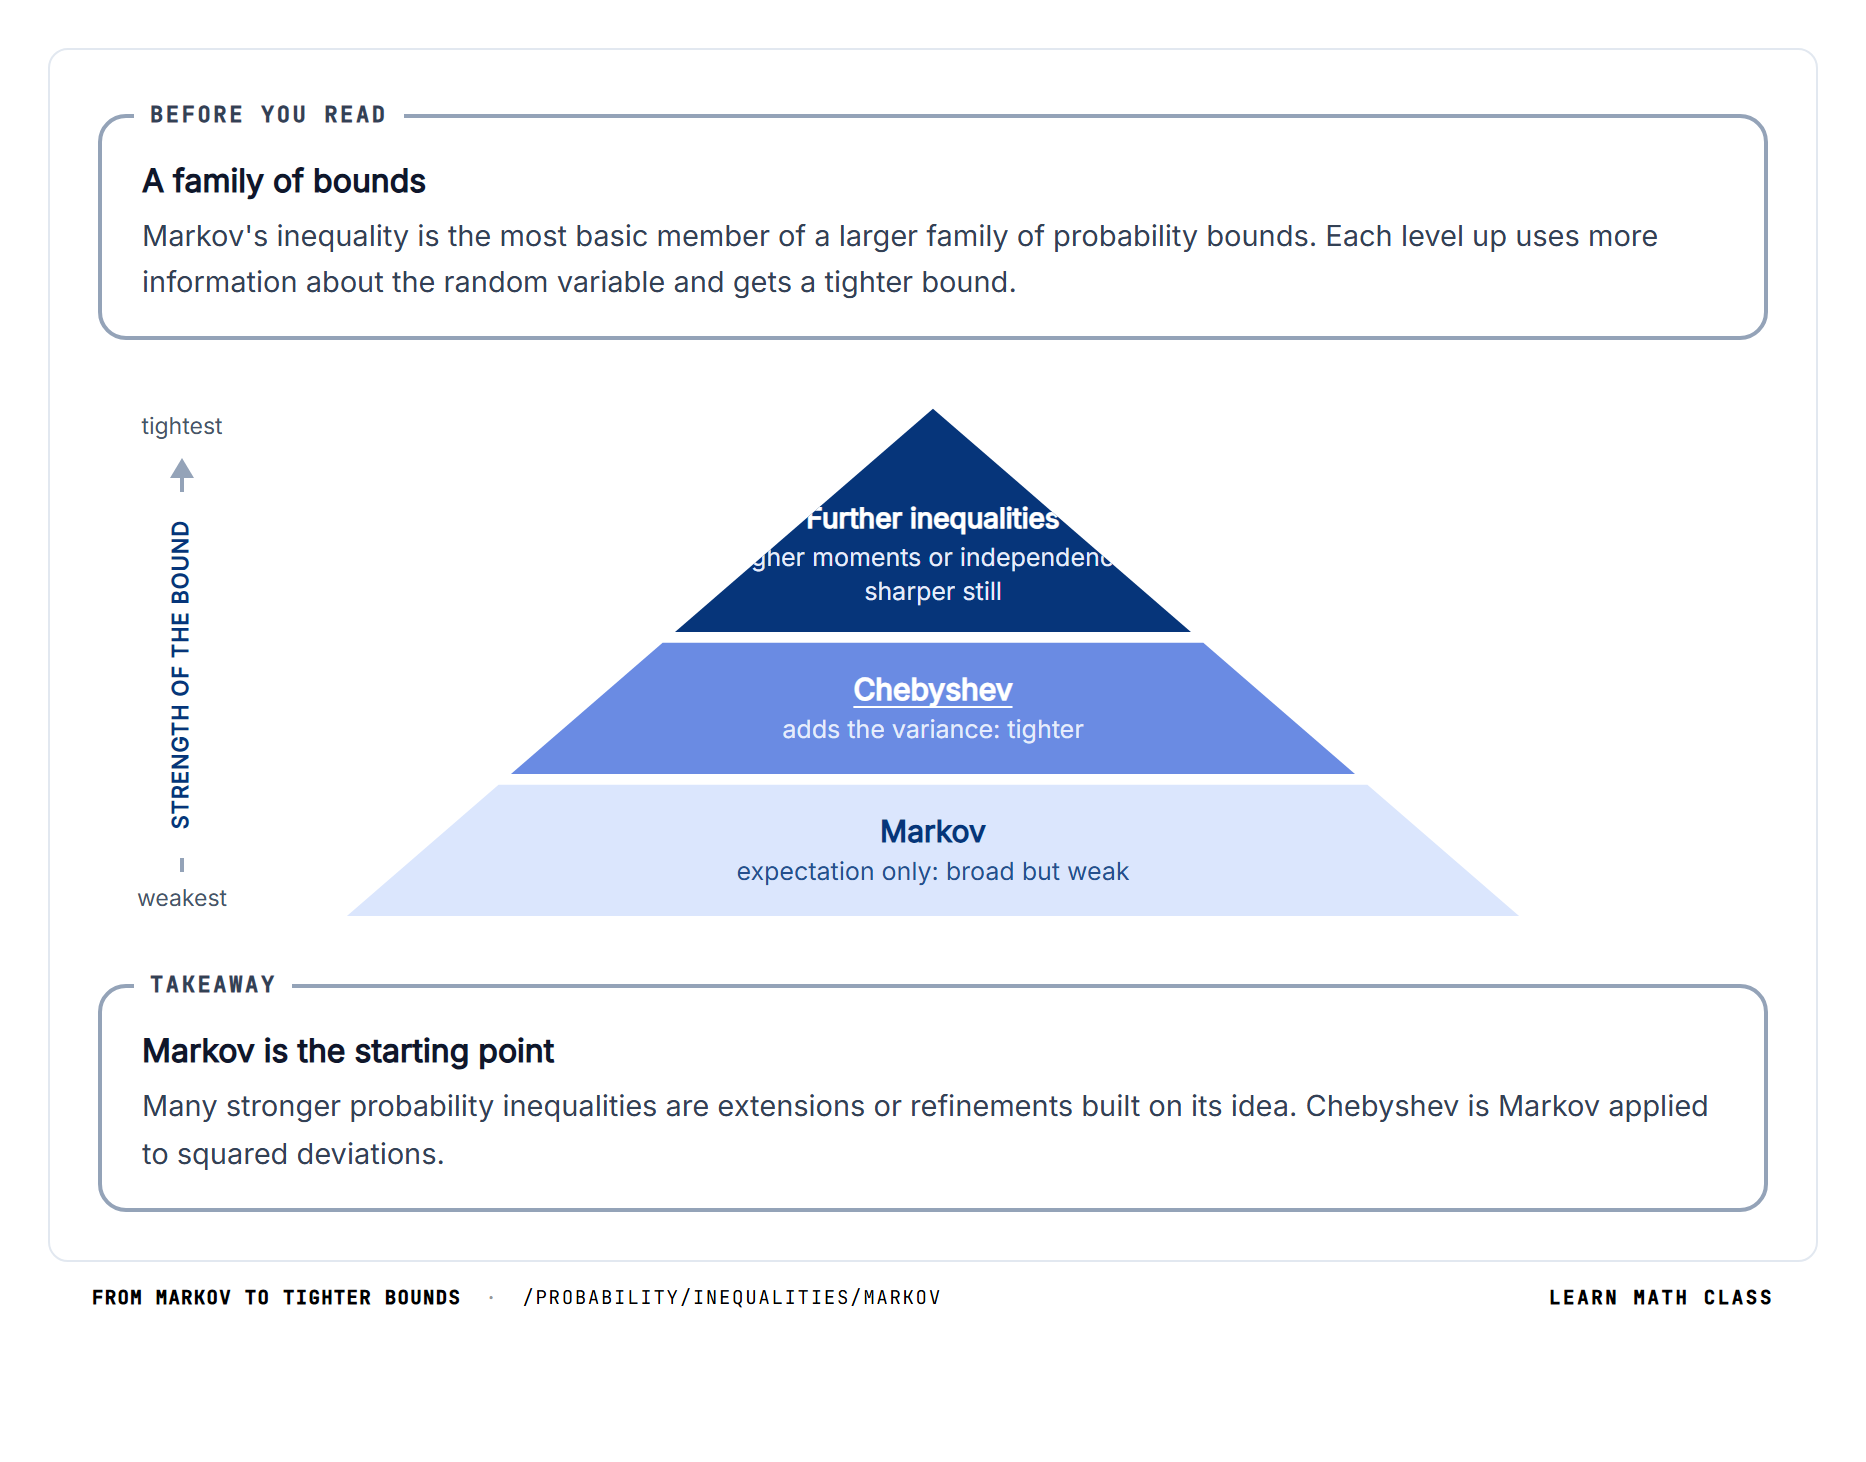
Before you read
A family of bounds
Markov's inequality is the most basic member of a larger family of probability bounds. Each level up uses more information about the random variable and gets a tighter bound.
tighteststrength of the boundweakest
Further inequalitieshigher moments or independence: sharper still
Chebyshevadds the variance: tighter
Markovexpectation only: broad but weak
Takeaway
Markov is the starting point
Many stronger probability inequalities are extensions or refinements built on its idea. Chebyshev is Markov applied to squared deviations.
From Markov to tighter bounds·/probability/inequalities/markovLearn Math Class

Limitations of Markov's Inequality


Although Markov's inequality always holds under its assumptions, the bounds it provides are often very loose.

Fact: Loose, yet impossible to improve
For any mean mm and threshold a≥ma \ge m, the variable equal to aa with probability ma\frac{m}{a} and to 00 otherwise has mean mm and P(X≥a)=ma\mathbb{P}(X \ge a) = \frac{m}{a} exactly. Knowing only the mean, no smaller bound can be guaranteed.

Because it uses only the expected value, the inequality ignores how values are distributed around that average. As a result, the bound may be far larger than the true probability, especially when the random variable has light tails or is tightly concentrated.

Markov's inequality is also uninformative when the threshold is close to the expected value, since the bound may approach or exceed 1. In such cases, it provides little practical insight.

For these reasons, Markov's inequality is best viewed as a guarantee of what cannot happen too often, rather than a precise estimate of what does happen.
xPDFE[X]=10a=8010203040
A threshold below the mean: the bound exceeds 1 and says nothing

When the threshold is smaller than the mean the ratio is larger than 1, and a probability bound above 1 carries no information. Even for thresholds above the mean the bound is usually far from the truth because it ignores everything except the expected value. Move the threshold across the mean and watch the bound become useless on the Markov inequality visualizer.

Its importance lies elsewhere, as the next section argues.

Why Markov's Inequality Matters


Markov's inequality is the simplest non-trivial result that connects expectation to probability.

It shows that meaningful probabilistic statements can be made even when almost no information about a random variable is available. This idea lies at the core of many arguments in probability theory: before refining estimates, one must first establish absolute limits.

Because of its minimal assumptions, Markov's inequality appears repeatedly as a foundational tool. More advanced inequalities refine it, but none bypass the basic logic it introduces.

Summary


Markov's inequality provides an upper bound on the probability that a non-negative random variable exceeds a given level.

It requires only the existence of an expected value and makes no assumptions about distribution shape. The resulting bound is universal but often loose.

For this reason, Markov's inequality is best understood as a baseline result: simple, reliable, and foundational, but rarely the final word in probabilistic analysis.

Markov's Inequality at a Glance

The table below collects the anatomy of Markov's inequality — what it applies to, the single piece of information it consumes, the bound it produces, how to read it, the role it usually plays, and the situations where it stops being informative — into a single reference card.
DownloadPNG2×PDF
Layout
AspectStatementNote / example
Applies tonon-negative random variables with finite expectationno symmetry, boundedness, or continuity assumed
Information usedE[X] onlyno variance, no higher moments, no distribution shape
StatementP(X ≥ a) ≤ E[X] / a, for any a > 0the bound depends only on E[X] and the threshold a
What it boundsupper tail of a non-negative variableone-sided: bounds only the upper tail P(X ≥ a) (by complement, P(X < a) ≥ 1 − E[X]/a)
Plain readinglarge values cannot occur too frequently if the average is smalla constraint, not an approximation
Typical rolequick baseline bound, first step in proofsrarely the final result; refined by stronger inequalities
Tightnessvery broad; usually looseignores how mass is distributed around the mean
When it breaks downthreshold a near E[X] makes the bound ≥ 1 and uselessalso loose for light-tailed or tightly concentrated X
Natural refinementapply Markov to (X − μ)² and use Var(X)this gives Chebyshev's inequality
Markov's Inequality at a GlanceLearn Math Class

Common Pitfalls

Three mistakes account for most wrong uses of Markov's inequality. Two of them are marked where they happen in the sections above; here each is worked through in full, with the wrong and the right working side by side.
DownloadPNG2×PDF
1Applying it to a variable that can be negative
The formula is applied to a variable that takes negative values, because the statement looks as if it needed only a mean and a threshold.
Start
Let XX be −10-10 or 1010, each with probability 12\frac{1}{2}.
Wrong turn
Error here
Then E[X]=0\mathbb{E}[X] = 0 and
P(X≥5)≤05=0\mathbb{P}(X \ge 5) \le \frac{0}{5} = 0
Right path
The true probability is P(X≥5)=P(X=10)=12\mathbb{P}(X \ge 5) = \mathbb{P}(X = 10) = \frac{1}{2}, so the "bound" is false. Markov needs X≥0X \ge 0. Shifting to Y=X+10Y = X + 10, which is never negative and has E[Y]=10\mathbb{E}[Y] = 10, gives a valid bound:
P(X≥5)=P(Y≥15)≤1015=23\mathbb{P}(X \ge 5) = \mathbb{P}(Y \ge 15) \le \frac{10}{15} = \frac{2}{3}
And indeed 12≤23\frac{1}{2} \le \frac{2}{3}.
Why it happensNon-negativity is stated once, among the conditions, and does not appear in the formula itself.
How to checkBefore using the bound, ask whether XX can ever be below 00. A mean of 00 or below with a positive tail probability is a sure sign the condition was broken.
2Reading the bound as the probability
The number E[X]a\frac{\mathbb{E}[X]}{a} is reported as the chance that XX reaches aa, as if Markov computed the probability rather than capped it.
Wrong turn
Error here
For an exponential variable with mean 1010 and the threshold 1515,
P(X≥15)≈1015≈0.67\mathbb{P}(X \ge 15) \approx \frac{10}{15} \approx 0.67
Right path
Markov only says P(X≥15)≤23\mathbb{P}(X \ge 15) \le \frac{2}{3}. For this exponential variable the true value is
P(X≥15)=e−1.5≈0.22\mathbb{P}(X \ge 15) = e^{-1.5} \approx 0.22
About a third of the bound.
Why it happensThe bound is the only number the calculation produces, and with nothing else to compare it with it gets read as the answer.
How to checkWrite ≤\le in the answer, never == or ≈\approx. If the distribution is known, compute the true tail and compare; it should come out at or below the bound, often far below.
3Leaving the threshold unsquared
Markov is applied to the squared deviation (X−μ)2(X - \mu)^2 to bound P(∣X−μ∣≥ε)\mathbb{P}(|X - \mu| \ge \varepsilon), but the threshold is left as ε\varepsilon instead of being squared along with the deviation.
Start
For σ2=4\sigma^2 = 4 and ε=3\varepsilon = 3,
Wrong turn
Error here
P(∣X−μ∣≥3)≤E[(X−μ)2]3\mathbb{P}(|X - \mu| \ge 3) \le \frac{\mathbb{E}[(X - \mu)^2]}{3}

=43= \frac{4}{3}
Right path
The event ∣X−μ∣≥3|X - \mu| \ge 3 is the same as (X−μ)2≥9(X - \mu)^2 \ge 9, so Markov is applied with threshold 99:
P(∣X−μ∣≥3)=P((X−μ)2≥9)\mathbb{P}(|X - \mu| \ge 3) = \mathbb{P}\big((X - \mu)^2 \ge 9\big)

≤49≈0.44\le \frac{4}{9} \approx 0.44
This is Chebyshev's bound σ2ε2\frac{\sigma^2}{\varepsilon^2}.
Why it happensThe variable is squared, and the threshold, written separately, is not carried along. With ε<1\varepsilon < 1 the slip is worse than useless: for σ2=0.01\sigma^2 = 0.01 and ε=0.5\varepsilon = 0.5 it claims 0.020.02, while the correct bound is 0.040.04.
How to checkThe bound must not change when the units change. Measuring in other units multiplies σ2\sigma^2 by the square of the conversion factor; only σ2ε2\frac{\sigma^2}{\varepsilon^2} stays the same, while σ2ε\frac{\sigma^2}{\varepsilon} does not.
Common pitfalls with Markov's inequality·/probability/inequalities/markovLearn Math Class
Each slip uses Markov's inequality outside its terms. The variable must never be negative, the result caps the probability rather than giving it, and applied to (X−μ)2(X - \mu)^2 the threshold becomes ε2\varepsilon^2. Asking whether XX can be below 00, writing ≤\le in the answer, or checking that the bound does not change with the units, catches each slip.

Skills You Should Learn

Each skill opens its step-by-step method page. Skills marked "On this page" are taught above.
Taught on this page
Random variable methods

Markov's Inequality FAQ

What is the 1/k form of Markov's inequality?

+
Substitute a = k·E[X] and the bound becomes dimensionless: P(X ≥ k·E[X]) ≤ 1/k. In words, no more than a fifth of the mass can sit at five times the average, no more than a tenth at ten times, and so on — for any non-negative variable, whatever its distribution. This is the form worth remembering.Read more →

Does Markov's inequality estimate the probability?

+
No — it is a ceiling, not a prediction. The ≤ is a guarantee that the true probability sits at or below E[X]/a, and it may sit far below. Reading ≤ as ≈ turns a worst-case constraint into an estimate, which is the single most common misuse of the inequality.Read more →

When does Markov's inequality tell you nothing?

+
Whenever the threshold is at or below the mean. If a ≤ E[X], then E[X]/a ≥ 1, and the bound says the probability is at most something ≥ 1 — true, but no news, since every probability already satisfies it. The inequality only becomes informative once the threshold sits meaningfully above the average.Read more →

Does it matter whether Markov's inequality uses ≥ or >?

+
Only for discrete variables. The two spellings differ by the atom P(X = a) sitting exactly at the threshold, which is zero for a continuous variable and can be substantial for a discrete one. Markov is normally stated with ≥, so the boundary value is included; switching to > gives a smaller left side and the bound still holds.Read more →

If Markov's bound is so loose, can it be improved?

+
Not without more information than the mean. For any mean mm and threshold a≥ma \ge m, the variable equal to aa with probability ma\frac{m}{a} and to 00 otherwise has mean mm and P(X≥a)=maP(X \ge a) = \frac{m}{a} exactly. The waiting-time example is this case: 00 minutes three quarters of the time and 2020 minutes otherwise gives mean 55 and a tail of exactly 14\frac{1}{4}.Read more →

How is Markov's inequality used to prove that something exists?

+
Through a count. If NN counts objects of some kind, then N≥0N \ge 0, and the threshold a=1a = 1 gives P(N≥1)≤E[N]P(N \ge 1) \le E[N]. When the expected count is below 11, there is a positive chance of none, so an outcome with none exists. Erdős's 1947 argument works this way: coin-toss colourings of the links among 10241024 points expect about 7×10−167 \times 10^{-16} single-coloured 2020-point groups, so some colouring has none.Read more →