In many probability problems, the average of a random variable is known, but its full distribution is not.
Even in this limited setting, information about how much the variable varies around its mean can strongly restrict how often large deviations occur. Chebyshev's inequality captures this idea by relating deviation probabilities directly to the variance.
The result is deliberately general. It applies without assuming any particular distribution shape and provides guaranteed bounds on how far values can stray from the mean, based solely on variability.
Key Terms
Variance— Var(X), the key input to Chebyshev's bound
Chebyshev's inequality applies to random variables under very broad conditions.
Specifically: • the random variable must have a finite mean • the variance must exist and be finite • no assumptions are made about the distribution's shape
The inequality applies equally to discrete and continuous random variables. There is no requirement of symmetry, boundedness, or independence.
Compared to Markov's inequality, Chebyshev uses more information — variance — and therefore provides a tighter bound, while still remaining distribution-free.
Statement of Chebyshev's Inequality
Exam scores have mean 70 and standard deviation 10. Knowing nothing else, what share of the class can score 20 or more points away from 70?
The standard deviation measures how far scores typically sit from the mean. Scores far out add a lot to it, so a small spread leaves little room for many far-off scores.
Measured in standard deviations, the share outside k of them is at most 1/k²: at most a quarter of the class lies 2 deviations out.
scores outside
distance from 70
in standard deviations k
at most 1/k² of the class
60 to 80
10
1
1 — no information
55 to 85
15
1.5
4/9 ≈ 44%
50 to 90
20
2
1/4 = 25%
40 to 100
30
3
1/9 ≈ 11%
The bound holds for any shape of score distribution — skewed, lumpy or flat — as long as the mean and standard deviation are as given.
The bound uses only the mean and the spread, nothing about the shape.
The bound depends only on the variance and makes no assumptions about the form of the distribution.
In a problem, the two forms are fed with whatever numbers it supplies: a mean, a measure of spread, and a distance from the mean. The first form needs that distance expressed as a number k of standard deviations, while the second takes the distance ε as it stands and compares it with the variance. Both routes lead to the same number, because ε=kσ.
The definition
Chebyshev's inequality says that a random variable with finite mean μ and standard deviation σ satisfies P(∣X−μ∣≥kσ)≤k21 for every k>0.
Let X be a random variable with finite mean μ and finite variance σ2.
For any real number k>0, Chebyshev's inequality states:
Statement of Chebyshev's Inequality
P(∣X−μ∣≥kσ)≤k21
Equivalently, for any ε>0,
Statement of Chebyshev's Inequality
P(∣X−μ∣≥ε)≤ε2σ2
So with μ=70 and σ=10, at most 41 of the scores lie outside 50 to 90.
It is a guaranteed upper bound for every distribution, so it is often far from the true share.
For bell-shaped scores the share outside 2 deviations is only about 5%, well below the guaranteed 25%. The bound pays for working everywhere by being loose in the common cases.
Chebyshev bound for a normal variable, mean 10, variance 4, deviation 3
The bound is the variance divided by the square of the deviation, here 4 over 9, and the shaded tails show the true probability of deviating by at least 3, which is much smaller. Two units of standard deviation against a deviation of three produce the same ratio for every distribution. Change the variance or the deviation and watch the bound move on the Chebyshev inequality visualizer.
The next section reads the inequality in words.
Use the standard deviation, not the variance, when counting distances in units of σ.
Pitfall: Treating the variance as the standard deviation
With variance 4 and a deviation of 3, taking σ=4 gives k=43 and a bound of 916, which says nothing. The standard deviation is σ=4=2, so k=23 and the bound is k21=94≈0.44.
For k≤1 the bound is at least 1 and says nothing. How it improves on its parent result is shown in why Chebyshev improves on Markov.
The rest of the page covers notation, what the inequality says, why it improves on Markov's inequality, and where it is used.
Chebyshev's Inequality Notation
Notation
Chebyshev's Inequality Notation
Chebyshev's marks refine Markov's in two moves: the tail turns two-sided, and the threshold changes units — from multiples of the mean to multiples of the standard deviation. This section fixes the deviation event, the bound's two equivalent spellings, and the flipped form that reads as a coverage guarantee. All of them are catalogued among the probability symbols.
X lands at least k standard deviations from its mean — in either direction
Two refinements in one event: the absolute value makes the tail two-sided — both directions at once, where Markov'sX≥a watches only one — and the threshold kσ is measured in units of the standard deviation, the origin of everyday "two-sigma, three-sigma" talk.
CasesThe same event in absolute units swaps kσ for a plain tolerance ε — the spelling the law of large numbers runs on; the two are interchangeable through ε=kσ, and which one a text uses signals whether it thinks in σ-units or in raw distance.
Do not confuseMarkov's k. There the letter multiplies the mean, here the standard deviation — same letter, different unit, and carrying a bound from one threshold convention to the other silently changes what is being claimed.
≤k21, ≤ε2σ2
at most one over k squared — at most variance over tolerance squared
One inequality, two dresses: substitute ε=kσ and each becomes the other. The σ-units spelling gives the clean distribution-free constants; the ε spelling exposes the mechanism — variance up top, tolerance squared below — that Why Chebyshev Improves on Markov below explains.
CasesThe bound only says something when k>1 — at k≤1 the right side reaches 1 and the statement goes vacuous, Markov-style; the square is the visible improvement over Markov's 1/k: twice the threshold buys four times the guarantee, not two.
Do not confuseEach other, mid-formula. Writing σ2/k2 or 1/ε2 mixes the two spellings — the numerator and the denominator must come from the same convention, and the mismatch produces bounds that are silently off by a factor of σ2.
P(∣X−μ∣<kσ)≥1−k21
at least the fraction one minus one-over-k-squared lies within k standard deviations
The same fact flipped through the complement: the tail bound becomes a coverage guarantee, and both marks turn around together — ≥ becomes < inside, ≤ becomes ≥ outside. In numbers: at least 75% within 2σ, at least 89% within 3σ, for every distribution with a variance.
CasesThis is the honest, distribution-free cousin of the normal distribution's 68–95–99.7 rule — Chebyshev promises less (0, 75, 89) because it assumes nothing about shape.
Do not confuseThe normal rule itself. Quoting "95% within two sigmas" for data nobody checked for normality claims the bell curve's privilege without its assumptions — Chebyshev's 75% is what the variance alone can promise, and the gap between the two numbers is exactly what normality is worth.
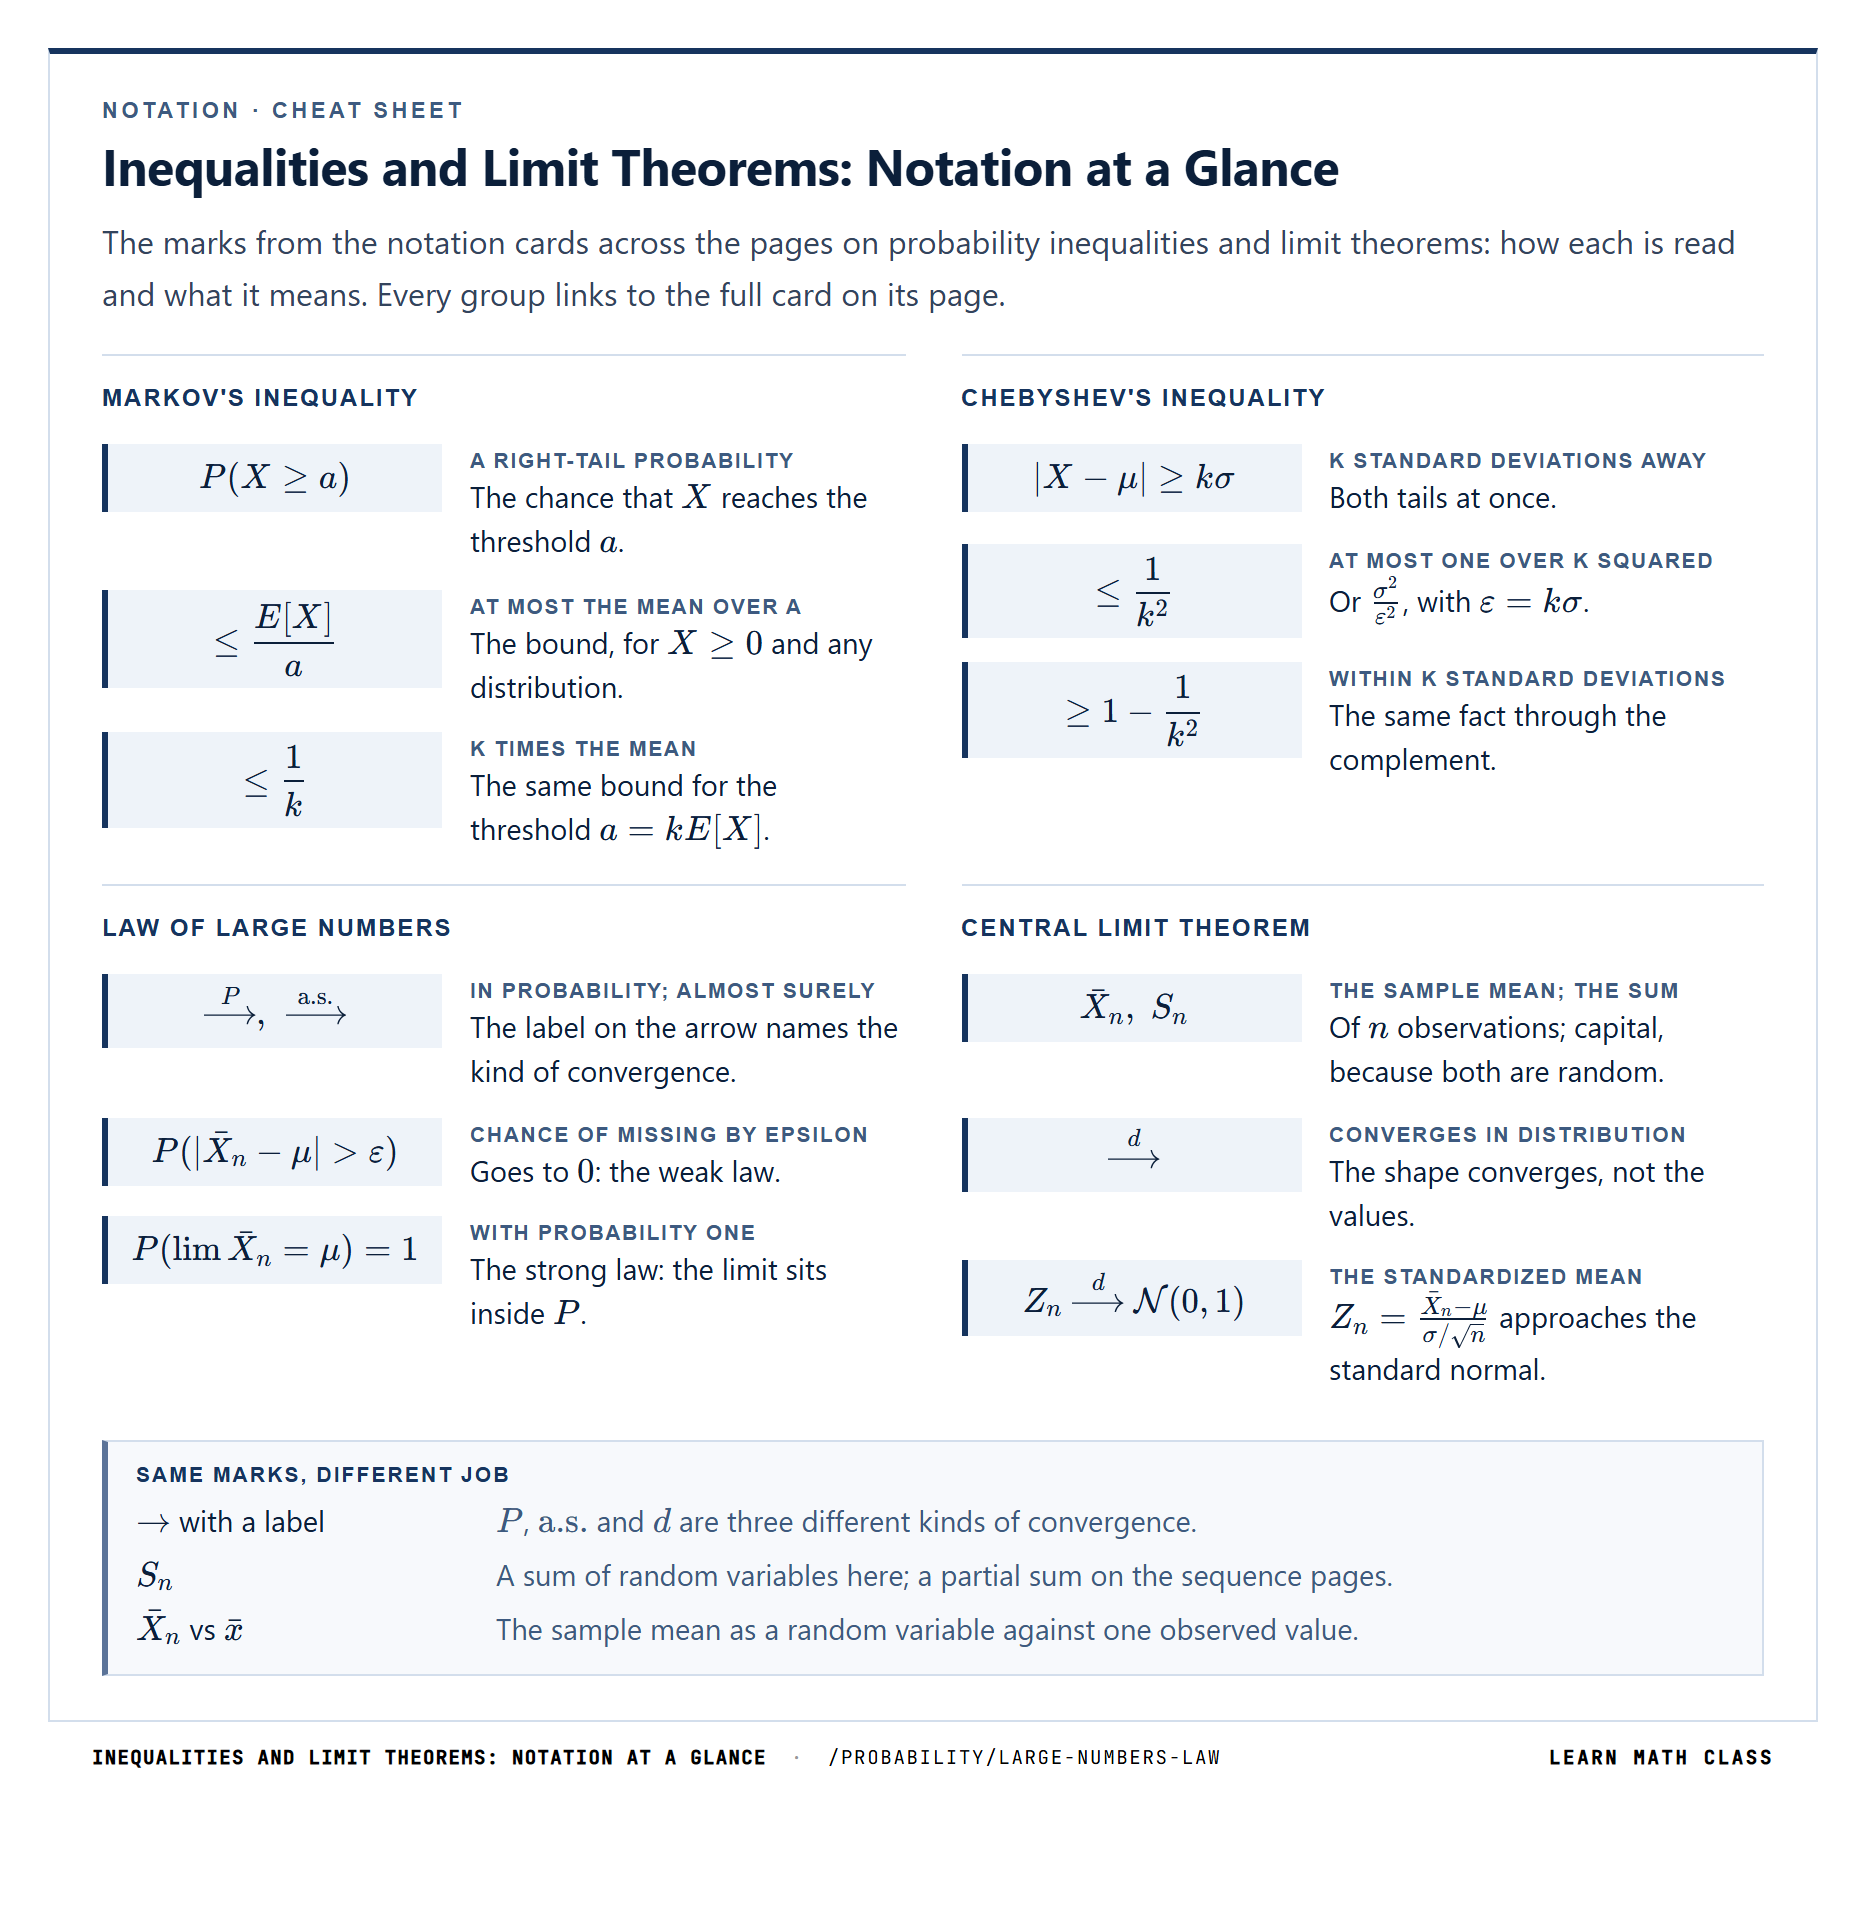
Inequalities and Limit Theorems: Notation at a Glance
The marks from the notation cards across the pages on probability inequalities and limit theorems: how each is read and what it means. Every group links to the full card on its page.
Chebyshev's inequality states that a random variable with small variance cannot stray far from its mean very often.
Fact: The bound is reached exactly
Take X=−2,0,2 with probabilities 81,43,81: the mean is 0, the variance is 1, and P(∣X∣≥2)=41, exactly the bound for k=2. Knowing only the mean and the variance, no smaller bound is safe.
The variance measures how spread out the values of the variable are. If this spread is limited, then large deviations from the mean must be rare. The inequality makes this idea precise by turning variability into a bound on deviation probabilities.
The result does not predict where values will cluster. It only guarantees that extreme departures from the mean are constrained by the size of the variance.
For this reason, Chebyshev's inequality should be read as a guarantee, not as a description of typical behavior.
Why Chebyshev Improves on Markov
Markov's inequality uses only the expected value of a random variable and applies to non-negative quantities. As a result, it places very weak restrictions on how values are distributed.
Chebyshev's inequality incorporates additional information: the variance. By measuring how values spread around the mean, variance allows much stronger control over deviations in both directions.
Pitfall: Halving the bound for one tail
Splitting k21 equally between the tails gives P(X−μ≥2σ)≤0.125. But X=2 with probability 0.2 and X=−0.5 with probability 0.8 has μ=0, σ=1 and that tail equal to 0.2; without symmetry, one tail is bounded only by the full 41.
In effect, Chebyshev's inequality applies Markov's idea to squared deviations from the mean. This extra structure tightens the bound while still avoiding any assumptions about the exact form of the distribution.
Chebyshev therefore refines Markov's inequality: it remains distribution-free, but achieves stronger bounds by using more information.
Typical Use Cases
Chebyshev's inequality is used when information about variability is available, but the exact distribution is unknown or unnecessary.
Common uses include: • bounding the probability of large deviations from the mean • analyzing the stability of averages and estimators • providing guarantees in problems involving uncertainty and noise • serving as a tool in theoretical arguments where distributional details are absent
In many applications, Chebyshev's inequality provides a first meaningful bound that can later be refined if stronger assumptions are introduced.
Chebyshev's inequality plays a central role in establishing convergence results in probability.
Because it controls the probability of deviations from the mean using variance, it is naturally suited to analyzing sequences of random variables, especially averages. When variances shrink, Chebyshev's inequality shows that large deviations become increasingly unlikely.
This makes the inequality a key tool in proofs of the Law of Large Numbers, where it is used to show that sample averages concentrate around their expected value.
In this role, Chebyshev's inequality acts as a bridge between basic moment information and asymptotic behavior.
Chebyshev applied to an average
Roll a die n times and take the average. Each roll has variance 35/12, so the average has variance 35/(12n). Chebyshev with ε = 0.5 bounds the chance that the average misses 3.5 by at least 0.5 by (35/12)/(0.25 n) ≈ 11.67/n. For fewer than 12 rolls the bound is above 1 and says nothing; at n = 100 it is at most 0.117, and it keeps falling toward 0.
Pitfall: Using the variance of one roll for the average
Putting the variance of a single roll, 1235, into the bound gives 0.2535/12≈11.67 for every n, which says nothing. The average of n rolls has variance 12n35, so the bound is n11.67, at most 0.117 at n=100.
In the die example the quantity being controlled is the average of the rolls, and the tolerance ε=0.5 stays fixed however many rolls are taken. The threshold does not move as n grows; the bound responds only through the spread that is divided by ε2. Each roll on its own is exactly as variable after a hundred rolls as after one.
A bound that tends to 0 as n grows is exactly what the weak law of large numbers states.
Limitations of Chebyshev's Inequality
Although Chebyshev's inequality is widely applicable, the bounds it provides are often conservative.
Fact: One peak puts 95% within three sigma
For a distribution with a single peak, the Vysochanskij–Petunin inequality lowers the bound to 9k24 when k≥8/3≈1.63. At k=3 that is under 5%, against about 11% from Chebyshev, whose worst case splits its mass into three spikes.
Because it depends only on variance, the inequality ignores finer features of the distribution such as shape, symmetry, or tail behavior. As a result, the bound may be much larger than the true probability, especially for well-behaved distributions.
Chebyshev's inequality is also insensitive to how deviations occur. Two random variables with the same variance but very different distributions receive the same bound, even if one is far more concentrated than the other.
For tighter control, additional assumptions or more specialized inequalities are usually required.
Chebyshev bound for a uniform variable
For a uniform variable the true tail probability can be zero while the bound stays positive: the inequality knows only the variance and cannot see that the distribution has no tails at all. That gap is the price of generality. Switch between families and see how loose the bound gets on the Chebyshev inequality visualizer.
Why the inequality matters despite this is explained next.
Why Chebyshev's Inequality Matters
Chebyshev's inequality is the first probability bound that explicitly connects variability to deviation control.
By using variance, it shows that knowing how spread out a random variable is already imposes strong restrictions on how often extreme values can occur. This insight is fundamental in probability theory and underlies many results about stability and convergence.
Because it makes no assumptions about distribution shape, Chebyshev's inequality remains broadly applicable while still being strong enough to support key theoretical arguments.
A single number for spread, with nothing said about shape, already limits how often extremes can occur.
Summary
Chebyshev's inequality provides an upper bound on the probability that a random variable deviates far from its mean.
It requires only finite mean and variance and applies to both discrete and continuous random variables. The resulting bound is distribution-free and stronger than what can be obtained from expectation alone.
For this reason, Chebyshev's inequality is a central tool in probability theory: simple, general, and essential for understanding convergence and variability.
Chebyshev's Inequality at a Glance
The table below collects the anatomy of Chebyshev's inequality — what it applies to, the moments it consumes, the bound it produces, how to read it, why it strengthens Markov, the role it plays, its key application, and where its sensitivity ends — into a single reference card.
Var(X̄ₙ) = σ² / n shrinks ⟹ concentration around μ
Limitation
sees only variance, not shape, symmetry, or tail behaviour
two distributions with the same σ² receive the same bound
Chebyshev's Inequality at a GlanceLearn Math Class
Common Pitfalls
Four mistakes account for most wrong uses of Chebyshev's inequality. Three of them are marked where they happen in the sections above; here each is worked through in full, with the wrong and the right working side by side.
A problem gives the variance, and that number is used where the standard deviation belongs, either to convert the distance into k or as the σ in ε=kσ.
Wrong turn
Error here
For a variable with mean 10 and variance 4, and a deviation of 3,
k=43,k21=916≈1.78
A bound above 1 says nothing.
Right path
The standard deviation is σ=4=2.
k=23,k21=94≈0.44
The second form gives the same number directly: ε2σ2=94.
Why it happensBoth numbers describe spread, and problems give one or the other. The letter σ2 in the second form makes it easy to forget that the first form needs σ itself.
How to checkCompute the bound both ways. The k route and the ε route must give the same number; here 916 against 94 shows that one of them used the wrong spread.
2Reading the bound as the probability
The bound is reported as the chance of a large deviation, as if Chebyshev computed it rather than capped it.
Wrong turn
Error here
For a normal variable with mean 10 and variance 4,
P(∣X−10∣≥3)≈94≈0.44
Right path
Chebyshev only says the probability is at most 94. For this normal variable the deviation is 1.5 standard deviations, and the true probability is
P(∣Z∣≥1.5)≈0.134
About a third of the bound.
Why it happensThe bound is the only number the calculation produces, and with nothing else on the page it gets read as the answer.
How to checkWrite ≤ in the answer, never = or ≈. If the distribution is known, compute the true probability and compare; it should come out at or below the bound, often far below.
3Halving the bound for one tail
Only one direction matters, say X far above its mean, and the two-sided bound k21 is split in half on the assumption that the two tails share it equally.
Start
With k=2,
Wrong turn
Error here
P(X−μ≥2σ)≤21⋅41=0.125
Right path
Take X=2 with probability 0.2 and X=−0.5 with probability 0.8. Then
μ=0.2⋅2+0.8⋅(−0.5)
=0,
σ2=0.2⋅4+0.8⋅0.25=1
And P(X−μ≥2σ)=P(X≥2)=0.2, more than 0.125. Without symmetry, the event X−μ≥kσ is contained in ∣X−μ∣≥kσ, so the safe one-sided bound is the full k21=0.25.
Why it happensThe picture of a bell curve with two equal tails is the default, and Chebyshev assumes nothing about shape, symmetry included.
How to checkAsk whether the distribution is known to be symmetric about its mean. If it is not, keep the whole k21 for a single tail.
4Using the variance of one roll for the average
Chebyshev is applied to the average of n observations, but the variance put into the bound is that of a single observation.
Wrong turn
Error here
For the average of n die rolls and ε=0.5,
P(∣Xˉn−3.5∣≥0.5)≤0.2535/12≈11.67
For every n, a bound that never says anything.
Right path
For independent rolls, the average has variance nσ2=12n35, so
P(∣Xˉn−3.5∣≥0.5)≤0.25n35/12≈n11.67
Which is about 0.117 at n=100 and falls toward 0 as n grows.
Why it happensThe variance of one roll is the number that is easy to compute, and the step from one roll to the average is skipped.
How to checkThe bound for an average must shrink as n grows. If n does not appear in it, the variance of the average was never used.
Each slip changes what goes into the bound or what comes out of it. The distance is measured in standard deviations, not in units of the variance; the result is an upper bound, not a probability; one tail keeps the whole k21 unless the distribution is symmetric; and the average of n observations has variance nσ2. Computing the bound two ways, or checking that it shrinks as n grows, catches each slip.
Skills You Should Learn
Each skill opens its step-by-step method page. Skills marked "On this page" are taught above.
How much of a distribution lies within two standard deviations?
+
At least 75%, for any distribution with a finite variance. Chebyshev's coverage form says P(|X − μ| < kσ) ≥ 1 − 1/k², giving 75% at two sigma and about 89% at three. The familiar 95% figure belongs to the normal distribution, not to Chebyshev — quoting it for unchecked data claims the bell curve's privilege without its assumptions.Read more →
Why does Chebyshev's inequality use an absolute value?
+
To make the bound two-sided. |X − μ| ≥ kσ captures deviations in both directions at once — too far above the mean and too far below — where Markov's X ≥ a watches only one side. That symmetry is possible because variance measures spread around the mean rather than size, so no direction is privileged.Read more →
Is the bound 1/k² or σ²/ε²?
+
Both, but never mixed. They are the same inequality in two conventions: put ε = kσ and each becomes the other. The σ-units spelling gives the clean constants; the ε spelling exposes the mechanism, variance over squared tolerance. Writing σ²/k² or 1/ε² crosses the two and produces a bound silently off by a factor of σ².Read more →
Does k mean the same thing in Markov's and Chebyshev's inequalities?
+
No — same letter, different unit. In Markov's normalized form k multiplies the mean, so the threshold is k·E[X]. In Chebyshev's it multiplies the standard deviation, so the threshold is kσ. Carrying a value of k from one to the other silently changes what is being claimed.Read more →
Can Chebyshev's bound be reached exactly?
+
Yes, so it cannot be improved using the mean and variance alone. Take X=−2,0,2 with probabilities 81,43,81: the mean is 0, the variance is 1, and P(∣X∣≥2)=41, exactly the bound for k=2. The worst case puts its mass in three spikes, one at the mean and two at the threshold, which is why the bound looks loose for smooth distributions.Read more →
Can you halve Chebyshev's bound to get one tail?
+
Not without symmetry. Splitting k21 equally between the tails assumes both carry the same share, and Chebyshev assumes nothing about shape. Take X=2 with probability 0.2 and X=−0.5 with probability 0.8: then μ=0, σ=1, and P(X−μ≥2σ)=0.2, more than the halved 0.125. The full k21 is always a safe bound for a single tail.Read more →
Is there a tighter version of Chebyshev's inequality for single-peaked distributions?
+
Yes. If the distribution has a single peak, the Vysochanskij–Petunin inequality lowers the bound to 9k24 for k≥8/3≈1.63. At k=3 that is under 5%, against about 11% from Chebyshev, so at least 95% of the mass lies within three standard deviations. Chebyshev's worst case has three separate spikes, which a single-peaked shape rules out.Read more →